Light-O1: A Humanoid Foundation Model Pretrained on Human Video
Loading video
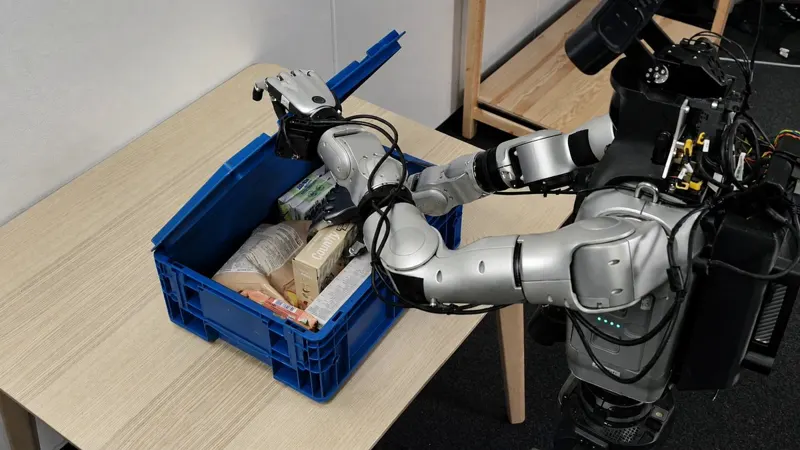
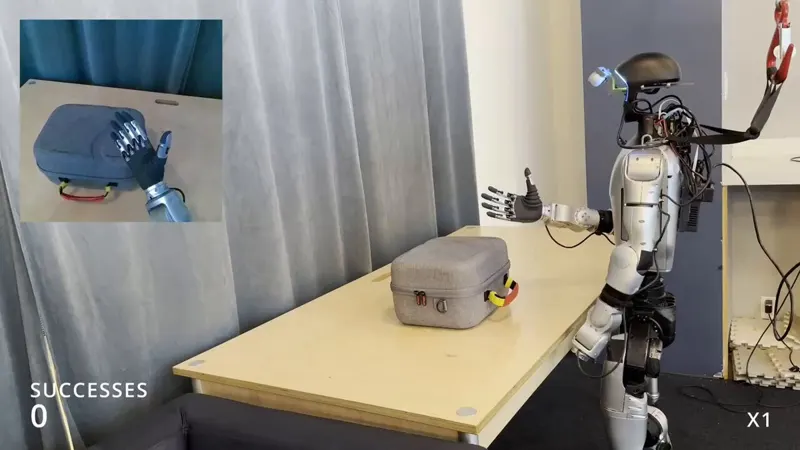
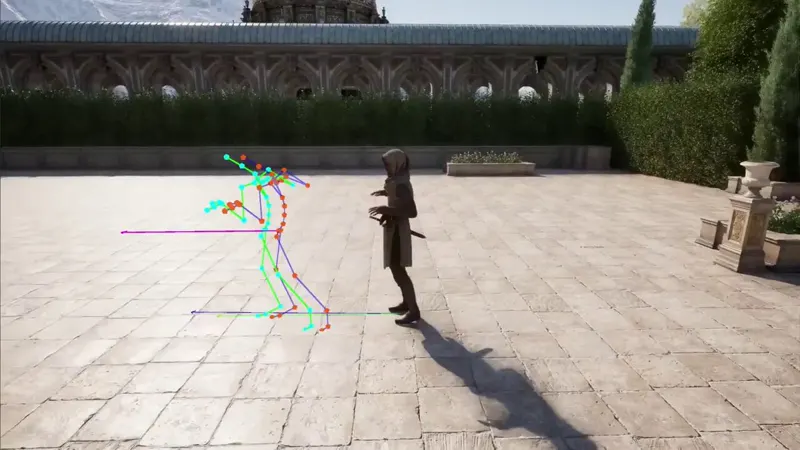
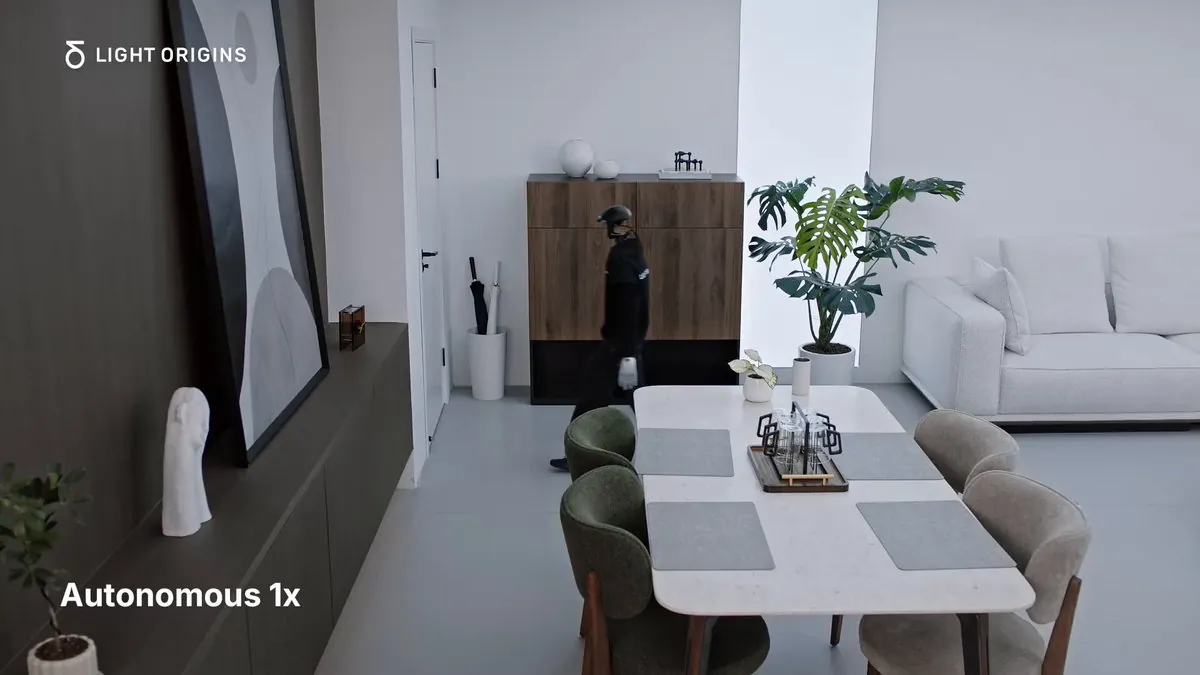
Loading videoLight-O1 recovers structured whole-body actions from ordinary human video, turns them into action tokens and pretrains a humanoid foundation model on them. Its largest run corresponds to 100,000 hours of human action and 120B multimodal tokens, with power-law gains as pretraining grows; the same action prior transfers to Unitree G1 and the Light Origins humanoid for tasks from taking out trash to cartwheels.
Category: research
Author: @heetezition
Date: 2026-09-22T00:00:00
Duration: 143.44s
Reference: https://www.lightorigins.cn/en/blog/light-o1