Skip to content
SimpleVLN: Towards Simple and Frontier Vision-Language Navigation

SimpleVLN: Towards Simple and Frontier Vision-Language Navigation

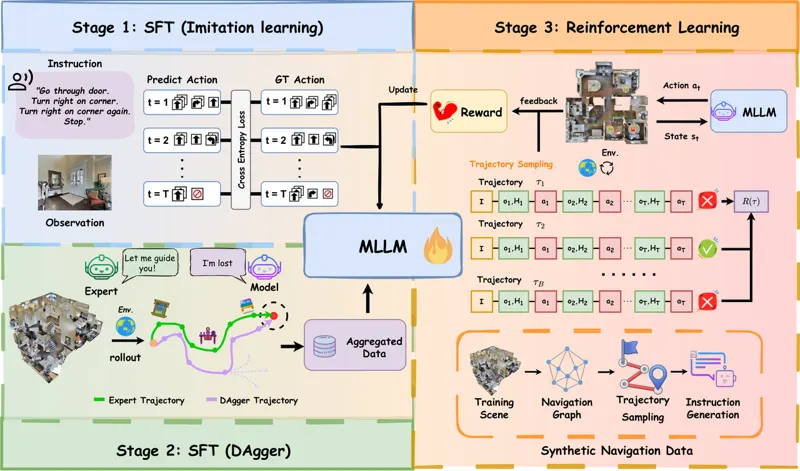
Vision-and-Language Navigation (VLN) requires embodied agents to ground language in visual observations and make long-horizon decisions. Existing methods often address these demands through task-specific architectures. As multimodal large language models (MLLMs) become increasingly capable, an important question remains: Have we truly unlocked the potential of native MLLMs for VLN before introducing task-specific architecture? We present SimpleVLN, an architecture-preserving framework developed through studies of navigation formulation, data construction, and optimization. At the formulation level, SimpleVLN combines single-turn decision inputs with fixed-budget global-local memory to efficiently use navigation history without unbounded context growth, while action chunks enable efficient output of multiple primitive actions per model invocation. For data construction, we combine expert demonstrations with policy-dependent DAgger experience and develop a scalable synthesis pipeline that generates large-scale tasks for reinforcement learning. At the optimization level, a progressive IL-DAgger-RL pipeline advances from action imitation to task-level outcome optimization. Comprehensive experiments validate the effectiveness of these three aspects. We instantiate SimpleVLN across multiple MLLM backbones and model sizes, demonstrating its generality. SimpleVLN achieves 76.7% and 80.1% success rates on the R2R-CE and RxR-CE splits, respectively, substantially outperforming existing methods. These results show that the navigation capabilities of native MLLMs can be effectively unlocked without task-specific architectural designs.

Vision-language navigationEmbodied AI
Lingyi Hong, Weiren Cai, Jiayu Chen · 33 views · Oct 16, 2026
Agent World Model in the Wild: Computer-Use Agent Environment Synthesis

Agent World Model in the Wild: Computer-Use Agent Environment Synthesis

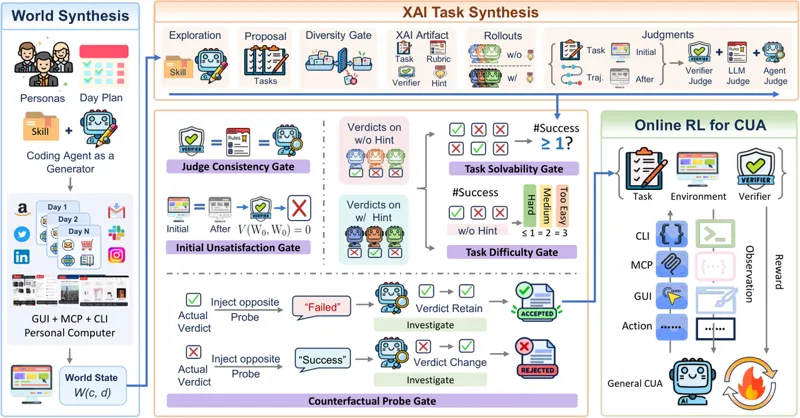
Agent learning is shifting from learning from human data toward learning through interaction with the world. However, scaling such learning directly in real-world computer systems is challenging and can introduce substantial security risks. We therefore propose Agent World Model in the Wild (WildAWM), a scalable pipeline for synthesizing controllable environments and tasks for training general computer-use agents (CUAs). Whereas existing approaches typically specialize in a single agent interaction interface, we construct executable environments that jointly support graphical user interfaces, model context protocol services, and command-line interfaces, allowing agents to flexibly combine visual interaction, tool use, and code execution. WildAWM is entirely powered by open-source models, demonstrating that high-quality computer-use environments can be generated without proprietary frontier models. Beyond environments, we address three recurring challenges in task synthesis: ensuring solvability, maintaining sufficient difficulty, and producing reliable verifiers, by introducing execution-based quality gates that combine heterogeneous agent rollouts, cross-judge consistency checks, and counterfactual probes of judgment robustness. The resulting pipeline synthesizes 341 long-horizon environment-task pairs that can require over 100 agent steps to solve and remain challenging even for frontier models, with GPT-6-Astra solving only 60% of them. We train two Qwen models of different sizes exclusively in these synthetic worlds. Both models achieve substantial gains across 8 out-of-distribution benchmarks spanning web, claw, and computer-use agents, demonstrating that learning in WildAWM's synthesized worlds generalizes broadly to unseen computer-use tasks. The code is publicly available at https://github.com/MSR-Orchard/WildAWM.

Computer-Use AgentWorld Models
Zhaoyang Wang, Qianhui Wu, Haorui Wang · 24 views · Oct 19, 2026
OpenVLHarness: Real World Visual Agentic Tool-Use with Multimodal Memory

OpenVLHarness: Real World Visual Agentic Tool-Use with Multimodal Memory

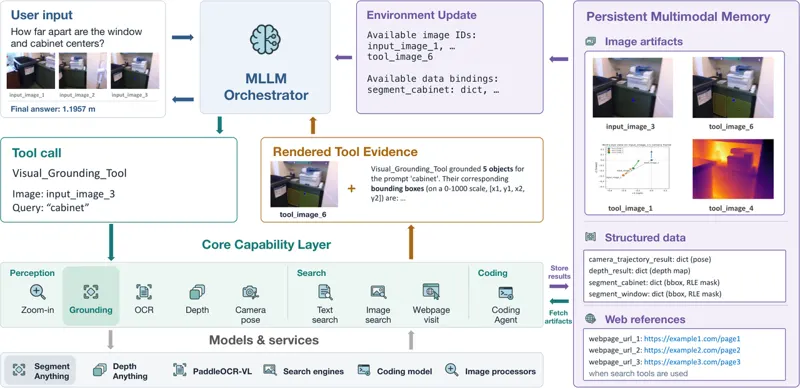
Multimodal large language models (MLLMs) have made rapid progress on visual reasoning, yet many tasks require evidence that is difficult to obtain through internal reasoning alone: our controlled study on 22 benchmarks shows that simply increasing the inference budget of the base model yields only modest gains. Such tasks demand grounded perception, external knowledge, and numerical measurements obtained through heterogeneous tools, whose outputs must be made interpretable to the model and retained across reasoning steps. We introduce OpenVLHarness, a multimodal reasoning harness organized around a capability layer and persistent multimodal memory. The capability layer combines task-level tool interfaces with evidence rendering, providing consistent access to heterogeneous backends and converting their outputs into model-readable observations. Persistent multimodal memory retains the corresponding images, structured data, and web references as addressable artifacts throughout each query. A coding interface executes generated programs over stored data, enabling computations that combine results from multiple tools. Together, these mechanisms support an iterative process of acquiring, inspecting, and composing multimodal evidence. Evaluated on 22 benchmarks with eight open and proprietary backbones, OpenVLHarness improves average scores by 9.7-12.6 points over matched no-tool baselines, including +11.2 with Qwen3-VL-8B, +9.7 with Kimi K3, and +9.9 with GPT-6 Astra. With GPT-6 Luna at medium reasoning effort, OpenVLHarness outperforms the base model, Codex, and Visual Sketchpad at maximum effort by 7.7-8.5 points while incurring at most 37% of their model-token cost.

Multimodal ReasoningTool Use
Yu Zhou, Cheng-Fu Yang, Rui Sun · 187 views · Oct 19, 2026
Data-Free Continual Learning for World Action Model with Rectified Generative Replay

Data-Free Continual Learning for World Action Model with Rectified Generative Replay

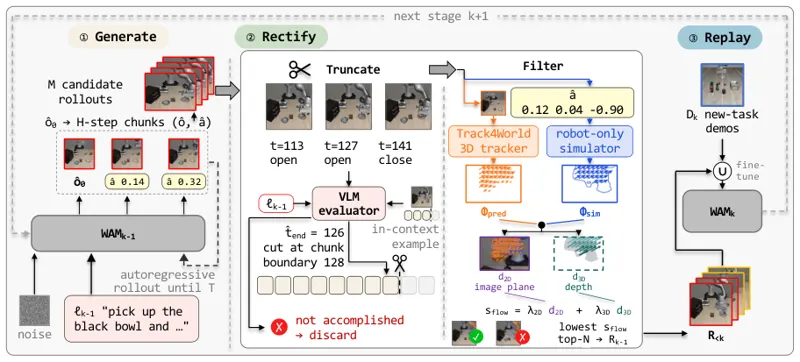
World action models (WAMs) built on pretrained video generation models adapt quickly to new robotic tasks, but they forget previously learned tasks under sequential fine-tuning. Experience replay (ER) mitigates such forgetting by rehearsing data of previous tasks, yet this data is often unavailable in robotics, where a policy is deployed as weights only and its training data is not shared along with it. In this work, we ask whether a WAM can achieve data-free continual learning by regenerating its own past. Our key observation is that a WAM can indeed autoregressively regenerate complete rollouts of previously learned tasks and replay them to mitigate forgetting. However, replaying such raw rollouts still lags far behind replaying real data, which we attribute to two issues. First, the WAM is unable to recognize task completion and keeps generating purposeless motion after the task is done. Second, under open-loop generation, the generated actions gradually drift away from the generated observations. To address both issues, we present rectified generative replay (R²-WAM), which truncates generated rollouts at task completion with an agentic evaluator and filters out rollouts whose actions are physically inconsistent with the observations. On the four LIBERO suites and five real-world tasks, R²-WAM reduces forgetting by over 90% relative to sequential fine-tuning and nearly matches ER without accessing any data from previous tasks. Our analysis further reveals that forgetting in WAMs concentrates in inverse dynamics modeling: a forgotten WAM still produces visually plausible observations of previous tasks while its generated actions fail. Project page: https://kaipengfang.github.io/r2-wam/

Continual learningWorld-action models
Kaipeng Fang, Hangxu Liu, Chaojian Shi · 34 views · Oct 13, 2026
Action-Aligned Latent Planning for Versatile Humanoid Loco-Manipulation

Action-Aligned Latent Planning for Versatile Humanoid Loco-Manipulation

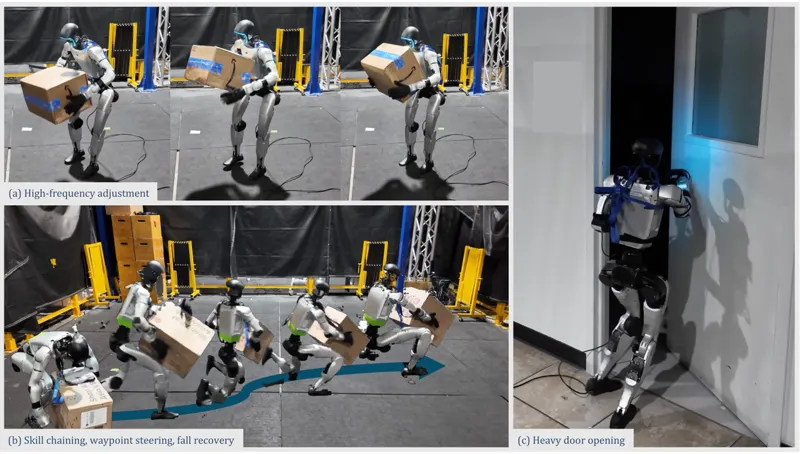
FIBER addresses a representation problem at the heart of versatile humanoid loco-manipulation: high-level planners need a compact abstraction, but kinematic or contact targets do not encode the state-dependent control responses that make contact-rich interaction succeed, while predicting low-level actions forces an offline planner to model high-frequency closed-loop feedback. FIBER resolves this by using the executable latent space of a frozen behavioral foundation model (BFM) as the shared planning representation. Its latent policy projection (LPP) maps each independently acquired task expert into that space by identifying latent commands whose BFM-induced actions match the expert's local control responses in physical joint-target space, regularized by a semantic term that anchors each command to the BFM backward representation of the same state. Because projection only requires the expert's actions, experts may differ in observations, objectives, and training pipelines, and are discarded once projected. Closed-loop latent rollouts from all projected skills are then aggregated to train a single perceptive flow-matching planner entirely offline, conditioned on egocentric depth, proprioception, and steering tokens derived from language or waypoints; at deployment it replans in a receding-horizon loop while the frozen BFM supplies 50 Hz state feedback. The paper further contributes AH-BFM, an adaptive-horizon BFM trained with multi-gamma forward-backward learning that keeps both short-horizon tracking fidelity and long-horizon behavioral coherence in one latent space, and successor-feature-guided behavior reuse, which composes an acquired interaction such as box carrying with native whole-body behaviors like crouching or running. In IsaacSim, across 128 variations per task, FIBER reaches 42.0% mean success versus 11.6% for projected latent replay and 3.5% for kinematic planning; on a real Unitree G1 it transfers zero-shot with 6/10 box pickup, 4/10 door opening, and 2/10 object grasping, running a 5 Hz TensorRT planner and the 50 Hz BFM on a single laptop GPU.

HumanoidMobile Manipulation
Yutang Lin, Guanya Shi, C. Karen Liu · 36 views · Oct 17, 2026
Perceptive Humanoid Parkour: Chaining Dynamic Human Skills via Motion Matching

Perceptive Humanoid Parkour: Chaining Dynamic Human Skills via Motion Matching

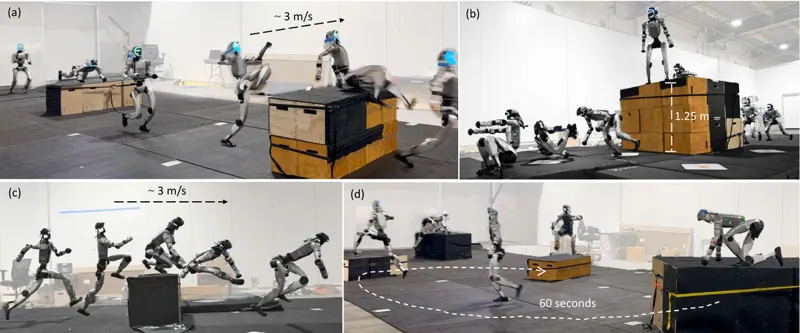
While recent advances in humanoid locomotion have achieved stable walking on varied terrains, capturing the agility and adaptivity of highly dynamic human motions remains an open challenge. In particular, agile parkour in complex environments demands not only low-level robustness, but also human-like motion expressiveness, long-horizon skill composition, and perception-driven decision-making. In this paper, we present Perceptive Humanoid Parkour (PHP), a modular framework that enables humanoid robots to autonomously perform long-horizon, vision-based parkour across challenging obstacle courses. Our approach first leverages motion matching, formulated as nearest-neighbor search in a feature space, to compose retargeted atomic human skills into long-horizon kinematic trajectories. This framework enables the flexible composition and smooth transition of complex skill chains while preserving the elegance and fluidity of dynamic human motions. Next, we train motion-tracking reinforcement learning (RL) expert policies for these composed motions, and distill them into a single depth-based, multi-skill student policy, using a combination of DAgger and RL. Crucially, the combination of perception and skill composition enables autonomous, context-aware decision-making: using only onboard depth sensing and a discrete 2D velocity command, the robot selects and executes whether to step over, climb onto, vault or roll off obstacles of varying geometries and heights. We validate our framework with extensive real-world experiments on a Unitree G1 humanoid robot, demonstrating highly dynamic parkour skills such as climbing tall obstacles up to 1.25m (96% robot height), as well as long-horizon multi-obstacle traversal with closed-loop adaptation to real-time obstacle perturbations.
HumanoidParkour
Zhen Wu, Xiaoyu Huang, Lujie Yang · 38 views · Feb 17, 2026
DiscoveryRSI: Recursively Learning to Discover Valuable Hypotheses

DiscoveryRSI: Recursively Learning to Discover Valuable Hypotheses

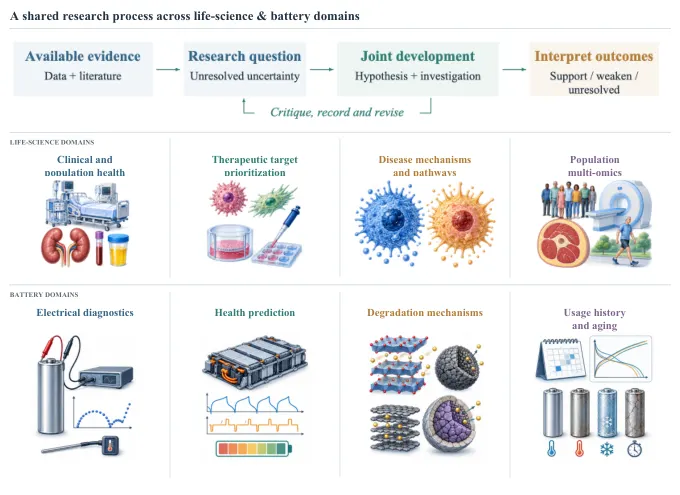
Scientific discovery requires developing worthwhile hypotheses into practical investigations, yet learning from this evolving research process remains challenging. We introduce an operational definition of valuable and testable research hypotheses: evidence-grounded claims about consequential uncertainties, coupled with feasible investigations, explicit decision criteria, and alternative explanations. Our DiscoveryRSI framework develops hypothesis trees through multi-agent evolutionary search, compiles selected investigations into executable Harbor tasks, and recursively learns through three mechanisms: hypothesis credit optimization attributes scientific assessments to documented research contributions; harness replay identifies productive strategies and recurring failures to refine research workflows; and rediscovery applies accepted improvements to new investigations, generating further experience for subsequent learning. We also introduce DFM-Bench, which provides comprehensive assessment of hypothesis quality and cumulative research progress at the levels of hypotheses, revisions, development paths and research runs. Across four life-science domains, automated evaluation shows that hypothesis quality rises from 4.86 for the base model to 5.39 after two rounds of self-improvement, with the large gains in falsifiability and data resolvability. We further validate hypothesis quality through expert review, comparing our DiscoveryRSI-27B with other research agents. Preliminary human assessments show that DiscoveryRSI-27B scores higher than GPT-6 Luna on hypothesis importance and whether claims are plausible and evidence-bounded. DiscoveryRSI-27B achieved a 6.3% rate of hypothesis correspondence with research published after the model cutoff, largely outperform GPT-6 with 2.5% and Claude Opus 5 with 2.3%, while delivering greater human-rated improvement along research paths.

Scientific discoveryMulti-Agent Systems
Jianyuan Zhong, Chenwei Wu, Zhaochen Yu · 69 views · Oct 16, 2026
Social-WM: Safety-Aware Latent World Models for Robot Social Navigation

Social-WM: Safety-Aware Latent World Models for Robot Social Navigation

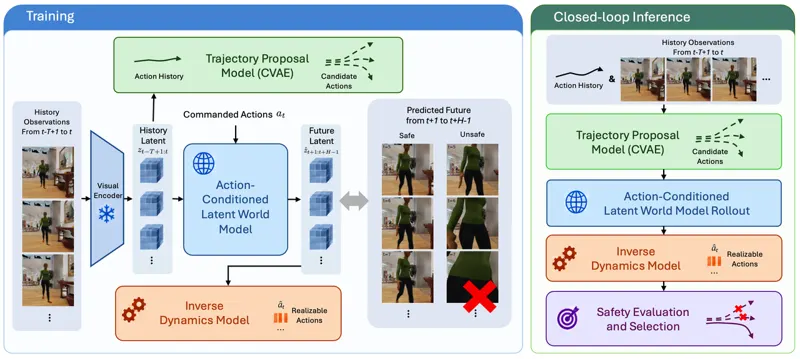
Safe social navigation requires a robot to anticipate not only the future consequences of its actions, but also whether a nominal action can actually be executed under surrounding physical and social constraints. We present Social-WM, an efficient latent world-model planning framework trained from egocentric RGB video sequences. Our key observation is that social-navigation experience contains a systematic discrepancy between the nominal action and the realizable action: a nominal forward action may be fully executed in free space, but needs to be constrained when heading towards a pedestrian or obstacle. Social-WM learns these safety-relevant consequences directly through action-conditioned future prediction, where the target is the actual observed future following each command. We further introduce a realizable inverse-dynamics objective that associates observed latent transitions with the action actually realized rather than the nominal one. At deployment, candidate actions are imagined through the latent world model, and the inverse dynamics model estimates their realizability; nominal–realizable discrepancy then provides a safety signal before execution. The learned dynamics and realizability model remain goal-independent and support both position- and image-goal navigation. On Social-HM3D, Social-WM achieves 63.77% success while reducing human collisions to 21.67%, and maintains strong performance under zero-shot transfer to Social-MP3D, without explicit pedestrian tracking, privileged human state, or online reinforcement learning.

Social NavigationWorld Models
Zhihao Zheng, Mooi Choo Chuah · 71 views · Sep 30, 2026
Juno: Taming Predictive Latents for Vision-Language-Action Models

Juno: Taming Predictive Latents for Vision-Language-Action Models

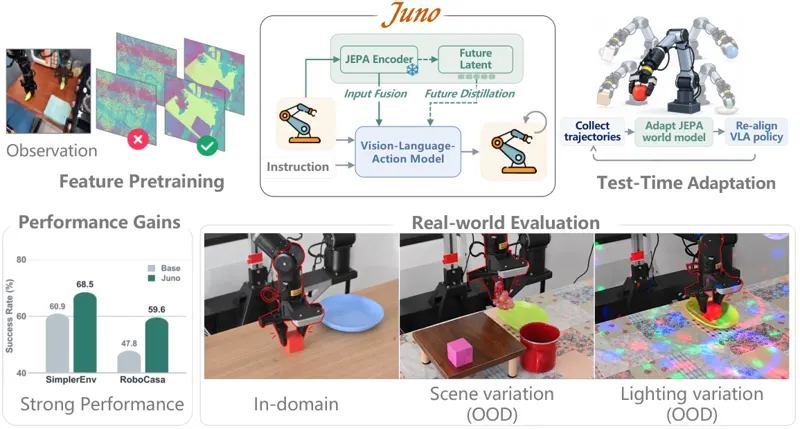
Joint-embedding predictive architectures (JEPAs) predict masked or future observations in representation space, offering a natural source of predictive latents for vision-language-action (VLA) models. Yet making these latents useful across pretraining, policy learning, and deployment requires addressing three failures: mismatch with embodiment-specific control, interference with action learning, and teacher miscalibration under distribution shifts. We introduce Juno, a unified framework built around one action-conditioned JEPA that serves as a control-aligned representation backbone, a predictive teacher, and an adaptable dynamics model. During pretraining, we train it on embodiment-matched trajectories and use a dynamic CLS loss to transfer motion-weighted patch dynamics to a compact global state. During policy learning, we fuse current-frame JEPA patches into VLA perception and use a decoupled reasoning branch with separate transformation parameters to distill future latent states for action generation. During deployment, we adapt the world model on all observed transitions, including failed rollouts, freeze the adapted teacher, and re-align the policy on verified executions using LoRA adapters and a trainable action head, without expert corrections or task rewards. On SimplerEnv, Juno raises average success from 60.9% to 68.5% over Qwen3GR00T, the strongest baseline, and test-time adaptation further reaches 72.7%; on a real robot, it retains 70%–75% success under background, height, and object shifts where the base policy collapses to 0%.

Vision-language-action (VLA)World Models
Yuchen Zhu, Chenyi Xu, Yulin Zhang · 55 views · Oct 7, 2026
Into the LidarVerse: A Real-Time Unified LiDAR World Model Across Tasks and Sensors

Into the LidarVerse: A Real-Time Unified LiDAR World Model Across Tasks and Sensors

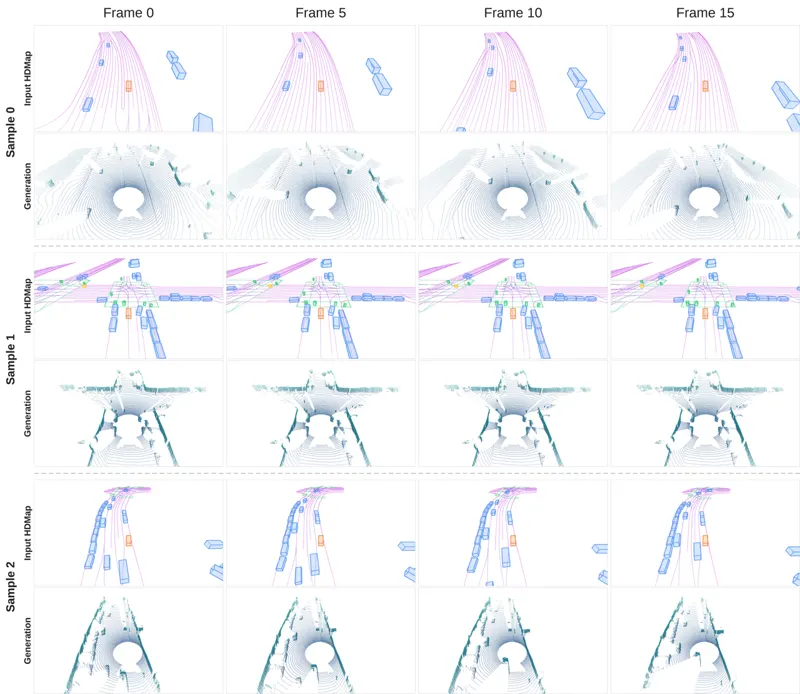
We present LidarVerse, a real-time unified LiDAR world model for sensor simulation across tasks and sensors. Existing LiDAR simulators largely follow one of two complementary paradigms: reconstruction-based methods preserve the geometry of a captured scene but require lengthy per-scene optimization, whereas generative methods amortize learning across data but lack the consistency needed for long-horizon rollouts. LidarVerse brings both paradigms into a single, unified conditional generative framework. A universal tokenizer maps LiDAR range sequences into a shared latent space, where a bidirectional teacher learns a common interface for conditioning on a LiDAR prefix, an HD-Map, a persistent spatial cache, and optionally, text. Varying the available scene evidence turns the same model into a generator of new worlds, a point-cloud forecaster, or a generalizable resimulator of observed scenes without per-scene optimization. We distill the teacher into a four-step autoregressive causal student and maintain both a rolling temporal K/V cache and a world-aligned spatial cache, enabling persistent long-horizon rollouts with real-time inference at 11 FPS on a single H100 GPU. LidarVerse achieves state-of-the-art performance on most reported metrics across all three evaluation protocols, while its tokenizer supports 32-, 64-, and 128-beam LiDAR and generalizes to an unseen scanning pattern. These results demonstrate that generative and reconstruction-grounded LiDAR simulation can be realized within one model, providing the core capabilities for future closed-loop sensor simulation.

LiDARWorld Models
Che, Henry, Ren, Xuanchi, Fidler, Sanja · 79 views · Oct 13, 2026
PaperBanana-Interact: Scientific Diagram Refinement with Multi-Turn Human Feedback

PaperBanana-Interact: Scientific Diagram Refinement with Multi-Turn Human Feedback

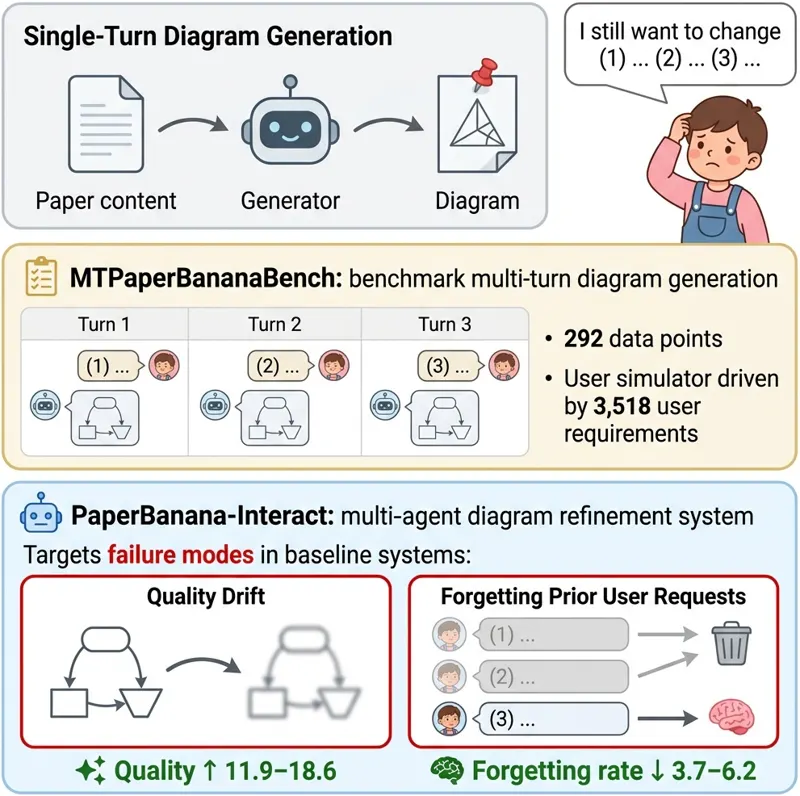
Recent efforts have aimed to automate scientific diagram generation from paper content (Lin et al., 2026; Zhu et al., 2026a). However, fully satisfying an author's visual and communicative preferences in a single turn is challenging: in our formative user study (N = 14), all participants requested further revisions after viewing an initial draft, and 86% of them rated the refined diagrams as more satisfactory. Despite the clear demand, the multi-turn workflow remains largely underexplored. To bridge this gap, we present MTPaperBananaBench, a benchmark for multi-turn diagram generation containing 292 images annotated with 3,518 user requirements. To reduce expensive human studies and enable scalable benchmarking, we construct a user simulator that, at each turn, identifies unsatisfied requirements and converts k of them into natural language feedback. Evaluating both requirement satisfaction and overall diagram quality reveals two key failure modes shared across baseline multiturn systems: (1) quality drift, where diagram quality progressively declines over turns, and (2) forgetting, where previously implemented features are lost in subsequent turns. To address these issues, we introduce PaperBanana-Interact, a multi-agent system that refines diagrams via an internal critique-and-refine loop. PaperBanana-Interact consistently improves rather than degrades diagram quality across turns, outperforming baselines by 11.9-18.6 points in quality score and reducing forgetting by 3.7-6.2 points.

Multi-agentDiagram Generation
Xueqing Wu, Ashwin Balasubramanian, Bingxuan Li · 49 views · Aug 31, 2026

As an Amazon Associate, we earn from qualifying purchases.