PAPER DEEP DIVE
Self-Adaptive VLA for Robust Robot Deployment
This post-training method turns a policy's own shifted rollouts into latent context, uses a lightweight encoder and adaptive layer normalization to adapt a vision-language-action policy, and recovers over 80% of base performance across four precision-critical manipulation tasks.
Paper Information
Title: Self-Adaptive VLA for Robust Robot Deployment.
Authors: Hongxin Zhang, Chunru Lin, Tsun-Hsuan Wang, Zhenjia Xu, and Chuang Gan.
Source: arXiv:2609.30092v1, September 24, 2026, with robotics as the primary subject and computer vision as the secondary subject. The full paper is available at https://arxiv.org/abs/2609.30092 and the project page at https://icefoxzhx.github.io/self-adaptive-vla .
Code status: The paper identifies https://github.com/Icefoxzhx/self-adaptive-vla as its official repository, but the current repository contains only the project site, styling, images, and demonstration videos. It does not include training or inference source code, configuration files, checkpoints, released data, or a software release. The paper therefore does not provide a public implementation sufficient for reproducing its experiments, and every method and result below is based on the arXiv full text.
One-Sentence Summary
Self-Adaptive VLA compresses a robot's failed deployment trajectory into an additive context vector that modulates an otherwise memoryless flow-matching VLA. By pre-compensating expert actions for known actuation bias or joint-encoder offset, it progressively identifies the unknown hardware error from its own failures, averaging 46%-49% recovery with one context trial and 80%-84% recovery with up to six trials across four precise bimanual and dexterous tasks.
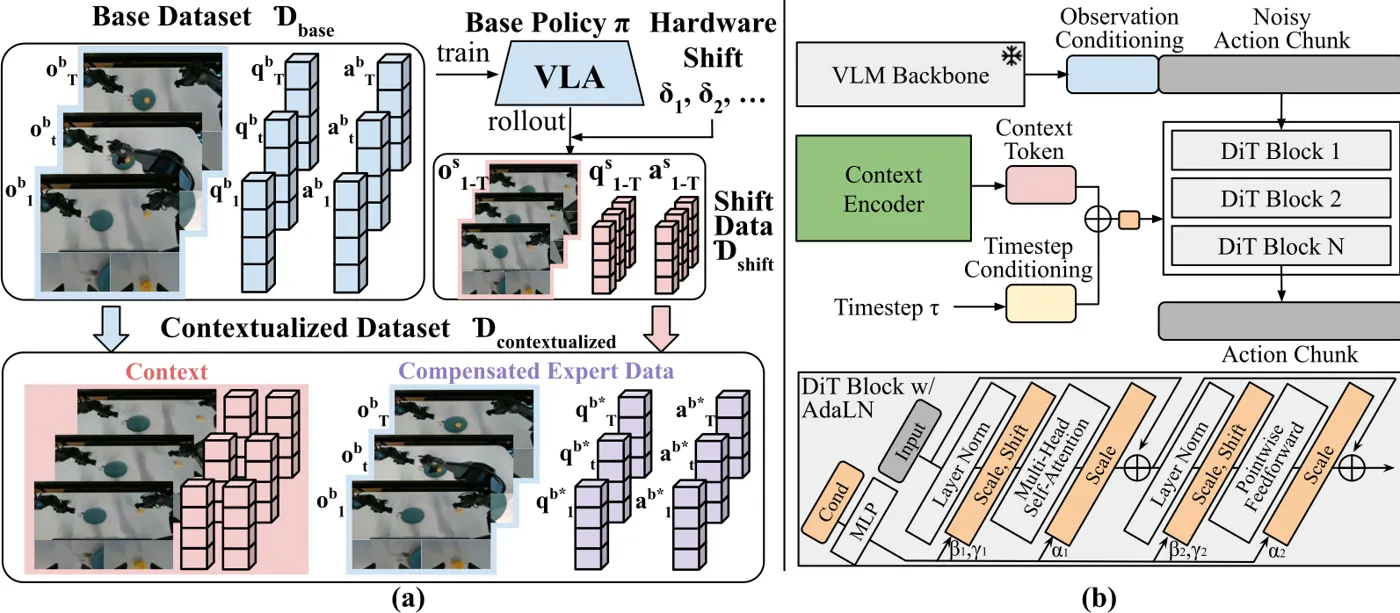
Figure 1: Method overview (paper Figure 2). The left side pairs expert demonstrations with failure rollouts under hardware shift; the right side adds the resulting context token to the diffusion timestep condition and modulates a frozen VLM policy through AdaLN.
Motivation
A typical vision-language-action policy maps a language instruction, the current image, and robot proprioception to a chunk of future actions. This interface performs well near its training distribution because it implicitly assumes that joint zero positions, actuator responses, and camera poses match the data-collection setup. Real robots violate that assumption through manufacturing tolerances, wear, small collisions, replacement parts, and recalibration. The same instruction and an almost identical image can therefore require a different sequence of joint commands.
The conventional remedy is either careful calibration before deployment or additional expert data and fine-tuning after a robot arrives at a site. Both approaches scale poorly. Calibration must be repeated as hardware changes, while on-site data collection requires skilled teleoperation, training infrastructure, and downtime. Different workstations may require separate datasets even when they run the same task. A foundation model that can manipulate objects in a laboratory is not yet a system that can be maintained across a fleet.
Memoryless policies make the problem worse because a diagnostic signal is visible only across attempts. A robot might miss a grasp, approach a tube slightly too high, or insert a marker cap with a small lateral error. Each failure contains useful evidence, but ordinary VLA inference discards it after producing the next action chunk. Generic long-context memory methods can remember video, yet remembering is not the same as identifying which hardware degree of freedom is offset. Rapid adaptation methods often depend on simulation, additional online optimization, or explicit human corrections.
This paper changes the role of failure data. A failed rollout is neither a target behavior to imitate nor merely a negative example. It is an observation about the current hardware. A context encoder extracts a low-dimensional representation of that observation, and the action policy learns to alter expert actions conditioned on the representation. The context is computed once after a trial, not during every high-frequency control step. As a result, deployment adaptation can reuse the original VLA control path with little additional closed-loop computation.
Problem Setup and Hardware Models
Let $n$ be the number of actuated degrees of freedom, $a_t\in\mathbb{R}^{n}$ the absolute target joint command, $\hat{q}_t$ the physical state, and $q_t$ the encoder reading available to the policy. An evaluation episode samples one unknown offset $\delta\in\mathbb{R}^{n}$. The offset remains fixed across all trials in that episode and uses the same units as the action space. Each episode therefore represents one uncalibrated deployment condition, and adaptation must happen through context accumulated over trials rather than through knowledge of the true $\delta$.
The first condition is actuation bias. A constant low-level controller error or torque-sensor bias shifts physical execution while the encoder continues to report the true physical state. Under ideal low-level tracking, the relation is:
$$\hat{q}_{t+1}\approx a_t+\delta,\qquad q_t=\hat{q}_t.\tag{1}$$
The second condition is joint-encoder offset. A mis-zeroed encoder shifts both the realized action and the state read by the policy. The resulting relation is:
$$\hat{q}_{t+1}\approx a_t+\delta,\qquad q_t=\hat{q}_t-\delta.\tag{2}$$
Although the two equations differ by one term, the diagnosis problem is different. Actuation bias produces a direct mismatch between commanded and sensed motion, making proprioception informative. An encoder offset shifts both action execution and sensing in a self-consistent way, so the intrinsic state signal can look deceptively normal. The policy must rely more heavily on visual evidence, such as the changing relation between the gripper and an object. The ablation later confirms that removing proprioception hurts both shifts, but is especially damaging for actuation bias.
Base Policy and Flow Matching
The base policy receives a language instruction $l$, current observations $o_t$, and proprioception $q_t$. A vision-language model fuses these inputs into an observation condition, and a diffusion transformer denoises a future action chunk. Let $c_t^o$ denote the VLM condition. The policy can be summarized as:
$$c_t^o=\mathrm{VLM}(l,o_t,q_t),\qquad \pi(A_t\mid l,o_t,q_t)=v_\theta(A_t^\tau,\tau\mid c_t^o).\tag{3}$$
The target chunk $A_t$ contains the next $h$ actions. During training, it is interpolated with Gaussian noise along a straight path:
$$A_t^\tau=\tau A_t+(1-\tau)\epsilon,\qquad \epsilon\sim\mathcal{N}(0,I),\qquad \tau\sim\mathcal{U}[0,1].\tag{4}$$
The path has constant velocity $A_t-\epsilon$, so the denoiser is trained with a conditional flow-matching loss that regresses this velocity:
$$\mathcal{L}(\theta)=\mathbb{E}\left[\left\|v_\theta(A_t^\tau,\tau\mid c_t^o)-(A_t-\epsilon)\right\|_2^2\right].\tag{5}$$
At inference, Euler integration moves an initially noisy chunk along the predicted field to obtain its clean actions. The implementation uses Qwen-3.5-0.8B as the VLM encoder and an 8-layer diffusion transformer with about 340 million parameters as the action denoiser. The important limitation is architectural rather than incidental: the denoiser sees only the current observation condition. A repeated failure cannot change the next decision because no trial history enters the policy.
Building Contextualized Expert Data
The authors do not ask the robot to imitate its failed trajectories. They first sample random shifts $\delta$, run the frozen base policy under those shifts, and record trajectories containing observations, proprioception, and executed actions. These rollouts are useful because they show how the policy behaves under a known hardware error, not because their actions are desirable. The collection of trajectories and shifts becomes the source of diagnostic context.
Next, the pipeline samples a high-quality human expert demonstration and pre-compensates its actions for the known shift. If the hardware model also affects sensing, the corresponding proprioceptive targets are transformed as well. The final training sample pairs the failed context with the language instruction, a corrected proprioceptive target, and a corrected expert action target. The compensation target always comes from human expert data, never from the sub-optimal rollout.
This separation matters. If the policy were trained to copy failed actions, it would learn the very error that needs correction. If the failed rollout were discarded, the policy would have no evidence about which hardware condition produced the failure. Pairing diagnosis with an expert-derived target preserves both pieces. The procedure avoids additional teleoperation, but it still assumes an explicit parameterization of possible shifts and a training distribution that covers deployment behavior.
The Plug-In Context Encoder
The context encoder processes a deployment trial lasting about 15 seconds. Its inputs include ego video, left-wrist video, right-wrist video, proprioception, and the actions executed during the trial. Video frames are temporally downsampled and encoded by a pretrained DINOv3 backbone into one compact CLS token per sampled frame. State and action segments within each interval are passed through a shared MLP projector.
Different camera streams, state, and actions receive learned type embeddings so that the network can distinguish a wrist view from the ego view and a joint command from a measured joint position. Two self-attention blocks with one-dimensional rotary position encoding fuse the multimodal sequence while preserving temporal alignment. A learned attention-pooling query then compresses the full sequence into one context token $c^s$.
$$c^s=\mathrm{ContextEnc}(\{I_t^{ego},I_t^{left},I_t^{right},q_t,a_t\}_{t=1}^{T}).\tag{6}$$
The context token has the same dimension as the DiT timestep embedding. The modified condition is their sum:
$$c_t^{cond}=c^\tau+c^s.\tag{7}$$
Each DiT block receives this combined vector through AdaLN-Zero and produces dimension-wise scale, shift, and gate parameters. The VLM remains frozen during this post-training stage, and the context encoder is optimized with the same conditional flow-matching objective. The original VLM token sequence is not expanded with minutes of video, nor does every control step repeat context encoding.
The deployment advantage is that the encoder runs once after a failed trial. During the subsequent closed-loop trial, the policy performs the original action denoising plus a vector addition to the timestep condition. The encoder's cost has not disappeared, but it is outside the high-frequency action cycle. This distinction is important for interpreting the paper's phrase “zero additional computational overhead during inference”: the overhead is negligible inside each control step, not for the system as a whole.
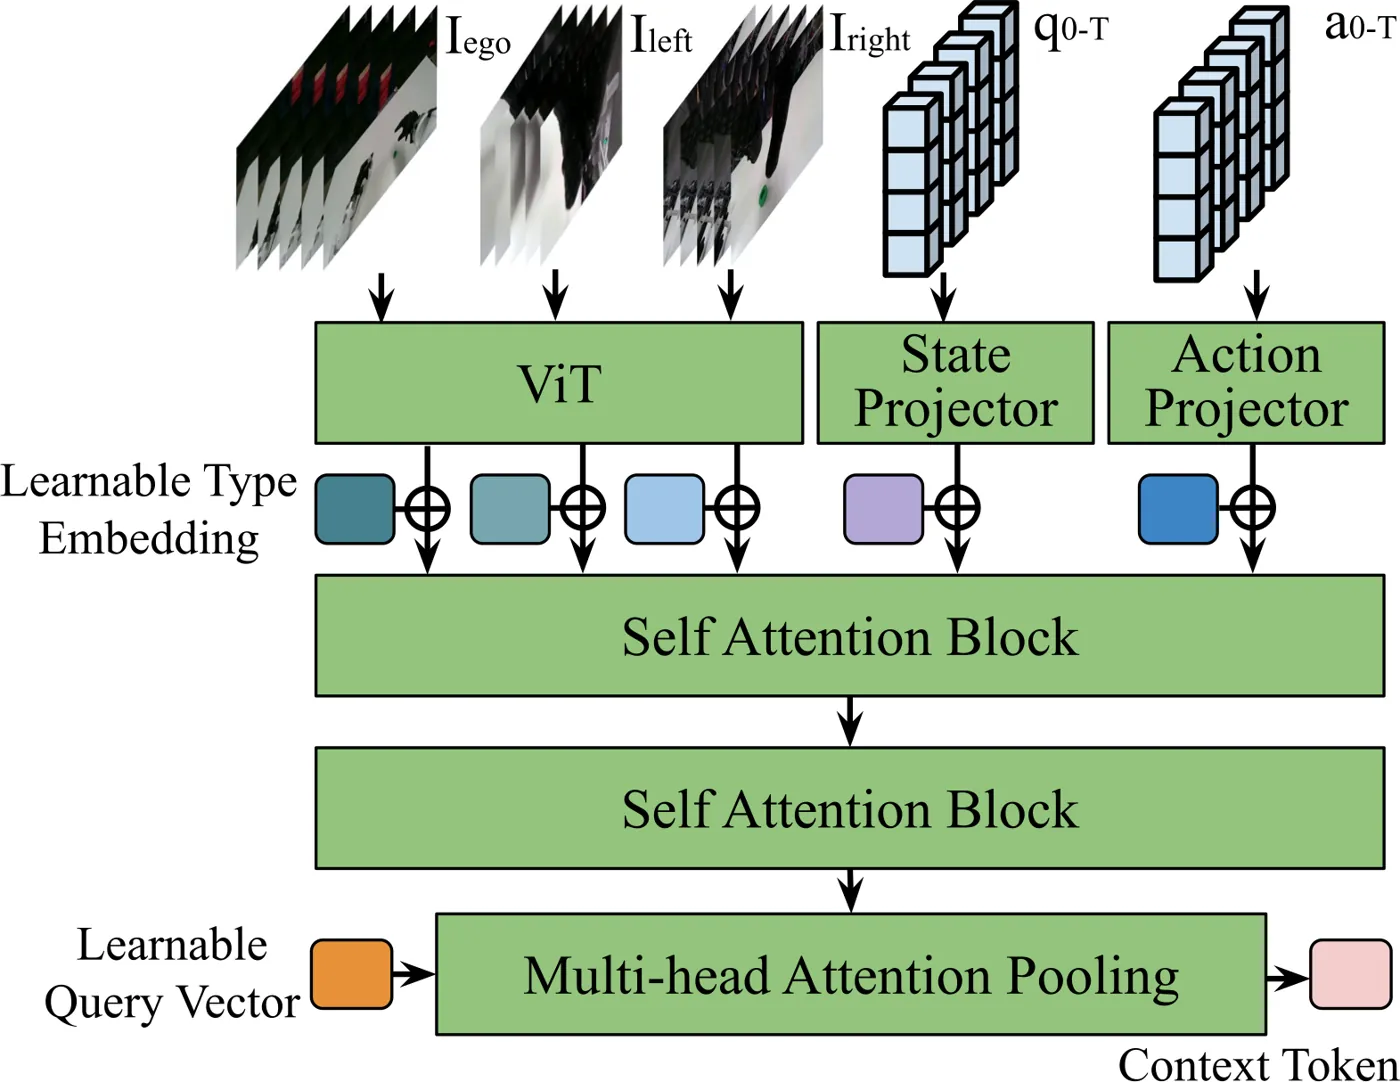
Figure 2: Context encoder (paper Figure 3). Video frames become CLS tokens, state and action intervals pass through MLP projectors, and type embeddings, temporal self-attention, and learned-query pooling produce one context token.
Iterative Adaptation through Additive Tokens
A single failed rollout need not reveal every component of an unknown shift. One large joint error can dominate the visual failure while a smaller error remains hidden. After the dominant component is corrected, a later attempt may expose the residual. Instead of growing a long video context or retraining after every trial, the method encodes each trial independently and adds the resulting tokens:
$$\mathrm{ensemble}(c_1,c_2,\cdots,c_m)=c_1+c_2+\cdots+c_m.\tag{8}$$
The rule works because the paper finds a structured latent geometry. Each signed degree of freedom in the hardware shift behaves approximately as an independent direction. Tokens for opposite signs of the same axis point in nearly opposite directions, while tokens for different axes are close to orthogonal. Summing several tokens preserves much of this directional evidence and strengthens the inferred compensation. The policy can move from failing to grasp, to grasping one side, to grasping both sides, and finally completing the precise insertion.
The authors also describe the addition as a mechanism for correcting the policy's own over- or under-compensation. A first correction may move the gripper too far; the next failed trial contributes evidence in the opposite direction. Unlike a fixed-length cross-attention memory, the additive representation does not explicitly overwrite earlier trials. Its stability nevertheless depends on the learned representation remaining close to the structured, nearly orthogonal geometry observed in the controlled experiments.
flowchart TD
    A["Expert demonstrations"] --> B["Inject known hardware shift"]
    B --> C["Roll out frozen base VLA"]
    C --> D["Failure trajectory context"]
    D --> E["Context encoder
three views, state, action"]
    E --> F["Static context token"]
    A --> G["Pre-compensate expert actions"]
    B --> G
    G --> H["Shift-conditioned expert target"]
    F --> I["Add token to timestep condition"]
    I --> J["AdaLN modulates DiT policy"]
    H --> K["Conditional flow-matching loss"]
    J --> K
    K --> L["Post-trained Self-Adaptive VLA"]
    L --> M["Deployment trial"]
    M --> N["Failure detected"]
    N --> E
    N --> O["Sum context tokens
from all failed trials"]
    O --> I
    M --> P["Task success"]
Evaluation Protocol
The evaluation covers four precise bimanual and dexterous tasks: transporting corn onto a plate, inserting a tube into a rack, capping a marker, and assembling a ring. The first three use pairs of 6-DoF Piper or Piper-X arms with parallel grippers. Ring assembly uses two 7-DoF Marvin arms and two 20-DoF Wuji hands. Every frame combines an ego view with left- and right-wrist views, and each task lasts roughly 10 to 15 seconds.
For each task, a base policy is first trained on human teleoperated demonstrations. Every baseline is post-trained from the same base policy to reduce initialization differences. Evaluation uses 20 episodes. Each episode samples an unseen shift from a hardware-specific distribution and holds it fixed across trials, so the 20 episodes represent 20 distinct uncalibrated deployment environments. A policy may use up to six trials per episode, with a full scene reset between attempts. An episode counts as successful if any trial completes the task.
The primary result is success rate. To compare tasks whose nominal difficulty differs, the paper also defines performance recovery:
$$\rho=\frac{s-s_{\mathrm{base,misaligned}}}{s_{\mathrm{base,nominal}}-s_{\mathrm{base,misaligned}}}.\tag{9}$$
Here $s$ is the evaluated method's success rate under shift, while the denominator is the performance lost by the base policy when moving from nominal calibration to the shifted environment. A value of one means full recovery, and a negative value means the adaptive method performs worse than the unadapted base policy.
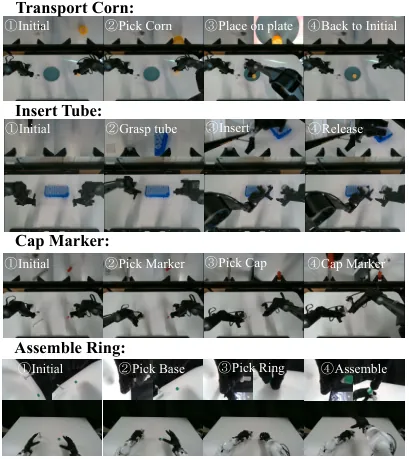
Figure 3: The four evaluation tasks (paper Figure 4). The frames show initial, grasp, placement, and insertion stages across parallel-jaw and dexterous-hand platforms.
Main Results
Under nominal calibration, the base policy averages 88.8% success: 100% for corn transport, 75% for tube insertion, 85% for marker capping, and 95% for ring assembly. Actuation bias drops the average to 7.5%, while joint-encoder offset reduces it to 5.0%. The changes are small in joint space but decisive for contact-rich manipulation. Fine-tuning on data collected under hardware shift without a context encoder reaches only 10.0% and 15.0%. Merely exposing the policy to shifted trajectories does not tell it which shift is active in the current episode.
With one context trial, Self-Adaptive VLA averages 45.0% under actuation bias and 46.3% under encoder offset, corresponding to 46% and 49% recovery. With up to six trials of context, the averages rise to 72.5% and 75.0%, or 80% and 84% recovery. The gain is not confined to one easy task. Corn transport returns from 0%-20% to 100%, ring assembly rises from 10%-20% to 70%-90%, and tube insertion climbs from 0% to 50%.
| Actuation bias | Transport corn | Insert tube | Cap marker | Assemble ring | Average |
|---|---|---|---|---|---|
| Nominal base policy | 100 | 75 | 85 | 95 | 88.8 |
| Base under shift | 20 | 0 | 0 | 10 | 7.5 |
| Base plus shift data | 30 | 10 | 0 | 0 | 10.0 |
| Gated Memory Policy | 70 | 30 | 20 | 0 | 30.0 |
| Ours, one context | 60 | 20 | 40 | 60 | 45.0 (46% recovery) |
| Ours plus ensemble | 100 | 50 | 70 | 70 | 72.5 (80% recovery) |
Table 1: Success under actuation bias, in percent (paper Table I). Each task uses 20 episodes and up to six trials per episode.
| Joint-encoder offset | Transport corn | Insert tube | Cap marker | Assemble ring | Average |
|---|---|---|---|---|---|
| Base under shift | 0 | 0 | 0 | 20 | 5.0 |
| Base plus shift data | 50 | 0 | 0 | 10 | 15.0 |
| Gated Memory Policy | 85 | 20 | 20 | 40 | 41.3 |
| Ours, one context | 80 | 25 | 30 | 50 | 46.3 (49% recovery) |
| Ours plus ensemble | 100 | 50 | 60 | 90 | 75.0 (84% recovery) |
Table 2: Success under joint-encoder offset, in percent (paper Table I). Proprioception looks deceptively normal in this condition, increasing the importance of visual context.
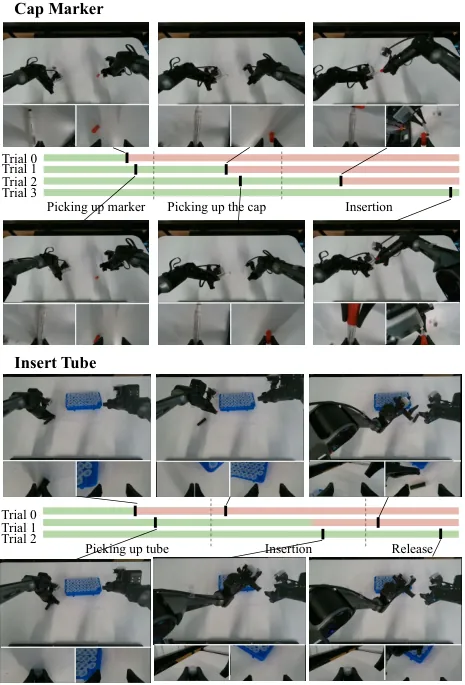
Figure 4: Qualitative iterative recovery (paper Figure 5). The green-to-red boundary marks the first visually identifiable failure; accumulated context moves the policy from failed grasps toward successful insertion and release.
Deployment on New Workstations
The controlled shifts are useful for scientific analysis, but deployments also contain combinations of real mechanical differences. The authors therefore test ring assembly on the workstation used to collect demonstrations and on two new workstations without robot hardware calibration. The base policy scores 95% on the original station and falls to 70% and 10% on the new stations.
With context from at most two trials, Self-Adaptive VLA raises the new-station scores to 90% and 50%. This is stronger evidence that the learned context identifies combinations of shift beyond the exact two-parameter evaluation. It is also a clear boundary: the harder new station recovers only half of its lost success, so the result does not establish permanent calibration-free operation.
| Workstation | Base policy | Self-Adaptive VLA, up to 2 trials | Absolute change |
|---|---|---|---|
| Original demonstration station | 95% | — | Preserves nominal capability |
| New station A | 70% | 90% | +20 percentage points |
| New station B | 10% | 50% | +40 percentage points |
Table 3: Ring assembly across workstations (paper Figure 9). Context is collected once during initial deployment and can then be reused for routine operation on that station.
Why Token Addition Works
To study the learned geometry, the authors isolate hardware axes in the Insert Tube task. They collect ten trajectories for each positive and negative direction of six signed degrees of freedom, average the context token within each type, and compute pairwise cosine similarity. Opposite signs of the same axis have cosine similarity between $-0.987$ and $-0.991$, while different axes are close to zero. The encoder therefore does more than encode a generic failure severity; it learns directions aligned with individual hardware degrees of freedom.
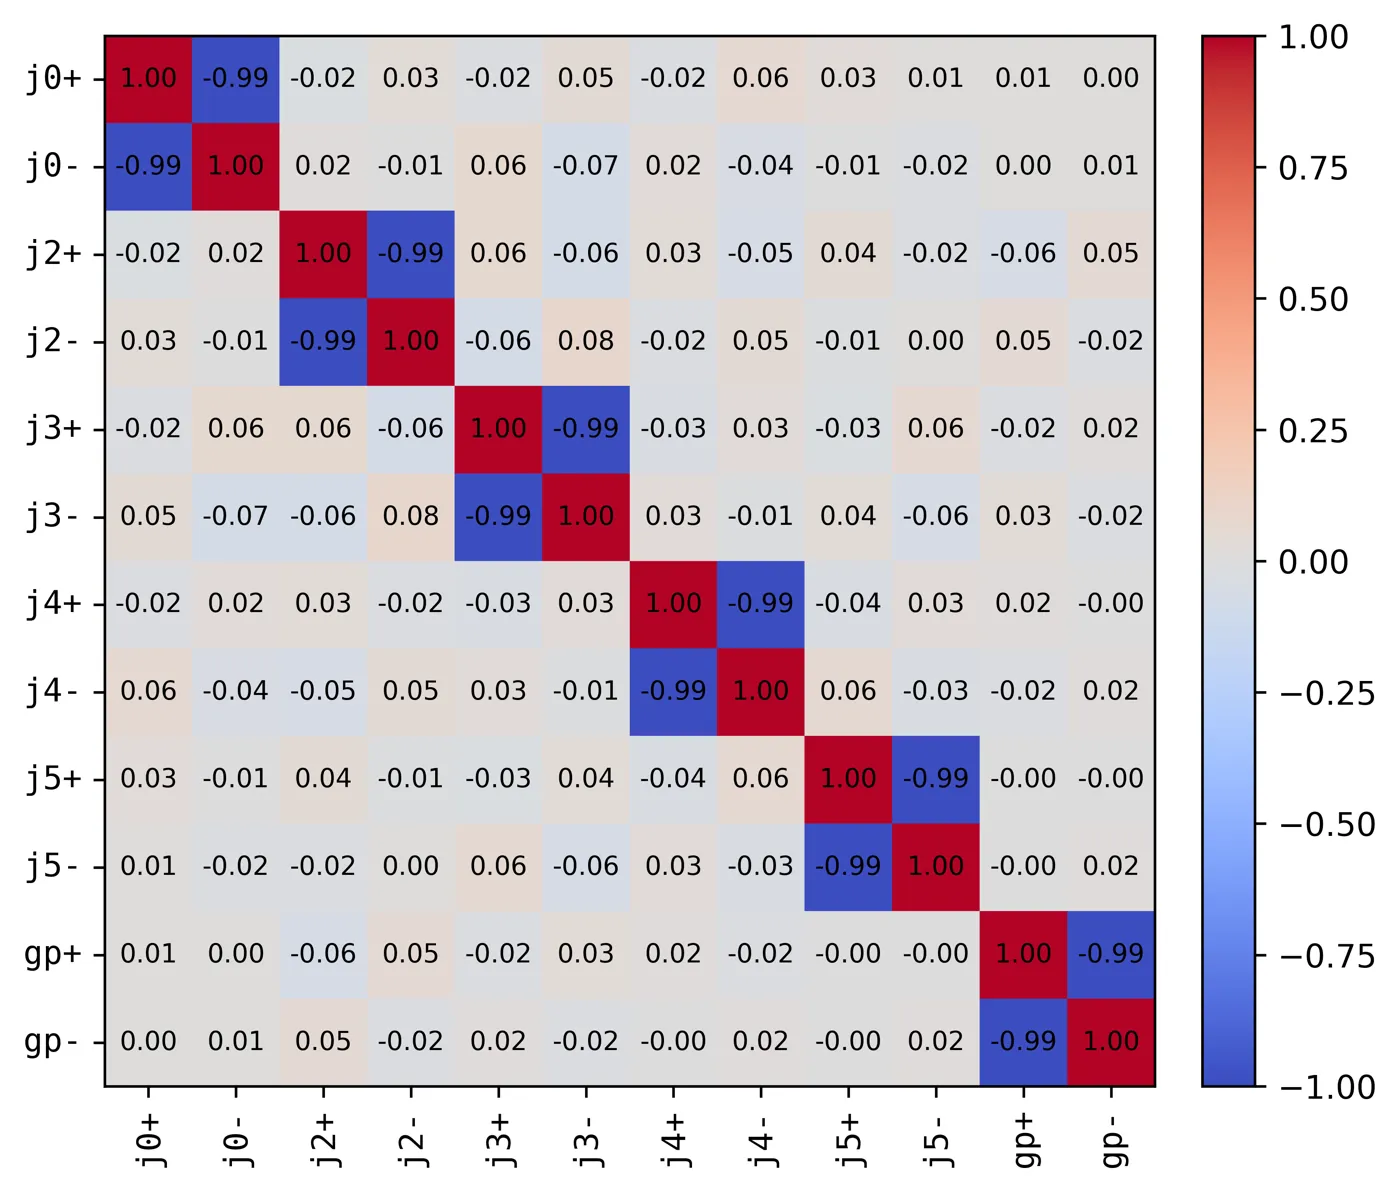
Figure 5: Pairwise context-token cosine similarity (paper Figure 7a). Opposite signs of the same axis point in nearly opposite directions, while cross-axis similarity is close to zero.
A principal-component analysis shows that the first two components explain 23% and 17% of the variance, so the representation is not organized on one scalar failure axis. Mean within-type spread is 0.27, compared with a mean inter-centroid distance of 10.27. Six components explain 99.8% of the variance, while the seventh contributes 0.05%. The effective dimension matches the six shift axes, with tight clusters and substantial separation between different shifts.
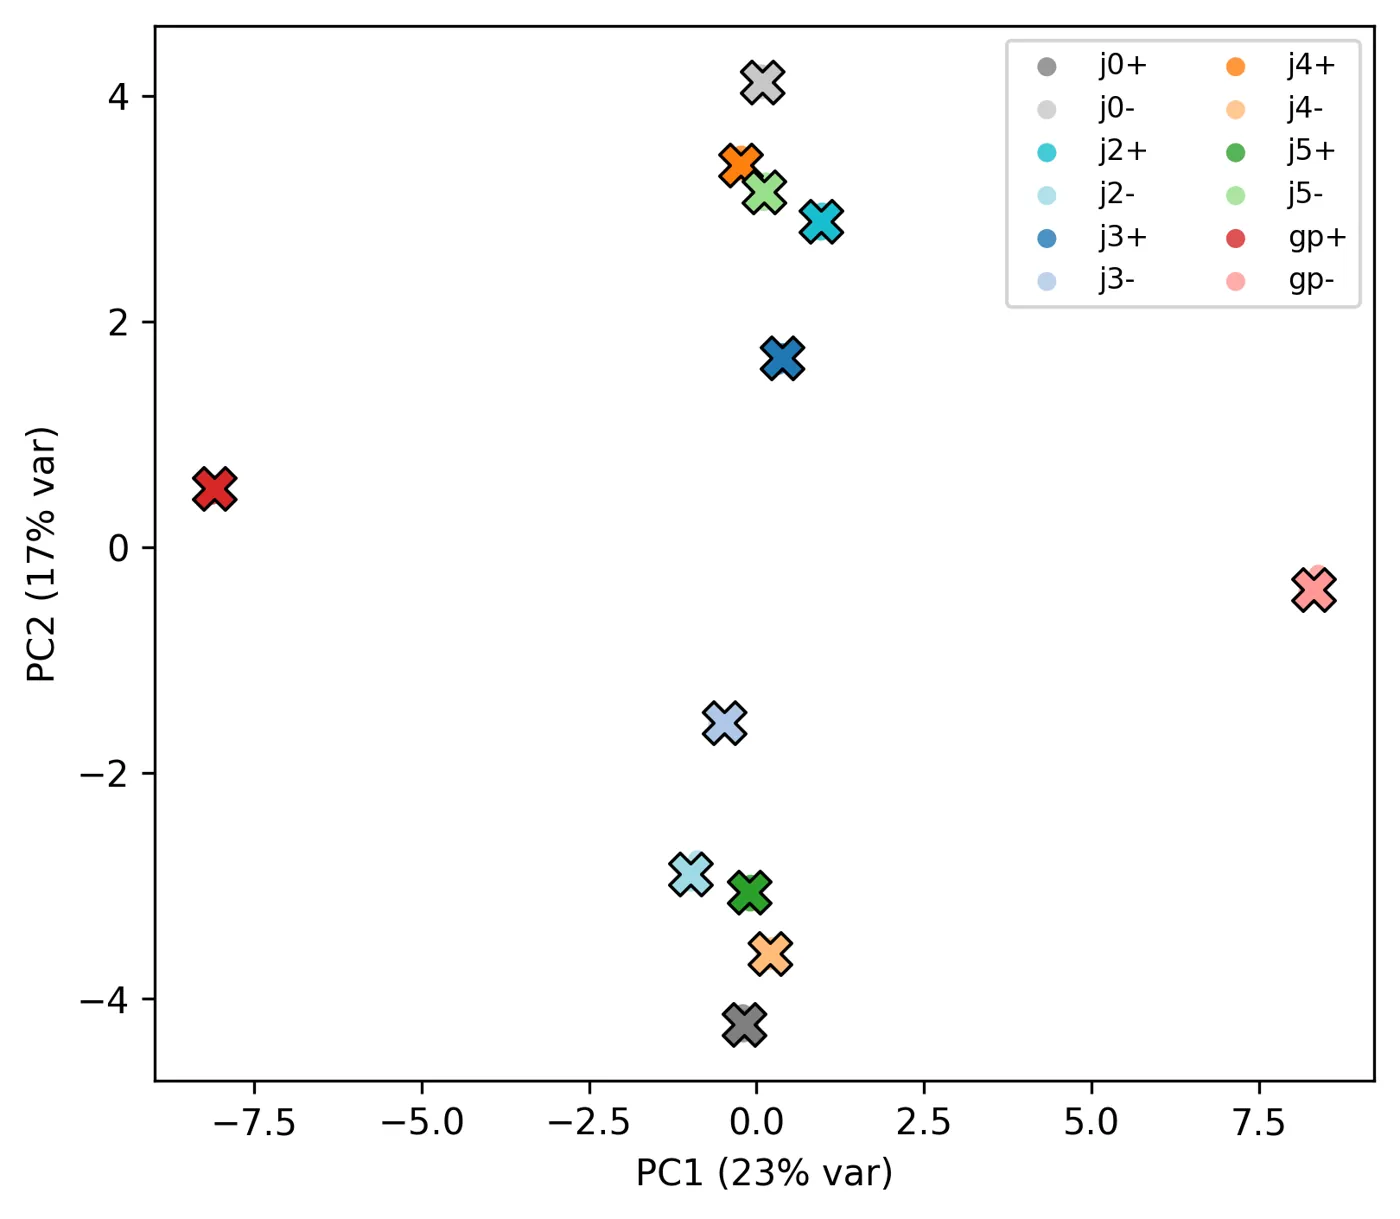
Figure 6: PCA projection of context tokens (paper Figure 7b). Crosses mark per-type means and colored points are the ten trajectories for each shift type; the first two components explain 40% of the variance.
These measurements provide an empirical explanation for Equation 8, but they also limit its interpretation. Six components explaining 99.8% applies to the tested configuration-space shifts and data distribution. It does not prove that camera pose errors, floor friction, payload variation, and tool wear can all be represented as independent linear directions. If those factors interact, token addition may entangle rather than isolate them.
Ablations and Failure Behavior
The context-modality ablation uses the Cap Marker task. Removing proprioception reduces success under both shifts, with a larger loss under actuation bias where commanded and measured joints directly expose the error. Replacing each frame's CLS token with a full set of two-dimensional patch tokens produces no significant improvement. The result suggests that a compact representation of object-robot relative motion is sufficient for identifying these hardware errors, even though a full spatial map contains more information.
Gated Memory Policy is the strongest memory baseline. It reaches 28% average recovery under actuation bias but varies sharply by task, and under encoder offset it remains at 20% on both Insert Tube and Cap Marker. The authors attribute this behavior to a fixed attention window that overwrites older context, trapping the policy in repeated error modes. Additive context tokens preserve earlier directional evidence and continue improving through later trials.
The qualitative timelines expose why a single scalar correction is unlikely to solve every case. The first attempt fails to grasp. The first context allows one arm to compensate but leaves residual error on the other. A later context produces a successful grasp but an inaccurate insertion. Additional evidence then resolves the contact-stage error. Adaptation is thus a sequence of revealing smaller errors after larger ones are corrected, not a one-shot classification of a known label.
Limitations and Risks
First, the method directly models shifts in the robot's configuration space. The authors explicitly leave camera-calibration error and broader environmental discrepancies for future work. Actuation bias and encoder offset are common and important examples, but real deployments may combine kinematic, perceptual, dynamic, and object-level changes. The reported 80%-84% recovery should not be generalized to every form of distribution shift.
Second, a static context does not support in-trial adaptation. The encoder runs after a full failed trial to avoid additional cost inside closed-loop control. If the hardware or environment changes during a trajectory, the policy cannot update its context at control frequency. The approach also assumes that collecting a sub-optimal rollout is safe. For irreversible or safety-critical tasks, an initial diagnostic failure may be unacceptable.
Third, the main evidence comes from 20 episodes per task and six trials per episode under sampled shift distributions. The new-workstation study adds valuable realism, but it covers only ring assembly. More embodiments, objects, wear stages, and stratified confidence intervals would be needed before treating the average recovery as an operational guarantee.
Fourth, additive tokens have a structural risk. The controlled latent analysis supports near-orthogonal directions, but a longer deployment history or a noisy trial could add irrelevant components. The experiments stop at six trials and do not characterize slow drift, forgetting, outlier rollouts, or recovery after maintenance changes the hardware again.
Fifth, the public repository does not release the implementation, training configuration, checkpoints, or data. The method diagram and videos are useful, but independent reproduction would require rebuilding the contextualized data pipeline, DINOv3 integration, AdaLN modulation, flow-matching training, and multi-trial combination. For a paper motivated by scalable deployment and maintenance, that is a substantial engineering gap.
Engineering Implications
The key design decision is not a larger memory module; it is defining what needs to be remembered. For hardware adaptation, the useful representation is not a full video window but a compact vector that separates joint directions, gripper width, and multi-arm combinations. Once that vector is computed after a trial, the VLA's high-frequency computation barely changes. This is closer to a deployable fleet-maintenance mechanism than online backpropagation through long histories.
The data pipeline offers a second lesson. Because the training system knows the synthetic offset it injected, it can produce shifted expert targets automatically. Failed rollouts identify the condition, while expert trajectories define the desired behavior. Keeping those roles separate is more stable than labeling all failed actions as negative examples and prevents the policy from imitating its own error.
Recovery rate is still not the final operational metric. A real system also needs to know how many failures are safe, whether context persists across reboots, how to reject an unreliable context, and how to detect that maintenance has invalidated an old token. The paper opens a clear path to those questions, but it does not close them.
Conclusion
Self-Adaptive VLA shows that the deployment fragility of a memoryless VLA can be reduced through post-training context rather than continuous recalibration. It encodes hardware-shift failures into a static token, injects the token through AdaLN, and sums tokens from multiple trials for iterative compensation. Across four precise manipulation tasks, one trial recovers roughly half of the lost performance and up to six trials recover roughly 80%. The latent analysis further shows that individual hardware axes align with distinct, nearly orthogonal directions.
The next step is to broaden both the shift model and the safety model. Camera calibration, contact dynamics, and tool wear could be included in the context, and the policy could update or reject context when evidence is weak. A useful future system should not merely accumulate every failed trial; it should decide which trials are informative, whether the context is trustworthy, and when the safest action is to collect a targeted diagnostic rollout.
Key Takeaways
A failure is not a behavior to imitate; it is a diagnostic signal. Self-sampled trajectories identify the hardware condition while expert data continues to define the correct action.
Putting memory outside the control loop is what makes adaptation practical. A context token is computed once per trial, leaving the original VLA as the high-frequency controller while adding only a conditioning-vector sum.
References
Paper: https://arxiv.org/abs/2609.30092
Project: https://icefoxzhx.github.io/self-adaptive-vla
Official repository: https://github.com/Icefoxzhx/self-adaptive-vla