PAPER DEEP DIVE
Agentic World Action Models
Recent world action models provide visual foresight and future prediction for robot manipulation, but lack explicit mechanisms for compositional skill reuse. Agentic robotics combines code-based planning and reasoning with reusable skills, but often lacks predictive grounding in physical dynamics. We introduce AW-0, an agentic world action model framework that integrates code-based planning with joint video and action prediction. We jointly model code, future video, and robot actions as three coupled generative streams within a unified mixture-of-transformers architecture. Within this architecture a code expert generates parameterized skill routines and control logic while video and action experts generate future visual states and low-level motor commands. Code serves two complementary roles: it structures multi-step prediction and control within the world model and represents skills as reusable programs for subsequent agentic execution. We further introduce an automated curation pipeline that labels robot and human video trajectories with aligned programs and consolidates recurring routines into reusable skill libraries. Evaluations on RoboTwin 2.0 and physical bimanual manipulation tasks show improved task performance over VLA and WAM baselines, alongside gains in language following, semantic reasoning and robustness, demonstrating that agentic code enables connection between planning, prediction and execution within WAMs.
Paper Metadata
Title: Agentic World Action Models (AW-0)
Authors and affiliations: Zhuoyang Liu, Dantong Niu, Botong Zhang, Boning Shao, Jing Wang, Ruijie Zheng, Yuvan Sharma, Runyu Lu, Jiaming Liu, Renrui Zhang, Roei Herzig, Yutong Bai, Ken Goldberg, Danfei Xu, Yuke Zhu, Guanzhi Wang, Linxi "Jim" Fan, and Trevor Darrell; UC Berkeley, NVIDIA, and the University of Pennsylvania. The first four authors contributed equally; Yuke Zhu, Guanzhi Wang, Linxi Fan, and Trevor Darrell jointly advised the work.
Links: arXiv:2610.30136v1 [cs.RO], 21 October 2026; paper https://arxiv.org/abs/2610.30136 ; project page https://agentic-wam.github.io/ ; code https://github.com/ZhuoyangLiu2005/agentic-wam ; pretrained checkpoint https://huggingface.co/miniFranka/agentic-wam-pretrain-yamego3k-soup-e1 .
Code status: The official repository is released under BSD 2-Clause and contains pretraining, downstream fine-tuning, real-robot deployment, and RoboTwin 2.0 evaluation code. The README is explicit about scope: full training code and one pretrained checkpoint are public, but the pretraining corpus and the Cosmos-Predict2.5-2B checkpoint used to initialize the video expert are not distributed. Reproducing pretraining from scratch therefore still requires missing data and initial weights, while task fine-tuning from the released checkpoint is a workable path.
One-Sentence Summary
AW-0 places skill programs, future video, and continuous actions inside a single mixture-of-transformers and denoises all three jointly: the code expert emits a parameterized skill plan, the video expert imagines the coming frames, and the action expert produces an action chunk. It reaches 80.8% success on the clean RoboTwin 2.0 setting and a mean score of 71.1% across eight real bimanual tasks, 25.1 points above the strongest baseline; hybrid execution then lifts the randomized setting from 20.6% to 29.2% while dropping the clean setting to 63.1%.
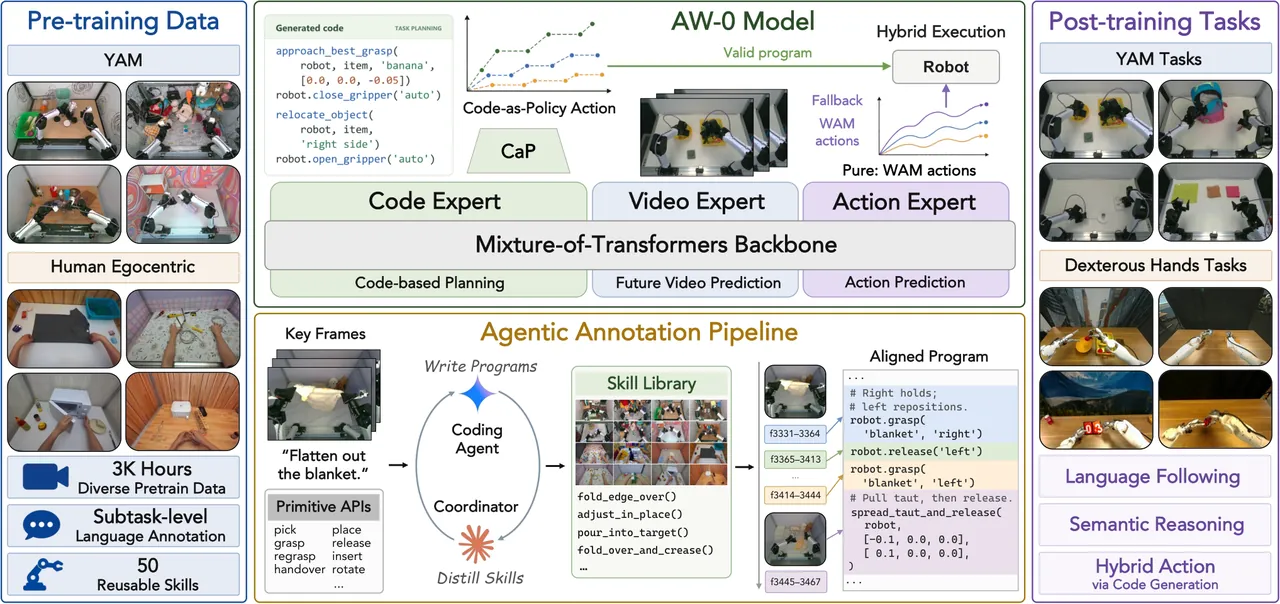
Figure 1: AW-0 overview (paper Figure 1). The model treats the skill program, future video, and actions as three coupled streams generated in one denoising loop; the program can condition the action expert or, under hybrid execution, be interpreted as executable skill code.
Background and Motivation
Robot manipulation models have moved over the past decade from task-specific visuomotor policies toward foundation models that connect vision, language, and action. In parallel, video prediction has long served as a signal for learning how the world evolves: imagine the future first, then decide what to do. World action models merge these two lines, using predicted future representations to constrain control so that a policy does not merely fit a mapping from current observation to action but also anticipates object motion, contact, and the consequences of low-level commands.
Predicting video and action chunks, however, does not answer a longer-horizon question: how should a multi-step task be decomposed, which reusable skills should be invoked, how should skill parameters bind to the current scene, and how do subtasks chain together. A pure video diffusion model can produce a plausible future without ever making explicit the skill structure of "grasp the zipper, pull it open, then place the object inside the bag." The problem grows with parameter count: the model must cover both visual dynamics and skill composition, while the training signal only says what the next frame and the next action segment are.
Agentic robots supply complementary structure. A programmatic execution stack can select skills and tools, bind parameters to the scene, track progress, and replan when observations change. Code is therefore a dense, composable, and inspectable intermediate representation. Yet a conventional code agent often lacks predictive support for real physical dynamics: it knows which skill to call but not where that skill will take the world in a contact-rich scene.
AW-0 starts from the idea that these two capabilities should constrain each other inside one model. Code is no longer a planner bolted onto the outside of a policy; it is a generative stream denoised together with video and actions. The video and action experts can read code at every layer, and the code expert can see the current multi-view observation. Code thus organizes multi-step prediction while remaining a reusable program for a downstream agent to execute. The paper's central claim can be stated in one line: the program gives the world model a semantic skeleton, and the world model gives the program physical grounding.
Problem Formulation and Preliminaries
The model represents a skill program as a sequence of discrete tokens, a future observation as continuous video latents encoded by a pretrained variational autoencoder, and robot motion as an action chunk over a fixed horizon. These are written as the program, the future video, and the action. The conditioning context combines the current multi-view observation, the language instruction, the robot state, and a compact memory of preceding program slices. Joint generation is therefore a probabilistic model over all three modalities conditioned on the scene and the instruction:
$$\mathcal{C}_{t}=\{\mathcal{O}_{t},L,S_{t},M_{t}\},\qquad p_{\theta}(C_{0},Z_{0},A_{0}\mid\mathcal{C}_{t}).\tag{1}$$
Action chunks cover a fixed horizon, 32 steps by default in the downstream experiments. Robot states and actions are mapped into a 64-dimensional space shared across embodiments: each side contains a 9-dimensional end-effector pose, 22-dimensional dexterous-hand joint angles, and a 1-dimensional parallel-gripper opening, so the two sides sum to exactly 64. Dimensions unused by an embodiment are zeroed without normalization, while the remaining dimensions are normalized per dimension by the 1st and 99th percentiles. This lets the parallel gripper of YAM and the 22-DoF hands of Tianji–Sharpa share the same input and output projections even though the degrees of freedom they actually use differ.
$$S_{t},A_{t}\in\mathbb{R}^{64},\qquad 64=2\times(9+22+1).\tag{2}$$
Continuous modalities are modeled with flow matching. A noise level is drawn separately for video and action, the real sample is linearly interpolated with Gaussian noise, and the model regresses the velocity pointing from noise to data. The noise level is not sampled uniformly but passed through a shift map that concentrates training mass in the high-noise regime; the video side additionally uses Beta sampling from the pretrained distribution to preserve the noise curriculum of the original video diffusion model. The interpolation is written as:
$$X_{\sigma_{m}}^{m}=(1-\sigma_{m})X_{0}^{m}+\sigma_{m}\epsilon_{m},\qquad \epsilon_{m}\sim\mathcal{N}(0,I),\qquad \sigma_{m}=\phi_{\gamma_{m}}(u_{m})=\frac{\gamma_{m}u_{m}}{1+(\gamma_{m}-1)u_{m}}.\tag{3}$$
The code side uses discrete absorbing masking. Each program token is replaced by a mask token with probability r, and cross-entropy is computed only at masked positions. Visual prefixes, instructions, and padding do not contribute to the program loss, and every non-empty training target masks at least one program token so that no degenerate batch lacks supervision. The corruption is:
$$\widetilde{c}_{i}=\begin{cases}[\mathrm{MASK}],& b_{i}=1,\\ c_{i},& b_{i}=0,\end{cases}\qquad b_{i}\sim\mathrm{Bernoulli}(r).\tag{4}$$
Method: How the Three Generative Streams Couple
The backbone is a mixture-of-transformers with three modality experts. Each expert keeps its own query, key, and value projections, layer normalization, and feed-forward network, but at every layer the experts exchange information through one masked joint attention operation. Attention inside an expert is bidirectional; across experts it is blockwise causal in the order code, video, action. Code can see the current observation and instruction, video can see code, and action can see both code and video. The ablation changes this order from "video to action" and "video to code to action" to "code to video to action" and observes a performance change, which indicates that letting video generation read code is not incidental wiring but the channel through which a semantic plan enters future prediction.
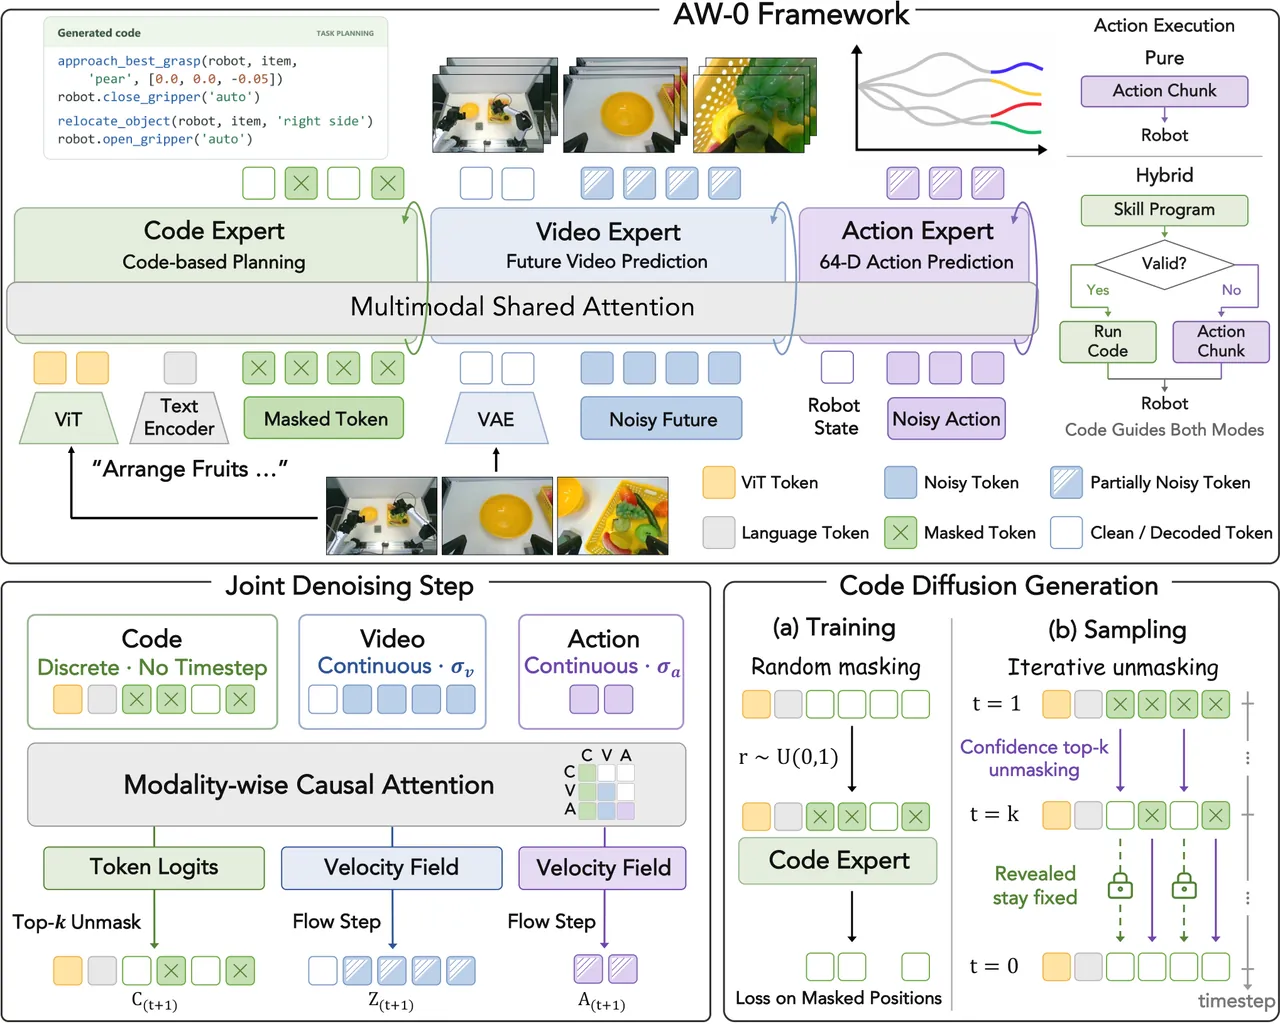
Figure 2: AW-0 framework (paper Figure 2). The code expert turns multi-view observations and the instruction into a skill program; the video expert, initialized from Cosmos-Predict2.5, predicts future latents; the action expert emits continuous action chunks. All three exchange information through joint attention across 28 layers, ordered code, video, action.
All three experts have 28 layers, and queries, keys, and values are projected into a common 2048-dimensional attention space with 16 heads of width 128 per layer. The code expert is built on a SDAR-1.7B body, with token embeddings, layer normalization, feed-forward networks, and the vocabulary head frozen; only the joint attention projections and modulation parameters are trained. The visual side uses a frozen Qwen3-VL-2B tower followed by a trainable merger. The video expert is initialized from the Cosmos-Predict2.5-2B DiT and switched to a frozen Wan2.2 variational autoencoder with 48 latent channels; because the channel count changes, the input and output projections of the video DiT are reinitialized. The action expert is a separate action DiT initialized from scratch and additionally receives robot-state conditioning.
On the observation side, each view at 224×320 is spatially merged into 70 visual tokens, giving 210 prefix tokens for three views. Training gives the instruction and program a shared budget of 512 tokens, with the visual prefix appended separately; inference uses a program canvas of 128 tokens by default. The video side samples nine frames at temporal offsets from 0 to 32, uses only the first frame as the observation condition, and treats the rest as prediction targets. This separates "seeing the present" from "imagining the future": the current frame enters the condition cleanly, while future frames start from noise.
The code expert also maintains a memory of preceding program slices. A single observation is often insufficient to judge task progress, so history is compressed into 32 learnable memory slots that are read back into the code stream as prefix tokens. During training the buffer holds preceding annotated slices and is replaced with the model's own predictions with some probability; at inference it resets each episode and grows with every decoded slice. The memory is not an external text summary but a continuous representation that participates in attention alongside code tokens. In the official configuration this memory is disabled by default, so reproducing the full method requires turning it on explicitly.
At every joint denoising step the three experts simultaneously emit code logits, video velocity, and action velocity. The code stream supplies planning context to video and action, and the action expert reads video representations, so the modalities co-evolve throughout the iteration rather than generating code first, freezing it, then generating video, and finally actions. The code canvas is revealed by confidence ranking: each step commits the most confident masked positions until the whole canvas is filled. This decoding order matches the random masking distribution used in training and avoids the exposure bias of autoregressive models that see ground-truth prefixes during training and their own prefixes at inference.
The training objective must balance video generation against predictive guidance. Video noise is sampled from a mixture of the pretrained distribution and a uniform distribution, then importance weights map each target back to its own distribution: the video term uses the pretrained density weight, while action and code use the uniform reference weight. After clipping, weights are normalized per batch to unit mean so that no modality's loss scale overwhelms the others. In expectation form:
$$u_{v}\sim q(u)=\alpha p_{\mathrm{pre}}(u)+(1-\alpha)p_{\mathrm{ref}}(u),\qquad p_{\mathrm{ref}}=U(0,1).\tag{5}$$
$$w_{v}(u)=\frac{p_{\mathrm{pre}}(u)}{q(u)},\qquad w_{g}(u)=\frac{p_{\mathrm{ref}}(u)}{q(u)},\qquad \mathcal{L}=\mathbb{E}_{u_{v}\sim q}\!\left[\lambda_{v}\bar{w}_{v}\ell_{v}+\bar{w}_{g}(\lambda_{a}\ell_{a}+\lambda_{c}\ell_{c})\right].\tag{6}$$
The paper sets the mixture coefficient to 0.5, the loss weights for video, code, and action to 1, 0.5, and 1, and both the video and action shifts to 5. This weighting places code in an auxiliary role: it is not meant to dominate video at the pixel level but to provide a stable semantic condition at lower weight. The ablation shows that removing code lowers inference latency from 0.23 s to 0.19 s, a saving of only 0.04 s, while degrading all eight real tasks, which indicates that the benefit of the code stream is not a marginal gain bought with more computation.
The diagram below traces the actual data flow through one replanning step. It highlights two points that are easy to conflate when reading the paper: in default mode code is only a symbolic plan and is never executed; only hybrid execution sends code to the interpreter, where an arbiter decides whether it takes over the current stage.
flowchart TD
    O["Multi-view observation O_t"] --> CTX["Conditioning context
observation, instruction, state, memory"]
    L["Language instruction L"] --> CTX
    S["Robot state S_t"] --> CTX
    M["Program memory M_t"] --> CTX
    CTX --> C["Code expert
masked discrete diffusion"]
    C --> C0["Skill program C_0
parameterized skill calls"]
    C0 --> V["Video expert
future latents Z_0"]
    C0 --> A["Action expert
action chunk A_0"]
    V --> A
    C0 --> D{"Hybrid execution?"}
    D -->|No| A
    D -->|Yes| G["Stage, dependency, syntax, allowlist, non-empty gates"]
    G -->|Pass| E["Interpreter executes the code slice"]
    G -->|Reject| A
    E --> R["Environment observation and next replan"]
    A --> R
Automatic Annotation and the Skill Library
The method only works if the training data contain programs time-aligned with video trajectories. The paper does not hand-write these programs. Instead it builds a three-stage automatic annotation pipeline. In the first stage one episode per task is sampled, Gemini 3.1 Pro writes subtask-level skill programs against low-level interfaces that are declared but not implemented, and Claude Code running Claude Opus 4.8 acts as coordinator, distilling recurring cross-task fragments into skills. In the second stage the skill library is frozen and sampled episodes are relabeled with the final vocabulary, producing a cache of subtask-to-program entries. In the third stage the remaining corpus is labeled: if the contact and motion evidence of the current subtask matches a cached entry, that entry is reused; otherwise a coding agent writes a new annotation and writes it back to the cache.
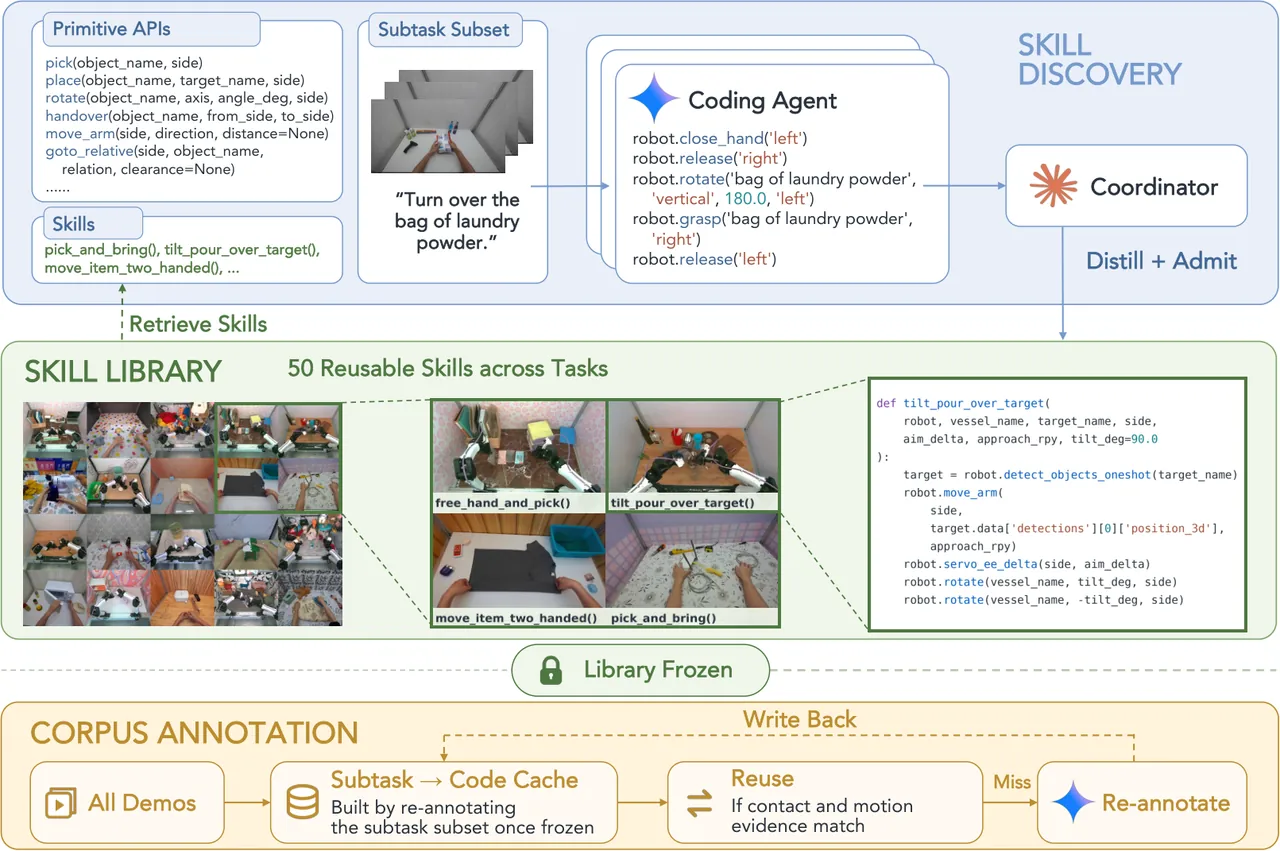
Figure 3: Automatic annotation pipeline (paper Figure 3). A coding agent writes subtask programs against predefined low-level interfaces; a coordinator distills repeated patterns into skills; once the library is frozen, cache entries are reused when contact and motion evidence match, and new annotations are generated only on a miss.
The result is 50 skill entries, 23 for the YAM parallel gripper and 27 for egocentric human demonstrations. Skills are not generic verbs such as "grasp" or "place" but concrete routines with contact semantics: pulling along a zipper seam, flattening fabric with alternating hands, unscrewing a threaded part with a ratcheting motion, or drawing a long object step by step out of a bag. Every low-level interface declares which contact events it produces, so a program can be aligned with contact evidence in the demonstration rather than relying only on visual similarity between frames.
The pretraining corpus combines two real data sources. The YAM portion has 73,101 episodes, 1,919.3 hours, and 279 tasks, averaging 13.5 program slices per episode; the egocentric human portion has 175,541 episodes, 993.9 hours, and 327 tasks, averaging 6.2 slices per episode. Together they amount to 248,642 episodes, 2,913.2 hours, 606 tasks, and 2,075,373 slices. Human data has only a single head-mounted camera, so the same view is replicated into all three input slots during training, and hand motion is retargeted into 22-dimensional joint targets per hand.
| Source | Episodes | Hours | Tasks | Program slices | Slices per episode |
|---|---|---|---|---|---|
| YAM robot | 73,101 | 1,919.30 | 279 | 986,314 | 13.5 |
| Egocentric human | 175,541 | 993.91 | 327 | 1,089,059 | 6.2 |
| Total | 248,642 | 2,913.22 | 606 | 2,075,373 | 8.3 |
Table 1: Pretraining corpus statistics (paper Table 7). A slice is a time-aligned program unit, not a video frame; YAM has about 2.2× the slice density of the human data, reflecting finer subtask segmentation in robot demonstrations.
Training Recipe and Implementation Details
Pretraining first learns a unified generative prior on the large YAM and human corpora, after which each downstream task is fine-tuned jointly for 20 epochs on 100 demonstrations. Real-robot tasks reuse the same optimizer, warmup, and mixed-precision settings, but batch size and learning rate are adjusted per task: the YAM configuration uses batch size 4 per GPU, gradient accumulation 1, learning rate 10⁻⁴, and weight decay 10⁻²; the RoboTwin configuration uses two eight-GPU nodes, batch size 6 per GPU for an effective batch of 96, learning rate 2×10⁻⁴, weight decay 10⁻², and 100,000 optimization steps. Downstream fine-tuning transfers shape-compatible pretrained parameters and reinitializes the action and state projections when the embodiment dimensionality changes.
The RoboTwin 2.0 training set contains 50 tasks with 50 clean demonstrations each, for 2,500 episodes; every task is rolled out 50 times, and the reported numbers average success over the clean and randomized settings. Randomization covers background and tabletop textures, lighting, table height, and distractors. Real-world evaluation uses eight tasks, four on YAM and four on Tianji–Sharpa; each task is fine-tuned on 100 demonstrations and evaluated with three training seeds times 16 rollouts, with randomized initial object poses and an additive rubric that awards partial credit per substep.
Both real platforms provide three RGB inputs: a head or overhead camera looking at the tabletop and left and right wrist cameras looking at the local manipulation area. YAM is a fixed-base dual 6-DoF arm with a parallel gripper, teleoperated leader-to-follower with a trigger controlling gripper opening; Tianji–Sharpa is a Tianji humanoid torso with two 22-DoF Sharpa hands, collected with Manus gloves and PICO trackers for wrist pose, with finger motion retargeted to 22-dimensional joint targets. AW-0 uses the same 64-dimensional state-action representation on both platforms, but YAM predicts relative end-effector pose plus an absolute gripper target, whereas Tianji–Sharpa predicts relative end-effector pose plus absolute finger joint targets.
Experimental Results
The main RoboTwin 2.0 result splits cleanly. AW-0 in default mode reaches 80.8% in the clean setting, 16.0 points above the strongest baseline WLA at 64.8%; under randomization it drops to 20.6%, below the 27.7% of π0.5 but still above DreamZero at 17.6%. Hybrid mode raises the randomized setting to 29.2% while pulling the clean setting down to 63.1%. The two modes average 50.7% and 46.2%, respectively, which suggests that default mode suits controlled environments while hybrid mode suits environments with strong visual distribution shift.
| Method | Clean success (%) | Randomized success (%) | Average (%) |
|---|---|---|---|
| π0.5 | 54.9 | 27.7 | 41.3 |
| DreamZero | 33.6 | 17.6 | 25.6 |
| EgoScale | 26.2 | 2.9 | 14.5 |
| WLA | 64.8 | 3.6 | 34.2 |
| AW-0 default | 80.8 | 20.6 | 50.7 |
| AW-0 hybrid | 63.1 | 29.2 | 46.2 |
Table 2: Main RoboTwin 2.0 results (paper Table 1). Fifty tasks with 50 rollouts each; hybrid mode uses separately collected code-as-policy demonstrations, so the comparison is between two complete configurations rather than a switch of execution mode alone.
The eight real-world tasks span a wide range: arranging fruit, packing a backpack, replacing a lightbulb, and folding towels on YAM; picking fruit with tongs, dealing poker, flipping a scoreboard, and solving a Rubik's cube on Tianji–Sharpa. AW-0 averages 71.1%, against 46.0% for the strongest baseline DreamZero, a gap of 25.1 points. The largest advantages appear on the semantic-selection task "Arrange Fruits" (91.7% vs. 70.8%) and the fine bimanual coordination task "Solve Cube" (72.1% vs. 52.3%); the tool-use task "Fruits with Tong" rises from 7.3% for π0.5 to 54.2%, suggesting that the skill structure supplied by the code stream matters most for tool-mediated manipulation.
| Method | Arrange Fruits | Pack Backpack | Replace Lightbulb | Fold Towels | Fruits w/ Tong | Deal Poker | Flip Scoreboard | Solve Cube | Avg. |
|---|---|---|---|---|---|---|---|---|---|
| π0.5 | 70.8 | 49.7 | 63.8 | 81.7 | 7.3 | 13.1 | 26.3 | 36.1 | 43.6 |
| DreamZero | 53.3 | 36.7 | 67.4 | 79.8 | 22.6 | 37.1 | 28.4 | 42.5 | 46.0 |
| EgoScale | 37.5 | 27.3 | 60.2 | 53.3 | 17.6 | 25.6 | 40.8 | 24.9 | 35.9 |
| WLA | 39.6 | 29.6 | 56.0 | 74.6 | 14.2 | 22.9 | 29.7 | 52.3 | 39.9 |
| AW-0 | 91.7 | 64.6 | 75.0 | 84.4 | 54.2 | 58.3 | 68.8 | 72.1 | 71.1 |
Table 3: Real-world scores on eight tasks (paper Table 2). Three training seeds times 16 rollouts per task, scored additively by substep; the first four columns are YAM with a parallel gripper, the last four are Tianji–Sharpa with dexterous hands.
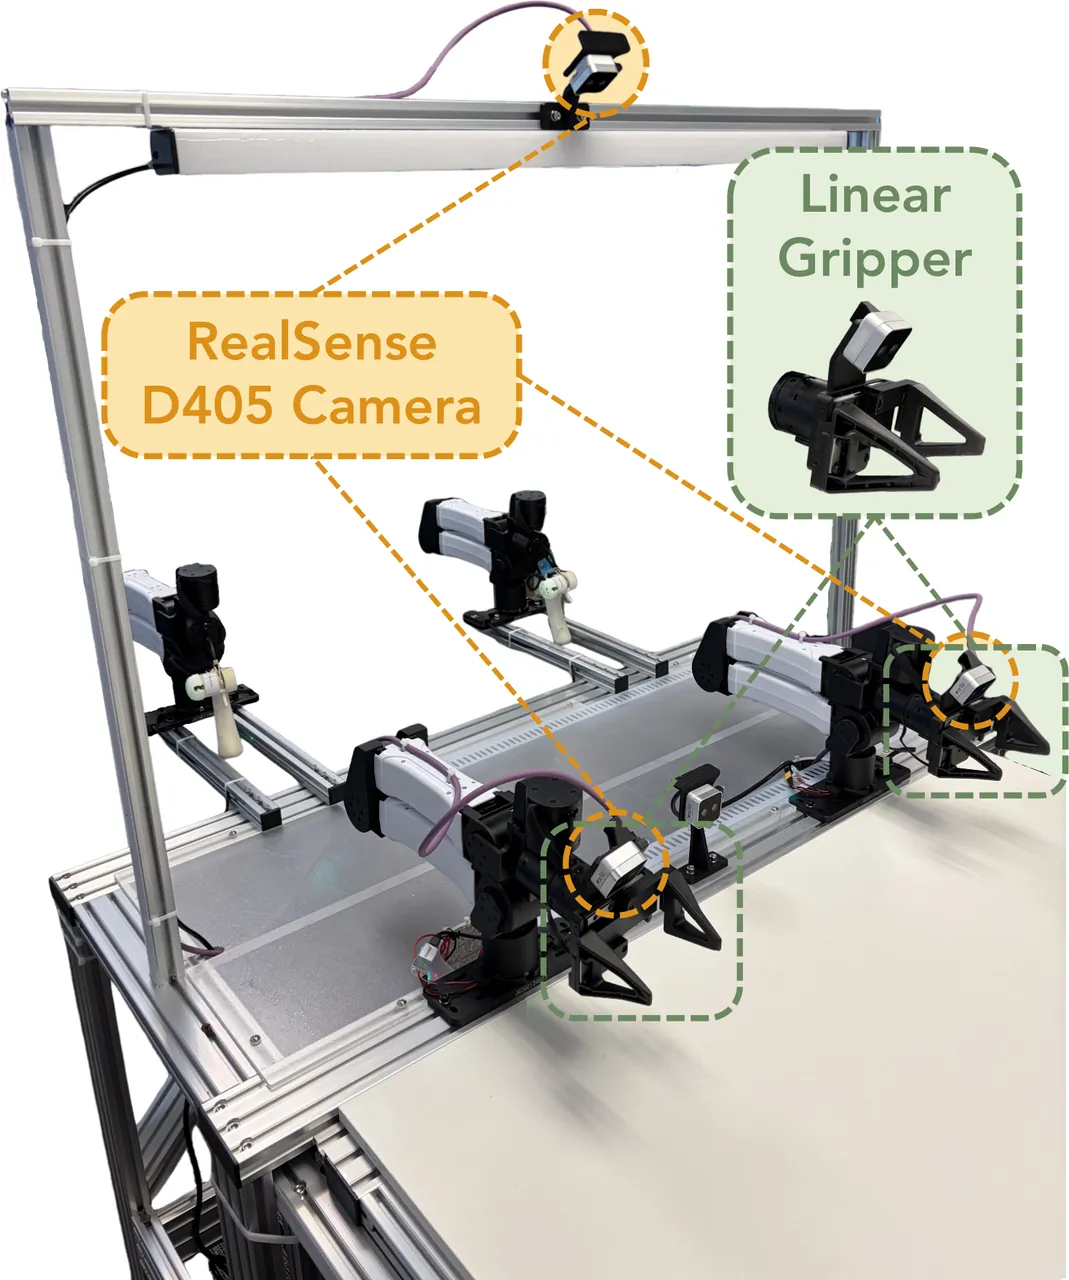
Figure 4: YAM platform (paper Figure 20a). Fixed-base dual 6-DoF arms with a parallel gripper, one RealSense D405 overhead and one camera per wrist; the bottom camera is not part of the policy input.
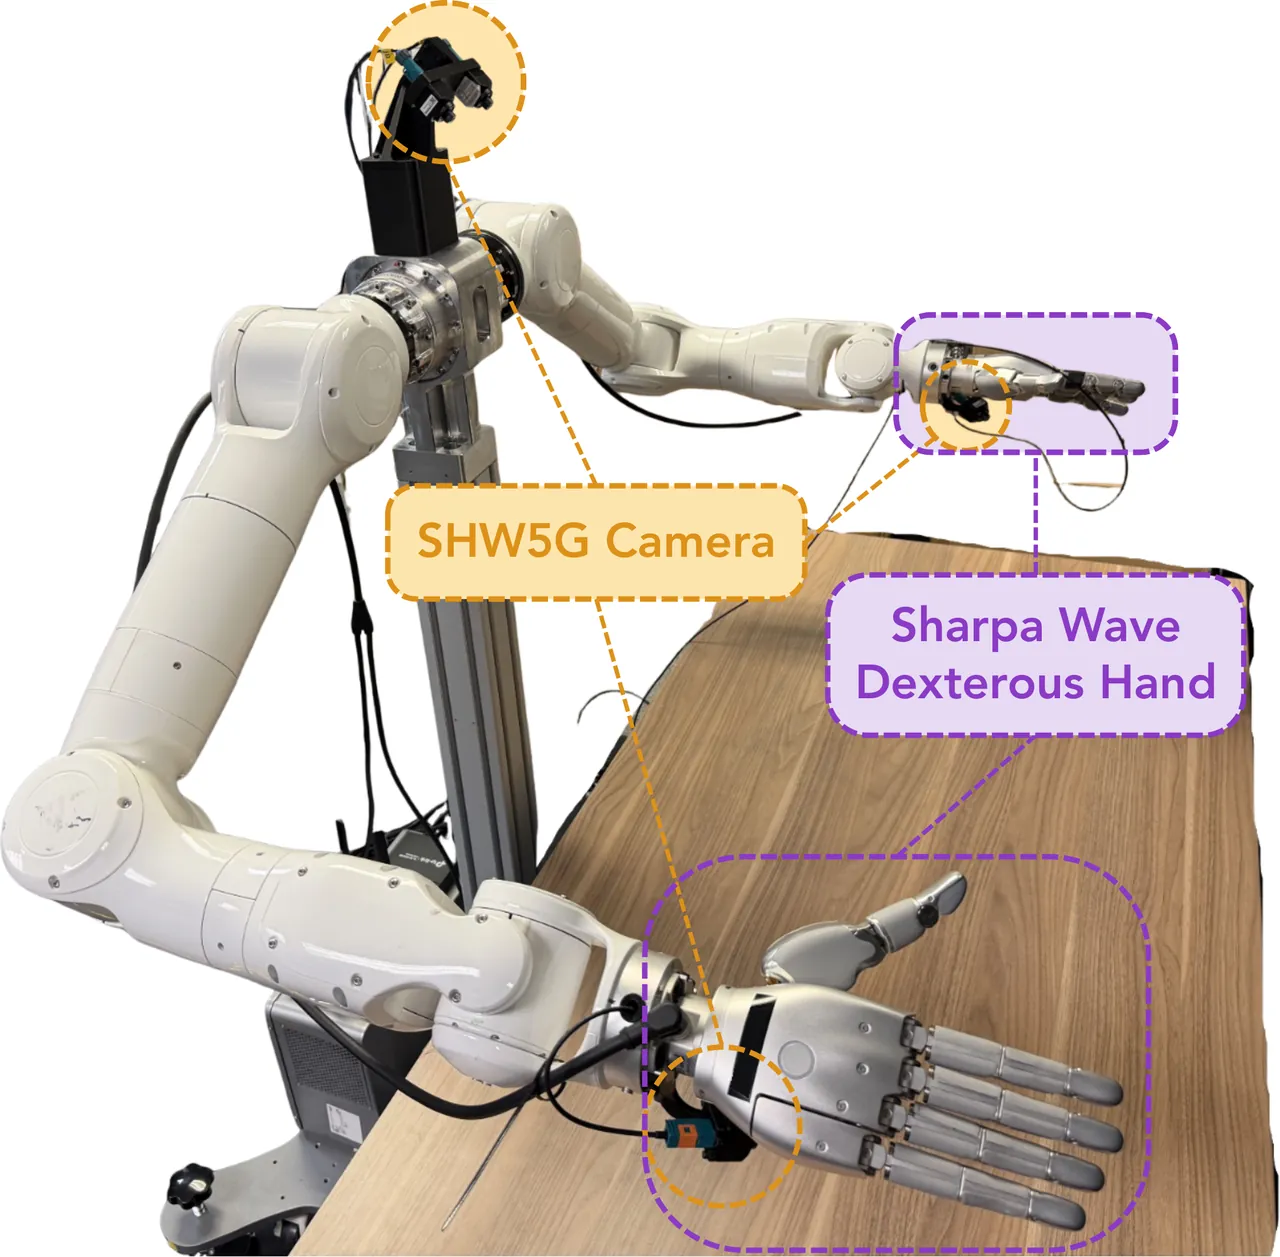
Figure 5: Tianji–Sharpa platform (paper Figure 20b). A Tianji torso carries two 22-DoF Sharpa Wave hands, with one SHW5G head camera and one camera per wrist.
How Code Enters Prediction: Qualitative Evidence
Two sets of future-frame comparisons show that code does not only affect the action head. The first instruction is "arrange the fruit so that only the mango remains in the left bowl." Given the same scene and similar initial observations, AW-0 directs the predicted interaction toward the mango; a variant that replaces code with a natural-language subgoal wavers between apple and mango; a model without the code stream goes straight for the apple. None of the three sees the final answer, so the difference comes from the conditioning representation: the object parameter inside the skill call turns the phrase "only the mango" into a concrete manipulation target.
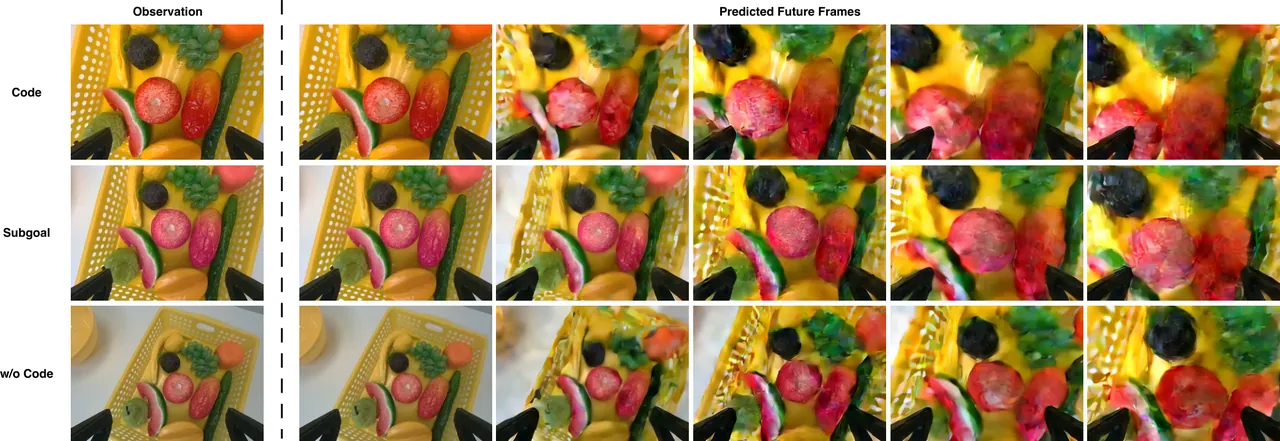
Figure 6: Future-frame prediction on Arrange Fruits (paper Figure 33). Left to right within a row is predicted time; AW-0 selects the object named by the instruction, while the language-subgoal and no-code variants show target ambiguity or error.
The second set covers the final phase of dealing a card into a narrow slot. This motion requires the hand, the card, and the slot to align simultaneously, and even a small offset leaves the card stuck at the opening. AW-0 predicts a card that stays aligned and enters the slot; the language-subgoal and no-code variants show blur and deformation around the finger-card contact and an incoherent insertion trajectory. The authors conclude that explicit skill calls and object parameters make it easier for the video expert to predict where the hand should carry the card, which in turn gives the action expert a more reliable predictive representation.
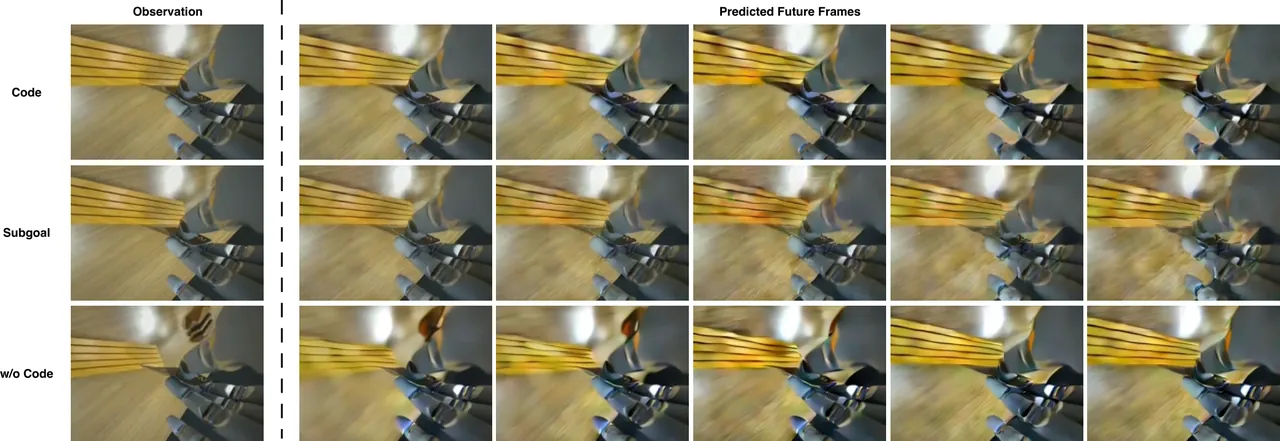
Figure 7: Fine insertion prediction on Deal Poker (paper Figure 34). AW-0 keeps the card aligned with the slot, while both control variants show blur at contact and a discontinuous insertion sequence.
Hybrid Execution: How Code and Action Chunks Divide Labor
In default mode code is only a symbolic plan and the action chunk is what actually drives the robot. Hybrid mode sends code to the interpreter: on every replan the policy returns both an action chunk and a code slice; the arbiter first checks whether the slice's stage is unfinished, whether it is not earlier than an already attempted stage, and whether its failure count is under the limit, then checks whether every variable it reads is defined in the shared namespace, and finally checks syntax, the allowlist, and non-emptiness. Code takes over the current stage only if every gate passes; once execution is attempted, the action chunk produced by the same forward pass is discarded, even if the code raises an exception, and the next round observes again and replans.
The paper states that the arbiter inspects the raw, unrepaired slice. The official code differs here: its arbiter calls a repair function before the gates, falls back to a nearest-neighbor repair path when repair fails, and then rechecks the allowlist. The paper's "inspect as written" and the released code's "repair, then inspect" are therefore not the same procedure. Both may be defensible, but a reproduction must say which one it uses, otherwise hybrid success rates are not directly comparable.
The effect of hybrid execution depends strongly on the environment. In the clean setting the action expert is already strong, and handing control to the code channel lowers success from 80.8% to 63.1%; in the randomized setting the action expert degrades to 20.6%, and on successful episodes the code channel carries 35.0% of simulation steps, lifting success to 29.2%. Over all episodes code accounts for only 8.5% of clean steps and 5.6% of randomized steps, because failing episodes run to the step limit almost entirely under direct action, which inflates the denominator. This accounting matters: "code carries 35% of steps in successful episodes" must not be read as "code carries 35% of steps overall."
| Setting | Episode set | Code-executed steps | Direct-action steps | Steps per episode |
|---|---|---|---|---|
| Clean | All | 8.5% | 91.5% | 26,720 |
| Clean | Success | 14.5% | 85.5% | 11,549 |
| Clean | Failure | 6.3% | 93.7% | 52,687 |
| Randomized | All | 5.6% | 94.4% | 41,716 |
| Randomized | Success | 35.0% | 65.0% | 8,400 |
| Randomized | Failure | 3.7% | 96.3% | 55,483 |
Table 4: Share of simulation steps taken by the two control channels under hybrid execution (paper Table 12). Code carries more physical time in successful episodes, while failing episodes run to the step limit almost entirely under direct action.
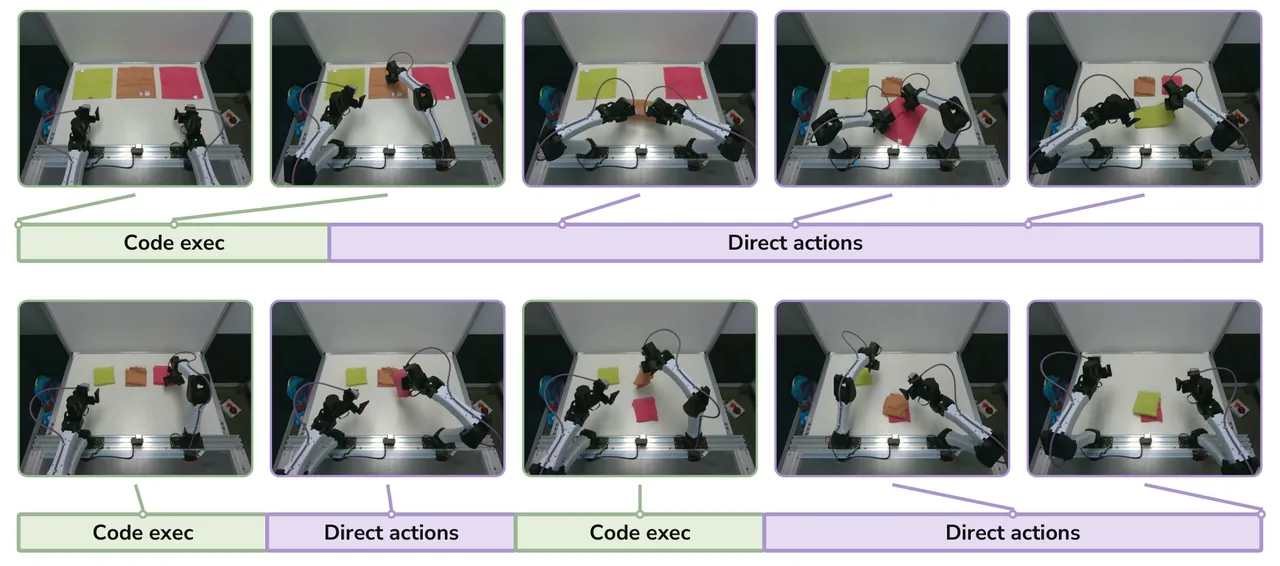
Figure 8: Hybrid execution on the real towel-folding task (paper Figure 35). Green segments execute code and purple segments are direct action-expert output; folding and pressing rely mainly on direct action, while approach and stacking are more often taken over by code.
The real-world hybrid experiment is run only on the YAM towel-folding task, where hybrid execution scores 90.6% and action-chunk execution scores 84.4%. This gain cannot be attributed to "stronger code" alone: the hybrid and default configurations use different demonstration-collection pipelines, the default using the native RoboTwin motion planner and the hybrid using code-as-policy programs, because the latter naturally provide executable, aligned programs. The appendix explicitly acknowledges that the comparison evaluates two complete configurations rather than isolating execution mode. The 90.6% versus 84.4% result should therefore be read as "the hybrid configuration is better on this task," not as "switching execution mode alone gains 6.2 points."
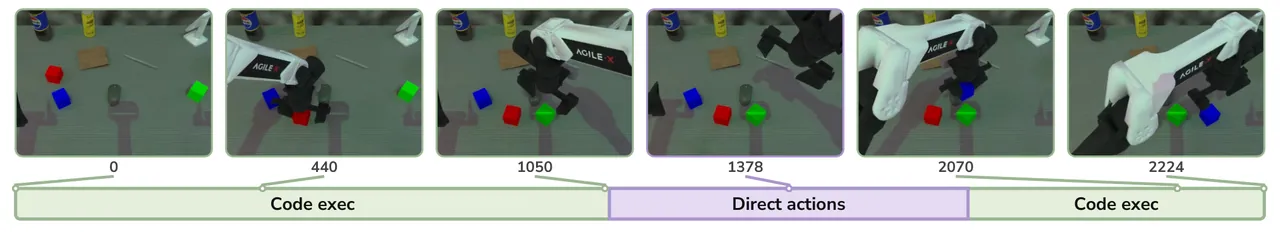
Figure 9: Two representative RoboTwin hybrid episodes (paper Figure 37). The block-sorting case runs almost entirely on code; in the dual-bottle case code handles localization and approach, but the grasp is unstable, so the action expert takes over and code resumes afterward.
Code Generation Quality and Ablations
The code expert is markedly stronger on syntax than on semantics. On the validation set the pretrained checkpoint reaches a teacher-forced loss of 0.535, teacher-forced token accuracy of 0.897, and a free-generation parse rate of 0.875; yet entity F1 is only 0.534, primitive-name F1 is 0.365, and the skill-call rate is 0.292. Shuffling visual observations across samples raises the code loss by 1.774, showing that prediction genuinely depends on visual context rather than reciting templates from a language prior. Taken together, the model usually writes something that looks like a program, but object names, parameters, and interface choices are often wrong.
| Metric | Value | Meaning |
|---|---|---|
| Teacher-forced loss | 0.535 | Token cross-entropy given the true prefix |
| Teacher-forced accuracy | 0.897 | Token hit rate given the true prefix |
| Loss increase under shuffled vision | 1.774 | Higher means code depends more on visual conditioning |
| Free-generation parse rate | 0.875 | Fraction of outputs parsable as valid programs |
| Entity F1 | 0.534 | Overlap of quoted object names with reference programs |
| Primitive F1 | 0.365 | Overlap of robot interface names with reference programs |
| Skill-call rate | 0.292 | Fraction of generated programs containing skill-style helper calls |
Table 5: Validation metrics for the pretrained code expert (paper Table 10). High syntactic validity coexists with low semantic F1, so "parsable" does not mean "executes correctly."
Qualitative examples make the gap concrete. In a YAM "wipe the keyboard with a cloth" validation sample, the model calls the scrubbing skill correctly and preserves the object parameter, arm assignment, and loop structure, but writes two extra elements into the displacement parameter; in an online Tianji–Sharpa Rubik's-cube deployment, it selects the correct hold-cube skill, object, and hand assignment but corrupts a comment, so the raw output cannot be executed directly. These are not cosmetic syntax defects but the characteristic failure of "right skill, wrong parameter or format," which explains why default mode treats code only as a condition instead of executing it.
Ablations break the gains down along three axes. For visual conditioning, ViT features give a mean of 71.1% across eight tasks, while replacing them with video VAE features drops the mean to 55.6%; Pack Backpack falls from 64.6% to 39.6% and Solve Cube from 72.1% to 53.9%. VAE features are optimized for pixel reconstruction and preserve texture and color but poorly support the semantic distinctions needed to decide whether to grasp the zipper or the body of the bag; ViT features are better suited to skill selection. For the generation paradigm, joint denoising averages 71.1% against 54.5% for autoregression, winning seven of eight tasks, with Replace Lightbulb the sole exception (75.0% vs. 79.2%). Joint denoising also cuts end-to-end latency from 0.55 s to 0.23 s, a 2.39× speedup, so it is not buying quality with more iterations.
| Ablation axis | Configuration | Mean score, 8 tasks (%) | Note |
|---|---|---|---|
| Code visual conditioning | ViT features | 71.1 | Paper default |
| Code visual conditioning | VAE features | 55.6 | Largest drops on Pack Backpack and Solve Cube |
| Code generation paradigm | Joint denoising | 71.1 | 0.23 s latency |
| Code generation paradigm | Autoregressive | 54.5 | 0.55 s latency, 2.39× slower |
| Planning content | Full program | Better than no-comment, no-skill, and language subgoals | Wins 7 of 8 tasks |
| Planning content | Remove skill calls | Deal Poker falls from 58.3 to 42.0 | Skill abstraction contributes on its own |
Table 6: Key ablations (paper Tables 3 and 4, plus Figure 7). Attention-order experiments further show that "code to video to action" beats both "video to action" and "video to code to action," but the paper does not report full averages for the three orders.
The three planning-content comparisons deserve detail. Full programs beat comment-free code on all eight shared tasks, so explanatory text helps the model connect program structure with task intent; removing skill calls lowers every task, with Deal Poker falling from 58.3% to 42.0%, so a skill is not syntactic sugar over primitives but a compression of a contact sequence into a reusable unit; and full programs beat natural-language subgoals on seven tasks, so structured object parameters and call order constrain action generation more tightly than a sentence saying "do this, then that."
Code Availability and Reproduction Boundaries
The repository structure maps closely onto the method. `GenericMoT.forward()` in `src/agenticwam/models/cosmos_mot/generic_mot.py` concatenates the queries, keys, and values of all experts at each layer for one masked joint attention and then splits the result back; `agenticwam_model.py` implements tri-modal joint denoising, confidence-based code reveal, and joint inference; `models/experts/code_expert.py` supports `joint`, `blockdiff`, and `ar` code objectives, with LLaDA-style global masking as the default; `models/experts/code_memory.py` implements the recurrent memory with confidence gating; and `robotwin/hybrid_eval/arbiter.py` implements the stage, dependency, syntax, allowlist, and non-empty gates for hybrid execution. These files make the architecture more than a block diagram in a paper.
The reproducible entry point is the pretrained checkpoint on Hugging Face, which the README describes as all training weights after one epoch on the mixed YAM and egocentric human corpus. Frozen public components load from their own release pages: the Wan2.2 video VAE, the Cosmos-Reason1 instruction encoder, the SDAR-1.7B code body, and the Qwen3-VL-2B vision tower. The repository supports three downstream paths, YAM, Tianji–Sharpa, and RoboTwin, and provides scripts that cover LeRobot shards, 64-dimensional statistics, instruction embeddings, preflight checks, training, and deployment.
The reproduction boundary is equally clear. The pretraining corpus is not public, and neither is the Cosmos-Predict2.5-2B starting checkpoint, so the 2,913-hour pretraining run cannot be repeated from scratch; what can be repeated is task fine-tuning from the released checkpoint, RoboTwin training, and hybrid evaluation. Two places in the code also diverge from the paper's description: the arbiter repairs before gating, whereas the appendix says it inspects the raw slice, and `code_memory` is disabled by default in the model configuration, whereas the paper presents the 32-slot memory as part of the method. Neither makes the code unusable, but both leave room between "results from the default configuration" and "the algorithm as described," and a reproduction should record the configuration differences.
The license is BSD 2-Clause, which permits commercial use and modification, while the public model components keep their own licenses. The last repository commit is dated 22 October 2026, immediately after the paper, so code and paper come from the same work cycle; the README still contains a comment that the arXiv link is to be added, indicating that the engineering release preceded full indexing of the paper. For a reader, the most practical entry point is not training from scratch but reproducing post-training on one real task from the pretrained checkpoint, then evaluating the code expert separately for program quality.
Limitations and Failure Modes
The first limitation comes from grounding programs. The code stream learns from automatically annotated demonstrations and a curated skill library, so planning quality is bounded by annotation accuracy and skill coverage. The model can choose the right skill and still write the wrong parameters; syntactic validity does not imply correct execution; and when a task needs a contact pattern outside the library, the model can only improvise a combination of existing skills. The paper proposes feeding execution feedback back into programs and the skill library, but the current system has no online learning, so failures do not automatically become new training signal.
The second limitation comes from predictive robustness. Structured planning improves the average performance of a world action model without removing sensitivity to visual distribution shift. Under RoboTwin randomization the default mode falls from 80.8% to 20.6%, which shows that the semantic skeleton supplied by code cannot replace the generalization of pixel-level future prediction. Hybrid execution recovers part of the robustness through the code channel, but its benefit depends on whether the underlying perception and control primitives are reliable and on whether the arbiter can judge that "this code is more likely to succeed than the action chunk." The current arbiter checks validity, not relative payoff, so in the clean setting it takes over when it should not and lowers success.
The third limitation comes from evaluation scope. Real-world hybrid execution is tested only on YAM towel folding, because the dexterous-hand platform has no corresponding code-as-policy system; although the eight real tasks cover two embodiments, each task has only 100 demonstrations and 48 evaluation rollouts, so task count and scene diversity remain limited. The paper also acknowledges the absence of online learning: the system does not keep revising the skill library or the arbitration policy during deployment. These limits do not undermine the core evidence that code can serve as a planning interface for a world action model, but they do define the distance to a long-horizon autonomous agent.
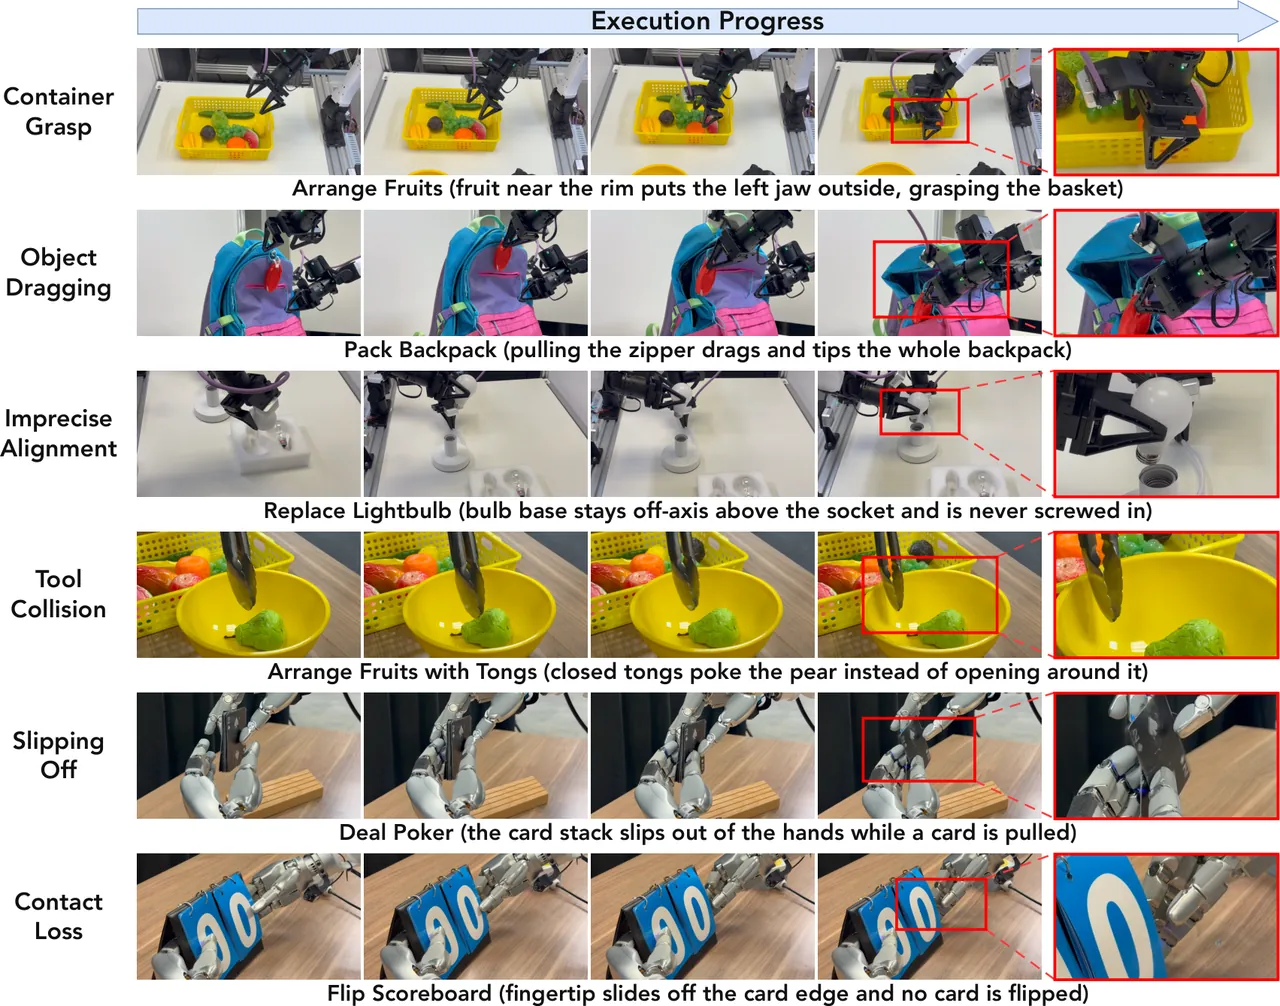
Figure 10: Six real-world failures (paper Figure 36). One case per row, with the failure region marked in red; failures cluster around grasp geometry under occlusion, deformable-object stability, fine alignment, tool coordination, bimanual handover, and sustained contact.
The failure cases can be read as a list of what the world model is missing. In fruit arrangement the left jaw crosses the basket rim and closes on the wall instead of the fruit, which is a failure to estimate surrounding geometry and the clearance along the closing path; when the backpack zipper is pulled the bag tips over, which is a failure of feedback between the supporting hand and the pulling hand; the lightbulb base is not aligned with the socket, which is a failure of joint position and angle alignment at fine scale; the tongs approach the pear closed and poke it, which is a failure to coordinate tool opening with the approach trajectory; the left hand does not catch the card stack securely, which is a failure to establish and release a grasp at the moment of handover; and the fingertip slips while flipping the scoreboard, which is a failure to maintain contact while rotating about the binding. None of these is solved automatically by generating a few more video frames; they require contact state, tool state, and bimanual timing to enter the conditioning explicitly.
Conclusion
AW-0 turns code from a planner outside the policy into a generative stream inside a world action model. A mixture of transformers lets code, video, and action exchange information at every layer; an automatic annotation pipeline turns robot and human video into supervision with skill programs; and joint denoising lets a semantic plan constrain future prediction and action generation at every iteration. Results on RoboTwin 2.0 and eight real tasks show clear gains in clean environments, semantic selection, and tool use; hybrid execution demonstrates the other face of code as an executable skill interface, though its benefit depends heavily on the environment and on arbitration quality.
As a research direction, the most important contribution is not any single percentage point but the placement of programs inside the generative process of a world model. Earlier code agents treated programs as external controllers, and earlier world action models treated future video and actions as internal representations; each was missing something. The former lacked physical anticipation, the latter lacked compositional structure. AW-0 joins them through joint denoising and turns "program" from a one-off plan into a reusable asset through the skill library. It also exposes the seams honestly: program semantics are imprecise, visual shift still breaks prediction, the arbiter does not estimate relative payoff, and dexterous hands lack a code-execution interface.
Golden Insight and Takeaways
The sentence worth carrying away is this: inside a world action model, code is not a substitute for action but an executable intermediate representation that gives future video and action a shared semantic skeleton. For teams building embodied systems, there are three practical lessons. First, align the skill library with contact evidence before worrying about code generation. Second, when code is used as a condition, evaluate whether it actually changes object selection and contact timing in video prediction. Third, when code is used as an execution channel, the arbiter must estimate whether a given slice is more likely to succeed than the action chunk; otherwise a validity-only gate will actively hurt in settings where the policy is already strong.