PAPER DEEP DIVE
RoboColosseum: Evaluating Physical Intelligence at Scale In-The-Wild
General-purpose robot policies must work across robots, tasks, and environments, yet the variation that makes physical trials informative also makes them difficult to reproduce. We introduce RoboColosseum, a distributed evaluation framework that combines unified policy serving and standardized protocols across a network of locally operated robots in diverse environments. Our initial study evaluates five vision-language-action (VLA) policies and three frontier AI agents across four embodiments (SO-101, Franka, Bimanual-YAM, and G1 Humanoid). The Open Track compares models without task-specific adaptation in blinded, pairwise trials under matched local conditions. The Fine-tune Track measures how well VLA policies adapt to 20 tasks across all four embodiments when each policy receives the same 100 demonstrations per task. Across 5,699 pairwise Open Track comparisons at 124 sites, frontier agents rival specialized VLA policies, while all systems struggle to complete open-world tasks reliably. After fine-tuning, GR00T N1.7 leads on SO-101 and pi0.5 leads on Franka and Bimanual-YAM. Policy rankings show weak agreement across embodiment-specific task suites (Kendall W = 0.24). Open Track rankings poorly predict relative performance after fine-tuning, with substantial rank reversals on all three embodiments shared between tracks. Measuring partial progress reveals differences that task success alone misses. On the G1 Humanoid, no policy completes any of the five tasks, yet average progress ranges from 13.3% to 23.2% across policies. Open Track rankings stabilize as trials accumulate, and active matchmaking achieves comparable ranking agreement with substantially fewer physical trials than uniform sampling. These results show how distributed physical evaluation can reveal where robot policies generalize, how well they adapt to new tasks, and how far they progress on tasks they fail to complete.
One-Sentence Summary
RoboColosseum turns thousands of locally operated physical trials across 124 sites into a reproducible comparison, showing where generalist policies generalize, where they adapt, and how far they progress when they never fully succeed.
Why Robot Foundation Models Need a Shared Real-World Examination
Language models can be compared with a common prompt, response format, and judge. A robot policy changes the next observation through its own action. A small error in grasp height can move an object, occlude a camera, or change the state used by the next policy call. The same semantic task is therefore not physically identical across sites.
Table height, lighting, camera extrinsics, friction, calibration, and the reset procedure all affect a rollout. Simulation can generate many trials with repeatable resets, but differences in sensing, actuation, and appearance limit how directly simulated performance predicts deployment. Physical trials are necessary, yet they are expensive and often too sparse to support stable comparisons.
Distributed evaluation addresses coverage by placing robots in offices, homes, libraries, parks, and factories. It also creates a statistical problem. If each site chooses a different task and every model receives a different mix, raw win rates confound policy ability with task difficulty. If every site copies one narrow tabletop, the benchmark gains control at the cost of ecological validity.
The paper's central compromise is explicit. Tasks and environments may vary across evaluations, but each blinded pair is executed on the same robot, task instruction, objects, initial arrangement, and timeout. This makes the local comparison meaningful while allowing the aggregate network to sample a much wider physical distribution.
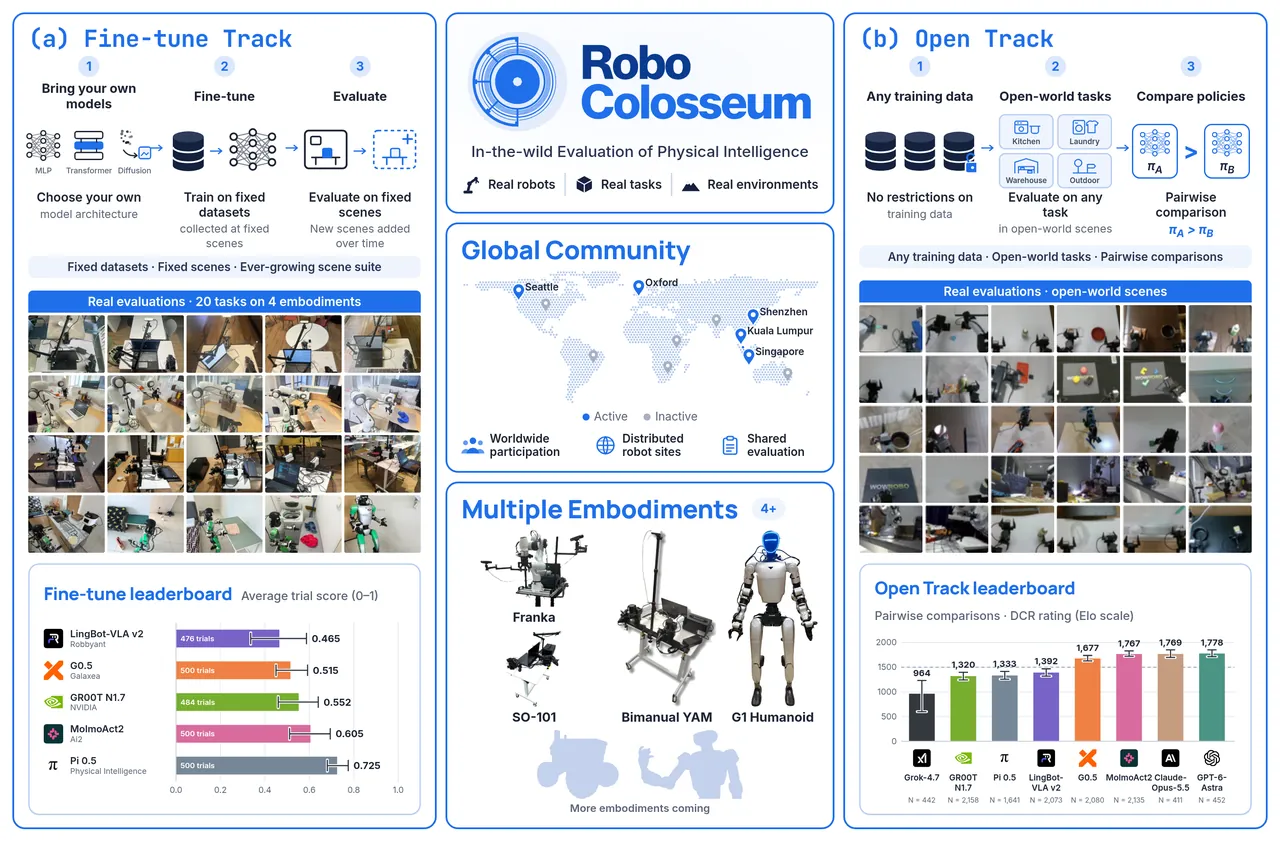
Figure 1 of the paper (downloaded as fig2): distributed sites, unified policy serving, the Open Track, the Fine-tune Track, and a shared leaderboard.
The Physical Testbed Is Part of the Method
The initial network supports SO-101, Franka in the DROID configuration, Bimanual-YAM, and the Unitree G1 humanoid. These platforms span a low-cost single arm, a research-grade arm, coordinated bimanual manipulation, and mobile humanoid manipulation. Each embodiment has a fixed observation and action specification shared by participating sites.
SO-101 uses six-dimensional joint-position actions, including a gripper dimension and five arm joints. DROID/Franka uses eight dimensions, while each YAM arm contributes six joints plus one gripper dimension for a fourteen-dimensional action vector. These interfaces do not erase hardware differences, but they make the differences visible and keep model adapters from silently inventing their own conventions.
The operational layer receives unusual attention for a robotics paper. Full-time evaluators set up tasks, reset scenes, execute trials, and judge outcomes. Sites include unstructured workspaces and public environments. Recordings are processed with face blurring and identity anonymization. A benchmark that depends on physical labor needs these procedures; otherwise missing resets and inconsistent stopping decisions become unmodeled variables.
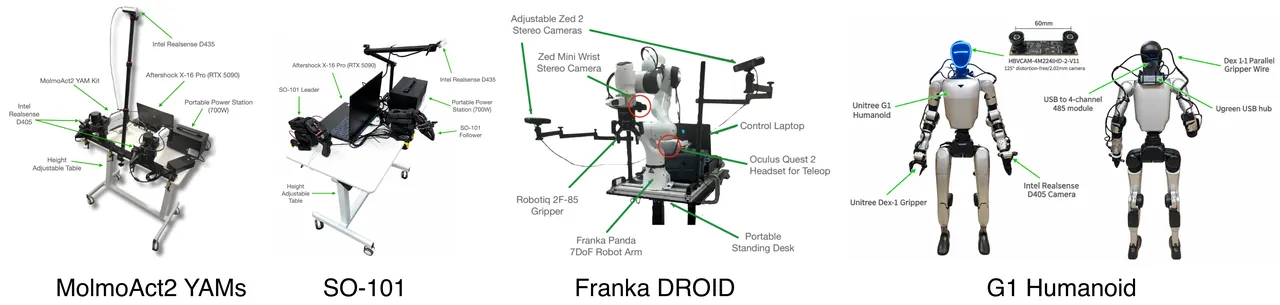
Figure 2 of the paper (downloaded as fig3): Bimanual-YAM, SO-101, DROID/Franka, and Unitree G1, with cameras, grippers, and compute highlighted.
The Fine-Tune Track Fixes Data, Not Architecture
The Fine-tune Track creates twenty tasks, five per embodiment. They cover pick-and-place, stacking, reorientation, articulated objects, deformable objects, pouring, tool use, bimanual coordination, and loco-manipulation. Every task card defines the language instruction, objects, initial setup, success conditions, timeout, progress conditions, and evaluation site.
Each task receives 100 teleoperated demonstrations. Every policy is trained from its base checkpoint on the same task data but uses its official adaptation recipe. The design therefore holds the data and evaluation protocol fixed while allowing optimizer, schedule, batch size, and training duration to vary across architectures.
After adaptation, each policy-task pair receives twenty-five trials. If a rollout satisfies $s_n$ of the $K$ task-specific progress conditions, the normalized progress score and success rate are:
$$ \mathrm{PS}=\frac{1}{N}\sum_{n=1}^{N}\frac{s_n}{K}. $$ $$ \mathrm{SR}=\frac{1}{N}\sum_{n=1}^{N}\mathbf{1}_n. $$Here $\mathbf{1}_n$ is 1 when rollout $n$ succeeds and 0 otherwise. Success answers whether the complete goal was achieved. Progress answers how much of the task specification was satisfied before failure. Each condition has equal weight, and conditions need not be completed in a fixed order. A rollout stopped for safety receives zero progress and counts as a failure, so hazardous behavior cannot benefit from an early stop.
This metric matters most when every policy fails. On the G1 humanoid, all five policies have zero success across five tasks. A binary leaderboard would show five identical zeros. The reported average progress instead ranges from 13.3% to 23.2%, revealing that some policies satisfy several intermediate requirements while still failing the complete task.
The Open Track Uses Blinded, Matched Pairs
Open Track tasks are proposed by local sites rather than selected centrally from a fixed list. The system assigns two eligible models, $A$ and $B$, without revealing their identities to the evaluator. The models execute consecutively on the same robot and scene. The evaluator records a preference, progress for each execution, natural-language feedback, and a difficulty rating from one to ten.
Blinding reduces identity bias but does not solve sample allocation. Uniform sampling spends many trials on pairs whose ordering is already clear. The paper uses active matchmaking inspired by Chatbot Arena. After an initial set of comparisons, the probability of selecting candidate pair $a$ is proportional to the expected reduction in uncertainty:
$$ P_t(a)\propto \sqrt{\frac{\hat{\Sigma}_{t,a,a}}{n_a}} -\sqrt{\frac{\hat{\Sigma}_{t,a,a}}{n_a+1}}. $$Here $n_a$ is the number of previous comparisons for the pair, and $\hat{\Sigma}_{t,a,a}$ is the current variance estimate. Pairs with high uncertainty and few observations receive more mass. The system then filters by hardware and checkpoint compatibility, because a statistically attractive pair is useless if no site can execute it.
flowchart LR
    S[Local site defines task] --> A[Server assigns hidden pair A and B]
    A --> E1[Execute model A on fixed scene]
    E1 --> E2[Reset and execute model B]
    E2 --> R[Record preference progress and difficulty]
    R --> D[DCR estimates ability and task difficulty]
    D --> M[Active matchmaking selects uncertain pair]
    M --> A
    R --> L[Public leaderboard]
The client code matches this workflow. In rc-client-h1/src/colosseum_client/evaluation.py, progress() prompts the operator for a partial success score from zero to one hundred, validates that range, and divides by one hundred. After both executions, local['result'] contains the per-side outcomes, the Open Track preference, and optional feedback. The submission does not resend model identities.
def progress(label):
    while True:
        raw = ask(f'{label} partial success (0–100): ').strip()
        try:
            value = float(raw)
            if 0 <= value <= 100:
                return value / 100
        except ValueError:
            pass
        print('Enter a number from 0 to 100.')

local['result'] = {
    'outcomes': local['outcomes'],
    'preference': preference,
    'feedback': ask('Feedback (optional): ').strip()
        if track == 'open' else '',
}
The per-side outcomes are the evidence behind both progress values. Recording two successes, two failures, or one partial completion lets the aggregate model infer task difficulty instead of treating every non-win as the same event.
The DCR Model Separates Policy Ability from Task Difficulty
A raw pair win rate assumes that a win means the same thing regardless of task difficulty. The paper instead models success as a one-parameter Rasch response. Policy $p$ succeeds on task $t$ with probability
$$ q_{p,t}=P(y_{p,t}=1\mid\theta_p,\beta_t) =\sigma(\theta_p-\beta_t). $$ $$ \sigma(x)=\frac{1}{1+e^{-x}}. $$Higher $\theta_p$ means greater policy ability, while higher $\beta_t$ means greater task difficulty. Both outcomes from a matched pair are retained. Two successes provide evidence that the task is easier; two failures provide evidence that it is harder. This is more informative than collapsing the pair into one win or loss.
Most in-the-wild tasks receive too few physical trials to estimate a free difficulty parameter reliably. Human ratings provide a prior. Let $d_t$ be the rating from one to ten and $\mu_k$ the typical latent difficulty of rating $k$. The category means are ordered:
$$ \mu_1 \lt \mu_2 \lt \cdots \lt \mu_{10}. $$An individual task is then modeled around its rating category:
$$ \beta_t\mid d_t=k\sim\mathcal{N}(\mu_k,\tau^2). $$The prior is not a fixed numerical weight. If a task rated nine is repeatedly completed, its posterior difficulty can move downward. If a task rated two causes widespread failure, its posterior difficulty can move upward. Physical evidence therefore calibrates, rather than merely decorates, the human rating.
Policies are ranked by posterior mean ability:
$$ s_p=\mathbb{E}[\theta_p\mid\mathcal{D}], $$and displayed on an Elo-style scale:
$$ R_p=1500+\frac{400}{\ln 10}s_p. $$The display transformation is linear, so it preserves ordering, uncertainty, and difficulty-aware estimates. It is not a sequential Elo update. The paper also compares DCR with Bradley–Terry–Davidson, which models pairwise win, loss, and tie outcomes without an explicit task-difficulty term.
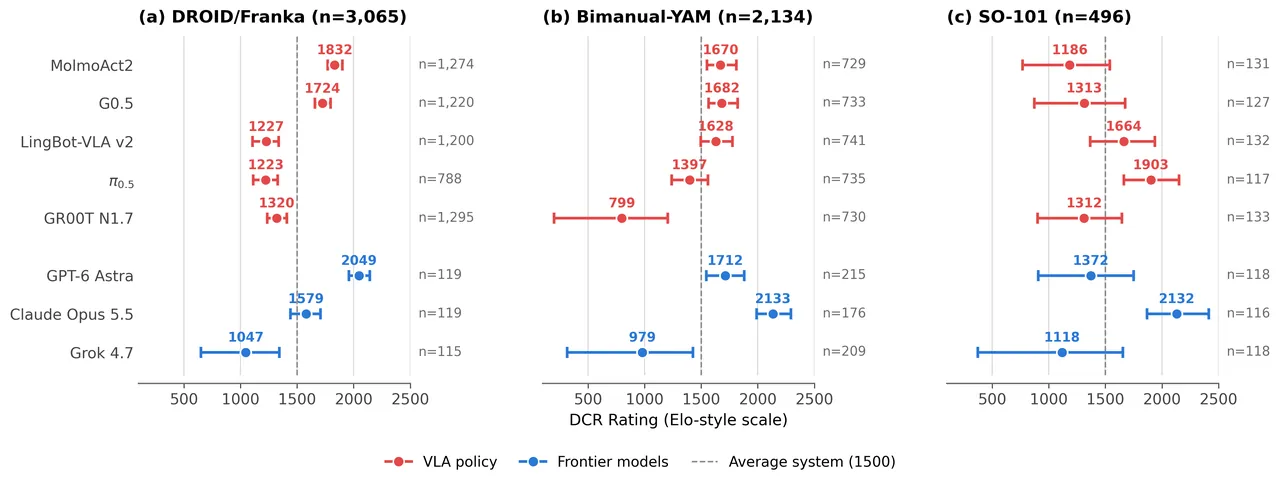
Figure 3 of the paper (downloaded as fig4): posterior mean DCR ratings and 95% credible intervals on SO-101, DROID/Franka, and Bimanual-YAM.
One Serving Layer Gives VLAs and Agents the Same Execution Contract
The three frontier agents do not use a separate robot-control benchmark. They run through the same policy server as the VLA models. At each decision step, an agent receives camera images, proprioceptive state, and the language instruction. It may issue one move call, declare completion, or give up. A declared completion is not accepted as task success; the local evaluator still applies the task card.
The server validates joint limits, per-step changes, action-chunk shape, and inference deadlines. In rc-policy-server-h1/src/colosseum_policy_server/backends/auto.py, the backend factory routes VLA and agent requests through a common interface. The client applies the same joint clipping to both model classes.
class AutoBackend:
    async def start_session(self, model, request):
        if self.active is not None:
            raise RuntimeError('Previous model session has not closed')
        shared = {key: value for key, value in self.options.items()
                  if key not in {'llm', 'vla'}}
        if (model.model_type == 'llm'
                or model.endpoint == 'inprocess://inspect-agent'):
            self.active = InspectAgentBackend(
                {**shared, **self.options.get('llm', {})})
        else:
            self.active = VLABackend(
                {**shared, **self.options.get('vla', {})})
        await self.active.start_session(model, request)

def create_backend(options):
    return AutoBackend(options)
SO-101 exposes why interface agreement is an engineering result rather than a configuration detail. The adapter in model_adapters/so101_vla.py requires a six-dimensional joint_position state and action: five joint positions plus one gripper position in LeRobot's so101_follower order. For legacy checkpoints it computes model = sign * current + offset with LEGACY_SIGNS=[1,-1,1,1,1,1] and LEGACY_OFFSETS=[0,90,90,0,0,0], then applies the inverse transform to returned actions. This is a six-valued coordinate-frame conversion, not a reduction from seven dimensions to six. A missing sign or offset can silently shift a joint even when the service appears healthy.
Agents are slower because every step depends on an API round trip. The benchmark nevertheless keeps a common trial budget: at most thirty model calls, 800 control steps, and a 120-second deadline per call. A timed-out call is discarded and the loop continues from the next observation. The comparison measures the complete deployed system under these constraints, not an idealized offline inference rate.
Experimental Scale: 41 Days, Four Embodiments, and 124 Sites
The study ran from 17 September through 28 October 2026. It evaluated five VLA policies: GR00T N1.7, $\pi_{0.5}$, MolmoAct2, G0.5, and LingBot-VLA v2. It also evaluated GPT-6 Astra, Claude Opus 5.5, and Grok 4.7 through their released APIs.
The Open Track contains 5,699 pairwise comparisons across 124 sites and four embodiments. The Fine-tune Track contains five tasks per embodiment, 100 demonstrations per task, and twenty-five trials per policy-task pair. Not every model participates on every embodiment; compatibility and checkpoint availability constrain coverage.
| Dimension | Open Track | Fine-Tune Track |
|---|---|---|
| Question | Zero-shot generalization in local environments | Adaptation from a fixed demonstration budget |
| Task source | Proposed and executed by local sites | Five predefined cards per embodiment |
| Control | Scene fixed within each blinded pair | Task, criteria, and procedure fixed across models |
| Adaptation data | None | 100 teleoperated demonstrations per task |
| Evaluation count | 5,699 pair comparisons | 25 trials per policy and task across 20 tasks |
| Primary metric | DCR, paired progress, success, and difficulty | Normalized progress and success rate |
Result 1: Frontier Agents Can Compete with Specialized Policies
The strongest surprise is that general-purpose API agents can match or exceed task-specialized VLAs on part of the physical benchmark. GPT-6 Astra has the highest DCR point estimate on DROID/Franka, while Claude Opus 5.5 leads on SO-101 and Bimanual-YAM. These agents receive no task demonstrations or fine-tuning.
Across 901 direct agent-versus-VLA pairs, the agent makes more progress in 394 comparisons, the VLA makes more progress in 265, and the pair ties in 242. The mean progress advantage for agents is 5.3 percentage points. The average hides large differences between agents: Claude Opus 5.5 is ahead by 12.1 points and GPT-6 Astra by 11.0, while Grok 4.7 trails by 7.5.
| Paired agent-versus-VLA result | Count or difference | Interpretation |
|---|---|---|
| Valid pairs | 901 | Each pair contains one agent and one VLA on the same task |
| Agent makes more progress | 394 (43.7%) | Agents hold an aggregate edge, not a universal win |
| VLA makes more progress | 265 (29.4%) | Specialized policies remain stronger on many pairs |
| Equal progress | 242 (26.9%) | Ties also carry task-difficulty information |
| Mean paired advantage | +5.3 points | Agent progress minus VLA progress for each pair |
| Claude Opus 5.5 | +12.1 points | Substantial positive mean advantage |
| GPT-6 Astra | +11.0 points | Also outperforms its paired VLAs on average |
| Grok 4.7 | -7.5 points | Frontier branding does not imply equal physical control |
This result supports the claim that visual reasoning plus tool use can produce a capable robot controller. It does not isolate the contribution of language reasoning, action frequency, or provider-specific implementation. The full-system comparison is the relevant deployment unit, but it cannot be read as a pure test of model intelligence.
Absolute reliability remains low despite the competitive ranking. MolmoAct2 has the highest relative comparison score in all six manipulation categories, ranging from 58% to 77%. Its observed success rate in those categories is only 6% to 13%, and no evaluated system exceeds 13% in any category. Relative advantage and deployment reliability are clearly different quantities.
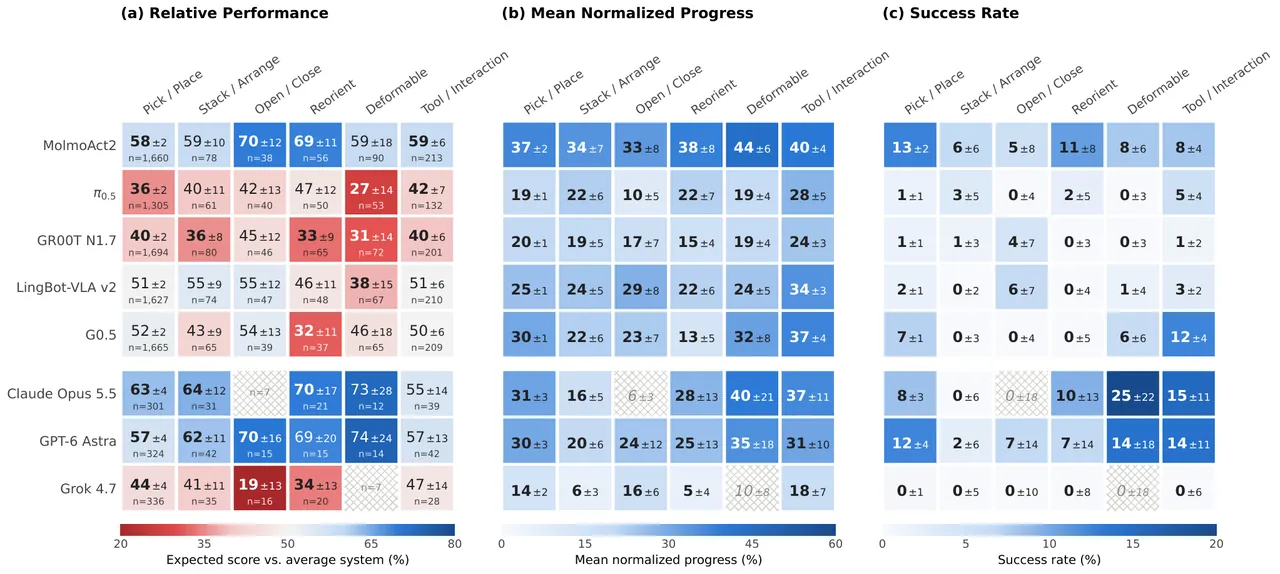
Figure 5 of the paper (downloaded as fig5): relative comparison scores, mean normalized progress, and success rate across six manipulation categories.
Result 2: Difficulty Collapses Completion and Partial Progress Together
The paper groups Open Track executions by human-rated difficulty. Full success falls from 30.7% on tasks rated one to four to 0.4% on tasks rated nine to ten. Normalized progress falls from 56.6% to 3.5%. If only success were reported, one could imagine that difficult tasks fail at the final condition. Progress collapses as well, showing that failure begins much earlier.
This distinction matters for research. A policy may fail before recognizing the object, before establishing a stable grasp, or after satisfying most of the sequence. Binary success assigns all three cases the same score. A progress vector can separate capability gaps and direct the next experiment toward the stage where execution actually stops.
| Human difficulty | Full success | Mean normalized progress | Interpretation |
|---|---|---|---|
| 1–4 | 30.7% | 56.6% | Even the easiest group is far from reliable completion |
| 9–10 | 0.4% | 3.5% | Failures occur near the beginning of the task sequence |
Result 3: The Best Fine-Tuned Policy Depends on the Embodiment
On SO-101, GR00T N1.7 has the strongest average progress and success rate at 89.0% and 82.4%. $\pi_{0.5}$ is second at 85.4% and 77.6%. On DROID/Franka, the order changes: $\pi_{0.5}$ reaches 91.2% progress and 84.0% success, while GR00T N1.7 falls to 56.4% and 42.4%.
The Bimanual-YAM suite produces an even larger gap. $\pi_{0.5}$ averages 97.2% progress and 93.6% success, with four of five tasks between 96% and 100% success. G0.5 averages 75.2% success, including 100% on drawer and microwave, but only 20% on stack cups. A model can adapt well to articulated objects and still struggle with multi-object composition and stable placement.
The G1 results define a different boundary. All five policies have zero average success, while average progress ranges from 13.3% for G0.5 to 23.2% for LingBot-VLA v2. Humanoid loco-manipulation is unsolved by this adaptation setup, but the policies are not equally close to the goal.
| Embodiment | GR00T N1.7 PS / SR | π0.5 PS / SR | MolmoAct2 PS / SR | G0.5 PS / SR | LingBot PS / SR |
|---|---|---|---|---|---|
| SO-101 | 89.0 / 82.4 | 85.4 / 77.6 | 71.8 / 59.2 | 58.8 / 40.0 | 55.2 / 36.8 |
| DROID / Franka | 56.4 / 42.4 | 91.2 / 84.0 | 78.2 / 54.4 | 44.8 / 16.0 | 59.4 / 40.8 |
| Bimanual-YAM | 52.6 / 20.0 | 97.2 / 93.6 | 72.1 / 49.6 | 89.1 / 75.2 | 48.3 / 30.4 |
| G1 Humanoid | 22.7 / 0.0 | 16.3 / 0.0 | 19.8 / 0.0 | 13.3 / 0.0 | 23.2 / 0.0 |
The averages weight five tasks equally within an embodiment. They do not imply that one model dominates every task. LingBot-VLA v2 reaches 100% success on DROID open drawer and 0% on marker in holder. MolmoAct2 shows the reverse pattern at 0% and 88%. Per-task reachability curves are therefore necessary to understand where the mean comes from.
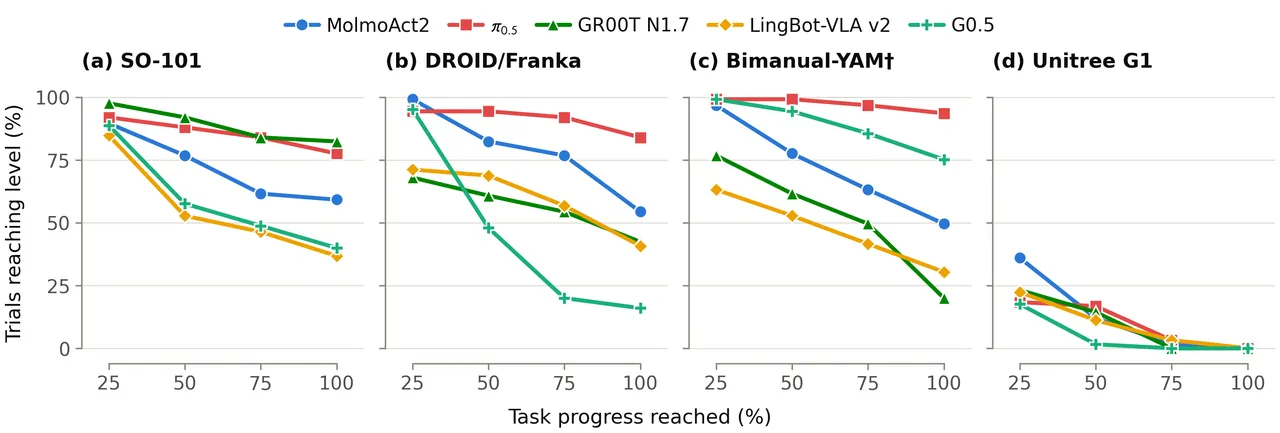
Figure 7 of the paper (downloaded as fig6): percentage of trials satisfying at least a given fraction of task criteria. The endpoint at 100% is full success.
Result 4: Open-World Rank Does Not Predict Fine-Tuned Rank
The paper compares the five VLA policies across the Open and Fine-Tune Tracks. The tracks differ in task distribution, initial checkpoints, and scoring metric, so low correlation cannot isolate generalization from adaptation. The observed reversals still show that one ranking cannot substitute for the other.
Spearman correlations are -0.20 on SO-101, -0.40 on DROID/Franka, and 0.20 on Bimanual-YAM. Only four, three, and six of ten model pairs preserve their order. $\pi_{0.5}$ moves from fifth among DROID VLAs in the Open Track to first after fine-tuning. G0.5 moves from second to fifth on the same embodiment.
Cross-embodiment rankings are also weak. Kendall's coefficient of concordance across the four fine-tuning task suites is 0.24. $\pi_{0.5}$ ranks first on DROID and YAM but fourth on G1. GR00T N1.7 ranks first on SO-101 but fourth on DROID and YAM. Morphology and task suite are entangled, so the paper does not claim that morphology alone causes the change.
| Shared-track embodiment | Spearman ρ | Pairs preserved | Observation |
|---|---|---|---|
| SO-101 | -0.20 | 4 / 10 | Low agreement with several reversals |
| DROID / Franka | -0.40 | 3 / 10 | Open-track strength does not imply easy adaptation |
| Bimanual-YAM | 0.20 | 6 / 10 | Positive but too weak for substitution |
| Four Fine-Tune embodiments | Kendall W = 0.24 | — | Weak cross-embodiment ranking agreement |
Result 5: Active Matching Saves Trials, but High Confidence Still Needs Scale
To test site sensitivity, the paper repeatedly partitions sites into two disjoint groups and fits DCR independently on each half. DROID/Franka and Bimanual-YAM preserve about 85% of model-pair orderings, with mean Spearman correlation near 0.82. SO-101 preserves only 59%, with a correlation of 0.30.
Active matchmaking reaches roughly 90% agreement with the full-data ranking after 400 to 500 evaluations. Uniform sampling needs about 1,000 trials for comparable agreement. By allocating trials toward uncertain pairs, the system extracts more ranking information from the same physical budget.
The result does not mean 400 trials guarantee a stable leaderboard. A random subset reaches 90% mean agreement at about 1,123 evaluations and 95% at about 4,755. The confidence band remains wide, so individual subsets of the same size can differ. Active sampling improves efficiency relative to the ranking objective, while absolute confidence still depends on the target and the data distribution.
| Analysis | Result | Practical meaning |
|---|---|---|
| DROID/YAM site split | About 85% pair agreement, ρ≈0.82 | Different site subsets recover similar rankings |
| SO-101 site split | 59% pair agreement, ρ=0.30 | Ranking is more sensitive to site composition |
| Active matching near 90% | 400–500 evaluations | Far fewer than about 1,000 uniform trials |
| Random subset at 90% mean agreement | 1,123 evaluations | Budget depends on the requested confidence |
| Random subset at 95% mean agreement | 4,755 evaluations | High-confidence stability still requires scale |
What the Public Code Reveals About Hidden Inputs
The client checks more than the presence of a preference label. It validates normalized progress, preserves both model outcomes, and submits the assignment used for the blinded pair. The server validates action chunks against the embodiment's dimensions and execution limits. These checks are part of the benchmark because an action that cannot execute is not equivalent to a model prediction that was never tested.
The SO-101 adapter is equally specific. It checks the six-dimensional model contract, combines five joint positions with one gripper value, and applies a legacy coordinate transform with fixed signs and offsets. The fine-tuning package uses the same six-value state and action convention on client and server. A benchmark that spans sites needs these explicit boundaries; otherwise a checkpoint can appear compatible while individual joints or the gripper are shifted.
These implementation details expose sources of variance that model-comparison papers often omit: serving version, action conversion, timeout policy, and clipping. RoboColosseum does not make them disappear, but it centralizes them and applies the same server and client contracts across compared systems.
How the Contributions Fit Together
The infrastructure contribution supplies compatible embodiments, local protocols, remote serving, and a growing site network. The design contribution combines two tracks that answer different questions: matched open-world pairs for generalization and fixed task demonstrations for adaptation. The statistical contribution combines DCR difficulty calibration with active comparison allocation.
The empirical contribution follows from those choices. Frontier agents can be competitive without task adaptation, but absolute reliability is low. Fine-tuned strengths are strongly task and embodiment dependent. Open-world ranking is a poor proxy for adaptation ranking. Partial progress exposes differences that zero success hides. No single sentence about a universal winner survives contact with the complete results.
The evidence is strongest for aggregate trends and ranking stability. The 5,699 comparisons are not a uniform probability sample of all possible tasks. Sites propose tasks, and model participation depends on compatibility. DCR corrects for rated task difficulty and matched pairs remove local scene differences, but category composition and site style can still matter. The paper states these boundaries rather than presenting the leaderboard as exhaustive.
Limitations
The first author-stated limitation is coverage. The study is an initial snapshot, not an exhaustive evaluation of every robot foundation model or deployment setting. Participation varies by checkpoint and hardware, and the Fine-Tune Track has five tasks per embodiment. The protocol can expand, but the current conclusions do not automatically apply to unmeasured systems or environments.
The second author-stated limitation is the adaptation recipe. Demonstrations and evaluation are fixed, while each policy uses its official optimizer, schedule, and training duration. The benchmark measures practical end-to-end adaptation from the same data. It does not isolate architecture under a common optimizer, and differences in engineering maturity remain part of the result.
The third author-stated limitation is the meaning of stability. Ranking stability is measured relative to the leaderboard estimated from the current complete dataset. As more sites and tasks arrive, the reference leaderboard changes. A sample size that yields 90% agreement now should not be treated as a permanent property of the benchmark.
An independent limitation is task-distribution control. Local task proposals improve ecological validity but allow category, object, and environment mixes to vary. DCR accounts for rated difficulty and observed success, yet unmodeled task properties may still interact with model strengths. A policy that receives more deformable tasks is not directly comparable to one that receives more rigid-object tasks without adequate overlap.
A second independent limitation is system-level attribution. Agents use API round trips and tool calls, while VLAs use local action generation. They share safety and scoring code, but observation history, call latency, and action frequency differ. The comparison is valid for the deployed packages, not for a hypothetical contest between language reasoning and VLA architecture in isolation.
A third independent limitation is progress cardinality. Normalization by $K$ makes PS comparable within a task, but task cards can assign different numbers and difficulties of conditions. Equal weighting across five tasks avoids favoring a task with more trials, but it does not prove that one percentage point of progress means the same physical achievement everywhere.
Conclusion
RoboColosseum is more than a larger leaderboard. It specifies how sites define tasks, how two anonymous policies share a local scene, how evaluators record both outcomes and partial progress, how difficulty enters a global model, and how the next costly trial is selected.
The results support a disciplined conclusion. Current physical intelligence can produce strong demonstrations and competitive agent behavior, but it is not reliable in open-world deployment. VLA policies, general agents, and embodiments have different strengths, and neither success nor one track's ranking captures the whole capability. Progress scores preserve information when completion is zero; cross-track and cross-embodiment reversals prevent a local winner from becoming a universal claim.
The next step is not to hide variation behind one grand average. It is to expand the model-by-embodiment-by-task matrix, publish where failures begin, and incorporate site and task uncertainty into the ranking. A physical benchmark becomes scalable only when every new trial also makes the next comparison more informative.