UniMate: one unified model animates arbitrary skeletons from text prompts
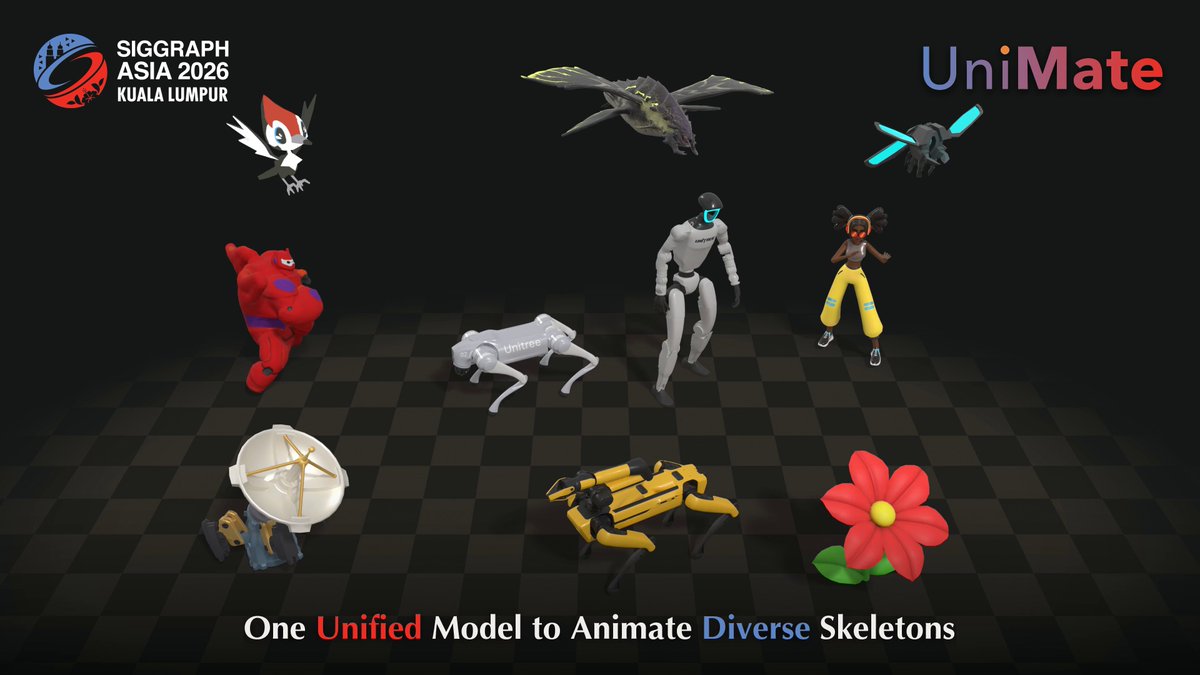
Princeton + UC Berkeley + MIT (SIGGRAPH Asia 2026, arXiv:2609.05415) present UniMate: given a rigged 3D asset and a text prompt, a single unified model generates animations for arbitrary skeletal topologies with no per-skeleton retraining or test-time optimization. The core is a topology-aware diffusion transformer integrating skeletal structure into attention via three mechanisms: graph-aware attention bias from pairwise joint relations and geodesic distances; spectral rotary position embeddings generalizing RoPE to arbitrary kinematic trees via the graph Laplacian; and a global topological conditioner attention-pooled from the rest-pose skeleton. They also curate UniML3D - 13,006 motion sequences spanning bipedal, quadrupedal, avian, marine, insectoid, serpentine and articulated rigid objects, canonically unified and text-paired. Supports zero-shot cross-topology transfer, in-betweening, expansion and text-guided editing, beating SOTA baselines in quality, generalization and efficiency. A direct answer to the bottleneck between automatic rigging and animation in 3D pipelines; code and dataset open-sourced.