One Policy, Many Embodiments: Unified Camera-Centric Action Geometry Pre-training for Heterogeneous Embodied Manipulation
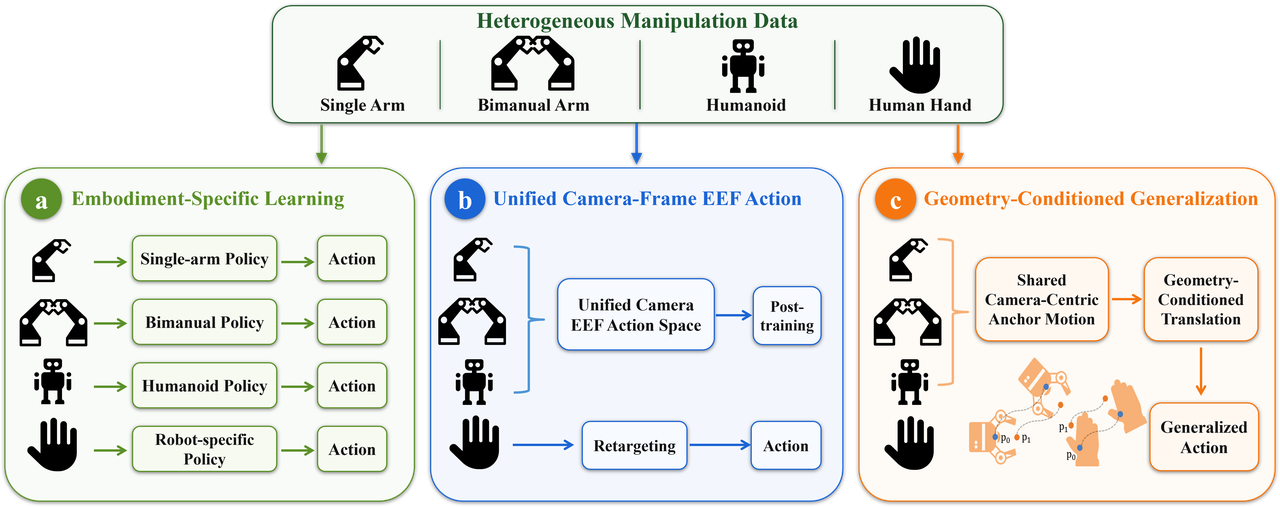
UCAG-P from Xiaomi Embodied Intelligence and University of Macau unifies robot arms, bimanual platforms, humanoids and human-hand videos into one camera-centric action schema: 3D camera-frame anchor trajectories of the wrist (p0) and grasp center (p1), with a geometry-conditioned translator emitting executable commands — no retargeting or human-to-robot video synthesis needed. Built on Qwen3-VL-4B with three-stage training over 1.02M episodes / 6,373.6 hours / nine embodiments (36.7% human data), a single checkpoint without benchmark fine-tuning reaches 98.3% on LIBERO, 88.7%/89.2% on RoboTwin Easy/Hard, 82.0% zero-shot on LIBERO-Plus and 62.0% on RoboCasa GR-1; on real Piper robots bread pickup hits 60% vs 20% for pi0.5, with 35% zero-shot ALOHA-to-ARX transfer.