Skip to content
← Tags
Social-WM: Safety-Aware Latent World Models for Robot Social Navigation

Social-WM: Safety-Aware Latent World Models for Robot Social Navigation

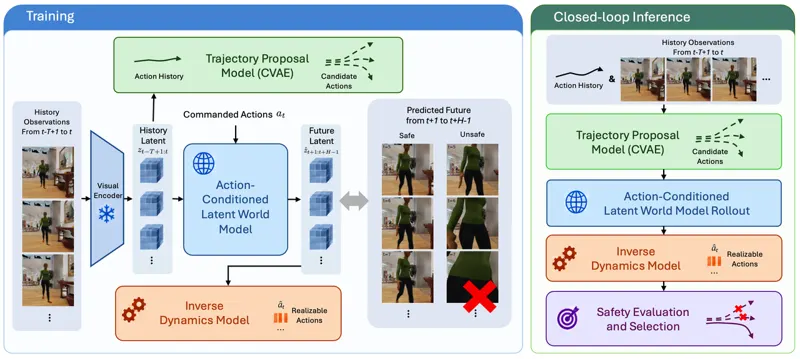
Safe social navigation requires a robot to anticipate not only the future consequences of its actions, but also whether a nominal action can actually be executed under surrounding physical and social constraints. We present Social-WM, an efficient latent world-model planning framework trained from egocentric RGB video sequences. Our key observation is that social-navigation experience contains a systematic discrepancy between the nominal action and the realizable action: a nominal forward action may be fully executed in free space, but needs to be constrained when heading towards a pedestrian or obstacle. Social-WM learns these safety-relevant consequences directly through action-conditioned future prediction, where the target is the actual observed future following each command. We further introduce a realizable inverse-dynamics objective that associates observed latent transitions with the action actually realized rather than the nominal one. At deployment, candidate actions are imagined through the latent world model, and the inverse dynamics model estimates their realizability; nominal–realizable discrepancy then provides a safety signal before execution. The learned dynamics and realizability model remain goal-independent and support both position- and image-goal navigation. On Social-HM3D, Social-WM achieves 63.77% success while reducing human collisions to 21.67%, and maintains strong performance under zero-shot transfer to Social-MP3D, without explicit pedestrian tracking, privileged human state, or online reinforcement learning.

Zhihao Zheng, Mooi Choo Chuah · 180 views · Sep 30, 2026
Social NavigationWorld Models
Sep 30, 2026
Token-Wise Latent Streaming from Slow Reasoners to Fast Planners for Dynamic Vision Language Navigation

Token-Wise Latent Streaming from Slow Reasoners to Fast Planners for Dynamic Vision Language Navigation

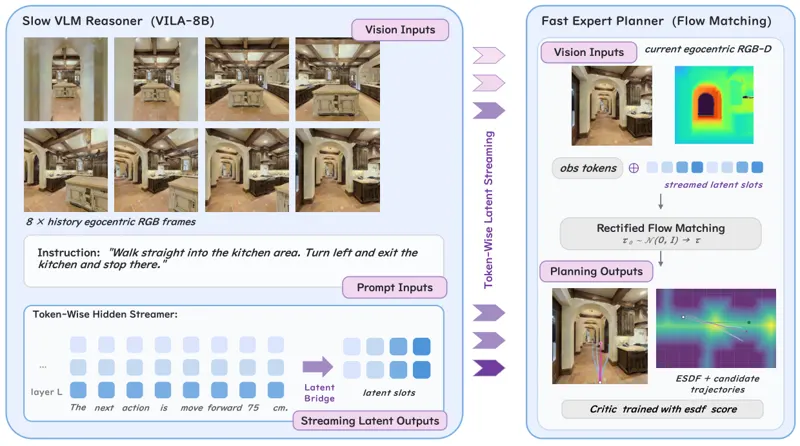
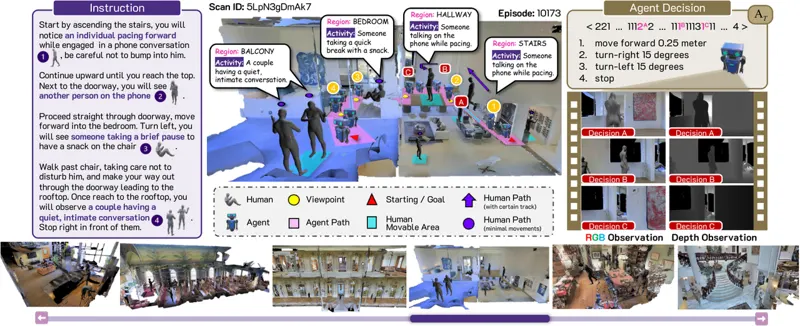
Vision-Language Navigation in dynamic, human-centric environments exposes a fundamental tension: linguistic reasoning is slow and deliberative, whereas safe, socially compliant planning should be instant and reactive. The resulting observation staleness is safety-critical: a maneuver chosen during inference can already be unsafe by the time it executes. We observe that, long before a VLM finishes its inference, its intermediate hidden states already encode action-relevant intent. We propose SPARK-VLN, a dual-system framework for dynamic social VLN that streams the slow VLM reasoner's knowledge to a fast flow-matching expert planner throughout token generation, providing fresh and evolving guidance during inference. This design is realized by three modules: a Token-Wise Hidden Streamer that extracts intermediate hidden states along the token generation process, a Sequence-to-Slot Latent Bridge that projects them into fixed-size latent slots, and an Evolving Latent Conditioner that infuses them into the expert planner. We also introduce a human-centric benchmark suite for dynamic social vision-language navigation that keeps pedestrians and the robot active throughout inference and reports navigation success, social compliance, human collisions, and explicit staleness statistics. Across these settings, SPARK-VLN mproves navigation success and social compliance while sustaining inference efficiency. Webpage: https://hutslib.github.io/SPARK-VLN/.

Tianshuai Hu, Yangyi Zhong, Zeying Gong · 692 views · Jul 18, 2026
Vision-language navigationSocial Navigation
Jul 18, 2026

As an Amazon Associate, we earn from qualifying purchases.