2:00Nemotron 3.5 Transcribe: One Model for Multilingual Audio@NVIDIAAI · 121 views · 2026-10-28NVIDIANemotron
0:46Fluid Speech Mini: Open-Source Dictation ASR Under 300 MB, On-Device@FluidVoiceApp · 230 views · 2026-10-13Speech RecognitionASR
0:22Microsoft's open-source VibeVoice-ASR: one pass over a 60-minute meeting yields speakers, timestamps and content; 54k GitHub stars@axichuhai · 795 views · 2026-09-30Voice InteractionASR
0:28Audio8 ASR Infinite: rolling KV cache enables 24/7 drift-free streaming ASR (Apache 2.0)@_akhaliq · 704 views · 2026-09-30Audio8 ASR InfiniteStreaming ASR
0:59Fish Audio upgrades its ASR model: speaker identification and inline emotion cues such as [laughter]@FishAudio · 885 views · 2026-09-28ASRSpeech Recognition
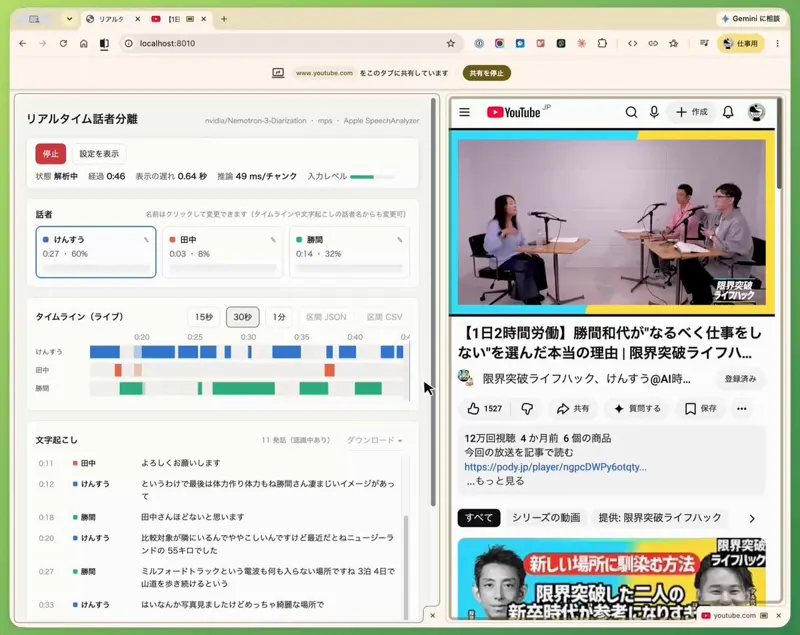
0:54Nemotron 3 Diarization tested: 100M-param real-time speaker diarization, better than expected locally@ouchi · 700 views · 2026-09-27NVIDIANemotron 3
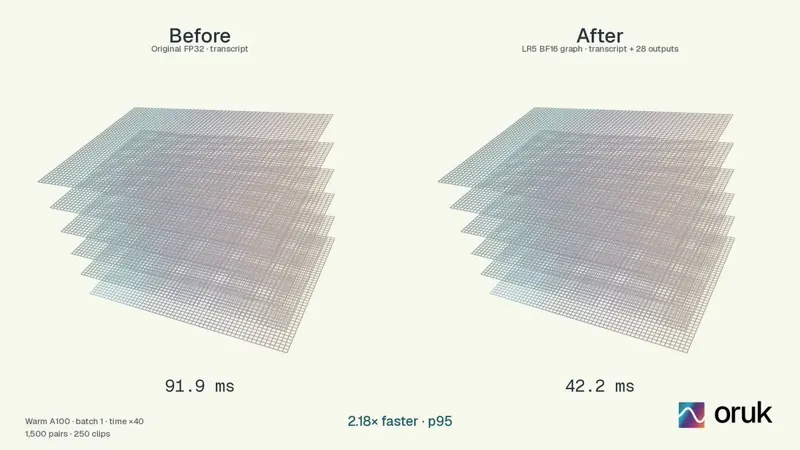
0:10JEV-Speech: Same 24-Layer Encoder, 2.18x Faster Inference@nrol_ling · 681 views · 2026-09-22Speech RecognitionInference Optimization
 0:56