ScaleNav: Scalable Internet Video Pretraining for Language-Conditioned Local Navigation
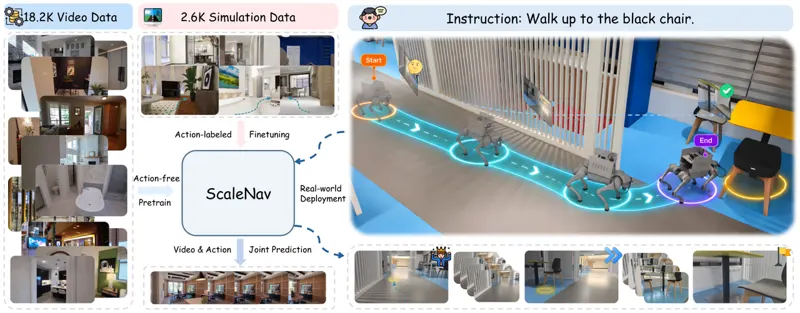
ScaleNav studies language-conditioned local navigation, where a robot must reach a text-specified target that is visible in its initial observation and stop near the described location. The method starts from action-free Internet egocentric videos, learns how observations evolve as a camera approaches an instructed target, aligns the resulting visual priors with executable action chunks using action-labeled simulation, and then jointly fine-tunes video and action prediction. The authors report 86.5% success on a single-view Short-Horizon OVON adaptation, 94.9% on HabitatGS-LN, and 83.3% overall success across 60 real-robot trials on a Unitree Go2 in three indoor environments.
Yihui Yang, Yuanhong Yu, Jiawei Wang · 71 views · Oct 19, 2026
Local NavigationVision-language-action (VLA)
Oct 19, 2026