Skip to content
← Tags

#Motion Imitation (4)

HuMBLE: Human Motion-Driven Behavior Learning for Embodied Locomotion

HuMBLE: Human Motion-Driven Behavior Learning for Embodied Locomotion

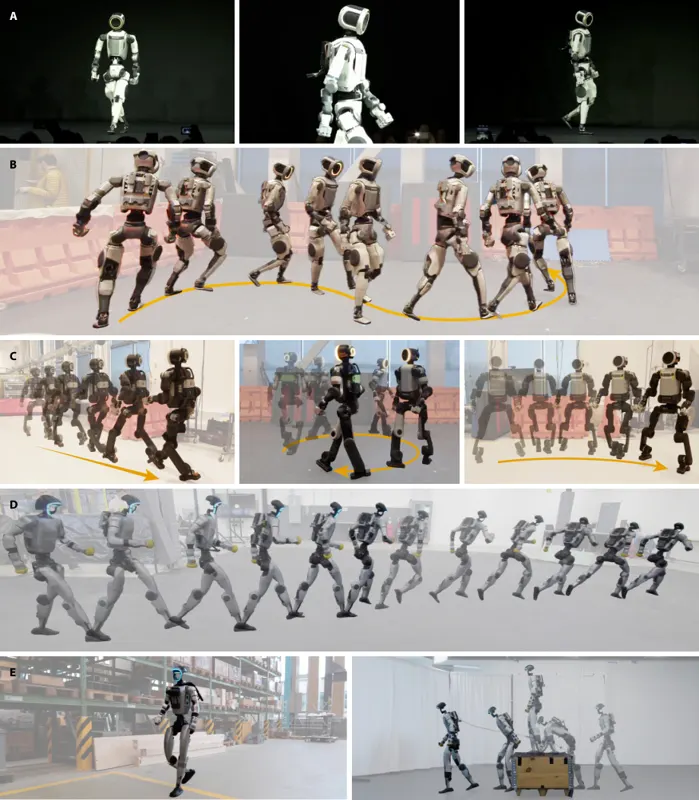
Despite recent advances in humanoid locomotion, controllers optimized for command tracking and robustness tend to produce mechanical gaits, whereas controllers tied to human motion data often fail to generalize to commands outside the data distribution. This work introduces a learning framework that balances these competing objectives to synthesize real-time steerable, robust, and biomimetic locomotion policies from human data. Using an in-house curated locomotion dataset covering diverse speeds and directions, we first learn a natural locomotion prior policy through a teacher-student distillation process. Specifically, we train a full-body reference-conditioned policy with Reinforcement Learning (RL), then distill it into a lightweight prior policy conditioned solely on proprioception and a planar torso-velocity steering command. Next, we fine-tune the prior policy with multi-task RL to expand command coverage and robustness beyond the data distribution, pairing a goal-conditioned task that tracks arbitrary commands with a reference-guided task that tracks the human data as an explicit style regularizer. We validate our framework on three humanoid robots: the Boston Dynamics Atlas R1, Atlas D1, and Unitree G1. Experimental results demonstrate robust performance across real-world scenarios, including direct user-controlled locomotion in indoor and outdoor environments, and integration as the locomotion layer within hierarchical control stacks. Benchmarks against Tabula Rasa RL policies trained without human data and ablation studies confirm that our framework yields a lightweight, deployable policy that reconstructs coordinated whole-body behavior from a steering command, retaining the human gait characteristics while remaining robust and fully steerable.
Mike Zhang, Dongho Kang, Kevin Bergamin · 540 views · Oct 7, 2026
Humanoid LocomotionMotion ImitationReinforcement LearningOct 7, 2026
Learning Athletic Humanoid Tennis Skills from Imperfect Human Motion Data

Learning Athletic Humanoid Tennis Skills from Imperfect Human Motion Data

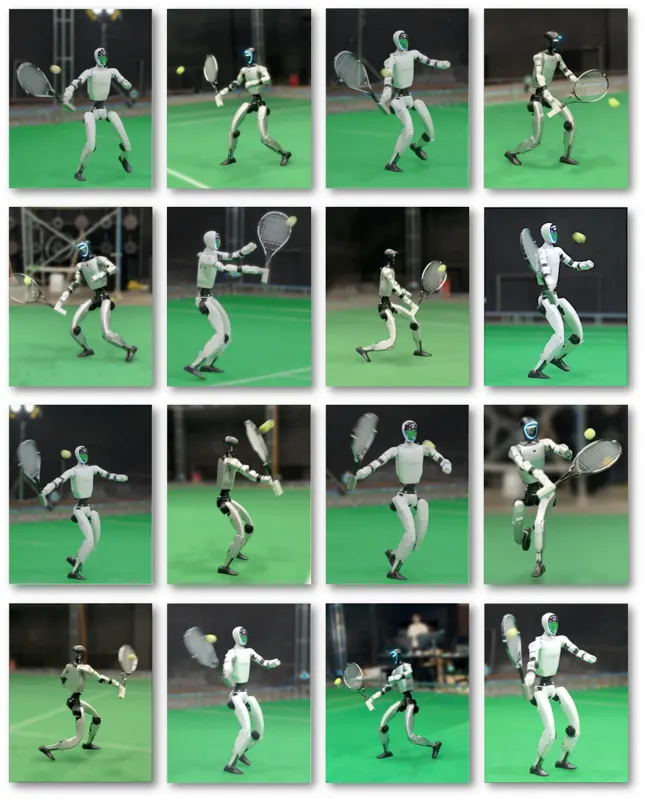
Human athletes demonstrate versatile and highly-dynamic tennis skills to successfully conduct competitive rallies with a high-speed tennis ball. However, reproducing such behaviors on humanoid robots is difficult, partially due to the lack of perfect humanoid action data or human kinematic motion data in tennis scenarios as reference. In this work, we propose LATENT, a system that Learns Athletic humanoid TEnnis skills from imperfect human motioN daTa. The imperfect human motion data consist only of motion fragments that capture the primitive skills used when playing tennis rather than precise and complete human-tennis motion sequences from real-world tennis matches, thereby significantly reducing the difficulty of data collection. Our key insight is that, despite being imperfect, such quasi-realistic data still provide priors about human primitive skills in tennis scenarios. With further correction and composition, we learn a humanoid policy that can consistently strike incoming balls under a wide range of conditions and return them to target locations, while preserving natural motion styles. We also propose a series of designs for robust sim-to-real transfer and deploy our policy on the Unitree G1 humanoid robot. Our method achieves surprising results in the real world and can stably sustain multi-shot rallies with human players. Project page: https://zzk273.github.io/LATENT/

Zhikai Zhang, Haofei Lu, Yunrui Lian · 568 views · Mar 13, 2026
LATENTSim-to-RealUnitreeMar 13, 2026
Learning Reusable Hybrid Motion Priors for Humanoid Locomotion from Motion Imitation

Learning Reusable Hybrid Motion Priors for Humanoid Locomotion from Motion Imitation

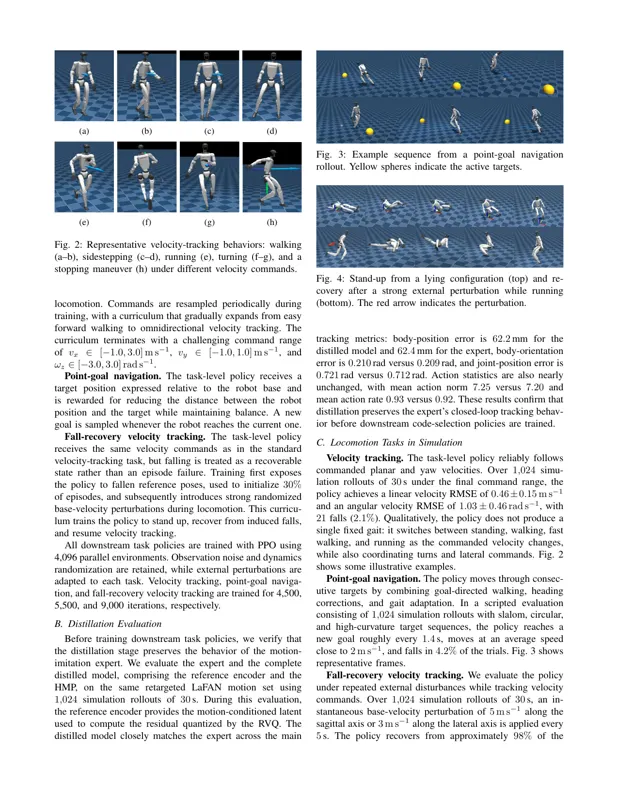
Reinforcement learning can produce robust humanoid controllers, but each new task is typically trained as a separate policy with its own reward design and training process. Motion imitation provides an alternative source of motor competence by training policies to track retargeted human motions, yet the resulting controllers remain reference trackers and are not directly usable as task policies. We propose a three-stage pipeline that turns motion-imitation skills into a reusable hybrid motion prior (HMP) for humanoid locomotion. First, an expert policy is trained to imitate retargeted human motion-capture clips. Second, the expert is distilled into a frozen architecture composed of a proprioceptive encoder, a residual vector-quantized (RVQ) codebook, and an action decoder. Third, task-level policies are trained to solve locomotion tasks by selecting discrete codebook entries while the HMP remains frozen. We evaluate the method on velocity tracking, point-goal navigation, and fall-recovery velocity tracking in simulation, and deploy the velocity-tracking policy on a real Unitree G1 robot. The distillation process preserves the tracking behavior of the expert, while the resulting HMP can be reused without retraining as the action interface for different downstream locomotion policies. The learned HMP reveals an interpretable codebook structure in which the number of active RVQ stages modulates the available gait patterns. We further show that training the codebook with the rotation trick improves latent organization and reduces downstream falls compared with a standard straight-through estimator.

Valerio Belli, Valerio Modugno, Enrico Mingo Hoffman · 280 views · Jul 27, 2026
Motion ImitationHumanoidGait optimizationJul 27, 2026

As an Amazon Associate, we earn from qualifying purchases.