World Action Agent: Harnessing VLMs for Robot Manipulation via World Action Rehearsal
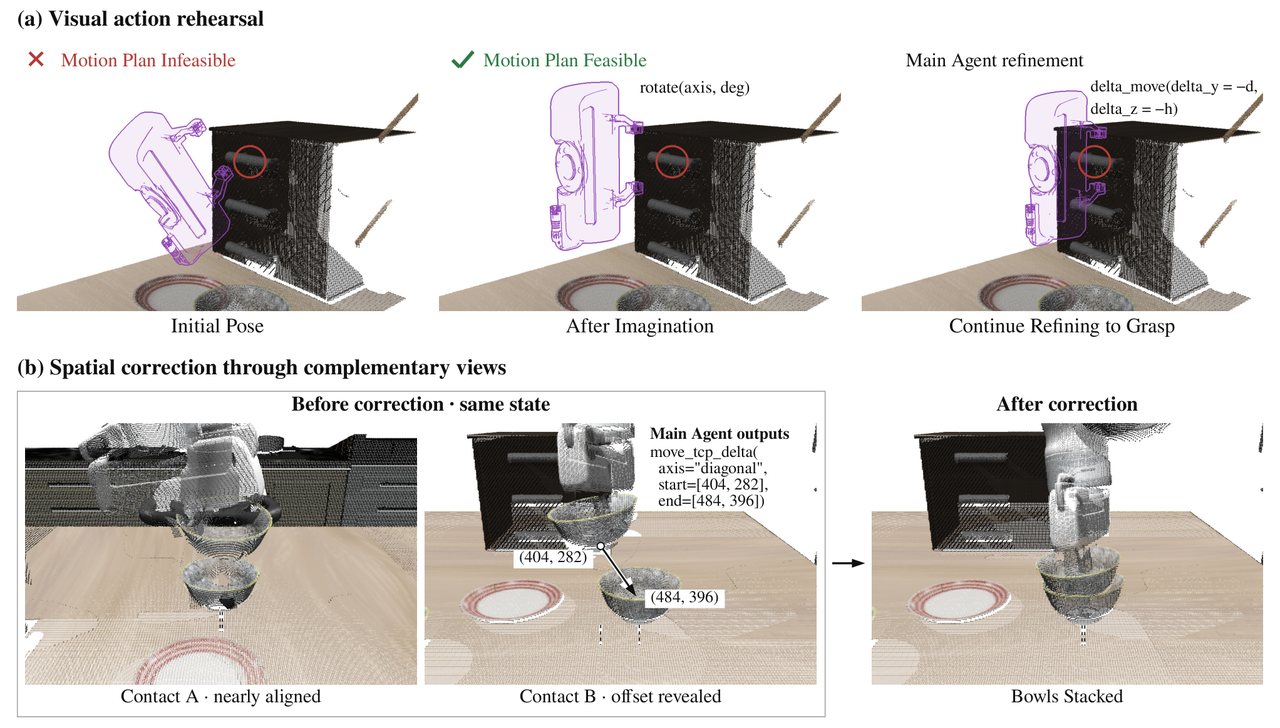
HKUST(GZ), CUHK and Knowin AI present World Action Agent (WAA), a multi-agent harness that changes what the VLM sees and how its decisions take effect — rather than the VLM itself — so a general-purpose VLM can pilot a robot with basic tools (point, drag, preview, execute), making every decision inside one visual action workspace. Three properties: Contact views, whose camera parameters are solved from interaction-region visibility under occlusion, framing compactness, view redundancy and stability, with the feasible set constraining the two views to orthogonal horizontal projections so any alignment error can be read along two independent directions — requiring only a base-frame point cloud, so the perception source (simulation, fused RGB-D, or VGGT reconstruction) is irrelevant; action rehearsal, where each action is an editable proposal planned by cuRobo, overlaid as a translucent robot in every view with a feasibility report, refined by an Imagination Agent in a separate context while the physical scene stays unchanged, and only proposals with executable plans become motion; and in-view correction, where the agent drags from a reference point to the desired location in the Contact view where the error is observed — the reference can be a visible point on the held object, so no conversion into an absolute gripper pose is needed. Skills evolve from expert videos and human Canvas-GUI teaching through Learner, Editor and Reviewer roles under evidence-citing and independent-review constraints. On LIBERO-Pro with Gemini 3.7 Flash, using skills evolved only from LIBERO-90 and frozen before evaluation, WAA reaches a state-of-the-art 75.6% average success, above ASPIRE (72.0%), end-to-end VLAs and the same-backbone Show-Harness (6.7%), scoring 80.0 / 73.3 on the two Spatial splits; an episode costs just 31 model calls, 150 s and $0.1996 versus 120 calls, 874 s and $0.5021 for Show-Harness. The frozen skills transfer to robosuite at 100.0%, and LoRA fine-tuning Qwen3.5-9B on 112 trajectories (1,774 decision steps) as the main agent only raises out-of-domain success from 1.7% to 43.3%.