Graph Engineering with Claude: 14 Steps from Linear Agents to Agent Fleets
Most multi-agent systems are still queues. This roadmap redraws them as graphs: nodes do work, edges move data, independent nodes run in parallel, and results converge only on real dependencies.
Most people building multi-agent systems are still building queues. Agent A finishes. Agent B starts. Agent C waits. Agent D waits even longer. The weird part is that most of that waiting is completely unnecessary: the tasks are independent, but the architecture isn't. No branching, no routing, no parallel execution — just one context dragging every step behind it until the workflow becomes slow, expensive, and eventually too large for one agent to reason about cleanly.
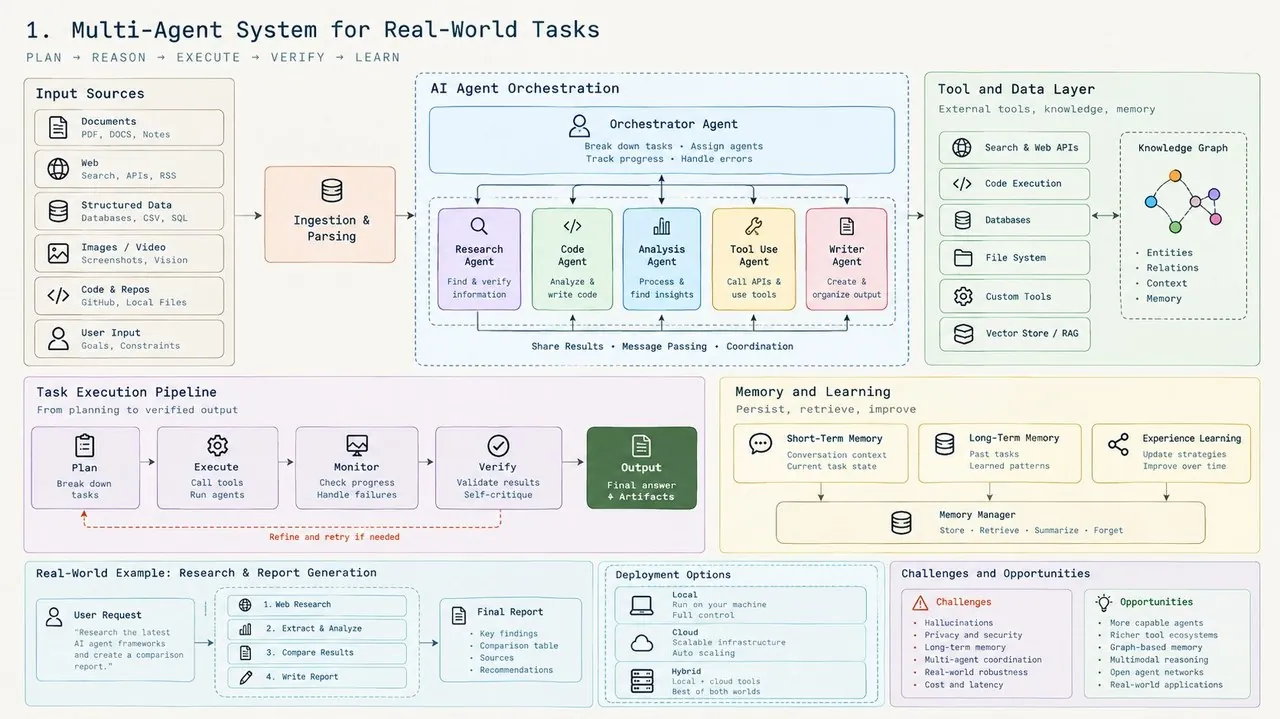
The fix isn't a better prompt. It's a different shape. Instead of treating an agent workflow like a list, treat it like a graph: nodes perform work, edges move data, independent nodes run simultaneously, and results converge only when they actually need each other. Once you start thinking this way, a single Claude session stops looking like one worker and starts looking like the control plane for an entire fleet. This article is the 14-step roadmap for getting there.
01. Stop thinking in steps. Think in dependencies.
Most workflows begin like this: A → B → C → D. It looks reasonable because that's how humans write instructions. But sequence does not automatically mean dependency. If B doesn't consume anything produced by A, there is no real reason B should wait. That's the first question to ask every time you see the word "then": does the next task actually need the previous task's output? If the answer is no, you've probably discovered parallel work.
A node is a bounded job. An edge exists only when information from one node is required by another. That distinction sounds tiny. It changes the entire architecture.
02. A linear agent is just the weakest possible graph
A → B → C → D is technically already a graph. It's simply a very narrow one: every node waits for the node before it, one slow task stalls everything downstream, and one failure can block the entire run. So don't immediately rebuild your agent — redraw it. Take every connection and ask whether actual data crosses that edge. You will often discover something closer to four independent jobs that can execute simultaneously and then converge when a final node needs their combined results. Same work, completely different wall-clock behavior.
flowchart LR
  subgraph linear["Linear: one context drags everything"]
    A1[A] --> B1[B] --> C1[C] --> D1[D] --> E1[E]
  end
  subgraph graph["Graph: independent nodes run at once"]
    A2[A] --> E2[E]
    B2[B] --> E2
    C2[C] --> E2
    D2[D] --> E2
  end
03. Give every node one job and one contract
Parallelism becomes dangerous when agents return unpredictable blobs of text. Every node should have three things: bounded input, one responsibility, and structured output. If a research node is supposed to return a title, URL, confidence score, and summary, define exactly that shape. Don't make the next agent guess what the previous agent meant. Schemas turn fuzzy conversations into components.
Instead of "research this and tell me what you find", think in an explicit contract:
{
  "title":      string,
  "url":        string,
  "confidence": number,
  "finding":    string
}
Now the downstream graph doesn't need a human to interpret the output. It can consume it directly.
04. Edges should move data, not intelligence
One of the easiest ways to waste model calls is asking an agent to perform work ordinary code can do instantly. Flatten an array? Code. Remove duplicates? Code. Sort numbers? Code. Filter failed results? Code. Convert one schema into another? Probably code. Agents should spend tokens where judgment is required; everything deterministic belongs in the wiring. That gives you a useful rule: nodes think, edges transform. The more deterministic work you remove from agents, the cheaper and more predictable the graph becomes.
05. Fan out anything independent
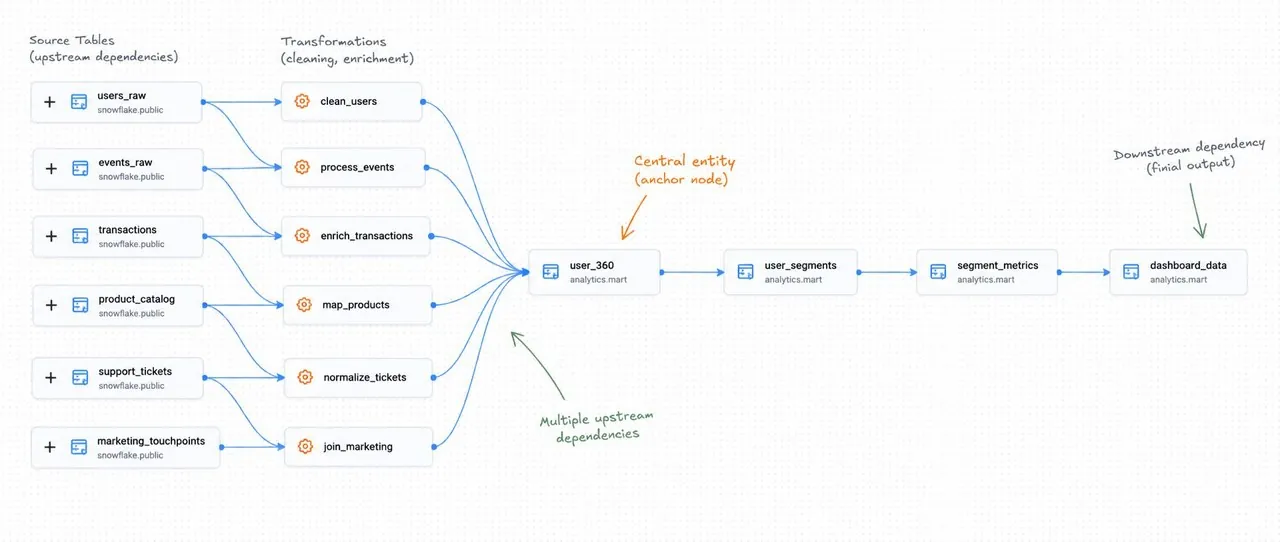
This is where graph architecture starts paying for itself. Imagine you need to inspect 40 files. A linear agent sees file 1 → file 2 → … → file 40. A graph sees 40 independent nodes: launch them concurrently, each gets a narrow context, performs one job, returns structured data, and disappears. The parent session never needs to stuff all 40 files into one enormous context — it only needs the outputs. That's the important scaling trick: parallelism doesn't just reduce time, it distributes context. Instead of one agent trying to remember everything, dozens of agents each remember only what matters to their node.
06. Merge only when the graph actually needs a merge
Parallel work eventually has to converge, but don't create barriers everywhere. A barrier makes downstream work wait until every upstream task finishes. Sometimes that's necessary: if you need to rank 50 findings against each other, you need the complete set; if you're deduplicating results across all sources, you need the complete set. But if every item can continue independently, forcing everything to synchronize is just wasted latency. The rule is simple: synchronize because the data requires it, not because the diagram looks cleaner.
07. Learn the diamond
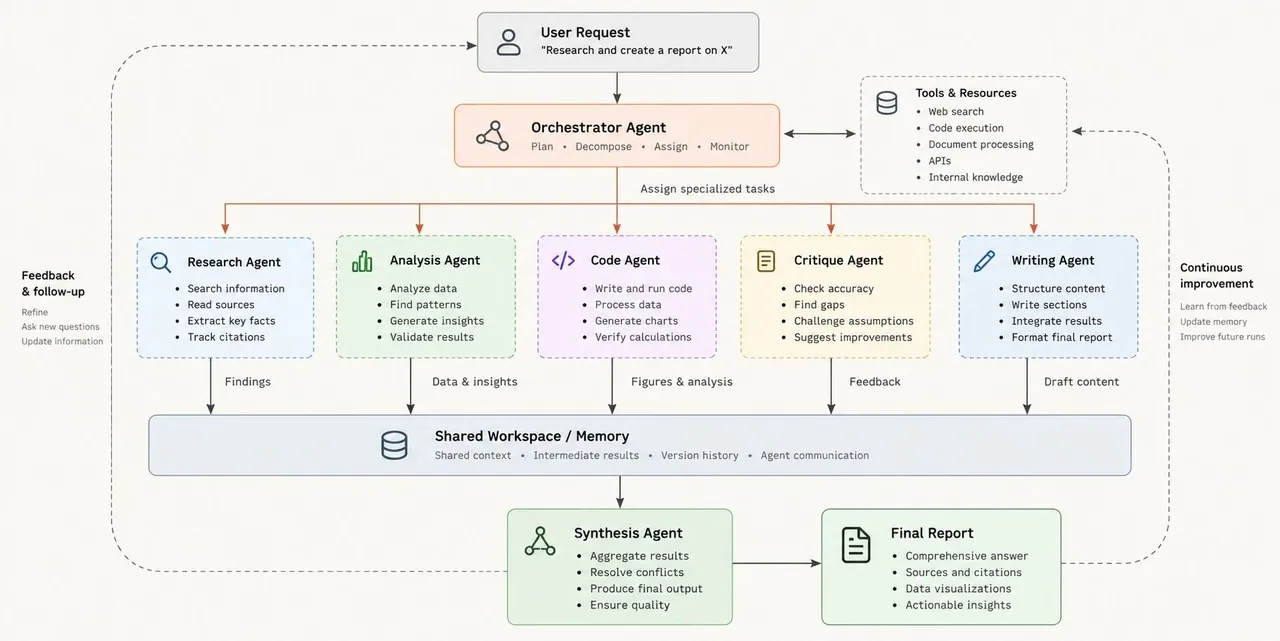
The most reusable agent topology looks like this: split → parallel work → reduce → synthesize. One task enters, many workers attack different parts, code compresses their outputs, and one final node synthesizes the answer. That's the diamond, and you can reuse it almost everywhere: research, code review, security auditing, market scanning, competitive analysis, document processing, dependency analysis, data extraction. The prompts change; the topology barely does. Once you recognize this pattern, "make the agent do more" becomes the wrong question. The better question is: where should this graph split, and where should it converge?
flowchart TD
  Q[Task enters] --> S1[Worker 1]
  Q --> S2[Worker 2]
  Q --> S3[Worker N]
  S1 --> R[Deterministic reduce: dedupe, normalize, rank]
  S2 --> R
  S3 --> R
  R --> SYN[Synthesis node: one answer]
08. Route dynamically instead of running everything
Some tasks shouldn't follow the same path. Suppose an agent inspects a code change and returns { "risk": "low" }: that can trigger a lightweight review. But { "risk": "high" } might trigger five independent reviewers covering security, correctness, performance, tests, and architecture. The intelligence decides what the situation is; the code decides what happens next. That's a powerful separation — Claude provides judgment at the node, your graph provides deterministic behavior between nodes.
result = classify_node(diff)           # judgment: model
match result["risk"]:                  # behavior: code
    case "low":  run(lightweight_review)
    case "high": fan_out([security, correctness,
                          performance, tests, architecture])
09. Make findings survive an attack
More agents aren't automatically better. Verification is better. Instead of asking one agent "is this finding correct?", create independent critics whose job is to destroy it: one checks correctness, one tries to reproduce it, one looks for security implications, one searches for contradictory evidence. Then only findings that survive verification continue downstream. This flips the normal agent pattern — you're no longer asking models to agree, you're designing a system where weak conclusions have difficulty surviving. For high-stakes research or code analysis, that difference matters enormously.
flowchart LR
  F[Finding] --> C1[Critic: correctness]
  F --> C2[Critic: reproduce it]
  F --> C3[Critic: security impact]
  F --> C4[Critic: contrary evidence]
  C1 --> V{"Survived all critics?"}
  C2 --> V
  C3 --> V
  C4 --> V
  V -->|yes| D[Continue downstream]
  V -->|no| X[Rejected and recorded]
10. Design failure as a local event
A good graph should expect nodes to fail. If you launch 30 research agents and two time out, the other 28 shouldn't become useless. Failures should collapse locally: downstream nodes need to tolerate missing results, parallel writers need isolated environments, and retries should target failed nodes instead of restarting the entire workflow. Think of each node as disposable. The graph is the durable thing. That's a major architectural shift from traditional single-agent prompting.
11. Add loops only when they have a stopping condition
Graphs don't have to move only forward; some problems require cycles. Find bugs, verify them, use the findings to search for related bugs, repeat. But an uncontrolled loop is just an expensive infinite machine. Every cycle needs a convergence condition. A useful pattern is to continue until several consecutive rounds discover nothing new — and to track everything you've already seen, including rejected findings. Otherwise rejected results can return in the next round and your agents will repeatedly pay to rediscover the same dead ends. A loop without memory isn't exploration. It's amnesia with a token budget.
seen = set()           # includes rejected findings
dry_rounds = 0
while dry_rounds < 3:
    new = discover(exclude=seen)
    if not new:
        dry_rounds += 1
    else:
        dry_rounds = 0
    seen |= verify_and_keep(new) | reject(new)
12. Stop paying premium-model prices for cheap work
A graph exposes something a monolithic agent hides: different jobs require different levels of intelligence. Extracting fields from 100 documents doesn't necessarily need the same model that performs final synthesis. Classification can be cheap, formatting can be cheap, basic extraction can be cheap — final judgment can stay expensive. So tier the graph: use lighter models for repetitive bounded nodes, and reserve the strongest model for synthesis, arbitration, difficult reasoning, and ambiguous decisions. You don't need to make the workflow less intelligent. You need to stop spending intelligence where it isn't useful.
| Job class | Model tier | Why |
|---|---|---|
| Classification, formatting, field extraction | Light / cheap | Bounded, repetitive, verifiable by schema |
| Per-file inspection, per-source search | Light / cheap | Narrow context, one job, structured output |
| Routing decisions on ambiguous input | Mid | Judgment needed, but the choice set is small |
| Synthesis, arbitration, hard reasoning | Strongest | Where an error costs the whole run |
13. Architecture determines latency
Two workflows can contain exactly the same agents and still finish at dramatically different times. Why? Topology. Consider a three-stage process across 20 items. With global barriers, stage 1 must finish for all 20, then stage 2 begins, then everyone waits again, then stage 3 begins. A pipeline behaves differently: item 1 can already be entering stage 3 while item 14 is still finishing stage 1. Nothing waits unless there is a genuine dependency. This is why graph design becomes a performance problem: you're optimizing not only prompts and models, you're optimizing critical paths. And once you start looking at workflows through that lens, unnecessary waiting becomes painfully obvious.
| Topology | When item 1 reaches stage 3 | Failure blast radius |
|---|---|---|
| Global barriers | After all 20 items finish stages 1 and 2 | One slow item stalls every stage |
| Pipeline (per-item edges) | As soon as item 1 finishes stage 2 | One slow item stalls only itself |
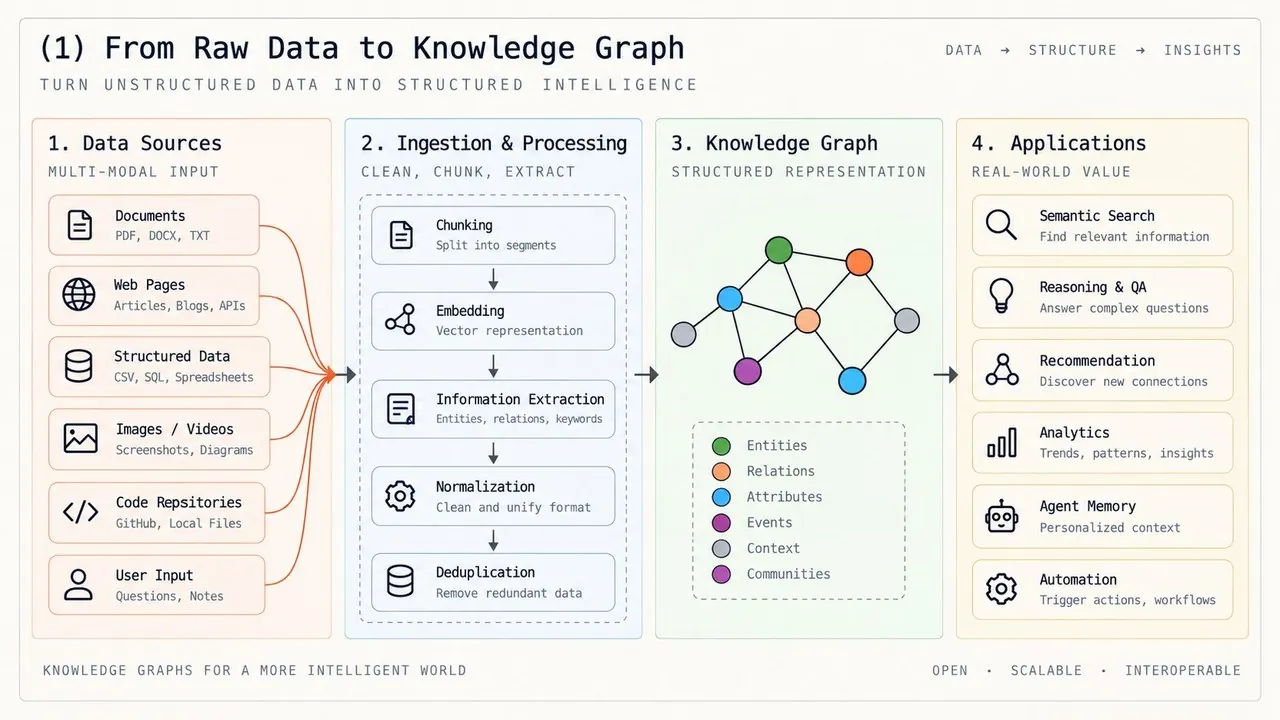
14. Eventually, let Claude design the graph
The final level is when you stop manually defining every topology. Give Claude the objective. Let it decompose the problem, identify independent tasks, decide where fan-out makes sense, generate the orchestration, launch specialized workers, and verify their outputs; then let a final node synthesize the result. At that point you're no longer writing a long prompt telling one model how to think — you're describing the objective of a temporary software system. Claude builds the system, the system executes, and the graph disappears when the job is done. That is a fundamentally different abstraction from prompting.
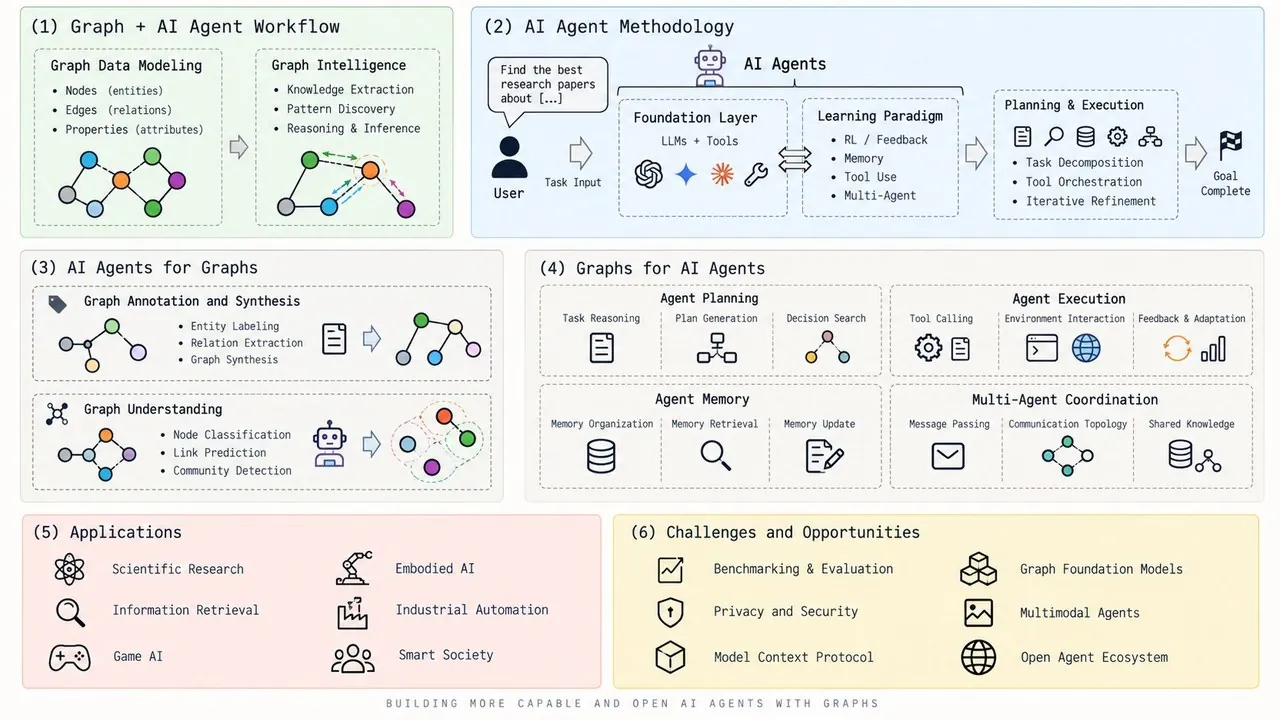
Six graphs worth building first
- Repository security sweep. One worker per route or module, independent vulnerability checks, a verification layer for every reported issue, and final synthesis only after findings survive review.
- Deep research engine. Split a question into competing research angles, search simultaneously, normalize sources with code, cross-check important claims, and synthesize only verified evidence.
- Large-scale code migration. One worker per file or module, tests after each transformation, failures routed into repair loops, and only passing work merged.
- Multi-perspective code review. Classify the size and risk of the diff first; small changes get a lightweight path, high-risk changes fan out across correctness, security, performance, architecture, and testing.
- Continuous ecosystem scanner. Check releases, repositories, blogs, documentation, and discussions simultaneously, deduplicate with code, rank meaningful changes, and generate one compact report.
- Unknown-size bug discovery. Launch multiple independent finders, track every discovered candidate, verify new findings through different lenses, feed survivors back into discovery, and stop only after repeated dry rounds.
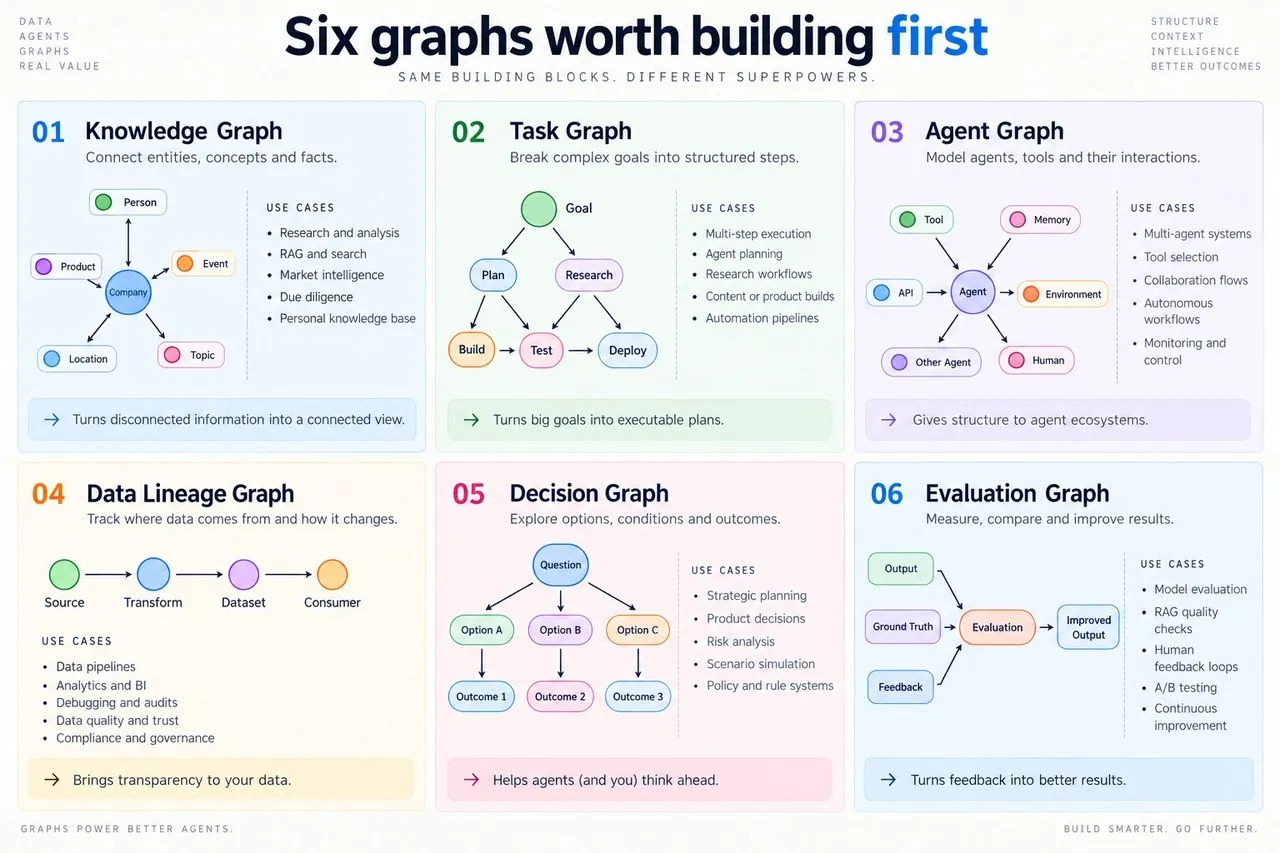
The larger shift
A beginner asks: what prompt should I write? A better builder asks: what agent should perform this task? But the architectural question is: what shape should the work have? One context shouldn't research everything. One agent shouldn't verify itself. One model shouldn't perform every class of work. And independent tasks shouldn't wait simply because you happened to write them on separate lines.
The linear agent isn't disappearing; it's becoming one node inside something larger. Once you start seeing work as nodes, edges, branches, barriers, routes, verifiers, and cycles, the ceiling moves. You stop trying to build one agent that can do everything. You build a graph that knows when to split the work, where to spend intelligence, what to verify, and when to bring the fleet back together.
Source: X (Twitter) article by Promix (@Promixyz), "Graph Engineering with Claude: 14 Steps from Linear Agents to Agent Fleets" (x.com/Promixyz/status/2102424036416348494, 2026-09-22). Fully adapted here; all figures are from the original article, and the Mermaid diagrams and tables were added for this edition.
Source:Promix (X)https://x.com/Promixyz/status/2102424036416348494