Skip to content
← Tags

#LLM Agent (17)

LongHarness: Stateful Evidence Management for Agentic Reasoning over 100M-Token Corpora

LongHarness: Stateful Evidence Management for Agentic Reasoning over 100M-Token Corpora

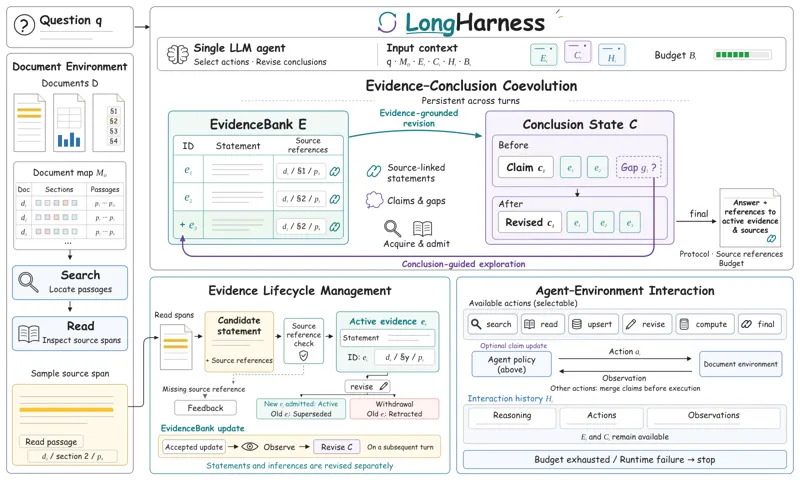
Corpus-level long-context reasoning requires agents to acquire and integrate evidence across document collections that exceed their context windows. Existing agent harnesses enable incremental access to these corpora, but acquired evidence and evolving conclusions often remain entangled in a growing interaction history. This implicit state management can lead to two coupled failure modes: unbounded exploration, where retrieval expands the interaction history without resolving decision-relevant information gaps, and evidence-state drift, where previously acquired evidence or subsequent corrections fail to inform the current conclusion. We present LongHarness, a model-agnostic harness that makes the interaction between acquired evidence and evolving conclusions explicit. Its core mechanism, Evidence-Conclusion Coevolution, uses unresolved conclusions to guide exploration toward missing information, while newly acquired evidence strengthens or revises the conclusions that directed the search. LongHarness couples this process with Evidence Lifecycle Management, which keeps accumulated evidence current and traceable throughout the interaction. Together, these mechanisms focus retrieval on remaining information needs and keep conclusions aligned with current evidence. We evaluate LongHarness on OfficeQA Pro V1 and V2, AA-LCR, and LongBench v2 using GLM-5.3-Flash and Qwen3.8-Flash. Compared with direct reasoning using the same backbone, LongHarness improves GLM-5.3-Flash exact match on OfficeQA Pro from 15.8% to 60.2% on V1 and from 4.4% to 61.1% on V2. Against state-of-the-art agent harnesses, it surpasses Claude Code by 12.0 percentage points on V1 and Codex by 18.9 points on V2. With Qwen3.8-Flash, LongHarness reaches 61.7% on V1, outperforming Claude Code by 8.3 points and Codex by 12.0 points.
Songtao Huang, Zhijie Zhong, Xiaohan He · 130 views · Oct 9, 2026
Agent HarnessLong-Context ReasoningEvidence ManagementOct 9, 2026
Dream-RSI: Recursive Self-Improvement through Evolving Worlds

Dream-RSI: Recursive Self-Improvement through Evolving Worlds

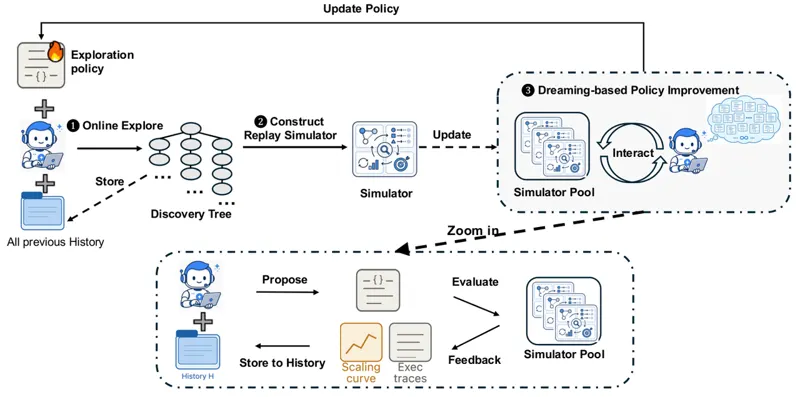
Recursive self-improvement is becoming increasingly vital for autonomous AI agents, where progress hinges on discovering high-value solutions across complex domains. The driver of this process is effective exploration, however, managing and improving exploration strategies remains a major bottleneck. Current systems face a fundamental dilemma: fixed strategies fail to adapt as search spaces scale, while online policy optimization requires navigating vast meta-search spaces under delayed and expensive feedback over long-horizon rollouts. We introduce {Dream-RSI}, a framework for scalable and recursively self-improving exploration. A lightweight orchestration layer makes exploration explicit and programmable while leaving the underlying coding agent unchanged. Our key insight is that accumulated discovery history can serve as a replay simulator over the realized search space. By performing dreaming in the replay simulator constructed from historical discovery trees, {Dream-RSI} secures immediate, low-cost off-policy feedback to evaluate and refine exploration policies without invoking repetitive, expensive online evaluations. The improved policy is subsequently redeployed online to drive further discovery, continuously expanding the simulator pool in a self-improving loop. Across algorithm engineering, mathematical optimization, and GPU kernel engineering, {Dream-RSI} achieves competitive or improved discovery quality while substantially reducing discovery cost in several settings.

Tong Zheng, Xidong Wu, Zheng Zhang · 976 views · Sep 14, 2026
Recursive self-improvementWorld ModelsLLM AgentSep 14, 2026
Harness VLA: Steering Frozen VLAs into Reliable Manipulation Primitives via Memory-Guided Agents

Harness VLA: Steering Frozen VLAs into Reliable Manipulation Primitives via Memory-Guided Agents

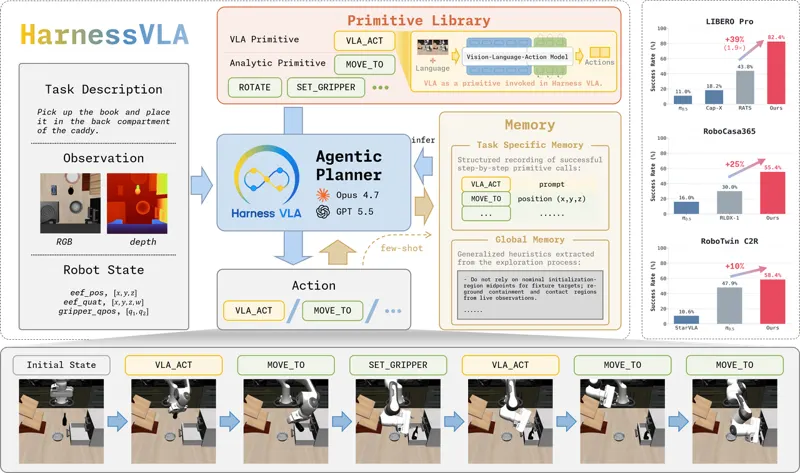
Language-conditioned manipulation requires both precise contact-rich control and robust reasoning over language, scenes, and long horizons. End-to-end Vision-Language-Action (VLA) models provide strong local visuomotor skills, but they are trained on in-distribution task trajectories and often fail under deployment perturbations such as semantic retargeting, goal re-binding, spatial-layout shifts, and unstable local contacts. LLM coding agents provide complementary semantic and compositional reasoning, but purely analytic primitives struggle with irregular grasping, constrained placement, and articulated-object interaction. We present Harness VLA, a memory-augmented agentic framework that exposes a frozen VLA as a retryable contact-rich primitive and composes it with a small fixed library of analytic primitives for grounding, staging, transport, navigation, and release. Rather than expanding the skill library, the harness learns the operating range of these fixed primitives from task-specific execution traces, global success rules, and failure models. By lifting semantic re-grounding, non-contact execution, and VLA re-staging to the planner while reserving the frozen VLA for local contact-rich phases, Harness VLA extends pretrained VLAs beyond their original trajectory distribution without finetuning. Across perturbed tabletop, household kitchen, and clean-to-randomized bimanual manipulation, Harness VLA improves over the strongest relevant baselines by 38.6 and 27.1 percentage points on LIBERO-Pro and RoboCasa365, respectively, and reaches 58.4% on RoboTwin C2R. Code is available at https://github.com/RLinf/RPent.

Yixian Zhang, Huanming Zhang, Feng Gao · 983 views · Jul 9, 2026
VLARobot ManipulationLLM AgentJul 9, 2026

As an Amazon Associate, we earn from qualifying purchases.