PAPER DEEP DIVE
VioLA: Learning Generalist Humanoid Control Policies from Human Data
VioLA is a generalist humanoid policy that predicts body and hand motion latents instead of joint commands. Frozen SONIC-based encoders map human and robot demonstrations into the same action space, so 93.2% of its 140.6M training frames come from human recordings. On a real Unitree G1 it reaches 100% locomotion and 88.6% manipulation success with no task-specific fine-tuning.
Paper: VioLA: Learning Generalist Humanoid Control Policies from Human Data (arXiv:2610.12435, arxiv.org/abs/2610.12435)
Authors: Mert Albaba, Jens Beißwenger, Anna Manasyan, Daniel Marta, Michael J. Black, Wieland Brendel, Andreas Krause, Georg Martius, Martin Riedmiller (Vesoma, ETH Zürich, MPI-IS, University of Tübingen, ELLIS Institute; Albaba and Beißwenger are co-first authors)
Project page: viola.is.tue.mpg.de Code status: the abstract states that code and checkpoints will be released, but the project page currently shows only "Code (coming soon)" and no matching repository exists on GitHub, so this entry is recorded as open source promised, code pending.
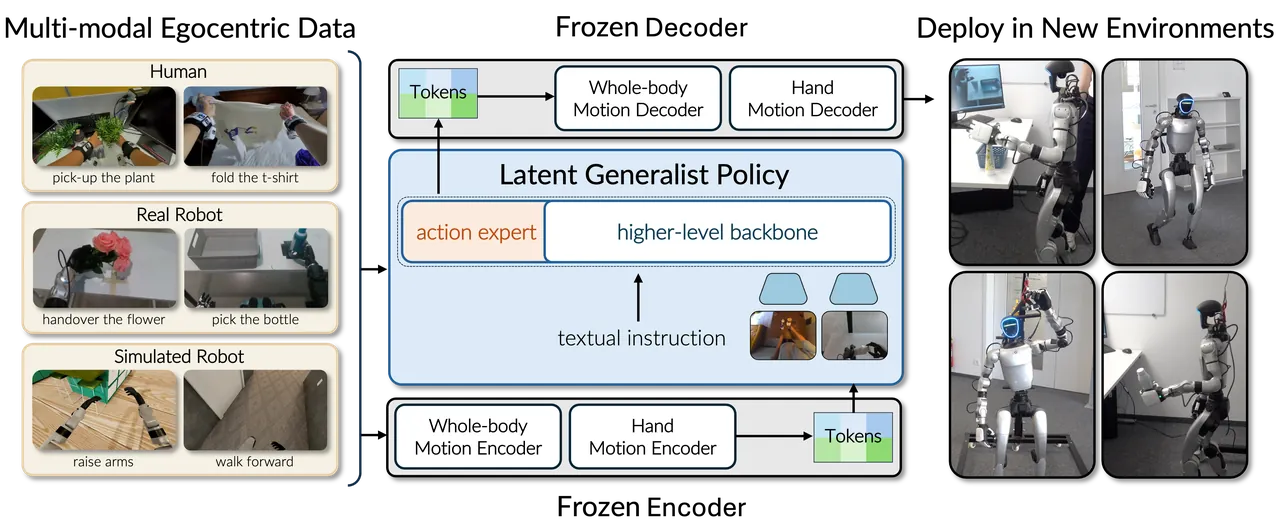
Figure 1: VioLA at a glance. Left: human and robot motion encoders write demonstrations into a shared body and hand latent space. Center: the generalist policy predicts motion latents from vision, language and proprioception. Right: frozen robot controllers execute the predictions. Annotated human motion therefore acts as supervision inside the policy's own action space.
In One Sentence
VioLA stops asking a humanoid generalist to emit joint commands and asks it instead for body and hand motion latents, handing coordination and balance to a frozen SONIC body controller and a frozen hand decoder; because paired encoders map human and robot motion into that same space, 93.2% of the 140.6M training frames are human recordings that serve directly as action labels, and on a real Unitree G1 the policy reaches 30/30 locomotion and 31/35 manipulation with no task-specific fine-tuning.
Background and Motivation
Consider telling a humanoid robot to walk to a table and close a laptop. It has to find the table, walk over to it, reach the screen and press the lid down, all without losing its balance. Vision-language-action models (VLAs) and world-action models (WAMs) already follow instructions of this kind on robot arms after demonstration learning, but moving the same generalist recipe onto a humanoid runs into two walls: what the policy must predict, and where the demonstrations come from.
The first wall is the action space. Whole-body control requires the legs, torso, arms and fingers to move together: reaching shifts the centre of mass, and stepping changes where the hands can reach. A generalist policy that predicts joint commands directly has to learn both how those degrees of freedom coordinate and which movement the instruction asks for. The coordination half is already solved by whole-body controllers: given a desired motion, a pretrained whole-body controller computes the joint commands that follow it while maintaining balance, and more recent latent motion controllers accept the desired motion as a compact learned vector, a motion latent, produced by an encoder.
The second wall is data. Humanoid teleoperation needs a robot plus an operator, so recording many tasks in many environments is expensive. Existing humanoid generalists such as GR00T and $\Psi_{0}$ are fine-tuned on the target task with additional robot demonstrations before deployment, which means every new task costs another round of collection. Recordings of people walking, reaching and handling objects are far more plentiful, but human motion is not a robot command: the recording does not contain the joint commands a policy would normally learn to predict.
Every prior route pays for this somewhere. HumanPlus has the robot physically shadow the person during recording, which again requires one robot per demonstration; VideoMimic reconstructs human motion and scene geometry from video and trains humanoid controllers to reproduce the movement in simulation; EgoMimic shares pose supervision between humans and robots while retaining a robot joint-action head; HAT and EgoVLA predict human-centric wrist and hand motion that is converted into robot commands at deployment; EgoScale pretrains on human wrist and retargeted finger motion before adapting with human-robot and task-specific robot data; Being-H0 pretrains a vision-language policy to predict tokenized human wrist and finger motion and adds a robot action head only during post-training; LAPA and WholeBodyVLA infer latent actions from video yet still learn robot-command prediction from robot demonstrations; UniT learns shared human-humanoid tokens through visual and action reconstruction, but those tokens align policy features and are never passed to a robot controller for execution. The common thread is that the human signal either never reaches the deployed action output, or every human demonstration still needs a robot-side counterpart.
The observation behind this paper is that the solution to the first wall already contains the answer to the second. Latent controllers such as SONIC give the human encoder and the robot encoder the same body latent space: encode a person walking and the paired controller decodes a latent that commands walking on the robot. The body controller does not command fingers, so the authors pretrain a hand encoder-decoder module with the same structure to cover the gap: human and robot hand encoders share one space, and a hand controller turns hand latents into finger commands. A generalist policy can then predict motion latents alone, choosing where and when to move, while frozen controllers determine how the joints must move to execute that choice. Human recordings thereby arrive already labelled in the policy's action space, and no robot has to replay them.
Three contributions follow. First, VioLA itself: a generalist humanoid policy that predicts body and hand motion latents while pretrained controllers convert those predictions into coordinated joint commands. Second, a pipeline that turns human recordings and robot demonstrations into latent targets, creating 781 hours of training data of which 93% is human. Third, zero-shot locomotion and manipulation on a real Unitree G1 in a new environment with different object instances and without task-specific fine-tuning, plus comparisons of VLA and world-action backbones and of human versus robot supervision, including real-robot locomotion learned from human demonstrations alone.
Preliminaries
FSQ motion codes and reference windows. Each encoder emits a 64-coordinate motion code formed by flattening two 32-dimensional finite-scalar-quantized (FSQ) codes whose coordinates lie on the grid $\{k/16:k=-16,\ldots,15\}$; call that grid $\mathcal{G}$. Body and hand codes share this format, but their encoders and decoders are independent. One code summarizes a reference window starting at the current frame: at 50 Hz, the SONIC v1.1 robot encoder and the hand encoder read 10 frames at offsets $0,5,\ldots,45$, while the human body encoder reads 10 consecutive frames $0,1,\ldots,9$; when a window would run past the end of a demonstration, the last frame is repeated. The reference window decides what a single code means, and the policy's chunk length $H$ decides how many consecutive codes one prediction covers.
Flow matching time convention. The action expert is trained with flow matching: target chunks are mixed with conformable Gaussian noise at an interpolation time $\tau$ and the network learns a velocity field. Inference starts from pure noise at $\tau=1$ and integrates backwards along the learned velocity to the clean action chunk at $\tau=0$. Even though encoder outputs are quantized codes, the action expert regresses continuous coordinates. Each backbone keeps its own time sampler: $\pi_{0.5}$ takes $\tau=0.999b+0.001$ with $b\sim\operatorname{Beta}(1.5,1)$; DiT4DiT takes $\tau=b/0.999$ and discretizes time into 1,000 conditioning buckets; GR00T runs in the opposite direction, sampling $r=0.999(1-b)$, building $(1-r)\bm{\epsilon}+r\mathbf{Z}_{t}$ and regressing $\mathbf{Z}_{t}-\bm{\epsilon}$, which returns to the common convention after setting $\tau=1-r$ and flipping the sign.
Real-time chunking (RTC). While the policy computes the next chunk, the robot is still executing part of the previous one, and two independent predictions can disagree at the handover, producing an action jump. RTC conditions the next prediction on the latents that will already be executed before inference finishes, so the new chunk grows out of the motion currently under way. This paper runs RTC inside the motion latent space and quantifies its effect on handover continuity in the experiments.
Method
A shared latent action space
Closing a laptop requires reaching for the lid and pushing it down while staying balanced. A body motion encoder summarizes a short segment of recorded movement as a vector, the motion latent; its paired decoder is a pretrained whole-body controller that, given the latent and the robot's recent state, produces commands for the legs, torso and arms to follow the encoded movement while maintaining balance. A separate hand encoder summarizes finger motion, and its paired decoder converts a hand latent into finger commands. What VioLA learns is to predict those body and hand latents from the scene and the instruction: for the laptop task it predicts standing, reaching and hand motions, while the pretrained body controller and hand decoder determine the joint commands that execute them.
On the body side the paper uses SONIC's pretrained encoders and controller, whose human and robot encoders map motion into the same body latent space. Because the body controller does not command the fingers, the authors pretrain a hand encoder-decoder module separately with the same structure, and its human and robot hand encoders likewise map motion into a common space. Each encoder summarizes a short window with a 64-coordinate latent, and the two are concatenated into VioLA's 128-coordinate action $\mathbf{z}_{t}=[\mathbf{z}_{t}^{\mathrm{body}};\mathbf{z}_{t}^{\mathrm{hand}}]$. Body and hand latents are predicted together so that reaching and finger motion can be timed to one another.
Given an egocentric image $I_{t}$, an instruction $\ell$ and robot proprioception $\mathbf{s}_{t}$, the policy $p_{\theta}$ predicts a chunk of $H$ successive actions:
$$\widehat{\mathbf{Z}}_{t}\sim p_{\theta}(\mathbf{Z}_{t}\mid I_{t},\ell,\mathbf{s}_{t}),\qquad \mathbf{Z}_{t}=[\mathbf{z}_{t},\ldots,\mathbf{z}_{t+H-1}]^{\mathsf{T}}. \tag{1}$$
Each row of the chunk supplies one body and hand latent for one control step. Because the paired encoders accept both human and robot motion, demonstrations from either source can supervise these predictions, and that is where the paper's whole data strategy starts.
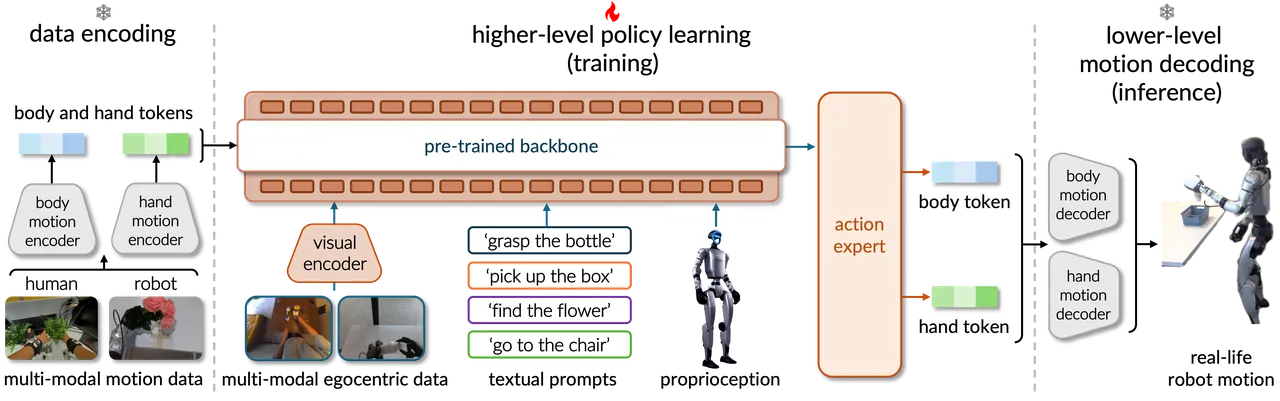
Figure 2: Method overview. Left: frozen motion encoders construct body and hand action targets from human or robot demonstrations. Center: the generalist policy predicts motion latents from an egocentric image, an instruction and proprioception, and is the only component updated during training. Right: the frozen body controller and hand decoder turn predicted latents into robot joint commands. Human and robot encoders produce targets for these same decoders.
Frozen motion modules: the body and hand ledgers
SONIC v1.1's body encoder takes 1,751 coordinates: the reference motion expressed in the simulated robot's heading frame. The body decoder takes the current 64-coordinate code plus 10 frames of proprioceptive history (joint offsets, joint velocities, base angular velocity, projected gravity, previous action), 994 input coordinates in total, and emits 29 values that become joint position targets after the controller's default posture and action scaling. Control runs at 50 Hz with four 200 Hz physics steps inside each update. On the hand side, the human and robot hand encoders map motion into a shared 64-coordinate space, and two decoders, Dex3 and Inspire, translate a code into finger trajectories for the corresponding hardware. Every motion encoder and decoder stays frozen while the generalist policy trains: the policy learns to predict their codes rather than learning a hand prior of its own.
Target encoding: humans and robots into one space
An annotated recording of a person closing a laptop contains that person's images, the instruction, and the body and hand movements used to complete the task, but no robot joint commands. The human motion encoders map those movements into VioLA's action space, and robot demonstrations enter the same space through the corresponding robot encoders. For a demonstration source $e\in\{\mathrm{human},\mathrm{robot}\}$, the target at time $t$ is
$$\mathbf{z}_{t}=\bigl[E^{e}_{\mathrm{body}}(\mathbf{m}_{t}^{\mathrm{body}};\gamma_{t});\,E^{e}_{\mathrm{hand}}(\mathbf{m}_{t}^{\mathrm{hand}})\bigr]. \tag{2}$$
Here $\mathbf{m}_{t}^{\mathrm{body}}$ and $\mathbf{m}_{t}^{\mathrm{hand}}$ are short annotated motion windows starting at $t$, and $\gamma_{t}$ is the robot heading used to express the desired body motion; consecutive targets are stacked into the chunk $\mathbf{Z}_{t}$. Demonstrations without hand annotation supervise body predictions only, and their hand coordinates are zeroed in the loss.
Closed-loop simulation annotation: supplying the proprioception human demos lack
Human data is still missing one input the policy requires, namely robot proprioception. The authors obtain it by letting the frozen body controller track the demonstrated motion in simulation. One detail here is easy to miss. Body targets depend on the executing robot's current heading, and the executor's heading can differ from the demonstrator's: if the robot turns toward the table more slowly than the person in the recording did, the next latent has to encode how much turning is still left. Carrying the human heading through the whole clip amounts to assuming the robot tracks the reference exactly, which physics does not permit. Targets are therefore computed in closed loop: at every simulation step the encoder codes the motion using the simulated robot's current heading, the controller decodes that code into joint commands, and the simulator advances one step:
$$\mathbf{z}_{t}^{\mathrm{body}}=E^{e}_{\mathrm{body}}\!\left(\mathbf{m}_{t}^{\mathrm{body}};\,\gamma(\mathbf{s}_{t}^{\mathrm{sim}})\right),\qquad \mathbf{s}_{t+1}^{\mathrm{sim}}=\mathrm{Sim}\!\left(\mathbf{s}_{t}^{\mathrm{sim}},\,D_{\mathrm{body}}(\mathbf{z}_{t}^{\mathrm{body}},\mathbf{h}_{t}^{\mathrm{sim}})\right). \tag{3}$$
At time $t$, the image $I_{t}$, the simulated state $\mathbf{s}_{t}^{\mathrm{sim}}$ and the encoded target $\mathbf{z}_{t}^{\mathrm{body}}$ are paired before the simulator advances. Human samples use this simulated state as body proprioception, while robot samples keep their recorded proprioception. Hand state inputs come from whatever the data stores: for robot demonstrations the hand target uses commanded finger motion where available and the hand proprioception uses measured motion, and the two differ materially during grasping because commanded fingers can close further than the object allows. All targets are computed before generalist-policy training; training itself runs no simulation and updates no motion module. What the pipeline buys is concrete: turning annotated human motion into latent targets never requires optimizing a per-recording mapping onto robot joints.
Training: retargeting GR00T N1.7's action expert to 128 latent coordinates
Demonstrations from both sources now have exactly the same form, namely an image, an instruction, a robot state and a target motion chunk, so one prediction head and one loss serve both. VioLA uses GR00T N1.7 as its backbone (a Cosmos-Reason2 vision-language trunk plus a flow-matching action transformer), keeps its flow-matching objective, and changes only the action expert's output to 128 latent coordinates per step. For a target chunk $\mathbf{Z}_{t}$, conformable noise $\bm{\epsilon}\sim\mathcal{N}(\mathbf{0},\mathbf{I})$ and interpolation time $\tau$,
$$\mathbf{X}_{t,\tau}=(1-\tau)\mathbf{Z}_{t}+\tau\bm{\epsilon},\qquad \mathbf{U}_{t}=\bm{\epsilon}-\mathbf{Z}_{t}, \tag{4}$$
and the action expert $v_{\psi}$, conditioned on backbone features and robot state (together $\mathbf{c}_{t}$), is trained to output $\mathbf{U}_{t}$ from $\mathbf{X}_{t,\tau}$:
$$\mathcal{L}_{\mathrm{motion}}=\mathbb{E}_{\bm{\epsilon},\tau}\!\left[\sum_{n\in\mathcal{B}}\sum_{k=0}^{H-1}\sum_{j=1}^{128}w_{nkj}\bigl(v_{\psi}(\mathbf{X}_{t,\tau},\tau\mid\mathbf{c}_{t})_{n,kj}-U_{n,kj}\bigr)^{2}\right], \tag{5}$$
where $n$ indexes samples in the batch $\mathcal{B}$ (each carrying its own target chunk, noise and condition), $k$ indexes steps inside the chunk and $j$ indexes latent coordinates. The weights $w_{nkj}$ normalize the loss and are zero for coordinates without a target, for example the hand coordinates of a recording with no hand annotation. Two reductions correspond to different backbones. $\pi_{0.5}$ averages over the annotated coordinates of each step first:
$$w_{nkj}=\frac{m_{nkj}}{NH\max(1,\sum_{j^{\prime}}m_{nkj^{\prime}})}. \tag{6}$$
GR00T and DiT4DiT instead average over all valid coordinates in the batch, with GR00T adding $10^{-6}$ to the denominator and DiT4DiT requiring at least one valid coordinate:
$$w_{nkj}=\frac{m_{nkj}}{\sum_{n^{\prime},k^{\prime},j^{\prime}}m_{n^{\prime}k^{\prime}j^{\prime}}}. \tag{7}$$
On a fully annotated batch the two differ only by a numerical offset; when hand annotations are missing, the first gives every action step equal weight while the second gives every annotated coordinate equal weight. Human and robot samples pass through the same action expert and the same loss, the model receives no explicit human or robot source label, and the motion encoders and decoders remain frozen throughout.
Three backbone interfaces: one action space, different conditioning
To test whether the recipe is bound to a particular model, the authors attach the same action space to two VLAs and one WAM: GR00T N1.7, $\pi_{0.5}$ and DiT4DiT. All three predict the same 128 coordinates per step (64 body plus 64 hand) with no target normalization, while chunk length and state conditioning stay exactly as each backbone defines them: GR00T uses $H=40$, the other two $H=50$. The state of $\pi_{0.5}$ is 110 discretized values, namely 29 body joint offsets, 3 gravity coordinates, 14 current finger positions in the Dex3 representation, and a 64-coordinate hand code delayed by 50 ticks; that one-second delay prevents the hand code's reference window from leaking future targets, and during training the delayed code is zeroed with probability 0.5, an option that remains available at deployment. GR00T's state encoder takes 46 values (29 joint offsets, 14 finger positions, 3 gravity coordinates) with state dropout 0.2, and human and robot samples share one action expert and embodiment tag; DiT4DiT uses 32 values.
| Backbone | Chunk length H | State conditioning | Motion target scaling |
|---|---|---|---|
| $\pi_{0.5}$ | 50 | 110 values, tokenized | identity |
| GR00T N1.7 | 40 | 46 values, state encoder | identity |
| DiT4DiT | 50 | 32 values, state encoder | identity |
Table 1: The VioLA interface for three backbones (paper Table 2). All variants predict the same 128 body and hand coordinates with no target normalization.
DiT4DiT is a world-action model: besides actions it predicts the future video frames $\mathbf{V}_{t}$ that follow the current image, and the two losses are summed:
$$\mathcal{L}_{\mathrm{WAM}}=\mathcal{L}_{\mathrm{video}}(\mathbf{V}_{t}\mid I_{t},\ell)+\mathcal{L}_{\mathrm{motion}}(\mathbf{Z}_{t}\mid I_{t},\ell,\mathbf{s}_{t}). \tag{8}$$
It uses Cosmos-Predict2.5-2B and conditions the action transformer on layer-17 features. During training the video branch is supervised by the current frame plus four future frames at offsets 12, 24, 36 and 48, and the action loss also backpropagates into the video backbone; at deployment only the current observation exists, so future video features come from the model's own prediction. For human clips, the recorded future frames supervise video prediction while the encoded body and hand motion supervises action prediction.
Deployment: turning latents into joint commands at 50 Hz
At deployment VioLA predicts a motion chunk from the robot camera image, the instruction and proprioception. At each control step the body controller turns the current body latent plus the recent proprioceptive history $\mathbf{h}_{t}$ into joint commands, and the hand decoder turns the hand latent into finger commands:
$$\mathbf{u}_{t}^{\mathrm{body}}=D_{\mathrm{body}}\!\left(\widehat{\mathbf{z}}_{t}^{\mathrm{body}},\mathbf{h}_{t}\right),\qquad \mathbf{u}_{t}^{\mathrm{hand}}=D_{\mathrm{hand}}^{\mathrm{robot}}\!\left(\widehat{\mathbf{z}}_{t}^{\mathrm{hand}}\right). \tag{9}$$
Body and hand commands update at 50 Hz. Because the body controller reads the robot's changing state at every update, joint coordination does not pause while the generalist policy computes the next chunk. The hand decoder reconstructs 10 frames from each hand latent, executes frame index 5 (0-based) after a 5-tick moving average, and converts that into hand joint commands; frame 0 is used separately to reconstruct the current hand state. The Unitree G1 carries five-fingered Inspire hands with 6 actuated joints per hand, and predicted latents pass through the Inspire decoder to produce 12 finger targets; for a policy trained on 14-value Dex3 hand states, measured Inspire motion is first encoded and then reconstructed with the Dex3 decoder, so what changes is the state representation shown to the policy while execution targets still come from the Inspire decoder. Encoder targets sit on the FSQ grid, yet the action expert predicts continuous coordinates: the $\pi_{0.5}$ execution path clips predictions to $[-1,1]$ and passes them straight to the decoder without rounding.
Continuous execution also requires neighbouring chunks to agree at the handover. VioLA performs RTC in the motion latent space: the next prediction is conditioned on the latents that will be executed before inference completes, so the new chunk carries the motion it has to continue. Handover continuity is measured as the L2 change of body latents between consecutive 20 ms control steps, $\Delta_{t}=\|\mathbf{z}_{t}^{\mathrm{body}}-\mathbf{z}_{t-1}^{\mathrm{body}}\|_{2}$, and a spike at a chunk boundary is a jump.
Data and training schedule: 93.2% of 781 hours is human
The training pool combines the human recording set EgoSuite, derived from EgoStandard, with four robot corpora: Humanoid Everyday, PSI, UnifoLM-WBT and LeVERB. After conversion the pool holds 31,988 demonstrations, 140,572,312 frames and 780.96 hours, with human data accounting for 64.6% of episodes and 93.2% of frames. EgoSuite keeps 20,680 of 26,382 source episodes, since 5,702 are excluded during conversion and filtering; the unified loader reserves 338 Humanoid Everyday episodes for evaluation; and at $H=50$, 46 of LeVERB's 3,555 episodes cannot supply one complete action chunk. Humanoid Everyday and UnifoLM-WBT provide commanded hand motion, PSI provides measured hand motion because it has no commanded trajectories, human hand targets come from fitted MANO trajectories, and LeVERB supplies body targets only.
| Corpus | Episodes | Frames | Hours | Targets |
|---|---|---|---|---|
| Humanoid Everyday (real G1) | 4,064 | 2,962,764 | 16.46 | body + hand |
| PSI (real G1) | 835 | 1,431,454 | 7.95 | body + hand |
| UnifoLM-WBT (real G1) | 2,854 | 4,454,240 | 24.75 | body + hand |
| LeVERB (simulated G1) | 3,555 | 713,279 | 3.96 | body only |
| EgoSuite (human recordings) | 20,680 | 131,010,575 | 727.84 | body + hand |
| Total | 31,988 | 140,572,312 | 780.96 | — |
Table 2: The converted demonstration pool (paper Table 1). Everything is unified to 50 Hz, and hours are frames divided by 50 Hz. Exposure during training is set by sampling weights, not by corpus volume.
The schedule is 150k steps on human demonstrations followed by 50k steps that sample the five corpora uniformly at probability 0.20 each. Batch size is constant, so this schedule assigns an expected 80% of training samples to human data, which is a different statement from humans holding 93.2% of the available frames. The robot-only variant uses the four robot corpora throughout and is evaluated at both 50k and 200k steps; the human-only variant uses human demonstrations throughout. No variant receives task-specific adaptation.
flowchart TD
  H[Human recordings EgoSuite
SMPL body and MANO hand motion] --> HENC[Frozen human body and hand encoders]
  R[Robot corpora Humanoid Everyday PSI UnifoLM-WBT LeVERB] --> RENC[Frozen robot body and hand encoders]
  SIM[Closed-loop sim tracking with frozen body controller
supplies robot heading and proprioception] --> HENC
  SIM --> RENC
  HENC --> TGT[Latent targets 64 body plus 64 hand FSQ coords
chunk Z of H steps]
  RENC --> TGT
  TGT -->|flow matching supervision| POL
  IMG[Egocentric image I_t] --> POL
  LANG[Instruction ell] --> POL
  PROP[Robot state s_t] --> POL
  POL[Latent generalist policy
GR00T N1.7 or pi_0.5 or DiT4DiT backbone
the only trained component] --> ZH[Predicted chunk with RTC conditioning
on latents executing during inference]
  ZH --> DB[Frozen SONIC v1.1 body controller
29 joint targets at 50 Hz]
  ZH --> DH[Frozen hand decoder
frame 5 of 10 plus 5-tick moving average]
  DB --> G1[Unitree G1 with Inspire hands]
  DH --> G1
Figure 3: Training and execution dataflow of VioLA. Frozen encoders write both kinds of demonstration into one latent space, the generalist policy is the only trained component, and frozen decoders turn predictions back into joint commands.
Experimental Results
Evaluation setup
The hardware is a Unitree G1 with five-fingered Inspire hands, evaluated in the authors' laboratory. Instructions for the six locomotion and posture tasks come from LeVERB and the seven manipulation tasks from Humanoid Everyday. Both corpora also contribute training demonstrations, so the evaluation tasks overlap the training task families; what is held out is the specific episodes, the laboratory environment and the object instances, and a reserved split of Humanoid Everyday is excluded from training entirely. Zero-shot here means deployment without task-specific fine-tuning. Each policy is tested five times per task, success requires completing the instruction while progress also credits partial completion (a robot-only policy that sits down with its arms still extended scores 0.5, and a DiT4DiT kettle trial that slowly closes the lid but never returns the arm to idle scores 0.8), tasks are weighted equally, and one standard error over trials is reported. Locomotion tasks are limited to 5 s (Bend Down 10 s), manipulation tasks have no fixed limit but how the motion ends still counts toward progress, and every task starts from an idle standing posture except Stand Up, which starts seated. Only full credit counts as success.
Zero-shot locomotion: 30/30
The six tasks span holding a posture, raising an arm, bending down, walking forward, sitting down and standing up from a chair. VioLA predicts the body and hand motion for each instruction, the frozen body controller produces the coordinated body commands and the hand decoder produces the finger commands, and all 30 trials succeed. The released GR00T N1.7 manages only standing still, 5/30 (16.7%), and $\Psi_{0}$ completes none (0/30). In other words, VioLA follows all six locomotion and posture instructions in the authors' laboratory without any task-specific fine-tuning, and the Bend Down sequence shows a full-body posture change in which the robot lowers from standing into a crouch and holds it.
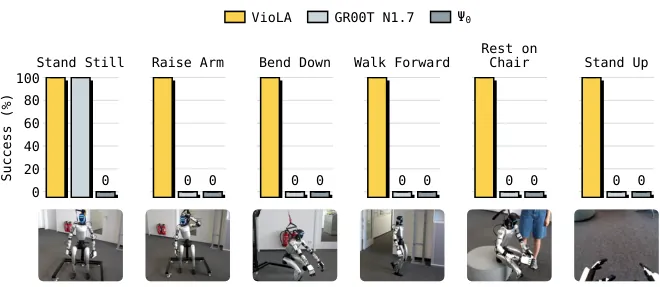
Figure 4: Locomotion and posture success rates (top half of paper Figure 3). Five trials per task across six tasks: VioLA is perfect, GR00T N1.7 is non-zero only at standing still, and Ψ₀ is zero everywhere. Photos show each task on site.
Zero-shot manipulation: 31/35
Manipulation adds a further requirement: the body must bring the hand to the object and the fingers must act at the right moment to move, grasp or release it. VioLA completes 31/35 trials (88.6%), succeeding in every trial of Rotate Chair, Close Laptop, Place Dumpling, Close Kettle and Push Duck, in 4/5 Hang Coat trials and in 2/5 Store Shampoo trials. Hang Coat means receiving a coat from a person and folding it over the other arm, so the task set covers pushing and closing as well as receiving, transporting and placing. The released GR00T N1.7 completes none of the 35 trials, and $\Psi_{0}$ completes three chair rotations and nothing else (3/35, 8.6%).
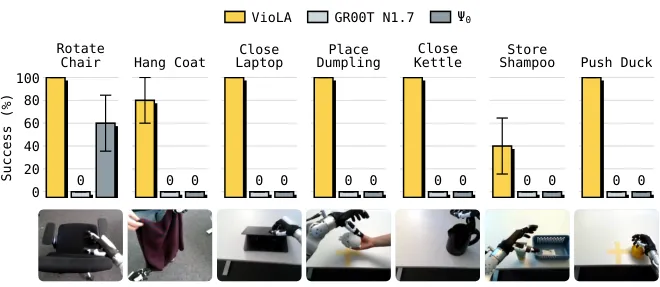
Figure 5: Manipulation success rates (bottom half of paper Figure 3). Ψ₀ reaches roughly sixty percent only on Rotate Chair; on Store Shampoo VioLA is near forty percent while the other two are at zero.
The four failures concentrate on acquiring and retaining objects. In the Store Shampoo failures the robot knocks the bottle over while reaching to grasp it, and the last row of Figure 6 shows a failed coat execution in which the robot catches the coat but drops it before completing the fold and return. These examples make the point that reaching an object or landing an initial grasp is not manipulation success. The separately analyzed bottle-carrying task remains unsolved: every VioLA variant fails all five trials, at different stages spanning grasp timing, the transition from grasping to walking, and upright release, and including it lowers VioLA's manipulation success from 31/35 (88.6%) to 31/40 (77.5%).
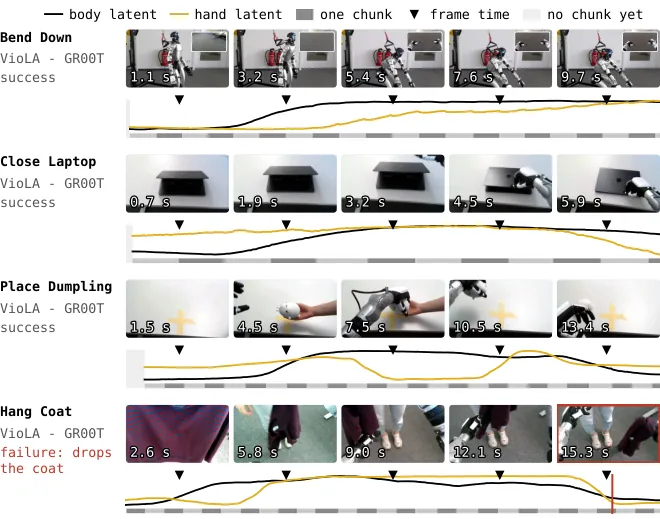
Figure 6: From body motion to object interaction (paper Figure 4). The first three rows, bending down, closing a laptop and placing a dumpling toy, succeed; the last row, hanging a coat, fails and is marked in red. Black and gold curves are the executed body and hand latents projected onto their first principal components (63-91% and 47-87% of variance), gray bands mark successive action chunks, and triangles align image timestamps.
| Policy | Locomotion / posture (6 tasks × 5 trials) | Manipulation (7 tasks × 5 trials) |
|---|---|---|
| VioLA (GR00T N1.7 backbone) | 30/30 (100%) | 31/35 (88.6%) |
| GR00T N1.7 (released) | 5/30 (16.7%, standing still only) | 0/35 (0%) |
| $\Psi_{0}$ (released) | 0/30 (0%) | 3/35 (8.6%, chair rotation only) |
Table 3: Main real-robot zero-shot results. None of the three receives task-specific fine-tuning, and VioLA's joint commands come from frozen controllers.
Motion tokens: describing a complex action takes surprisingly little
Consecutive latent predictions can produce nearly identical motion, so the authors group similar predictions and count one distinct motion token per group, separately for body and hand and restarting the grouping for each execution. One complete chair-rotation execution uses on average 60 body tokens and 31 hand tokens; closing a laptop uses 82 and 43; those two executions last 10.0 s and 9.3 s on average. Standing still and raising an arm take about 20 and 36 body tokens, walking forward takes 182, and the hand counts track content just as clearly: raising an arm needs a single hand token, while chair rotation and laptop closing need several distinct hand motions.
Grouping distance is measured on the integer grid: the 64-coordinate latent is mapped to grid coordinates and compared with an L1 distance,
$$\mathbf{q}=\mathrm{clip}\bigl(\mathrm{round}(16\mathbf{z}),-16,15\bigr),\qquad d(\mathbf{q},\mathbf{q}^{\prime})=\sum_{j=1}^{64}|q_{j}-q^{\prime}_{j}|. \tag{10}$$
Scanning in time, the first prediction is kept; each later prediction joins the nearest kept representative if its distance is within a threshold $\rho$, and otherwise becomes a new representative (representatives are original prediction vectors, not means or rounded vectors). The thresholds are calibrated on decoded postures: 84 calibration episodes (32 chair rotations, 32 laptop closings, and 10 each of dumpling placement and duck pushing) plus 21 held-out episodes, with the reference budget taken from SONIC's reported real-robot MPJPE-L of 25.7 mm over 14 links and the authors' measured commanded-versus-observed hand difference of 1.44 cm (83 Humanoid Everyday episodes, 6 fingertip proxies, 32,516 frames). The admissible thresholds satisfying "95% of calibration episodes within the reference budget" are 16 for body and 96 for hand, and the paper reports the tighter 8 and 32 to suppress wrist and single-finger deviations: dropping the body threshold from 16 to 8 lowers the mean wrist p95 over calibration episodes from 5.09 cm to 3.03 cm, and dropping the hand threshold from 96 to 32 lowers the worst-finger p95 from 1.08 cm (chair rotation) and 1.25 cm (laptop closing) to 0.31 cm. Under the tight thresholds, all 84 calibration episodes, all 21 held-out episodes and 3 chair-alternative transfer episodes satisfy the mean budget, and the largest episode-level mean p95 error across calibration and held-out data is 1.234 cm for body links and 0.294 cm for fingertip proxies.
| Task | Body tokens (mean) | Hand tokens (mean) | Mean duration (s) |
|---|---|---|---|
| Stand Still | 19.8 | 2.8 | 7.0 |
| Raise Arm | 35.6 | 1.0 | 4.8 |
| Walk Forward | 182 | 16.0 | 5.8 |
| Rotate Chair | 60.4 | 31.4 | 10.0 |
| Close Laptop | 82.2 | 43.2 | 9.3 |
Table 4: Mean distinct motion tokens per complete execution (read from paper Figure 5; thresholds body 8, hand 32; five recordings per task).
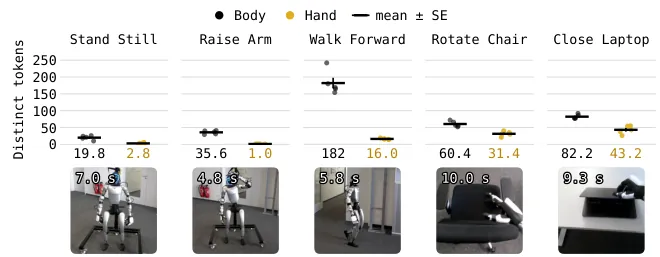
Figure 7: Motion token counts (paper Figure 5). Each point is one complete recording's distinct body (black) and hand (gold) token count; horizontal lines are means and whiskers one standard error. Numbers below give mean counts and durations.
These numbers make concrete how much the prediction problem has changed. Each body token describes a segment of coordinated motion that the frozen controller converts into joint commands in light of the robot's changing state, and each hand token specifies finger motion through the hand decoder. A complex execution needs only a small number of distinct motion predictions, while the controller still updates joints at every control step: what the generalist policy learns is which motions to emit and when, and coordination is reused from the pretrained motion modules.
What human data actually contributes
A VioLA variant trained exclusively on human data reaches 12/30 (40%) on the locomotion tasks: 4/5 bending down, 3/5 walking, 2/5 sitting and 3/5 standing up from a chair, while it cannot hold the standing-still or arm-raising instructions. It does follow "walk to the yellow sofa" and crouch down, behaviours for which the generalist-policy training contains no robot demonstration at all, which shows that encoded human motion really is usable action supervision for real-robot behaviour and simply does not yet cover all six instructions.
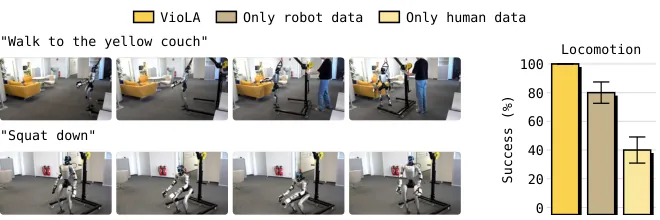
Figure 8: Human demonstrations teaching robot behaviours (paper Figure 6). Left: the human-only policy executing "walk to the yellow sofa" and "crouch down". Right: locomotion success for human-then-mixed 30/30, robot-only 24/30 and human-only 12/30, all with the same backbone and the same frozen motion modules, and both human-then-mixed and robot-only trained for 200k steps.
Once robot data is available, human-then-mixed VioLA reaches 30/30 after 200k steps against 24/30 (80%) for robot-only: the gap comes from bending down, where robot-only fails all five trials, and from one sitting trial in which the arm was never lowered. At equal update counts, the human-then-mixed schedule raises locomotion success by 20 percentage points. Manipulation goes the other way, with robot-only at 33/35 (94.3%) against VioLA's 31/35 (88.6%): robot-only succeeds on all five shampoo trials but only four kettle trials, while VioLA succeeds on every kettle trial and only two shampoo trials, with identical counts on the remaining five tasks. The division of labour is therefore clear: human data supplies the body motions the robot-only policy lacks, while fine interactions such as grasping a shampoo bottle remain stronger with robot demonstrations.
| Training data | Locomotion success | Manipulation success |
|---|---|---|
| human-then-mixed (main VioLA schedule) | 30/30 (100%) | 31/35 (88.6%) |
| robot-only (200k steps) | 24/30 (80%) | 33/35 (94.3%) |
| human-only | 12/30 (40%) | — |
Table 5: Human versus robot supervision (paper Section 4.5). All three are VioLA variants sharing one GR00T backbone and one set of frozen motion modules.
Backbone comparison: GR00T strongest, and a WAM can learn it too
The three variants use the same training data and budget, predict the same 64 plus 64 coordinates per step and are executed by the same frozen motion modules, which makes this a protocol-matched comparison between VLAs and a WAM on humanoid learning. On locomotion, GR00T and DiT4DiT both reach 30/30 while $\pi_{0.5}$ reaches 20/30 (66.7%), succeeding at standing still, raising an arm, sitting down and standing up but failing at walking and at the full bend. Manipulation widens the gap: VioLA on GR00T scores 31/35 (88.6%), $\pi_{0.5}$ scores 16/35 (45.7%) and DiT4DiT scores 9/35 (25.7%), with partial completions lifting progress to 51.4% and 29.4% respectively. At the behavioural level all three variants rotate the chair successfully; $\pi_{0.5}$ also closes the laptop and places the dumpling in every trial but drops the coat after grasping it in four trials, while DiT4DiT fails to close its thumb around the coat and one dumpling trial ends in a grasp followed by a drop. The frozen body controller and hand decoder are shared across all three, so the differences come entirely from the generalist policy's predictions: successful manipulation requires holding the reach, grasp and release sequence together through the end of the task.
On prediction latency, GR00T takes 160.2 ms, $\pi_{0.5}$ 208.6 ms and DiT4DiT 248.5 ms, giving replan intervals of 559.9, 608.4 and 648.0 ms (statistics over 161, 83 and 57 episodes and 3,871, 2,554 and 1,035 chunks). At 50 Hz each prediction spans roughly 8 to 12 control steps during which the robot keeps moving, which is exactly why the transition from an ongoing motion into the next prediction is a necessary part of execution and why RTC has to exist.
| Backbone | Episodes | Chunks | Prediction latency (ms) | Replan interval (ms) |
|---|---|---|---|---|
| GR00T | 161 | 3,871 | 160.2 ± 1.8 | 559.9 ± 1.8 |
| $\pi_{0.5}$ | 83 | 2,554 | 208.6 ± 0.6 | 608.4 ± 0.6 |
| DiT4DiT | 57 | 1,035 | 248.5 ± 2.5 | 648.0 ± 2.4 |
Table 6: Measured chunk timing (paper Table 3). Mean ± one standard error across recorded episodes.
RTC: the jumps at the handover really are suppressed
RTC is compared on and off for Stand Still and Raise Arm: the first probes consistency while a posture is held, the second probes continuity when the target posture changes. Without RTC, spikes recur around chunk switches, even for standing still; with RTC the change at a switch falls back to the level of the variation between switches. Within the displayed 5.1 s window the maximum step change drops from 0.332 to 0.064 for Stand Still and from 0.455 to 0.070 for Raise Arm. Appendix A.9 notes that prediction latency itself differs slightly across these four traces (Stand Still 138.9 ms with RTC and 154.1 ms without, Raise Arm 130.0 and 155.3 ms), with chunk switch intervals of roughly 537 and 552 ms and 529 and 553 ms; the reported values are maxima over these four examples, not averages over repeated trials.
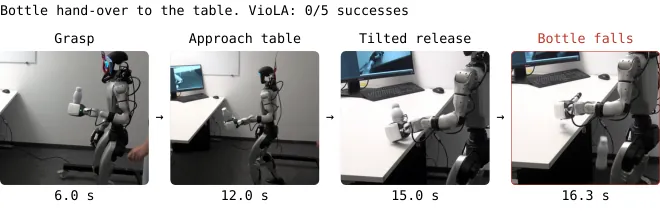
Figure 9: The bottle-carrying task failing at the release stage (paper Figure 10). The robot takes the bottle from a person's hand, walks to the table and opens its hand while the bottle is tilted, after which the bottle falls; timestamps are seconds from the start of the clip. This task scores 0/5 and is reported separately from the seven main manipulation tasks.
Limitations
The authors state three. First, VioLA reuses pretrained body and hand modules, so its ceiling is the set of motions those modules can execute; the hand decoder outputs finger position commands with no contact force feedback, reaching for and then retaining an object remains the hard part of the manipulation trials, and bringing contact feedback into hand control is named as the direction to improve. Second, learning from human recordings requires body and hand motion annotations, so scaling to more video depends on estimating those motions reliably; and under the current schedule human supervision is not uniformly better, since human-then-mixed improves locomotion while robot-only is actually stronger on manipulation, leaving open how to keep the locomotion gains while improving object interaction. Third, the main evaluation uses one Unitree G1, 13 tasks and five trials per task, so broader testing across tasks, environments and embodiments has not been done.
A reviewer's reading adds several more points worth naming. First, the zero-shot claim means the task families appear in training while episodes, environments and object instances are held out; it is not task-level zero-shot, and the conclusions should not be extrapolated into "any new instruction will be followed". Second, once the bottle-carrying task is folded in, manipulation success is 77.5% rather than 88.6%, and every variant including the 200k-step robot-only policy fails that task completely, which suggests the grasp-walk-release-upright chain is a systematic weakness of the approach rather than an accident of one backbone. Third, the continuity evidence for RTC comes from the maximum step change of four recordings, which the authors themselves describe as examples rather than statistics, and the token counts depend on the chosen thresholds: the appendix supplies calibration and sensitivity curves, but a claim like "60 tokens describe one chair rotation" is still threshold-sensitive. Fourth, the contribution of human data is entangled with the schedule, since the main schedule gives human samples an expected 80% of exposure while the robot-only control consumes the full 200k steps of robot data, and the paper does not decompose how much of the manipulation gap comes from the mixture ratio versus the nature of the data. Fifth, code and checkpoints are not yet public and the project page only says coming soon, so reproducibility cannot be verified at present.
Conclusion and Outlook
The decisive move in VioLA is not a new model but a change of output for the generalist policy. Once the action space is "motion latents that frozen controllers can execute", coordination and balance are outsourced to modules that are already trained, and the policy only has to decide which motion to perform and when. Because that same space is open to both human and robot motion, human recordings turn from unusable material into demonstrations that carry their own labels. The 140.6M-frame pool with 93.2% human data, together with the real-robot zero-shot results of 30/30 and 31/35, is the most direct evidence for this route so far, and the fact that a human-only policy still reaches 40% locomotion success turns the question "can human video supervise real-robot behaviour" from a hypothesis into something measurable.
It also leaves the community a clear list of questions: where the reliability ceiling for grasping and holding sits when the hand has no contact feedback; whether the benefit of human supervision can extend from body motion to object interaction; how much of the human data a WAM backbone can still exploit through its video branch; and how transferable the frozen controllers are when this latent action interface is attached to further embodiments. For teams building real humanoids, the actionable conclusion is plain: first train the low-level controller until it executes latent motion reliably, then let the upper policy learn inside that space, and the data bottleneck loosens from "robot demonstrations" to "annotated human motion".
Memorable Line
"The solution to the first obstacle already contains the answer to the second: once a controller can execute latent motion, human movement itself becomes the action label for a robot policy."