Skip to content
← Tags

#Flow Matching (28)

Image GenerationDesign & FrontendTopC

FLUX: the line that moved image generation from "produce a picture" to controllable editing with open weights

Black Forest Labs' FLUX family generates images with a rectified-flow transformer and ships Apache-2.0 dev weights, making it the most important open baseline on the image side; the Kontext tier turned "edit this part of the image on instruction without disturbing the rest" into a usable capability. The collected record also covers the FLUX 3 launch, which the vendor positions as a world model unifying image, video and audio - a claim log as unverified.

Apache-2.0Open-weight tier (dev)Vendor Claim · 2024-08
ProductBlack Forest LabsSiteRepo
FLUX: the line that moved image generation from "produce a picture" to controllable editing with open weights
TacitVLA: Reasoning Vision-Language-Action Models Without Reasoning Latency

TacitVLA: Reasoning Vision-Language-Action Models Without Reasoning Latency

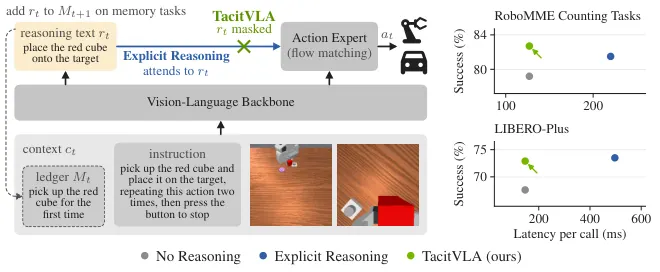
Textual reasoning before acting has improved vision-language-action (VLA) models, but at the cost of latency: every action conditioned on the reasoning text must wait for autoregressive decoding. We show that actions do not need to wait for or condition on the generated reasoning to benefit from it, because the reasoning supervision already improves the backbone representation. We introduce TacitVLA, a reasoning VLA whose action expert never attends to the reasoning it generates for the current call. On long-horizon tasks where the reasoning text also serves as episodic memory, it can generate each entry during action execution rather than before acting. We evaluate it in a controlled study on four benchmarks spanning manipulation and autonomous driving, memory and non-memory tasks: RoboMME, RMBench, LIBERO, and PhysicalAI-AV. On all four, TacitVLA matches the performance of its explicit-reasoning counterpart at up to 3.4x lower latency, and matches the latency of the same architecture trained without reasoning at up to +17.1% success. In absolute terms, it surpasses the best previously published results on the RoboMME Counting suite (82.7% vs. 66.8%) and RMBench (77.5% vs. 56.5%), and reaches 72.9% on LIBERO-Plus and a 52.5% scene score on the public split of the PhysicalAI-AV closed-loop driving challenge. Project page: https://tacitvla.github.io.

Jack Lu, Yurong You, Boyi Li · 58 views · Oct 13, 2026
VLAEmbodied ReasoningManipulationOct 13, 2026
Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models

Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models

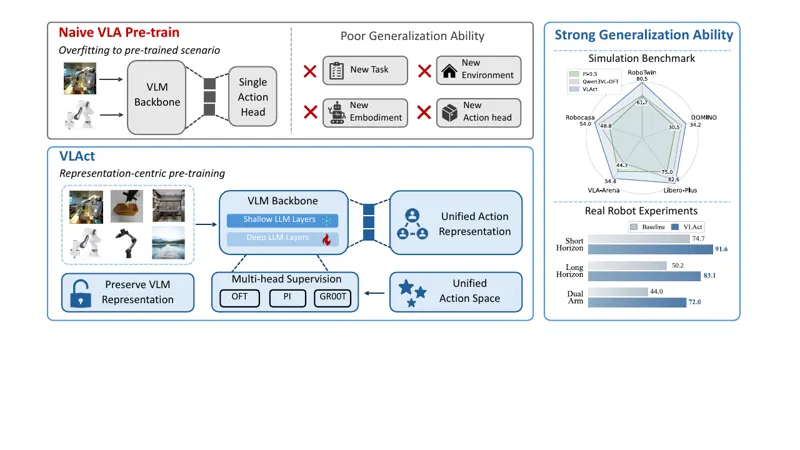
Scaling robot data is crucial for building generalist Vision-Language-Action (VLA) models, yet robot trajectories are harder to scale than web-scale image-text data because embodied collection is costly and sparsely covers the physical world. This makes representation quality a central bottleneck: under a fixed robot-data budget, continued pre-training must turn limited trajectories into transferable visual-action knowledge rather than merely fit actions. We propose VLAct, a VLA-oriented VLM backbone trained on broad, heterogeneous, multi-embodiment robot data before task-specific fine-tuning. VLAct preserves the broad VLM prior and encourages shared action semantics across embodiments through VLM-prior preservation, multi-head continuous action co-supervision, and a partially unified cross-embodiment action layout, while allowing task-specific action heads during fine-tuning. Across simulation, real-world, and unseen-embodiment transfer, VLAct consistently improves downstream performance under fixed fine-tuning protocols. On LIBERO-Plus and RoboTwin 2.0, VLAct surpasses industrial VLA systems including ABot-M0 and LingBot-VLA, achieving success rates of 82.6% and 92.5%. On RoboDojo, VLAct ranks sixth among all policies by success rate and outperforms all explicitly designated world-action model (WAM) entries on both metrics. Most notably, on RoboCasa-GR1, an unseen humanoid embodiment, VLAct using only 20% of downstream trajectories outperforms the full-data GR00T-N1.6 baseline. These results are obtained using fully open-source data and only a 16-GPU training setup, showing that representation-centric continued pre-training can deliver highly competitive performance under a modest compute budget and is an important independent axis of VLA progress beyond data scaling.

Senqiao Yang, Chengyao Wang, Yuxin Chen · 240 views · Aug 27, 2026
VLAContinued Pre-trainingCross-EmbodimentAug 27, 2026
Generate, Track, Improve: Perceptive Multi-Skill Humanoid Locomotion with RL-Fine-Tuned Motion Generators

Generate, Track, Improve: Perceptive Multi-Skill Humanoid Locomotion with RL-Fine-Tuned Motion Generators

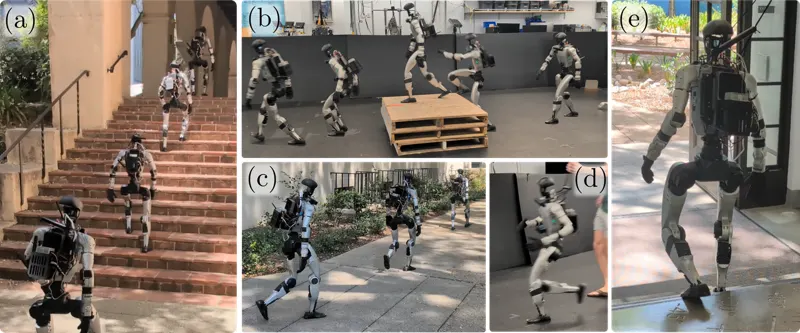
General purpose humanoids require locomotion controllers that are multi-skill, perceptive, dynamic, and robust enough to go anywhere humans can. In this work, we present a two layer locomotion architecture: (1) a perceptive flow matching motion generator plans whole body trajectories from raw depth images while a (2) perceptive tracking policy trained with control-guided RL follows these motions. Both policies are trained on a library of terrain consistent motion clips created with dynamically optimized human data which yields both accurate velocity tracking and terrain consistent references. Our central contribution is a simple yet effective off-policy RL fine tuning loop that improves the motion generator. A structured search method is used with the generator to gather data for advantage weighted regression. This off-policy loop is much more sample efficient than on-policy residual fine tuning and improves terrain consistency on unseen geometries and skill compositions. We find that successful terrain traversals increased by up to 25 percentage points and skill selection improved by up to 80 percentage points. By using raw depth images to perceive the environment no odometry or height maps are needed, and outdoor deployment is easy. With two cameras, the policy can see terrain coming from further away and adjust its velocity regardless of the commanded speed so it can traverse the terrain. A single policy pair enables a Unitree G1 humanoid to walk, run, stand, jump on and off of boxes, and traverse stairs in outdoor environments. Project page: https://zolkin1.github.io/generate-track-improve/

Zachary Olkin, William D. Compton, Aaron D. Ames · 661 views · Sep 25, 2026
Humanoid LocomotionPerceptive LocomotionReinforcement LearningSep 25, 2026
MachEmbodied-U0: Unified Understanding and Generation Model for Embodied Intelligence

MachEmbodied-U0: Unified Understanding and Generation Model for Embodied Intelligence

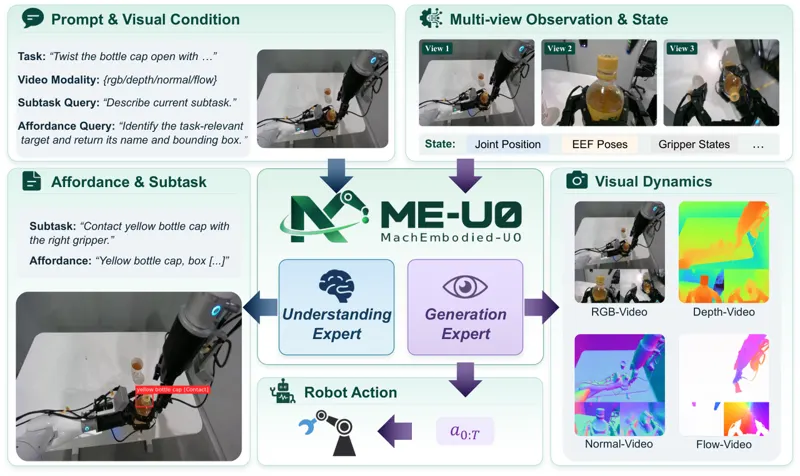
General-purpose robot control requires models to understand task intent, identify where to interact, capture how the scene evolves, and generate precise actions. Vision-language-action models provide strong semantic priors but typically do not explicitly model scene dynamics, while world-action models couple visual prediction with control without necessarily exposing the task-relevant semantic and spatial structure needed for fine-grained manipulation. We present MachEmbodied-U0 (ME-U0), a unified embodied foundation model connecting understanding and generation experts through a Mixture-of-Transformers architecture. Subtask prediction and affordance grounding guide joint visual-dynamics and action generation via flow matching. Visual dynamics encompass future RGB, depth, surface normals, and optical flow, providing complementary supervision for appearance, geometry, and motion. Multi-rate Rotary Position Encoding (MRPE) aligns visual dynamics with fine-grained control. We pretrain ME-U0 on approximately 4,200 hours of curated demonstrations from robotic datasets and egocentric datasets. Using only the supervision natively available in each downstream benchmark, ME-U0 achieves an average score of 17.66 on the RoboDojo simulation benchmark and average success rates of 99.0% and 82.5% on LIBERO and LIBERO-Plus, respectively. We additionally validate ME-U0 on real-world robotic manipulation tasks, demonstrating its effectiveness beyond simulation. Without corresponding downstream supervision, ME-U0 further demonstrates zero-shot subtask prediction, affordance grounding, and visual dynamics on simulated and real-world observations. Overall, ME-U0 combines competitive downstream control performance with transferable task-grounding and visual-dynamics capabilities across simulation and the real world.

Wen, Haoran, Wang, Wenfu, Shi, Kunsong · 913 views · Sep 22, 2026
MachEmbodiedME-U0VLASep 22, 2026
Memory as Plans: World-Action Modeling with Memory-Grounded Planning

Memory as Plans: World-Action Modeling with Memory-Grounded Planning

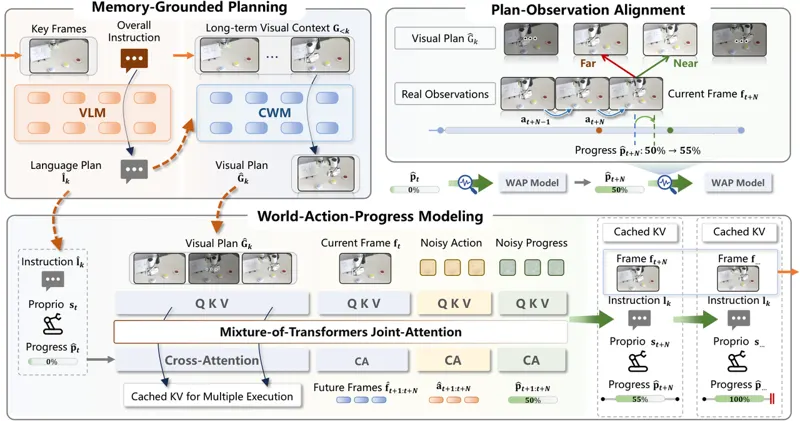
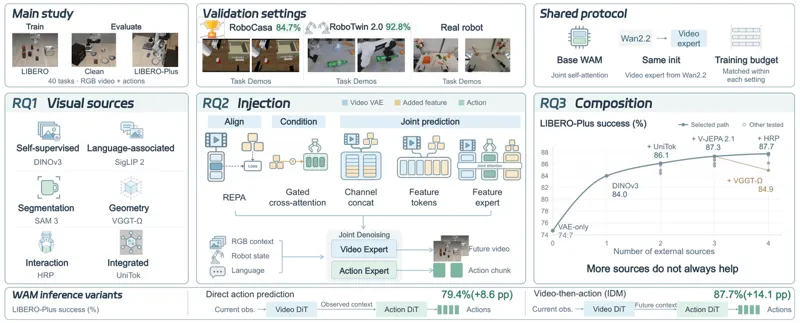
Most robot policies predict actions from the current observation or a short fixed window, yet long-horizon manipulation is non-Markovian: the evidence a decision needs may already be out of view. MaP-WAM treats memory as planning-time evidence instead of executor input. Completed segments are stored as structured multimodal records pairing a language instruction with sparse visual context (8 uniformly sampled frames per segment); a fine-tuned Qwen3.5-4B language planner proposes the next segment-level language plan, and a causal world model initialized from WAN-2.2-5B turns the long-term visual context into a matching visual plan. The two form a memory-grounded plan that conditions a World-Action-Progress executor, a Mixture-of-Transformers extension of a video DiT that jointly predicts action chunks, future visual latents, and execution progress, with progress as a first-class modality. Because the executor only sees a fixed-length plan prefix, its context stays constant as history grows, and block-causal attention makes both planning and execution KV-cacheable; plan-observation alignment calibrates recursively predicted progress against visual-plan frames, and a progress gate (threshold 0.95) triggers segment transitions that write resampled real observations back into memory. On RMBench MaP-WAM reaches 83.3% average success over nine memory-dependent tasks (best baseline LingBot-VA 77.1%), and 78.0% on two real Franka Research 3 tasks (88% Find Button, 68% Press Buttons), while a full-context executor runs out of memory at 1700 history frames and WAP holds an approximately constant 827 ms per action chunk. Limitations: segment structure is taken from benchmark annotations rather than discovered automatically, and plan-observation alignment uses a lightweight training-free pixel-difference metric.

Sizhe Zhao, Haozhe Xie, Weiyu Zhao · 718 views · Sep 10, 2026
World-action modelsLong-Horizon MemoryMemory-Grounded PlanningSep 10, 2026
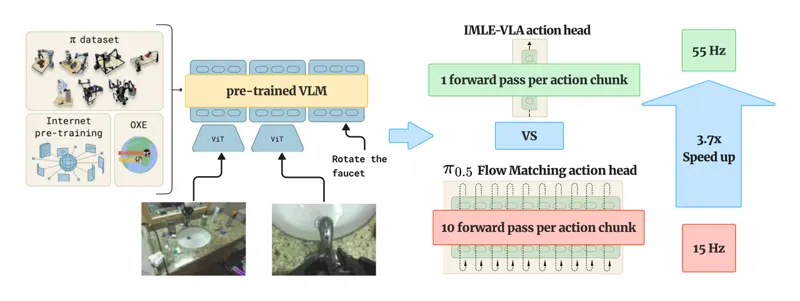
IMLE-VLA: Fast Single-Step Action Generation for Vision-Language-Action Policies

IMLE-VLA: Fast Single-Step Action Generation for Vision-Language-Action Policies

Vision-language-action (VLA) policies leverage pretrained vision-language backbones to achieve strong cross-task generalization. A leading design couples this backbone with a dedicated continuous action head trained via diffusion or flow matching. However, such heads rely on iterative multi-step sampling, for example 10 Euler steps in π_0.5. This creates an inference bottleneck that produces stop-and-go movement in the robot and slower task completion. We introduce IMLE-VLA, which replaces the iterative action head with a single-step conditional generator trained via conditional Implicit Maximum Likelihood Estimation (cIMLE). The cIMLE objective promotes multimodal action coverage, avoiding the mode collapse of naive regression heads while eliminating multi-step sampling entirely. When IMLE-VLA is applied to π_0.5, it increases inference frequency 3.67x (55 Hz vs. 15 Hz), enabling up to 11x higher action throughput. On the 40-task LIBERO benchmark, IMLE-VLA achieves the highest average success rate (98.0%) among all baselines while leading in inference frequency. Under the test-time perturbations of LIBERO-plus, IMLE-VLA retains π_0.5's robustness while other baselines degrade sharply, confirming that the cIMLE head preserves generalization. Real-world experiments on a Franka Emika Panda across four tasks demonstrate smoother motion (2.2x to 3.0x lower jerk) and faster task completion, with IMLE-VLA outperforming π_0.5 on every task and reducing average VLA inference time per episode by 3.9x to 6.6x. Videos and code are available at https://kianhk6.github.io/IMLE-VLA/

Hosseinkhani, Kian, Peng, Qinhe, Shramko, George · 906 views · Sep 10, 2026
VLAEfficient InferenceSingle-Step Action GenerationSep 10, 2026
A4A: Cross-Embodiment Transfer of Action-Oriented 4D Affordances from Human Demonstrations

A4A: Cross-Embodiment Transfer of Action-Oriented 4D Affordances from Human Demonstrations

Human demonstrations contain rich manipulation knowledge, but it remains unclear what information can be transferred effectively to robot control. Existing affordance representations are typically formulated as 2D masks, 3D regions, contact points, or actionability scores, and therefore primarily identify where interaction may occur. However, effective manipulation also requires modeling how interaction-relevant geometry evolves during task execution. To bridge this gap, we introduce action-oriented 4D affordances, which represent the language-conditioned future trajectories of interaction-relevant 3D points. These trajectories capture task-conditioned geometric evolution rather than embodiment-specific actions, enabling transferable interaction priors across humans and robots. Based on this representation, we construct a large-scale action-oriented 4D affordance dataset from existing human–object interaction video data and complementary RGB-D demonstrations, and introduce A4A, an affordance-to-action framework that uses 4D affordance trajectory prediction to pretrain robot policies before manipulation fine-tuning. Experiments in both simulation and the real world validate the effectiveness of A4A, showing that pretraining with action-oriented 4D affordance data consistently improves the manipulation performance of diverse VLA policies. These results establish action-oriented 4D affordances as an effective cross-embodiment representation for transferring manipulation knowledge from human demonstrations to robot control.

Yifan Han, Litao Liu, Yuqi Gu · 796 views · Sep 5, 2026
VLAAffordance4D AffordanceSep 5, 2026
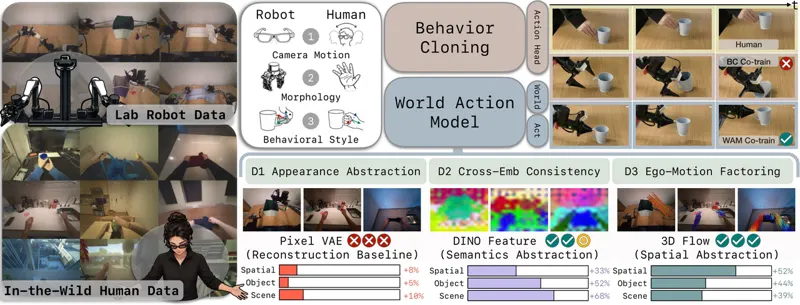
EgoWAM: World Action Models Beyond Pixels with In-the-Wild Egocentric Human Data

EgoWAM: World Action Models Beyond Pixels with In-the-Wild Egocentric Human Data

Egocentric human data offers scalable supervision for robot manipulation. However, behavior cloning entangles transferable content like objects, scenes, and task semantics, with non-transferable factors like human morphology, head motion, and behavioral style. We study whether World Action Models (WAMs) provide a better training signal by requiring policies to predict not only actions, but also how the scene evolves. The central question is what world representation best enables human-to-robot transfer. We hypothesize that an effective world target should abstract appearance, capture agent-invariant physical effects, and separate camera motion from environment change. We introduce EgoWAM, a controlled human-robot co-training framework that fixes the policy backbone, action head, and data mixture while varying only the world prediction target, comparing Pixel, DINO, and 3D motion flow. Across three real-world bimanual tasks, WAM co-training scales more effectively with in-the-wild egocentric human data than behavior cloning. Pixel-based prediction transfers weakly, while DINO and 3D flow yield substantial gains: DINO improves out-of-distribution object and scene generalization by up to 4x, and 3D flow improves in-domain performance by 20-30%. More details: https://gatech-rl2.github.io/egowam.github.io

Baoyu Li, Xinchen Yin, Mengying Lin · 789 views · Jul 8, 2026
World ModelsRobot ManipulationImitation LearningJul 8, 2026
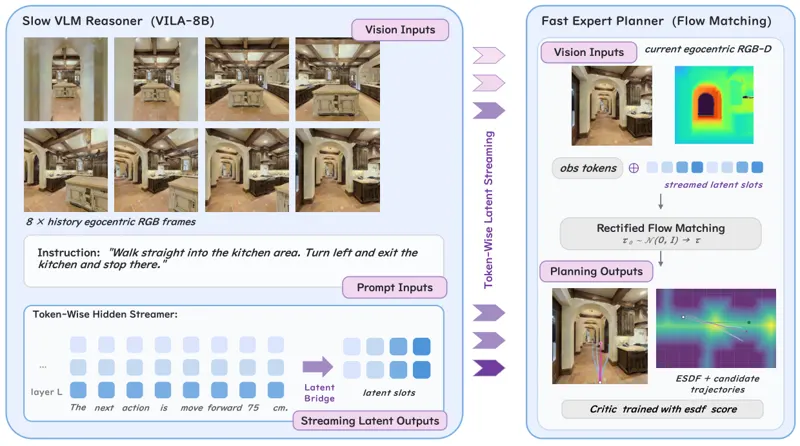
Token-Wise Latent Streaming from Slow Reasoners to Fast Planners for Dynamic Vision Language Navigation

Token-Wise Latent Streaming from Slow Reasoners to Fast Planners for Dynamic Vision Language Navigation

Vision-Language Navigation in dynamic, human-centric environments exposes a fundamental tension: linguistic reasoning is slow and deliberative, whereas safe, socially compliant planning should be instant and reactive. The resulting observation staleness is safety-critical: a maneuver chosen during inference can already be unsafe by the time it executes. We observe that, long before a VLM finishes its inference, its intermediate hidden states already encode action-relevant intent. We propose SPARK-VLN, a dual-system framework for dynamic social VLN that streams the slow VLM reasoner's knowledge to a fast flow-matching expert planner throughout token generation, providing fresh and evolving guidance during inference. This design is realized by three modules: a Token-Wise Hidden Streamer that extracts intermediate hidden states along the token generation process, a Sequence-to-Slot Latent Bridge that projects them into fixed-size latent slots, and an Evolving Latent Conditioner that infuses them into the expert planner. We also introduce a human-centric benchmark suite for dynamic social vision-language navigation that keeps pedestrians and the robot active throughout inference and reports navigation success, social compliance, human collisions, and explicit staleness statistics. Across these settings, SPARK-VLN mproves navigation success and social compliance while sustaining inference efficiency. Webpage: https://hutslib.github.io/SPARK-VLN/.

Tianshuai Hu, Yangyi Zhong, Zeying Gong · 608 views · Jul 18, 2026
Vision-language navigationSocial NavigationDual-SystemJul 18, 2026
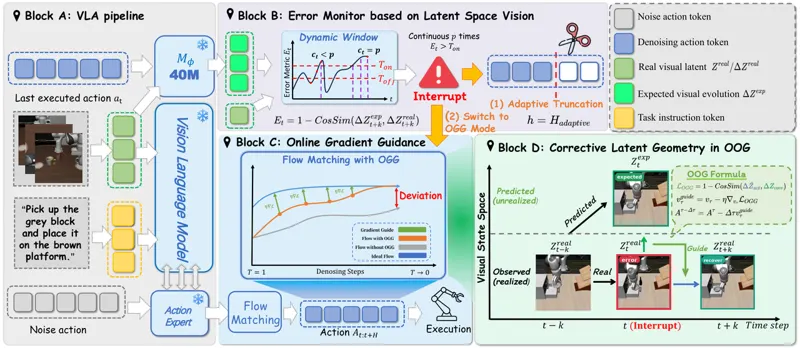
VLA-Corrector: Lightweight Detect-and-Correct Inference for Adaptive Action Horizon

VLA-Corrector: Lightweight Detect-and-Correct Inference for Adaptive Action Horizon

Vision-Language-Action (VLA) foundation models have recently achieved strong progress in embodied intelligence. To reduce policy-call frequency while preserving temporal coherence, most generative policies adopt an action chunk mechanism, executing multiple future actions in an open-loop manner under a fixed action horizon. However, this "predict-then-blindly-execute" paradigm sacrifices closed-loop reactivity: in contact-rich physical interactions, even small local perturbations can rapidly amplify within the open-loop blind spot, leading to compounding errors and ultimately task failure. To address this limitation, we propose VLA-Corrector, a lightweight corrective inference framework for action-chunked VLA policies. Without modifying the backbone policy weights, VLA-Corrector introduces a lightweight Latent-space Vision Monitor (LVM) that continuously compares predicted and actual visual feature evolution, enabling online detection of visual dynamics deviations. Once persistent deviation is detected, the system triggers a truncation event, discards the remaining stale actions, and invokes corrective replanning via Online Gradient Guidance (OGG). The detect-and-correct mechanism of VLA-Corrector naturally induces an event-triggered adaptive action horizon: it preserves long-horizon execution when the current chunk remains reliable, and invokes short-horizon corrective replanning when execution begins to drift. In doing so, VLA-Corrector mitigates the trade-off imposed by static horizons between execution robustness and policy-call frequency. It can be integrated into different VLA models without further retraining the VLA backbone, interrupting compounding errors while preserving much of the efficiency benefit of action chunking and substantially improving robustness in long-horizon, contact-rich robotic manipulation tasks.

Yi Pan, Miao Pan, Qi Lu · 580 views · Jul 2, 2026
VLARobotic ManipulationAction chunkingJul 2, 2026
FlashVLA: Streaming Action Decoding for Fast and Asynchronous VLA Inference

FlashVLA: Streaming Action Decoding for Fast and Asynchronous VLA Inference

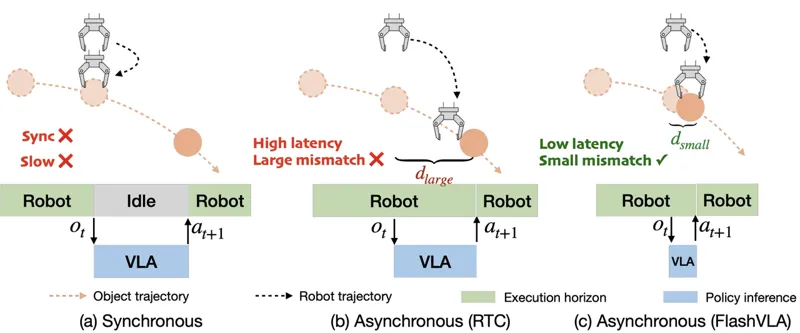
Vision-Language-Action (VLA) models are increasingly promising for robotic manipulation, yet their real-world deployment remains bottlenecked by high inference latency and unstable asynchronous execution. This challenge is particularly pronounced in flow-matching-based VLA models, where action decoding requires multiple iterative steps conditioned on the VLM context. While efficient inference methods improve control frequency and asynchronous methods reduce execution idle time, existing approaches often fail to jointly achieve low-latency inference and accurate, temporally consistent asynchronous execution. We introduce FlashVLA, a streaming action decoding framework that addresses both challenges in a unified formulation. FlashVLA maintains a streaming action buffer with multiple chunks at different noise levels and decodes them using chunk-wise causal attention. This design allows FlashVLA to produce one executable action chunk per inference step. Moreover, its chunk-wise autoregressive formulation implicitly preserves action continuity, enabling smooth asynchronous execution without extra future-state conditioning. Across extensive simulated and real-world experiments, FlashVLA substantially improves inference speed while maintaining strong task performance. It can achieve ≥30 Hz control frequency on a single GPU with smooth asynchronous inference in real-world deployment.

Zekai Li, Jiaming Tang, Zhijian Liu · 639 views · Aug 27, 2026
VLAFlow MatchingNVIDIAAug 27, 2026
GigaBrain-0.7: Scaling Embodied Foundation Models to Emergent Capabilities with a Three-System Architecture

GigaBrain-0.7: Scaling Embodied Foundation Models to Emergent Capabilities with a Three-System Architecture

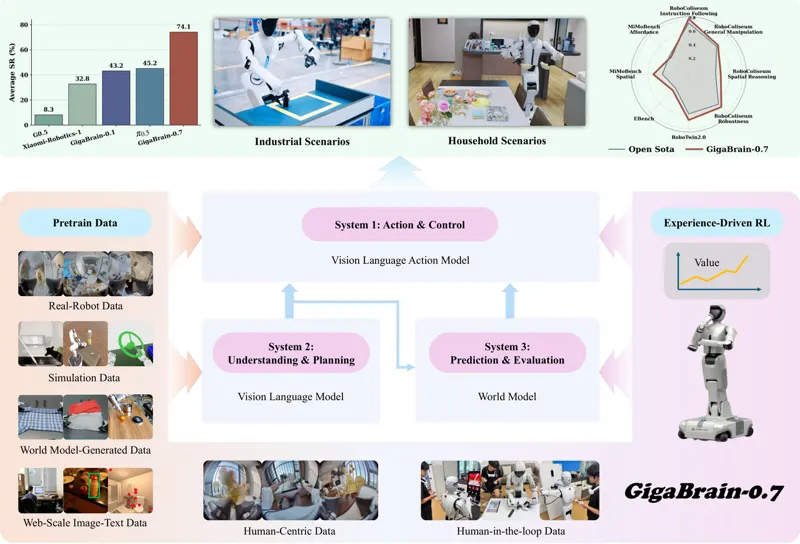
Vision-language-action (VLA) models have become a dominant paradigm for generalist embodied agents, demonstrating strong complex and long-horizon task completion in structured settings. Yet it remains an open question whether current VLA systems can benefit from more effective architectural design, scale to substantially larger and more heterogeneous data regimes, and achieve broader generalization across tasks and embodiments. To this end, we present GigaBrain-0.7, an embodied foundation model with substantially improved generalization across diverse robot embodiments. Specifically, GigaBrain-0.7 unifies understanding, prediction, and action through a three-system architecture, scales pretraining to over 37,000 hours of heterogeneous embodied data, and introduces one-stage alignment training that jointly optimizes vision-language understanding and multi-embodiment action generation. Compared with the preceding GigaBrain-0 series and prior state-of-the-art models including π_0.5, GigaBrain-0.7 achieves substantial improvements in foundation zero-shot capabilities, language-conditioned instruction following, and post-training task success rates. In particular, on our in-house Maker H01 platform and mainstream robot embodiments, GigaBrain-0.7 demonstrates strong task adaptability and completion ability across both home and industrial scenarios. All training code and pretrained model weights will be released.

GigaBrain Team, Angen Ye, Axiang Sun · 676 views · Aug 16, 2026
VLAGigaBrainFlow MatchingAug 16, 2026
HAF: Adapting Generalist VLAs to Humanoid Whole-Body Loco-manipulation via Hierarchical Action Flow and Spectral Latent RL

HAF: Adapting Generalist VLAs to Humanoid Whole-Body Loco-manipulation via Hierarchical Action Flow and Spectral Latent RL

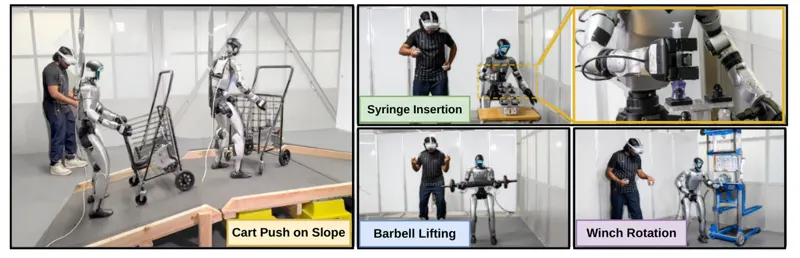
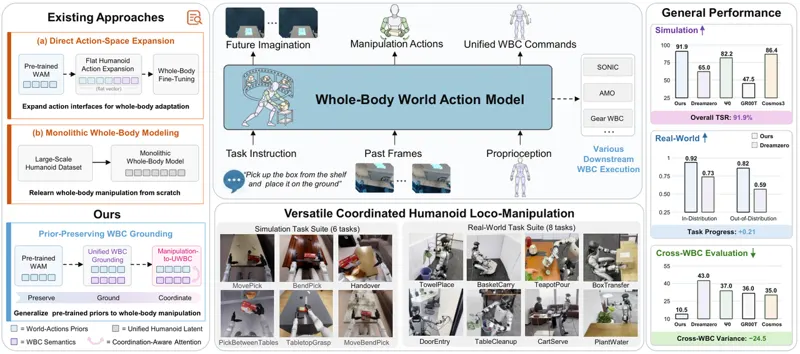
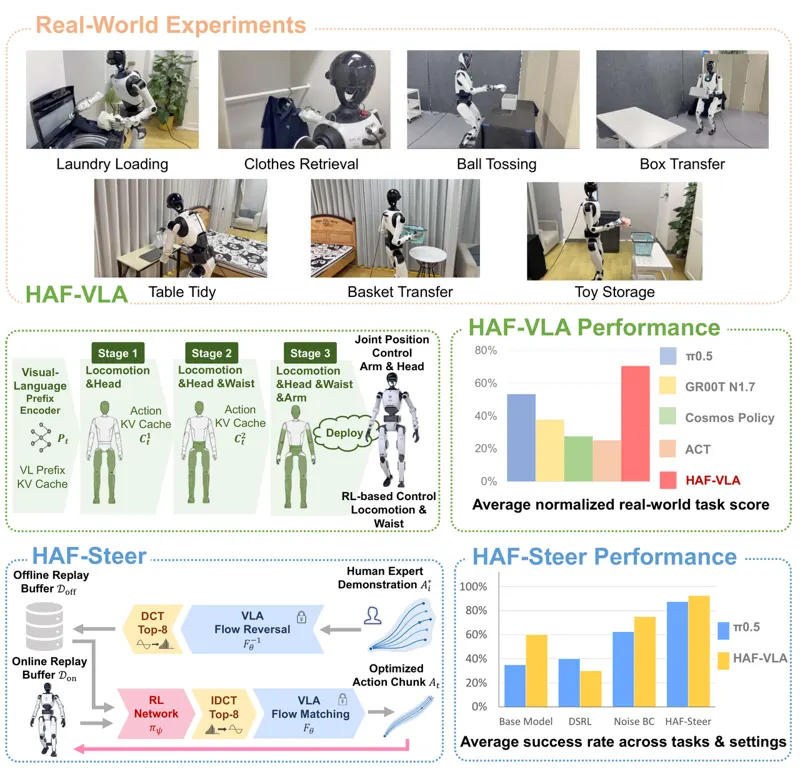
Humanoid robots hold great promise as general-purpose agents in human-centered environments, yet generalist vision-language-action (VLA) foundation models are not readily applicable to humanoid whole-body loco-manipulation. The high dimensionality and interdependence of humanoid motions make it challenging for conventional single-stage VLA architectures to coordinate locomotion, waist posture, and dual-arm manipulation effectively. Moreover, policies trained through offline behavior cloning can remain suboptimal during real-world deployment. Although online reinforcement learning can refine policies through real-world interaction, directly tuning large VLA backbones demands excessive computation and may introduce safety risks during real-robot exploration. To address these bottlenecks, we introduce HAF (Humanoid Adaptation Framework), a two-part framework consisting of HAF-VLA and HAF-Steer that transfers off-the-shelf generalist VLA foundation models to humanoid whole-body loco-manipulation. HAF-VLA is a hierarchical action-flow generator built on a pretrained flow-matching VLA. It splits full-body action denoising into three sequential stages with stage embeddings and cross-stage KV caches that retain kinematic dependencies, avoiding incoherent whole-body actions from one-shot generation. On top of the frozen HAF-VLA, HAF-Steer is a latent offline-to-online RL pipeline that leverages flow-matching invertibility and DCT-based dimensionality reduction to restrict RL optimization to a compact noise subspace and train a regularized SAC policy. This avoids updating the large VLA backbone and enables efficient real-world policy refinement. Evaluated on seven real-world humanoid loco-manipulation tasks, HAF surpasses vanilla single-stage VLA baselines and improves whole-body coordination and task performance. Project website: https://grange007.github.io/HAF .

Langzhe Gu, Chengkai Hou, Meng Li · 538 views · Aug 17, 2026
VLAHumanoidWhole-bodyAug 17, 2026

As an Amazon Associate, we earn from qualifying purchases.