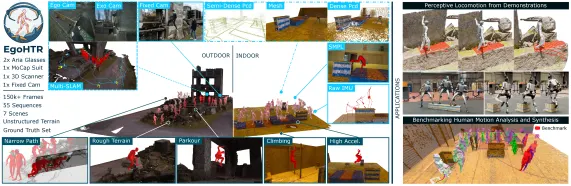
Deploying humanoid robots in unstructured terrain remains an open problem. While classic reinforcement learning struggles with the sheer complexity of real-world interactions, more promising methods leveraging human priors remain limited to models lacking contextual awareness. The restricted motion synthesis is a direct consequence of existing dataset pipelines failing to capture human-scene sequences in challenging environments. To bridge this gap between humanoid learning and scene reconstruction, we introduce the Egocentric Human-Terrain Reconstruction (EgoHTR) dataset. We develop and open-source a reconstruction pipeline capturing 55 scene-aligned 4D human motion sequences in diverse, complex environments using a multi-sensor setup of egocentric wearables and a portable 3D scanner. The resulting dataset comprises over 150k frames, which we evaluate against motion-capture ground truth, demonstrating state-of-the-art accuracy and establishing a rigorous benchmark for human motion analysis and synthesis. Further, we leverage this data to train perceptive locomotion policies, demonstrating hardware deployment on a Unitree G1 for reconstructed reference motions. Our pipeline enables community-driven dataset extensions and factors the problem to help researchers build foundational, context-aware robots that reliably traverse uneven terrain.
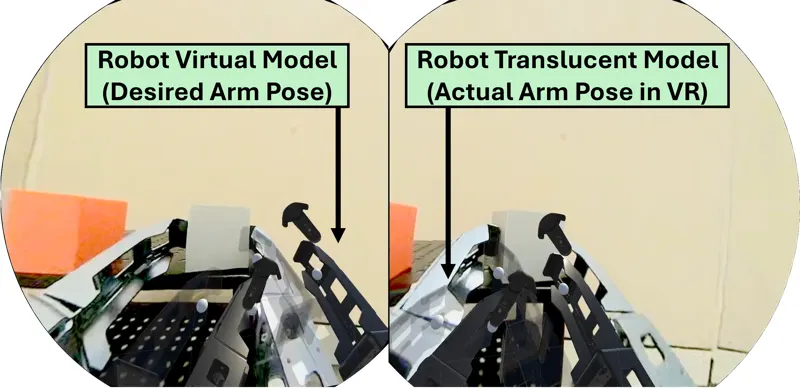
Full-sized humanoid robot capabilities have grown exponentially in recent years, aiming towards general-purpose deployment in human environments. A popular control method used by manufacturers utilizes Virtual Reality for upper-body teleoperation and Reinforcement Learning for lower-body balance and locomotion control. As a result, a single remote operator can see, manipulate, and navigate about a real, distant physical environment. This powerful control stack is often relegated to expensive full-sized robots, many of which are inaccessible to the research community. Miniature humanoids are more prevalent, but employ less biomimicry in their design (e.g. fewer sensors, Degrees of Freedom, etc) and lack similar developments. This paper describes a compliant full-body telepresence control stack developed from the ground up for miniature humanoids. Framework experimentation on ROBOTIS OP3 hardware showcases walking at speeds up to 0.45 m/s independent of arm motions. Tele-loco-manipulation is demonstrated via a cube relocation experiment with an expert human operator. On average, the teleoperated system moved 2 different 40 g cubes within 10 mins, walking a total distance of 5 m. Overall, the developed system shows potential for miniature humanoid tele-loco-manipulation.
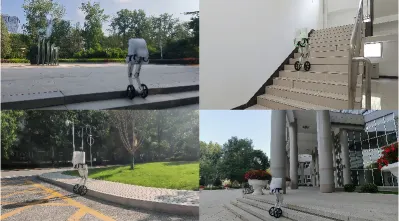
Recent advances in control have enabled bipedal-wheeled robots to traverse slopes and single-step obstacles, yet long staircase traversal remains challenging as current teacher-student frameworks suffer from weakened dynamics-aware representations and incomplete terrain geometry encoding. To bridge this gap, we propose DynaWM, a dynamics-aware representation learning framework. To enhance terrain encoding capability and enable transparent assessment, we introduce a world model as a regularizer to enforce forward-dynamics awareness, preserving comprehensive terrain geometry while facilitating hierarchical encoding visualization. To stabilize knowledge transfer, we employ a momentum target encoder to provide consistent distillation targets, preventing dimensional collapse from non-stationary teacher updates. Evaluation of the learned representations through Principal Component Analysis (PCA) visualization and quantitative metrics reveals that our encoder hierarchically captures terrain geometry with higher terrain encoding capability, leading to enhanced terrain adaptability and motion smoothness. Experimental results in simulation and real hardware demonstrate that our method achieves superior terrain adaptability and motion smoothness, enabling bipedal-wheeled robots to overcome diverse continuous stairs, as shown in Fig. 1.
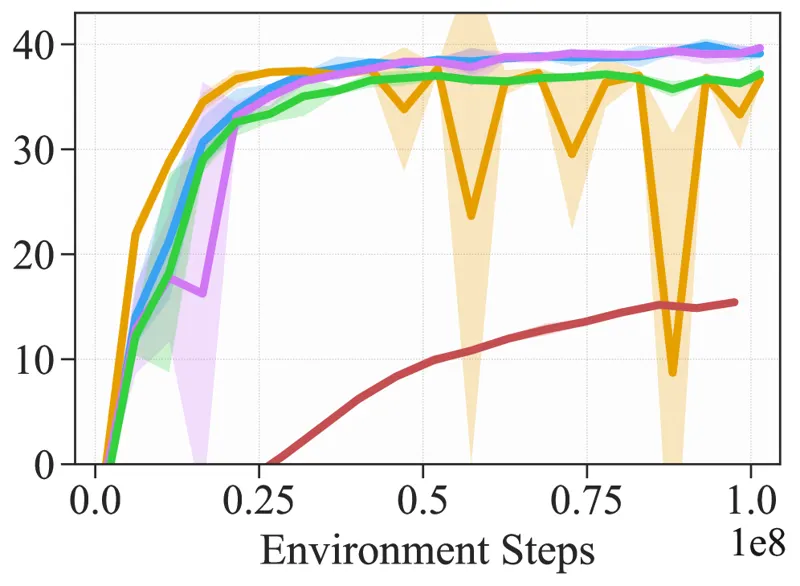
Scalable reinforcement learning has popularized high-throughput sampling architectures, which significantly compresses the training time for off-policy methods in robotic locomotion. However, the rapid increase of data volume and update frequency undermines the stability of value-based methods and diminishes the plasticity of policy networks. To address these challenges, this work presents FastDSAC, a fast and high-performance variant of the Distributional Actor-Critic algorithm designed for parallel sampling scenarios. Specifically, we introduce a truncated Gaussian distribution to approximate the learned policy, which effectively excludes out-of-distribution actions that strain target value estimation while keeping necessary stochasticity for exploration. The proposed action constraint functions as an implicit regularization, which counteracts the plasticity loss typically caused by aggressive gradient updates. This preservation of network adaptability enhances sample efficiency, particularly in scenarios with a high update-to-data ratio, and accelerates the early training process. In contrast to prior fast reinforcement learning approaches that rely on discrete value distributions, our method utilizes a continuous Gaussian representation equipped with adaptive variance regulation, which improves value estimation accuracy by sampling confident and informative transitions. Extensive experiments on MuJoCo Playground and HumanoidBench demonstrate that FastDSAC not only stabilizes the overall training process but also achieves superior asymptotic performance and faster convergence compared to state-of-the-art baselines.
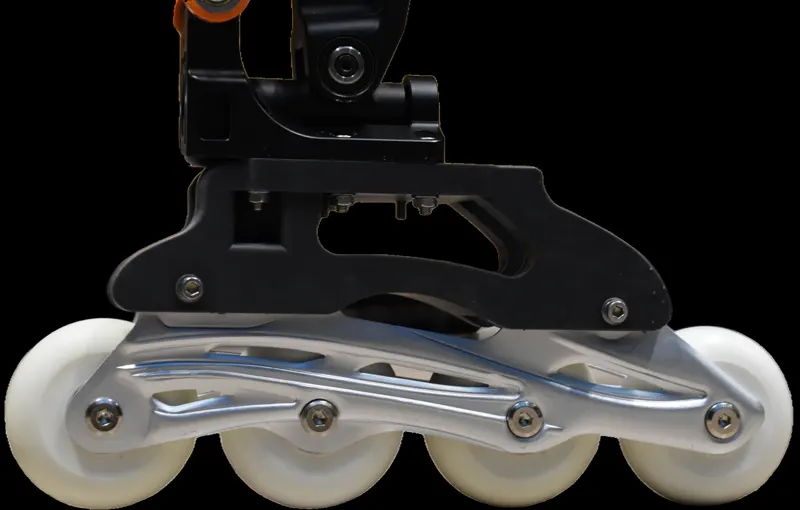
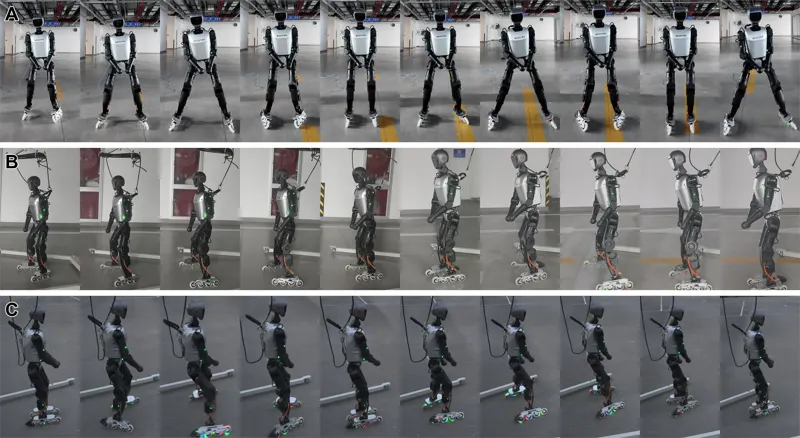
As humanoid robots become increasingly dynamic, coupling them with reinforcement learning offers a promising approach to solving the complex, underactuated mechanics of passive inline skating. Equipping a humanoid robot with passive inline skating wheels presents an opportunity to combine the versatile agility of humanoids with the high-speed, energy-efficient locomotion strategies utilized by human skaters. In this paper, we train and deploy a reinforcement learning control policy that enables novel locomotion strategies for a humanoid robot modified to equip consumer inline skates instead of conventional feet. Unlike previous work limited to quadrupedal robots or actively driven wheels, our system allows for precise 6-DoF control of the skates to execute dynamic, edge-driven propulsion strategies. Our skating strategies emerge entirely from our reward structure, without reliance on human motion data, imitation learning, or kinematic priors. We overcome the inherent instability of passive wheels and simulation contact artifacts by utilizing different geometric wheel models (spherical and ellipsoidal) during training and validation, along with a custom success-based command curriculum and a specialized rolling reward. Consequently, our policy demonstrates up to a 50% reduction in Cost of Transport (CoT) compared to standard walking gaits. The resulting policy successfully transfers zero-shot to the physical Booster T1 hardware. Real-world deployments demonstrate dynamic balance, the ability to reject active physical perturbations, and agile locomotion strategies capable of turning at speed. A video of our results can be found at https://www.youtube.com/watch?v=-_APcOS7uFo.
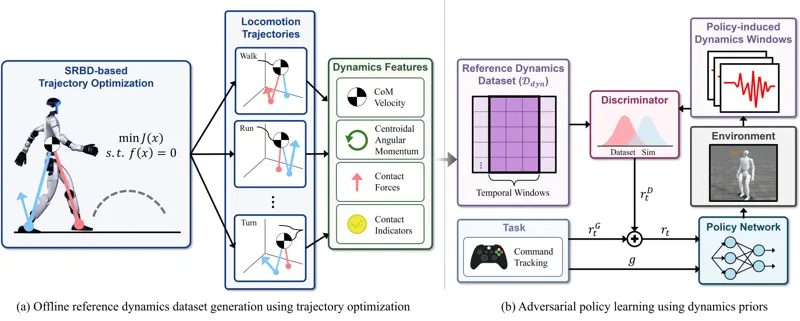
In this paper, we propose Adversarial Dynamics Priors (ADP) for perturbation-resilient humanoid locomotion control. Existing motion prior-based methods induce natural motion styles by imitating kinematic motion features, but they do not directly regularize dynamics features, such as CoM motion, centroidal momentum, contact forces, and contact states. To address this limitation, we replace kinematic motion-style feature with selected dynamics features extracted from locomotion trajectories as the target of adversarial regularization. To this end, we use trajectory optimization to construct a reference dataset and train a discriminator to evaluate whether policy-induced temporal windows are consistent with the resulting reference distribution. Without explicit motion tracking, ADP encourages policy rollouts to remain close to the reference support, even after perturbations. Experimental results show that, compared with AMP, the strongest baseline in our evaluation, ADP improves the 80%-success impulse threshold (J_80) by 16.7%, while reducing direction-averaged recovery time and velocity tracking error by 47.9% and 35.4%, respectively.
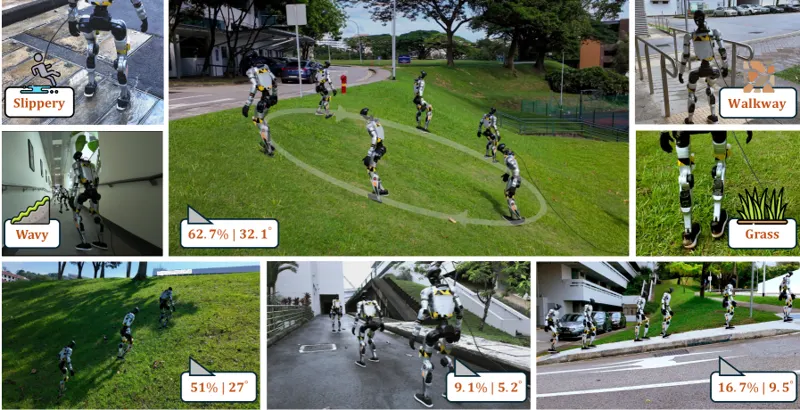
Model-free reinforcement learning has enabled impressive humanoid locomotion; however, control on steep slopes remains largely unexplored. Unlike flat or discrete terrains, sloped terrains impose a persistent gravitational bias that demands simultaneous stability and posture control. Consequently, under generic reward formulations, policies can converge to slow, conservative low-center-of-mass (CoM) crouched gaits. In this work, we propose a novel two-stage physics-guided framework, dubbed HumoSlope, dedicated to robust humanoid locomotion on diverse sloped terrains. Specifically, Stage I establishes a terrain-consistent balance prior by introducing a slope-adaptive Zero Moment Point (ZMP) regularizer evaluated directly on the local inclined support plane rather than a world-horizontal reference. To prevent the resulting policy from defaulting to a crouched posture, Stage II introduces the Biomechanical Slope Gait Adapter (BSGA). Utilizing extracted macroscopic terrain descriptors as privileged, training-only signals, BSGA dynamically gates soft reward priors to modulate CoM height and lower-limb coordination based on the estimated slope geometry – encouraging hip-dominant uphill propulsion and knee-oriented downhill braking. Crucially, the deployed actor remains entirely proprioceptive, requiring no online exteroceptive sensing. Extensive Sim-to-Real experiments demonstrate that our framework effectively mitigates posture degeneration and enables blind, continuous traversal of outdoor grass slopes up to 62.7% (32.1^∘), validating a physics-guided approach to challenging slope terrain adaptation.
Humanoid roller-skating is difficult because the robot must coordinate whole-body balance, rolling contacts, and velocity-dependent posture regulation. This paper presents an adversarial motion prior based reinforcement learning framework for two humanoid roller-skating gaits: Pump Glide skating and Push Glide skating. The two gait datasets are collected independently through motion capture and retargeted to the humanoid robot separately. The retargeted data are then smoothed and resampled into reference motion states for AMP training. The two gaits are learned by independent AMP training pipelines with separate reference datasets, separate policies, and independent reward architectures. Simulation experiments are designed to evaluate gait quality, velocity tracking, turning, and gait-specific reward ablations.
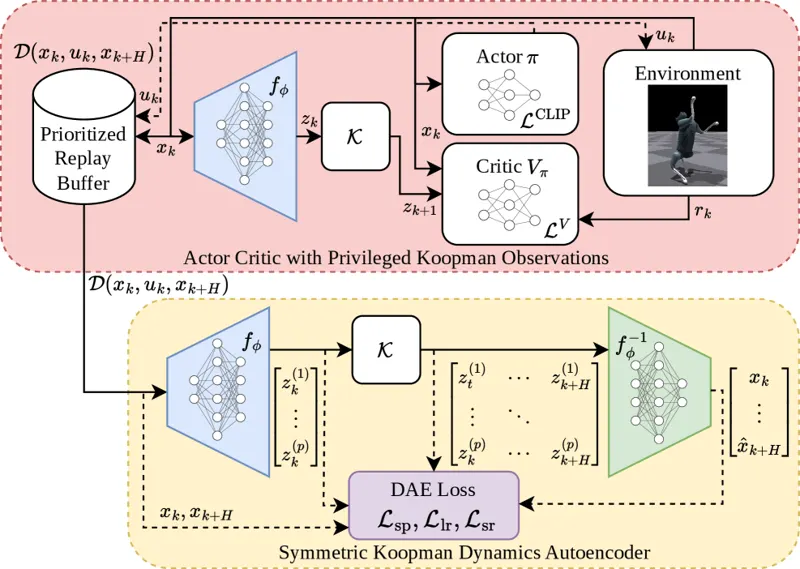
Reinforcement learning (RL) algorithms classically suffer from poor sample efficiency. In robotics, a recent line of work has emerged addressing this problem by encoding physics priors in the learning process. However, most of these approaches are validated on well-defined, low-dimensional benchmark systems rather than high-dimensional robots with complex nonlinear dynamics. In this paper, we introduce SKooP (Symmetric Koopman Predictions), an approach combining the advantages of morphological symmetries with those of a Koopman model learned via autoencoder to enhance policy learning. SKooP learns a Koopman model of the system dynamics alongside the policy. The resulting Koopman predictions are used as privileged observations for the critic, allowing the agent to learn based on smoother, more informative features. We also incorporate group symmetries into the actor, critic, encoder and decoder networks to produce a highly equivariant policy. The SKooP approach is validated via in-depth analysis of the learned Koopman models and symmetric policies to showcase how each of these influences the agent's performance. We also show that the learned policies are transferable to different simulation environments. Our results show that SKooP consistently reduces convergence time and increases the learned reward for multiple challenging bipedal locomotion tasks on a quadruped robot. Project page: https://evelyd.github.io/SymmetricKoopmanPredictions
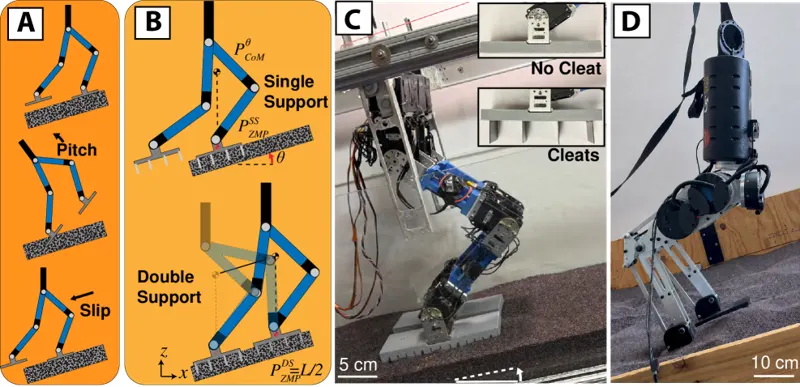
Bipedal robots are challenging to control because they operate close to instability, where small variations in foot-terrain contact can rapidly destabilize locomotion. On rigid terrain, bipedal robots mitigate this fragility by using well-established contact mechanics and control strategies. On flowable surfaces such as granular slopes, foot contact can induce large surface deformations and solid-fluid-like transitions, coupling terrain effects with robot dynamics, leading to underperformance or failure. This is partly due to the lack of reliable methods to represent the dynamics of flowable terrain, making it difficult to account for terrain effects in locomotion design. Here, we investigate how controlling terrain response can improve bipedal locomotion on granular slopes by studying the terradynamics of cleated feet, thin plates emanating from the foot soles. Systematic studies of a small-scale (1.4 kg) robophysical biped reveal that cleats with sparse and dense spacing lead to excessive terrain yielding and resistance, respectively, degrading performance and leading to failure. An intermediate cleat spacing distributes interaction forces to maintain substrate stresses near (or below) the yield threshold, enabling walking on granular slopes up to 30 degrees. Guided by these principles, we design a foot that actively adjusts cleat depth and accommodates both rigid and granular terrain. We also demonstrate that the principles of effective foot-terrain interaction translate to a larger (15 kg) autonomous biped. Our study presents an alternative to conventional body-centric robot control approaches, which regulate terrain-induced effects through body motion, by instead regulating terrain interactions through limb-centric approach.
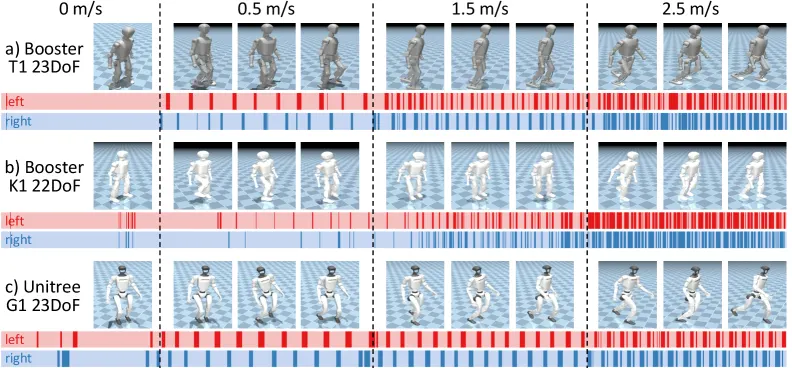
A humanoid that can walk should not relearn locomotion from scratch to jog or run. Yet current approaches often obtain gait diversity by prescribing gait schedules, imitating motion clips, training experts to switch between or distilling skills into one policy. These strategies can produce impressive behaviors, but offer limited flexibility across continuous speed commands, terrains, and morphologies. We study skill growth with GaitSpan, a framework that expands a pretrained, basic walking policy into faster locomotion. It treats walking as a seed skill: reusable motor structure for balance, support, body coordination, and contact transition that can be regenerated at new rhythms, extended into longer/higher strides, and corrected by residual adaptation. This expansion has three aspects: 1) rhythm generation, which modulates the frozen walking policy with multiple internal clocks and learns command-conditioned combinations of the resulting canonical actions; 2) stride shaping, which rewards dynamic locomotion patterns appropriate for higher commanded speeds using a physically grounded objective inspired by spring-loaded inverted pendulum dynamics; and 3) residual adaptation, which captures motion details not accounted for by rhythm generation or stride shaping. GaitSpan is the first to deliver a single command-conditioned humanoid policy that spans walking, jogging, and running-like regimes covering a continuous speed range, transfers across morphologies, and deploys zero-shot on unseen sim-to-sim, and real-world terrains. Compared with baselines either trained with multi-experts or imitation from humans, it learns faster and achieves stronger gait performance.
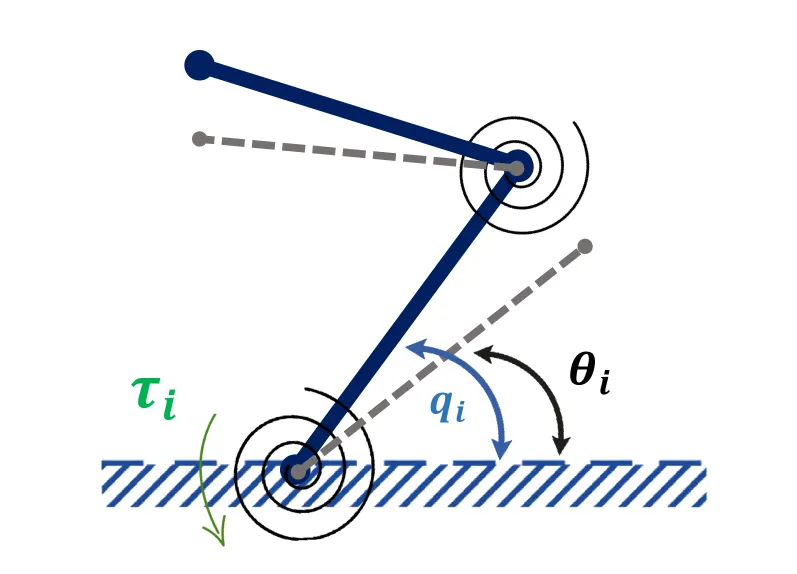
Bilateral teleoperation systems that include joint flexibility better reflect real robotic systems used in surgery, space, and rehabilitation. However, joint flexibility together with time-varying communication delays makes it difficult to maintain stable and coordinated motion between the master and slave robots. To address this, we propose a hybrid control method that combines a stable Proportional-plus-Damping (P+d) controller with a model-free deep reinforcement learning agent based on the Twin Delayed Deep Deterministic Policy Gradient (TD3) algorithm. The P+d controller provides basic stability under bounded delays, while the learning agent adjusts and tunes the remote-side proportional and damping gains in real time to reduce vibrations and improve tracking. Stability is guaranteed for bounded time-varying delays using Lyapunov-Krasovskii analysis. The approach provides a practical solution for teleoperation systems facing both joint flexibility and uncertain network delays.