Skip to content
Embodying Multi-Hand Manipulation Policies by Searching the Assignment and Null Spaces

Embodying Multi-Hand Manipulation Policies by Searching the Assignment and Null Spaces

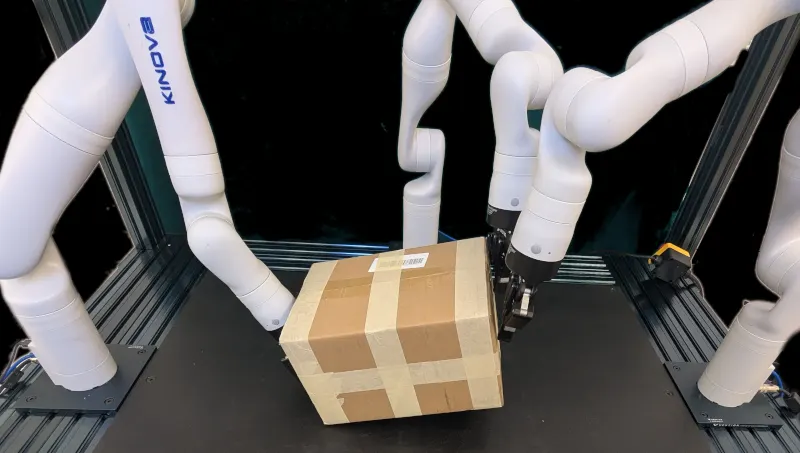
Learned manipulation policies increasingly predict motions for abstract "hands" and are attractive in practice because they rely on easily collected demonstrations and transfer across robot platforms. Executing these trajectories on multi-arm robots, however, is not trivial. Multi-hand policy outputs must be assigned to physical arms, each arm must realize a configuration-space motion that tracks its prescribed end-effector trajectory, and all arms must respect kinematic limits and avoid collisions. In the absence of algorithms that directly address this problem, practitioners typically extend single-arm inverse-kinematics (IK) pipelines in an ad hoc way, with no guarantees of feasibility or safety. In this work, we close this execution gap with a search-based framework that is theoretically complete for grounding policy-generated multi-hand trajectories onto physical multi-arm systems. Building on Conflict-Based Search, our method explicitly searches over both the discrete assignment of trajectories to arms and the continuous Jacobian null spaces of redundant manipulators, using redundancy to avoid inter-arm collisions while tracking the prescribed motions. This unified treatment of assignment and null-space motion yields a practically efficient planner that safely realizes coordinated manipulation-policy outputs on multi-arm robots. See omcbsa.github.io for more.

Embodied AIYorai Shaoul, Jiaoyang Li, Maxim Likhachev·Jul 24, 2026
Design and Human Evaluation of Tactile Withdrawal Reflexes for a Skin-Covered Robot Arm

Design and Human Evaluation of Tactile Withdrawal Reflexes for a Skin-Covered Robot Arm

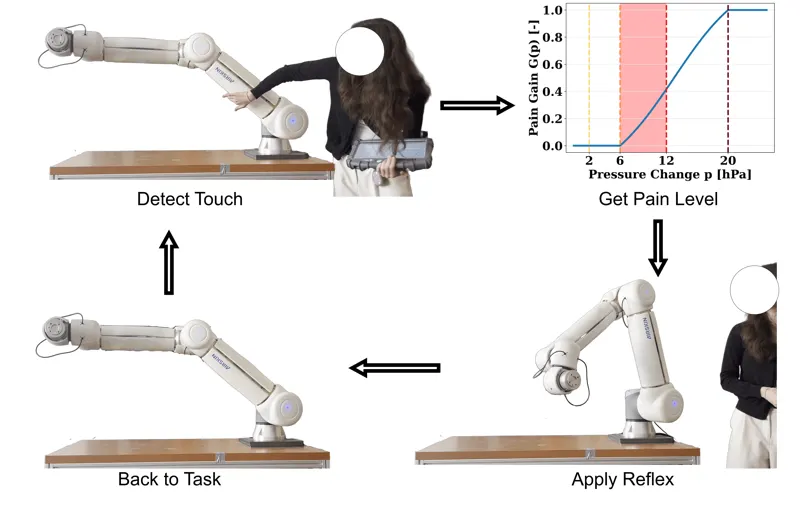
Nociception is a protective biological mechanism that links harmful stimulation to a reaction. This paper investigates artificial nociception for a robotic arm with whole-body tactile sensing. We present a complete pipeline that maps pressure changes from sensitive skin on a robot manipulator to bio-inspired withdrawal motions. The system first converts skin pressure into a scalar pain gain using a nonlinear continuous model. We compare three reflexes: (i) uniform reflex moves four robot joints by a fixed amount, whereby the withdrawal is approximated by a movement of the arm "toward the base", independent of where the robot was touched; (ii) biologically motivated location-dependent joint-space withdrawal derived from human withdrawal reflex characteristics; (iii) Cartesian space withdrawal along the surface normal of the contacted skin pad. All behaviors are integrated in a reflex controller that interrupts the task, executes the withdrawal, and returns to a pre-contact pose. A user study with 15 participants compared the strategies using Godspeed questionnaire subscales, custom perceived-naturalness and safety items, forced-choice comparisons, and qualitative feedback. Interestingly, participants rated more highly the uniform reflex behavior over one or both competitors on the anthropomorphism, animacy, and likeability Godspeed subscales and on the Naturalness and Realism custom scale. When asked to compare the conditions, the uniform reflex was scored best in "felt safest", "most human-like", and "most natural". This suggests that predictability of the robot behavior is key for user acceptance. The Cartesian reflex was judged the most appropriate reaction to touch. The bio-inspired reflex did not lead any evaluated measure. This may be partly attributed to the embodiment gap between the robot arm and human arm and participants having different expectations from a robot manipulator.

Embodied AILaura Babayeva, Lukas Rustler, Matej Hoffmann·Jul 24, 2026
MEMENTO: Memory-Guided Memetic Code-as-Policy Evolution

MEMENTO: Memory-Guided Memetic Code-as-Policy Evolution

Long-horizon embodied tasks require policies that execute many dependent actions before task success can be observed. Representing policies as executable control pro- grams (code-as-policy) enables their decision logic to be inspected and revised after rollout evaluation. Revised programs can then be executed and compared by rollout performance, framing policy improvement as execution-guided program search. Evo- lutionary methods driven by large language models (LLMs) provide a natural mecha- nism for this search by generating variants and selecting high-performing candidates. However, existing approaches primarily select among independently generated vari- ants and lack a sequential local improvement phase. We introduce MEMENTO, a memory-guided single-elite memetic framework for code-as-policy evolution. ME- MENTO first evolves a rollout evaluator that maps policy rollouts to scalar fitness and structured feedback metrics. Fitness selects accepted candidates and the next elite, while feedback metrics condition policy proposals generated by memory-guided hill-climbing, macro-mutation, and crossover. We evaluate MEMENTO on two long- horizon embodied domains: Robosuite Franka Tower-of-Hanoi manipulation and AI2- THOR household interaction. MEMENTO outperforms Eureka and REvolve, adapted as code-as-policy evolutionary baselines, in task success and generalization to held- out Robosuite object configurations and unseen AI2-THOR scenes. Ablations show that zero-shot generation and unevolved evaluators fail to solve either domain, and that removing policy-search branches reduces performance. Finally, we deploy the best-evolved Robosuite policy on a physical Franka robot, demonstrating the feasibil- ity of sim-to-real transfer of the evolved code-as-policy. Code, prompts, and videos are available at: https://github.com/sygkounas/MEMENTO.

Embodied AIAlkis Sygkounas, Victor Aregbede, Amy Loutfi·Jul 24, 2026
Real2Sim2Real for Vision-Language-Action Manipulation: An AMD ROCm-Based Pipeline

Real2Sim2Real for Vision-Language-Action Manipulation: An AMD ROCm-Based Pipeline

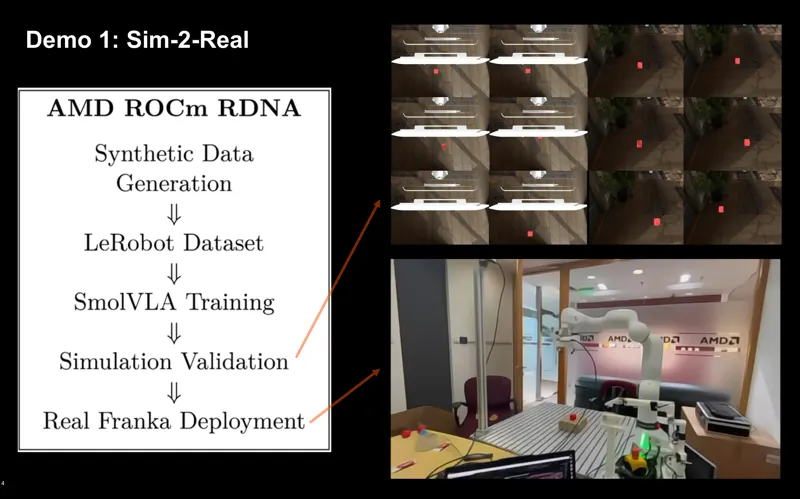
Physical AI – the integration of large vision-language-action (VLA) models with embodied agents that act in the real world – has emerged as the next major frontier for AI, echoed by industry leaders such as Jensen Huang (``the next big thing is Physical AI, AI with a body,'' GTC Paris, June 2025) and Dr. Lisa Su (`we're entering the world of Physical AI... this is where AI enters the real world,' CES 2026). This paper presents an end-to-end, fully AMD-accelerated technology stack for embodied manipulation, spanning data-center training silicon, Radeon PRO simulation/rendering GPUs, and Ryzen AI edge compute, unified by the open ROCm software stack. We demonstrate that training and deploying VLA-based manipulation policies does not require a CUDA-locked ecosystem. Four progressive demonstrations are presented: (1) a Sim-to-Real manipulation pipeline trained with SmolVLA and deployed on a physical Franka arm; (2) a semantic, language-grounded object-selection task (`one-of-three'); (3) a Real2Sim synthetic-data generation pipeline that fuses 3D Gaussian Splatting (3DGS) reconstructions of real scenes with the Genesis physics engine; and (4) large-scale reinforcement learning for quadruped and humanoid locomotion benchmarked across multiple hardware platforms. All pipelines run natively on ROCm + PyTorch on RDNA4 (Radeon AI PRO R9700) and RDNA3.5 (Radeon PRO W7900) hardware and are reproducible on the free Radeon Cloud Platform.

Embodied AIQing Yang, Xun Wang, Ziguan Wang·Jul 25, 2026