AgiBot GE-Act 2.0: the first native World Action Model to validate a pretraining and scaling path for embodied AI
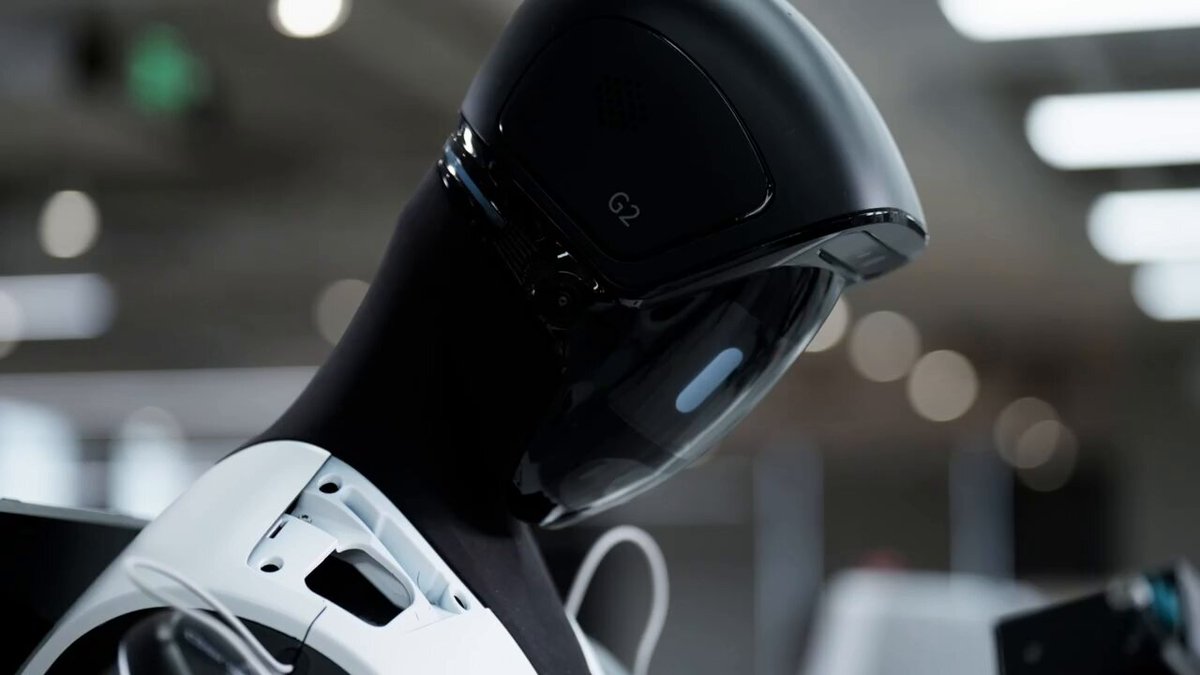
AgiBot Research (arXiv:2609.05588) presents GE-Act 2.0: unlike most world-action models that inherit pretrained video generators, all trainable generative and action components are initialized from scratch on manipulation data - no inherited video generators, no task-specific fine-tuning. Three components: a control-oriented autoencoder CoAE (retaining action- and instruction-relevant information under aggressive compression), a single-step visual planner SVP (producing a complete future state in one differentiable pass; 39,000 hours of pretraining data), and an inverse dynamics model IDM (32,000 hours); then jointly trained with Knowledge-Aligned Selective Optimization (KASO), which reduces mismatched supervision by selecting only predicted futures judged behaviorally compatible with recorded actions. A ruthless real-robot zero-shot OOD test: unseen scenes and objects, 100 atomic tasks across 20 skill groups, two embodiments (G1-OP covers 50%+ of co-training data, G2-90D under 2%). Scaling co-training data from 300 to 30,000 hours raises success from 17.1% to 44.1% on G1-OP and from 13.4% to 31.1% on G2-90D (+17.7 points despite under 2% data share, evidence of cross-embodiment transfer); gains span 19/20 and 18/20 skill groups, and skill coverage strongly correlates with zero-shot OOD success (Pearson r=0.80). The full pipeline from three-camera observations to 52 executable actions takes just 104 ms on a single RTX 5090, with 30 Hz action chunks spanning ~1.7 s - real-time control on consumer GPUs. Code coming soon.