RT-2: Turning Vision and Language Directly Into Robot Actions
Loading video
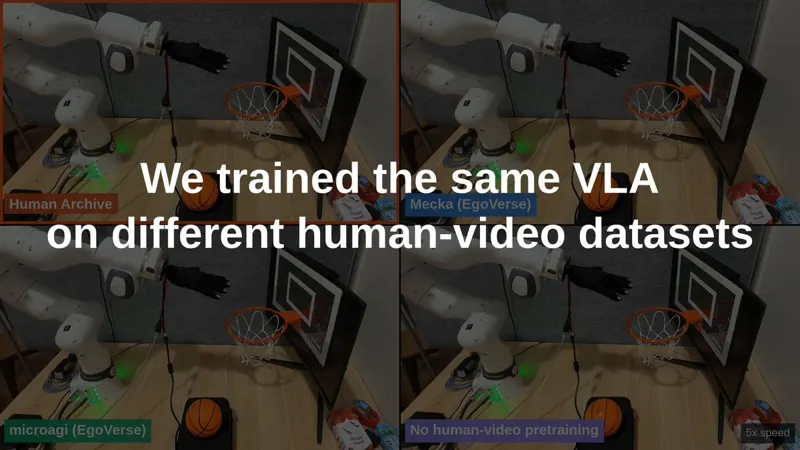
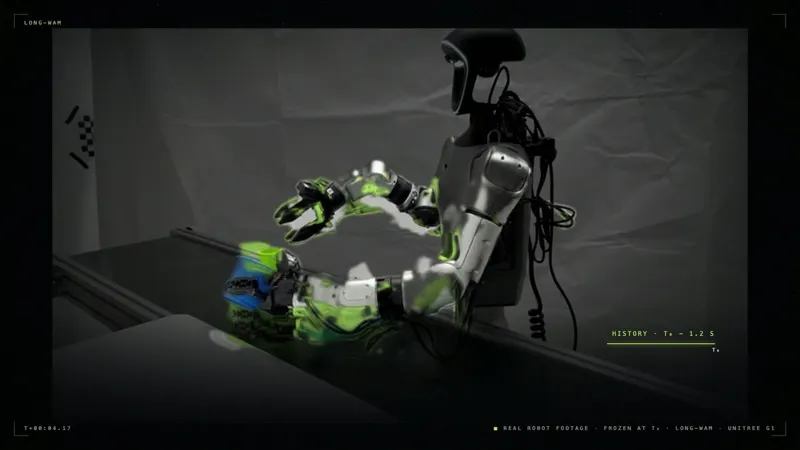
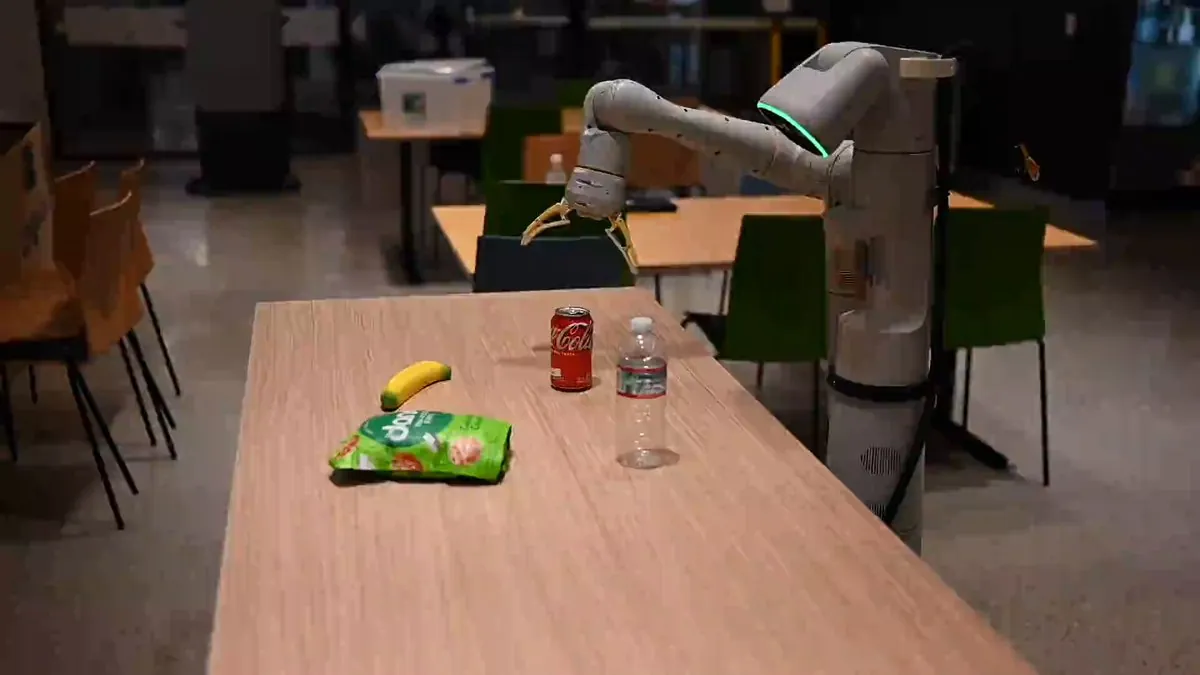
Loading videoRT-2 represents robot actions as tokens so a vision-language model becomes the controller itself. Web-scale pretraining transfers into better generalization on unfamiliar objects and tasks, including simple semantic reasoning.
Category: research
Author: @Alacritic_Super
Date: 2026-09-22T00:00:00
Duration: 112.228s
Reference: https://arxiv.org/abs/2307.15818