Skip to content
← Tags

#Algorithm Discovery (2)

MathResearchTopB

AlphaEvolve: pointing a model at problems that come with an objective scoring function

Google DeepMind's coding-agent-driven evolutionary search: Gemini Flash proposes candidates in volume and Gemini Pro in quality, automatic evaluators score them, and high scorers stay in the population as next-round context, i.e. evolutionary search with an LLM as the mutation operator; it applies only where an automatic evaluator exists, hence the math and agents filing. An evolved scheduling heuristic has run in production in Google data centres (Borg) for over a year, recovering 0.7% of Google's global compute (Google's compute, not all compute on earth), the card reading and the only result validated by long-running production. An evolved matmul kernel is 23% faster at specific sizes, and about 20% of 50+ open maths problems improved, including 4x4 complex matrix multiplication in 48 multiplications against Strassen's 1969 record of 49. Verification differs from the prover line: a Lean check is mathematical correctness, "23% faster" is an empirical reading on specific hardware. No public weights, Early Access is a waitlist, and the precondition is an evaluator you write yourself. Graded B (contested): a year of production behind the Borg result, nothing reproduced.
0.7%Google global compute recovered (production-verified)Contested · 2025-05
ProductionGoogle DeepMindSite
AlphaEvolve: pointing a model at problems that come with an objective scoring function
Dream-RSI: Recursive Self-Improvement through Evolving Worlds

Dream-RSI: Recursive Self-Improvement through Evolving Worlds

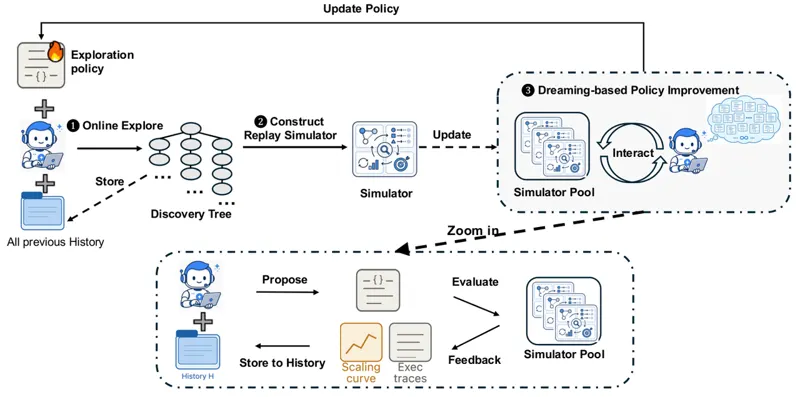
Recursive self-improvement is becoming increasingly vital for autonomous AI agents, where progress hinges on discovering high-value solutions across complex domains. The driver of this process is effective exploration, however, managing and improving exploration strategies remains a major bottleneck. Current systems face a fundamental dilemma: fixed strategies fail to adapt as search spaces scale, while online policy optimization requires navigating vast meta-search spaces under delayed and expensive feedback over long-horizon rollouts. We introduce {Dream-RSI}, a framework for scalable and recursively self-improving exploration. A lightweight orchestration layer makes exploration explicit and programmable while leaving the underlying coding agent unchanged. Our key insight is that accumulated discovery history can serve as a replay simulator over the realized search space. By performing dreaming in the replay simulator constructed from historical discovery trees, {Dream-RSI} secures immediate, low-cost off-policy feedback to evaluate and refine exploration policies without invoking repetitive, expensive online evaluations. The improved policy is subsequently redeployed online to drive further discovery, continuously expanding the simulator pool in a self-improving loop. Across algorithm engineering, mathematical optimization, and GPU kernel engineering, {Dream-RSI} achieves competitive or improved discovery quality while substantially reducing discovery cost in several settings.

Tong Zheng, Xidong Wu, Zheng Zhang · 1.2k views · Sep 14, 2026
Recursive self-improvementWorld Models
Sep 14, 2026

As an Amazon Associate, we earn from qualifying purchases.