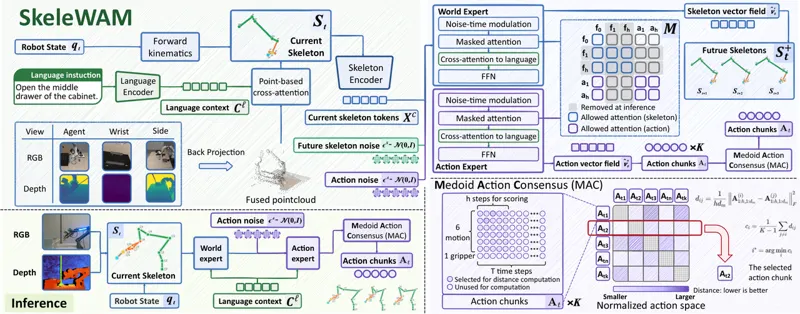
SkeleWAM: squeezing a manipulation scene into a sparse 3D skeleton
World action models usually represent future state as video or visual latents, which encode geometry only implicitly and carry appearance irrelevant to control. SkeleWAM keeps just three kinds of 3D landmarks - robot joints, object centres and interaction points - and uses that sparse skeleton for both action generation and future-skeleton prediction, training with the latter as auxiliary supervision and dropping it at inference. On LIBERO-Plus it reaches 85.9% zero-shot success with 57.1M parameters, beating the 2B-parameter Cosmos-Policy by 3.7 points.
Juyi Sheng, Hua Wang, Mengyuan LiuOct 1, 2026
VLAWorldActionModelManipulationOct 1, 2026