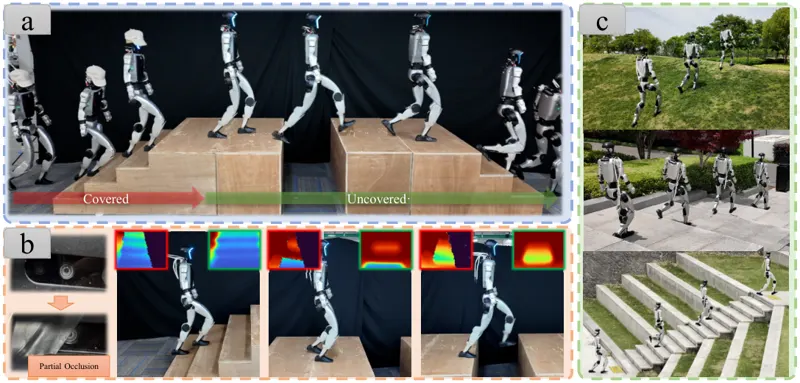
Humanoid locomotion across complex terrain demands forward-looking exteroception to anticipate obstacles, yet this signal is unreliable in real-world deployment, failing partially and intermittently. Existing perceptive policies often assume that depth observations remain clean and in-distribution, while recent attempts to unify perceptive and blind control typically route or switch between separate sub-policies, leaving recoverable information in partially corrupted depth unexploited. We instead propose CAP, a single-stage humanoid locomotion policy that recovers this signal with a perceptive world-model encoder trained as a learned denoiser to reconstruct clean depth from a corrupted input, together with a co-active proprioceptive variational encoder that supplies depth-free body-state information. A coupled training recipe pairs a depth-noise curriculum on the world-model input with world-model feature dropout on the policy-facing latent, exposing the policy to failures across the entire perception-quality spectrum. In simulation, CAP matches or improves upon perceptive baselines when depth remains informative, and degrades more smoothly than a binary-switching baseline as perception worsens. On the Unitree G1, controlled trials and indoor-outdoor deployments demonstrate perception-robust locomotion under intermittent occlusion, real-sensor corruption, and outdoor depth artifacts.
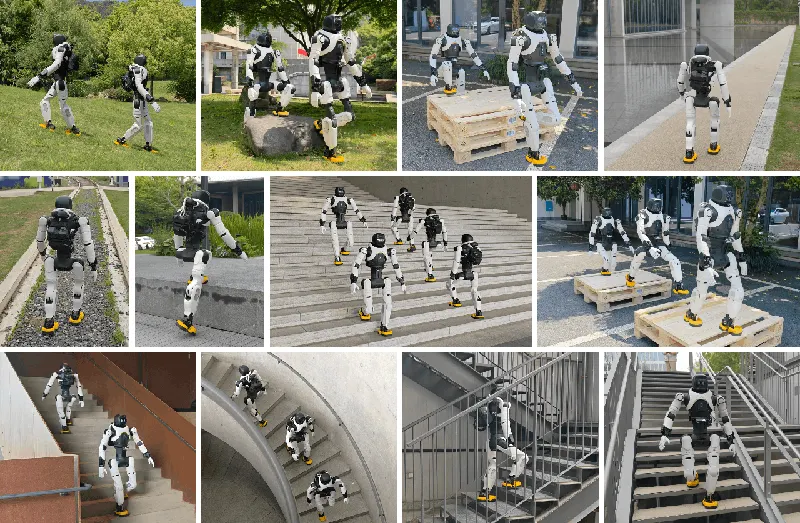
Extending humanoid traversal to the open world is key to practical deployment in human environments, but remains challenging. The robot must use vision to ensure safe and reliable foot placement on heterogeneous terrain under highly dynamic motion, while producing coordinated, natural whole-body behaviors. We propose SSR, an efficient end-to-end framework for egocentric vision-based humanoid traversal that jointly learns these capabilities. SSR introduces imagined foothold guidance, which learns to model forthcoming swing-foot contacts and evaluates their support to guide pre-touchdown swings toward stable regions, reducing edge slips. It further employs equivariant latent-space symmetry augmentation to efficiently induce bilateral coordination under high-dimensional visual observations, and uses terrain-specific multi-discriminator motion priors to encourage human-like behavior across scenes. Extensive experiments show that SSR achieves safe, stable, and high-quality locomotion on diverse real-world terrains, including stairs with varied structures and extreme challenges such as wide gaps and high platforms, while enabling reliable long-horizon traversal in open outdoor environments.
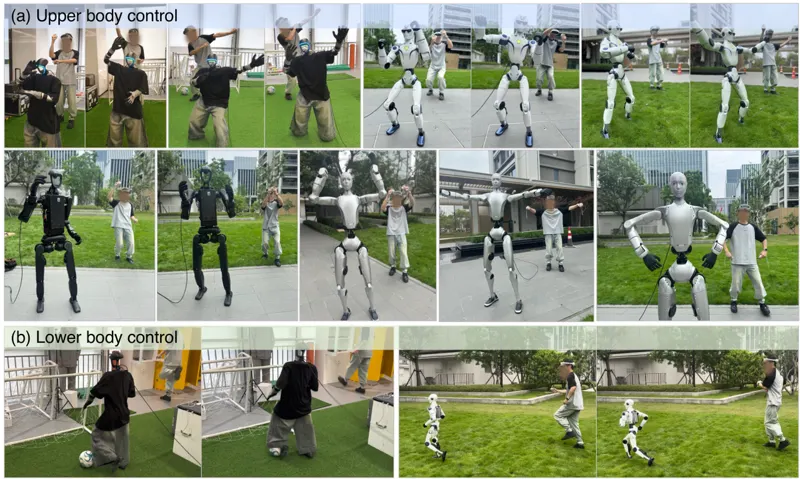
Scaling humanoid whole-body control toward general-purpose deployment requires large human motion corpora and training experience shared across robot bodies. Existing methods usually train one policy per robot, leaving motion experience isolated across embodiments. We introduce X-WBC, a cross-embodiment foundation framework that separates relatively shared human motion semantics from embodiment-specific physical execution. Human-centered command tokens align full human motion, robot reference motion, and sparse VR observations. A causal Transformer learns reusable temporal structure from mixed multi-robot rollouts, while lightweight robot-specific modules map the shared representation to each robot's proprioception and action space. Across nine simulated embodiments, external motions, and four real robots, experiments show that joint training improves tracking, the aligned representation supports consistent control across command sources, and the learned policy remains competitive beyond the training corpus. These results support heterogeneous humanoids as joint data sources and establish cross-embodiment joint training as a practical route toward whole-body control foundation models.
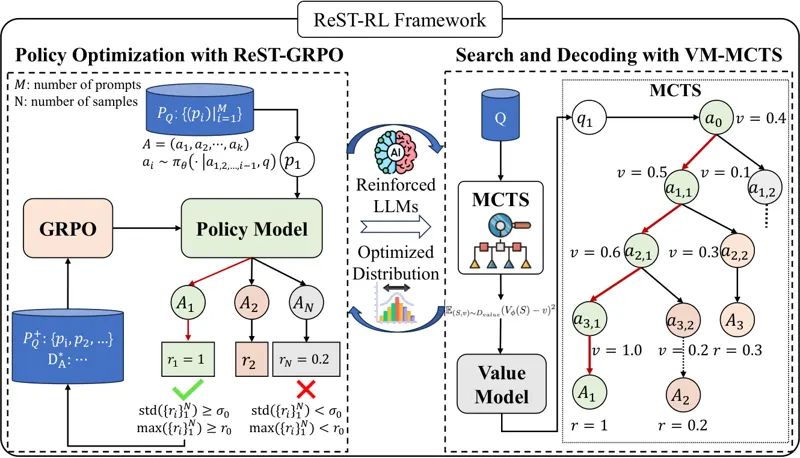
GRPO is the representative RL method for improving LLM reasoning, yet it only ever sees one sparse reward at the end of a whole trajectory: when the rewards inside a sampled group land close together, the group-relative advantage collapses into noise and the policy learns almost nothing. ReST-RL reconnects policy optimization and value-guided search into a single self-training pipeline. Stage one, ReST-GRPO, first filters out low-information prompts by reward standard deviation, then draws prefixes from each prompt's highest-reward trajectory under a discrete exponential distribution and uses them as fresh online-GRPO starting contexts. A selected prefix is context only; its suffix is re-sampled and optimized rather than imitated. Stage two, VM-MCTS, runs MCTS under the now-static policy to self-collect value targets and trains a value model that predicts expected terminal reward. At inference the same model both allocates the tree search through UCT and ranks completed candidates in a Best-of-N fashion, so search and verification share one state-value scale. On coding benchmarks including APPS, BigCodeBench and HumanEval, Qwen3-8B moves from 0.503 to 0.689 average. In matched policy-value controls, ReST-GRPO + VM-MCTS reaches 0.642 on APPS-500 while GRPO + VM-MCTS reaches only 0.538, so the stage-one distributional shift survives value learning. End-to-end accounting puts ReST-GRPO at 1,752 GPU-hours against 2,080 for GRPO, hitting a 9% gain in 71 hours instead of 207. A value model trained only on code trajectories also transfers to MATH, Omni-MATH and GPQA-Diamond without target-domain tuning.
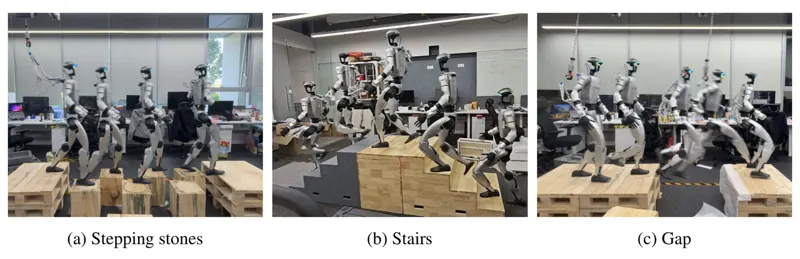
Foothold-constrained terrain is characterized by sparse, discontinuous, or geometrically restricted feasible foot contacts, as encountered on stepping stones, across gaps, and on narrow stair treads. On such terrain, a single misstep often leaves little room to recover, so policies that base foot-placement decisions primarily on the immediately visible terrain are prone to failure. We ask whether a learned predictive summary of near-future observations and rewards can provide the anticipatory information required in such settings. We present World-Model-Augmented Visual Locomotion (WM-LOCO), which jointly trains a recurrent world model and a PPO policy. Conditioned on proprioception and a single onboard depth image, the world model produces a predictive recurrent feature that guides the policy, without explicit foothold labels. In simulation, WM-LOCO succeeds on gaps and stepping stones where a matched baseline fails completely, and matches the baseline's success rate on stairs while improving stride efficiency and reducing pelvis acceleration. We deploy the same policy onboard a physical Unitree G1 humanoid using onboard proprioception and a single depth stream; it traverses all three terrain classes with an average success rate of 93.3%.
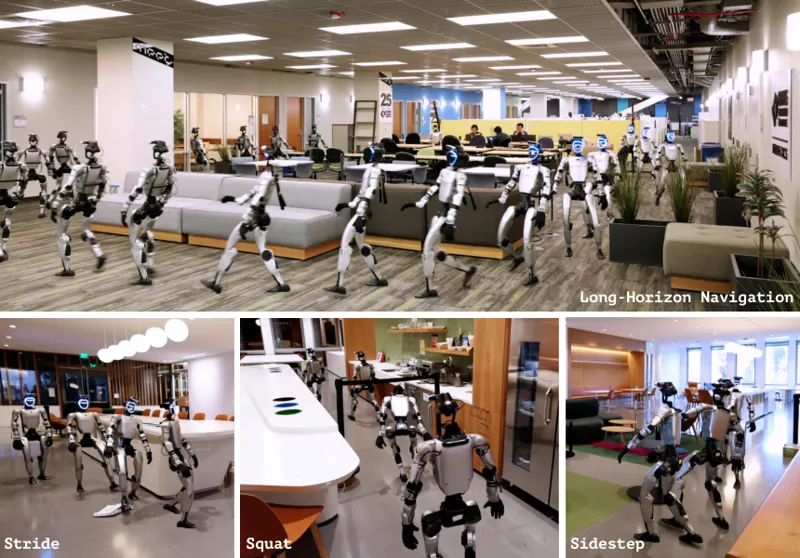
We study the problem of navigating cluttered indoor environments with a humanoid robot. Unlike conventional methods that model navigation as a 2D path planning problem, humanoid traversal in cluttered environments requires continuous geometry-aware whole-body adaptation, including coordinated arm placement, torso adjustment, and gait modulation for collision-free movement through complex 3D spaces. We introduce TANGO, the first whole-body vision-language navigation framework for language-conditioned humanoid traversal in cluttered environments. Given a natural-language instruction and egocentric RGB observations, TANGO directly predicts 29-DoF joint-space actions for downstream whole-body control. We train TANGO entirely in simulation by synthesizing diverse collision-free traversal behaviors via global path planning, kinematic whole-body motion generation, obstacle-aware motion editing, and RL-based tracking. This pipeline provides dynamically feasible action supervision for learning language-conditioned whole-body policies. In extensive simulation experiments, TANGO demonstrates state-of-the-art performance in vision-language navigation, while outperforming strong modular baselines in navigating challenging scenes requiring obstacle negotiation. Lastly, we deploy TANGO zero-shot on a Unitree G1 humanoid robot, and observe robust language-guided traversal in cluttered real-world scenes without training on any real-world navigation data.
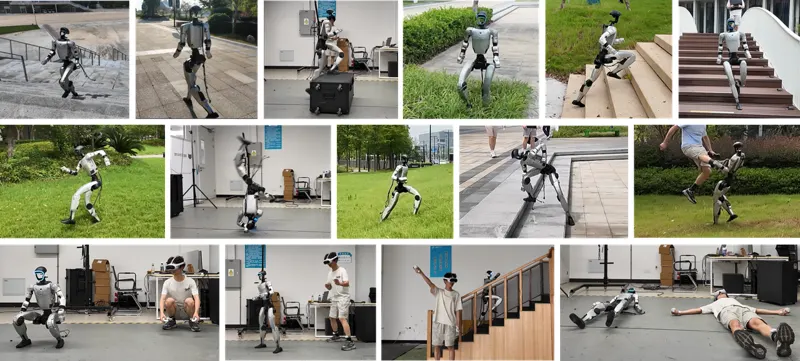
Humanoid motion trackers can reproduce diverse whole-body motions, but their performance degrades on complex terrain where terrain-agnostic references become physically infeasible. We present PGMT, a Perceptive General Motion Tracking pipeline for humanoid robots that learns terrain adaptation from independently selected motion references and terrains. PGMT first learns a general tracking and recovery prior, then incorporates terrain perception through motion-conditioned terrain glimpses that selectively encode regions relevant to the current motion. Terrain-aware tracking relaxation allows necessary deviations from the reference while preserving its motion intent. Zero-shot deployment on a Unitree G1 demonstrates robust terrain-adaptive locomotion and whole-body motion execution over real-world terrain with obstacles up to 37 cm high, while supporting teleoperation, dynamic motion tracking, and fall recovery. PGMT extends general humanoid motion tracking beyond flat ground, providing a unified policy for terrain-adaptive locomotion, diverse whole-body behaviors, and teleoperation in complex environments.
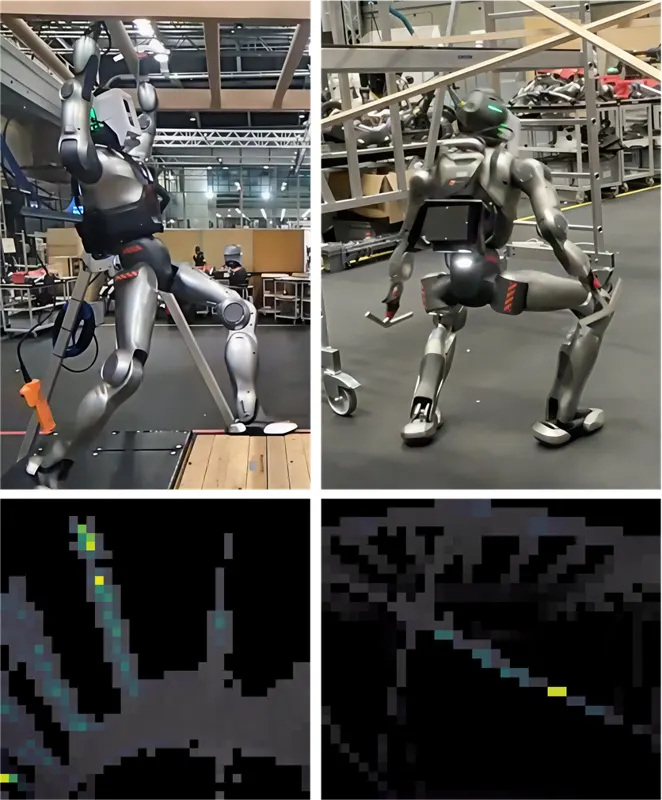
Traversing sparse 3D structures requires humanoid robots to perceive thin, overhanging geometry while executing agile, accurate whole-body motions. We study this problem through monkey-bar traversal, where the robot must jump to the structure, traverse it through sparse bar interactions, and land safely. For this task, we present a reinforcement-learning-based perceptive control system that operates directly on observations from a head-mounted solid-state lidar. To extract task-relevant geometry from the sparse returns, the policy consumes the raw lidar scan through an attention-based encoder with recurrent memory. This policy is obtained by a phase-scheduled teacher- student pipeline that combines privileged experts for jumping up, brachiating, and jumping down. For transfer to hardware, we model lidar noise, battery-voltage sag, and actuator thermal limits, and equip the humanoid with passive hook end-effectors for robust bar interaction. On hardware, the resulting policy completes the full jump-up->brachiation->jump-down sequence in 14 of 15 trials across three bar configurations and reaches brachiation speeds up to 0.5 m/s. Beyond brachiation, the same perception backbone supports a separately trained policy that ducks beneath thin overhead obstacles with 2 cm cross-sections.
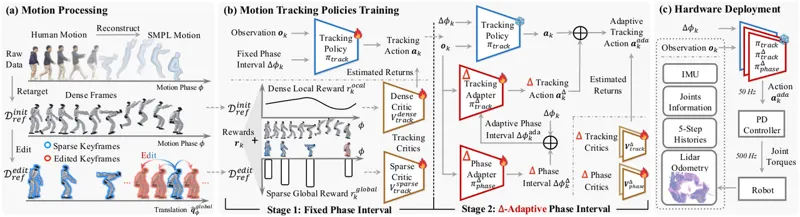
Humanoid robots are envisioned to adapt demonstrated motions to diverse real-world conditions while accurately preserving motion patterns. Existing motion prior approaches enable well adaptability with a few motions but often sacrifice imitation accuracy, whereas motion-tracking methods achieve accurate imitation yet require many training motions and a test-time target motion to adapt. To combine their strengths, we introduce AdaMimic, a novel motion tracking algorithm that enables adaptable humanoid control from a single reference motion. To reduce data dependence while ensuring adaptability, our method first creates an augmented dataset by sparsifying the single reference motion into keyframes and applying light editing with minimal physical assumptions. A policy is then initialized by tracking these sparse keyframes to generate dense intermediate motions, and adapters are subsequently trained to adjust tracking speed and refine low-level actions based on the adjustment, enabling flexible time warping that further improves imitation accuracy and adaptability. We validate these significant improvements in our approach in both simulation and the real-world Unitree G1 humanoid robot in multiple tasks across a wide range of adaptation conditions. Videos and code are available at https://taohuang13.github.io/adamimic.github.io/.
Achieving robust humanoid hiking in complex, unstructured environments requires transitioning from reactive proprioception to proactive perception. However, integrating exteroception remains a significant challenge: mapping-based methods suffer from state estimation drift; for instance, LiDAR-based methods do not handle torso jitter well. Existing end-to-end approaches often struggle with scalability and training complexity; specifically, some previous works using virtual obstacles are implemented case-by-case. In this work, we present Hiking in the Wild, a scalable, end-to-end parkour perceptive framework designed for robust humanoid hiking. To ensure safety and training stability, we introduce two key mechanisms: a foothold safety mechanism combining scalable Terrain Edge Detection with Foot Volume Points to prevent catastrophic slippage on edges, and a Flat Patch Sampling strategy that mitigates reward hacking by generating feasible navigation targets. Our approach utilizes a single-stage reinforcement learning scheme, mapping raw depth inputs and proprioception directly to joint actions, without relying on external state estimation. Extensive field experiments on a full-size humanoid demonstrate that our policy enables robust traversal of complex terrains at speeds up to 2.5 m/s. The training and deployment code is open-sourced to facilitate reproducible research and deployment on real robots with minimal hardware modifications.
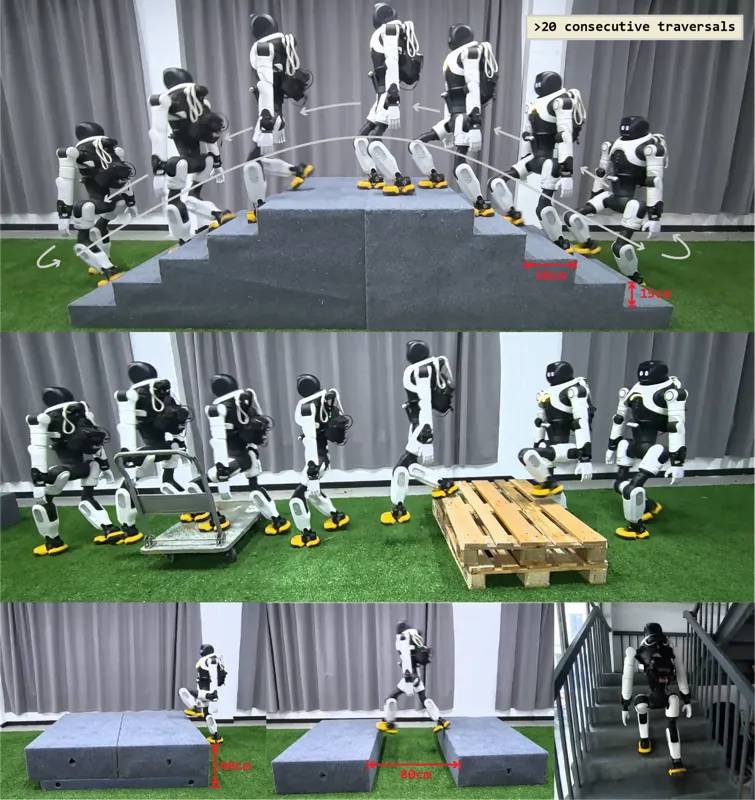
CReF is a single-stage depth-conditioned humanoid locomotion framework that maps onboard proprioception and forward-facing depth directly to joint position targets, without explicit geometric intermediates. It couples proprioception and depth tokens via proprioception-queried cross-modal attention, fuses them with a gated residual block, and integrates temporal context with a GRU regulated by a highway-style output gate. A terrain-aware foothold placement reward extracts supportable candidates from foot-end point-cloud windows and rewards touchdowns near them. Full CReF leads all terrain categories and difficulty levels in simulation and transfers zero-shot to a physical AGIBOT X2 Ultra across handrail stairs, hollow pallets, reflective interference, and cluttered outdoor scenes.
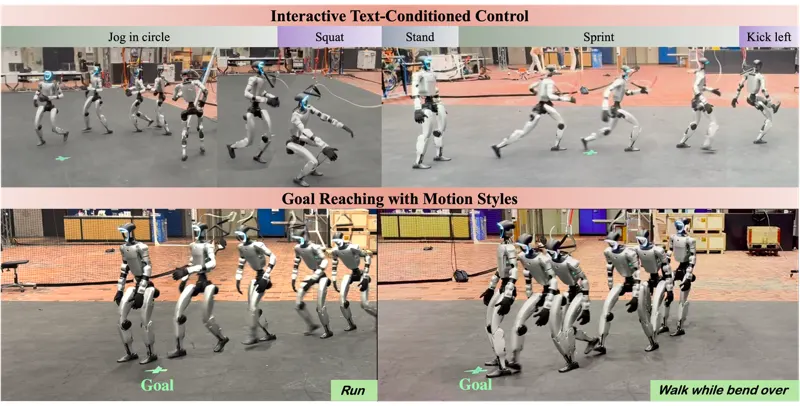
We present ADAPT, an end-to-end framework for interactive, text-conditioned humanoid whole-body control. Unlike dominant text-to-motion pipelines that generate kinematic motions for a separate tracker, ADAPT solves language control with an end-to-end closed-loop control framework, where the robot must continuously respond to changing commands while maintaining balance, natural motion, and smooth transitions. ADAPT learns a diffusion-based action prior from text-labeled humanoid state-action trajectories, enabling diverse motion skills to be directly executed from language commands. To improve long-horizon robustness and smooth prompt switching, we train a lightweight residual reinforcement learning policy on top of the frozen diffusion controller. We further show that the same diffusion policy can be reused as a steerable text-conditioned motion prior for downstream task adaptation. Experiments demonstrate robust language-grounded skill execution, smooth interactive transitions, and style-preserving downstream control.