Skip to content
SimpleVLN: Towards Simple and Frontier Vision-Language Navigation

SimpleVLN: Towards Simple and Frontier Vision-Language Navigation

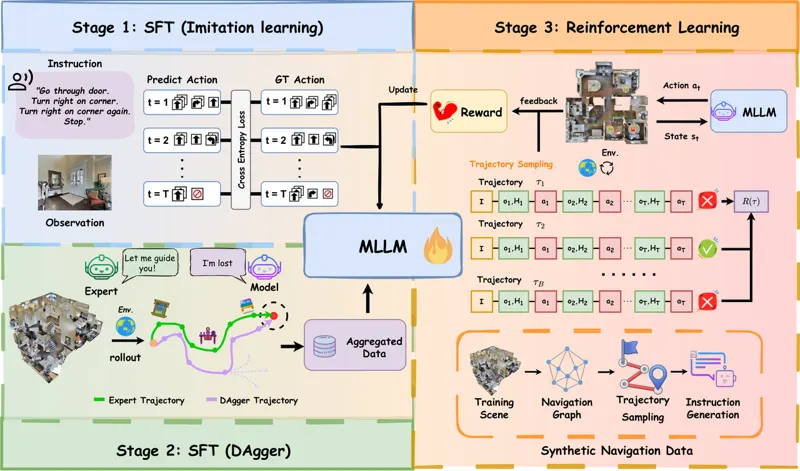
Vision-and-Language Navigation (VLN) requires embodied agents to ground language in visual observations and make long-horizon decisions. Existing methods often address these demands through task-specific architectures. As multimodal large language models (MLLMs) become increasingly capable, an important question remains: Have we truly unlocked the potential of native MLLMs for VLN before introducing task-specific architecture? We present SimpleVLN, an architecture-preserving framework developed through studies of navigation formulation, data construction, and optimization. At the formulation level, SimpleVLN combines single-turn decision inputs with fixed-budget global-local memory to efficiently use navigation history without unbounded context growth, while action chunks enable efficient output of multiple primitive actions per model invocation. For data construction, we combine expert demonstrations with policy-dependent DAgger experience and develop a scalable synthesis pipeline that generates large-scale tasks for reinforcement learning. At the optimization level, a progressive IL-DAgger-RL pipeline advances from action imitation to task-level outcome optimization. Comprehensive experiments validate the effectiveness of these three aspects. We instantiate SimpleVLN across multiple MLLM backbones and model sizes, demonstrating its generality. SimpleVLN achieves 76.7% and 80.1% success rates on the R2R-CE and RxR-CE splits, respectively, substantially outperforming existing methods. These results show that the navigation capabilities of native MLLMs can be effectively unlocked without task-specific architectural designs.

Vision-language navigationEmbodied AI
Lingyi Hong, Weiren Cai, Jiayu Chen · 34 views · Oct 16, 2026
Agent World Model in the Wild: Computer-Use Agent Environment Synthesis

Agent World Model in the Wild: Computer-Use Agent Environment Synthesis

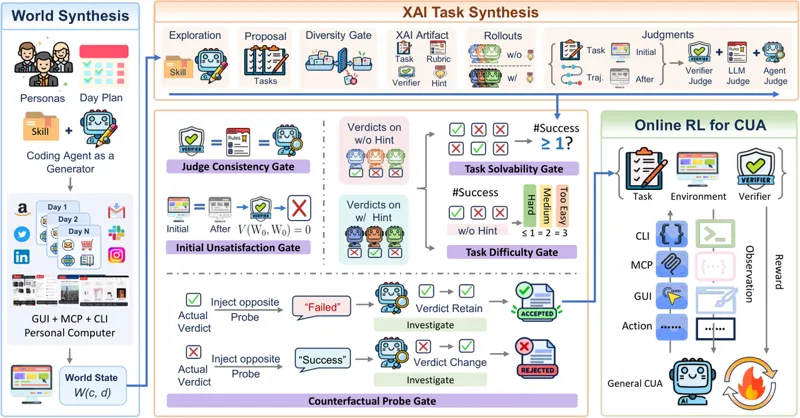
Agent learning is shifting from learning from human data toward learning through interaction with the world. However, scaling such learning directly in real-world computer systems is challenging and can introduce substantial security risks. We therefore propose Agent World Model in the Wild (WildAWM), a scalable pipeline for synthesizing controllable environments and tasks for training general computer-use agents (CUAs). Whereas existing approaches typically specialize in a single agent interaction interface, we construct executable environments that jointly support graphical user interfaces, model context protocol services, and command-line interfaces, allowing agents to flexibly combine visual interaction, tool use, and code execution. WildAWM is entirely powered by open-source models, demonstrating that high-quality computer-use environments can be generated without proprietary frontier models. Beyond environments, we address three recurring challenges in task synthesis: ensuring solvability, maintaining sufficient difficulty, and producing reliable verifiers, by introducing execution-based quality gates that combine heterogeneous agent rollouts, cross-judge consistency checks, and counterfactual probes of judgment robustness. The resulting pipeline synthesizes 341 long-horizon environment-task pairs that can require over 100 agent steps to solve and remain challenging even for frontier models, with GPT-6-Astra solving only 60% of them. We train two Qwen models of different sizes exclusively in these synthetic worlds. Both models achieve substantial gains across 8 out-of-distribution benchmarks spanning web, claw, and computer-use agents, demonstrating that learning in WildAWM's synthesized worlds generalizes broadly to unseen computer-use tasks. The code is publicly available at https://github.com/MSR-Orchard/WildAWM.

Computer-Use AgentWorld Models
Zhaoyang Wang, Qianhui Wu, Haorui Wang · 25 views · Oct 19, 2026
Perceptive Humanoid Parkour: Chaining Dynamic Human Skills via Motion Matching

Perceptive Humanoid Parkour: Chaining Dynamic Human Skills via Motion Matching

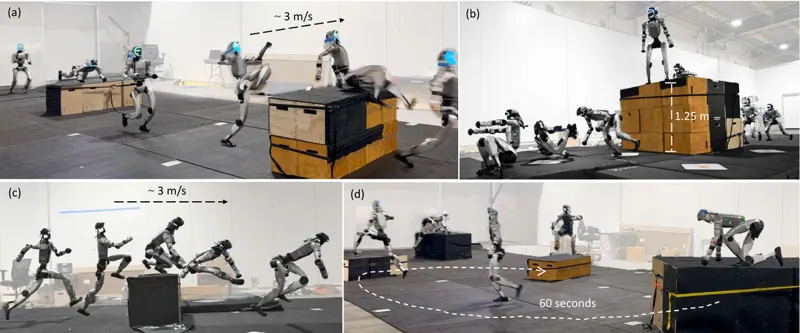
While recent advances in humanoid locomotion have achieved stable walking on varied terrains, capturing the agility and adaptivity of highly dynamic human motions remains an open challenge. In particular, agile parkour in complex environments demands not only low-level robustness, but also human-like motion expressiveness, long-horizon skill composition, and perception-driven decision-making. In this paper, we present Perceptive Humanoid Parkour (PHP), a modular framework that enables humanoid robots to autonomously perform long-horizon, vision-based parkour across challenging obstacle courses. Our approach first leverages motion matching, formulated as nearest-neighbor search in a feature space, to compose retargeted atomic human skills into long-horizon kinematic trajectories. This framework enables the flexible composition and smooth transition of complex skill chains while preserving the elegance and fluidity of dynamic human motions. Next, we train motion-tracking reinforcement learning (RL) expert policies for these composed motions, and distill them into a single depth-based, multi-skill student policy, using a combination of DAgger and RL. Crucially, the combination of perception and skill composition enables autonomous, context-aware decision-making: using only onboard depth sensing and a discrete 2D velocity command, the robot selects and executes whether to step over, climb onto, vault or roll off obstacles of varying geometries and heights. We validate our framework with extensive real-world experiments on a Unitree G1 humanoid robot, demonstrating highly dynamic parkour skills such as climbing tall obstacles up to 1.25m (96% robot height), as well as long-horizon multi-obstacle traversal with closed-loop adaptation to real-time obstacle perturbations.

HumanoidParkour
Zhen Wu, Xiaoyu Huang, Lujie Yang · 40 views · Feb 17, 2026
Blind Precise Assembly: Proprioceptive Sim-to-Real Peg-in-Hole for Diverse Parts

Blind Precise Assembly: Proprioceptive Sim-to-Real Peg-in-Hole for Diverse Parts

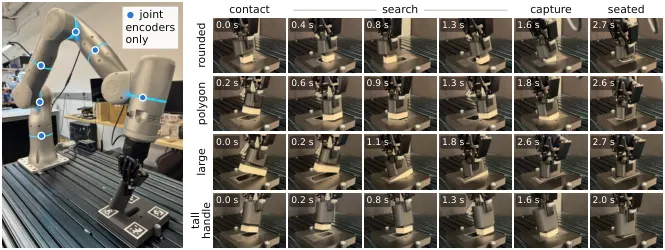
Every robot already carries high-resolution contact sensors: its own joints. Legged robots and humanoids exploit them to walk, run, and track whole-body motions without vision, but there the contacts are large and forceful. Is joint sensing also enough for precise, contact-rich assembly, where the robot must find a millimeter-scale opening, mesh gear teeth, or catch a thread through light contact? We study this question by training blind assembly policies that observe only a short history of joint positions, velocities, and their own actions, without visual, force, torque, or tactile sensing. The poses of both the fixture and the part are unknown to the policy, and the grasp is randomized substantially. The policy must therefore assemble the parts through contact, sensed exclusively through its own proprioception. Trained with reinforcement learning entirely in simulation over randomized parts, grasps, and contacts, such policies learn peg insertion, gear meshing, and nut threading. The peg insertion policy transfers zero-shot to the real world and inserts pegs of different shapes and sizes in 73% of trials. Controlled comparisons with matched visual policies in simulation show that blind policies generalize far better to unseen part shapes and sizes, though they can be slower. Training such policies needs thousands of different assemblies, each simulated with its clearance intact, so we also release an open-source generator that builds them procedurally from exact convex pieces for MuJoCo; it is more accurate and faster than convex decomposition or MuJoCo's signed-distance collision. Videos and interactive simulations are at https://younghyopark.me/blind-proprioceptive-assembly/.
Peg-in-HoleSim-to-Real
Antonia Bronars, Younghyo Park, Kushal Kedia · 91 views · Oct 16, 2026
Terminal-RSI: Recursive Self-Improving Terminal Agents via Recursive Self-Rewrite and Policy-Refine

Terminal-RSI: Recursive Self-Improving Terminal Agents via Recursive Self-Rewrite and Policy-Refine

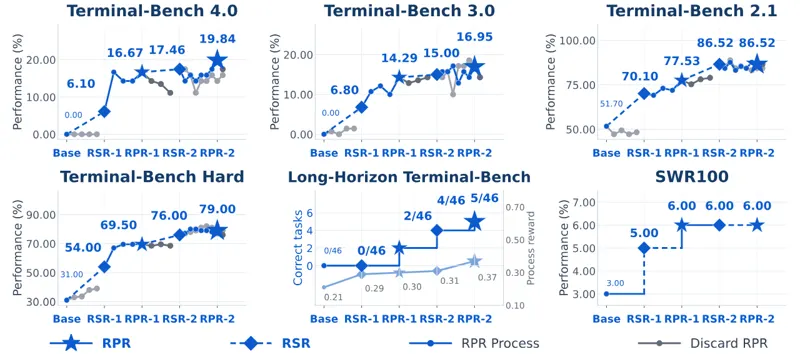
Converting verifier outcomes into useful policy updates and partial progress into complete task resolution is crucial for terminal agents. We present Terminal-RSI, which alternates Recursive Self-Rewrite (RSR) of verified trajectories with critic-inheriting Recursive Policy-Refine (RPR). We formulate Turn-Boundary Skip-Observation GAE (TB-GAE) to retain token-specific baselines while applying decay across interaction turns. Family Dense Reward (FDR) calibrates semantic progress across task families; Success-Prioritized Reward (SPR) separates strict success from bounded partial credit. A Warm-up Critic Model, recursive critic handoff, and stage-specific learning rates coordinate the two refinement phases. The five-stage sequence from Qwen3.8-27B base model through RSR-1, RPR-1, RSR-2, and RPR-2 yields Terminal-RSI-27B: 19.84% on Terminal-Bench 4.0, 86.52% on Terminal-Bench 2.1, 16.95% on Terminal-Bench 3.0, and 79.00% on Terminal-Bench Hard. On LHTB, process reward rises from 0.21 to 0.37 and strict completion from 0/46 to 5/46; SWR100 success doubles from 3.00% to 6.00%. By recursively coupling verified trajectory rewriting with critic-inheriting policy refinement, each retained stage consolidates discovered behaviors and progressively advances the agent from partial local repairs to strict terminal verification.

Terminal AgentReinforcement Learning
Junyao Yang, Zongxia Li, Yucheng Shi · 151 views · Oct 15, 2026
Agile and Generalized Legged Locomotion via Attention-Based Neural Map Encoding

Agile and Generalized Legged Locomotion via Attention-Based Neural Map Encoding

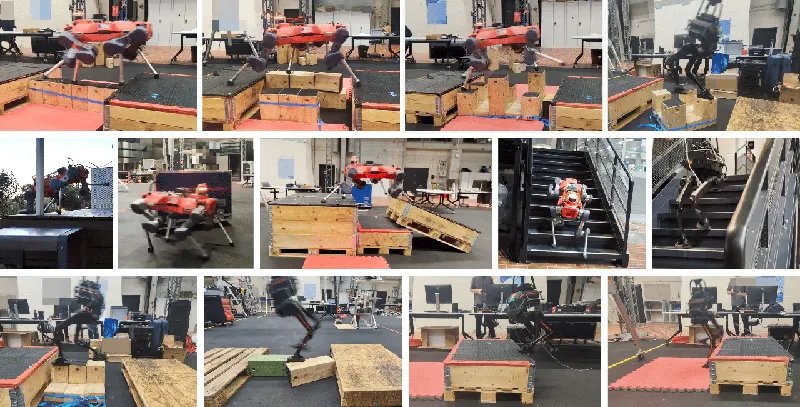
Achieving agile and generalized legged locomotion across terrains requires tight integration of perception and control, especially under occlusions and sparse footholds. Existing methods have demonstrated agility on parkour courses but often rely on end-to-end sensorimotor models with limited generalization and interpretability. By contrast, methods targeting generalized locomotion typically exhibit limited agility and struggle with visual occlusions. We introduce a unified reinforcement learning (RL) framework for agile and generalized locomotion that incorporates a novel attention-based map encoder in the control policy. This encoder extracts local and global mapping features and uses attention mechanisms to focus on salient regions, producing an interpretable and generalized embedding for RL-based control. We further propose a learning-based mapping pipeline that provides fast, uncertainty-aware terrain representations robust to noise and occlusions, serving as policy inputs. It uses neural networks to convert depth observations into local elevations with uncertainties, and fuses them with odometry. The pipeline also integrates with parallel simulation so that we can train controllers with online mapping, aiding sim-to-real transfer. We validate our framework with the proposed mapping pipeline on a quadruped and a biped robot, and the resulting controllers demonstrate strong agility and generalization to unseen terrains in simulation and in real-world experiments.

Legged LocomotionReinforcement Learning
Chong Zhang, Victor Klemm, Fan Yang · 376 views · Jan 13, 2026
HuMBLE: Human Motion-Driven Behavior Learning for Embodied Locomotion

HuMBLE: Human Motion-Driven Behavior Learning for Embodied Locomotion

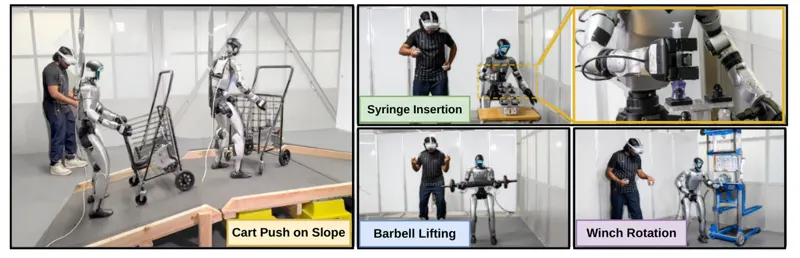
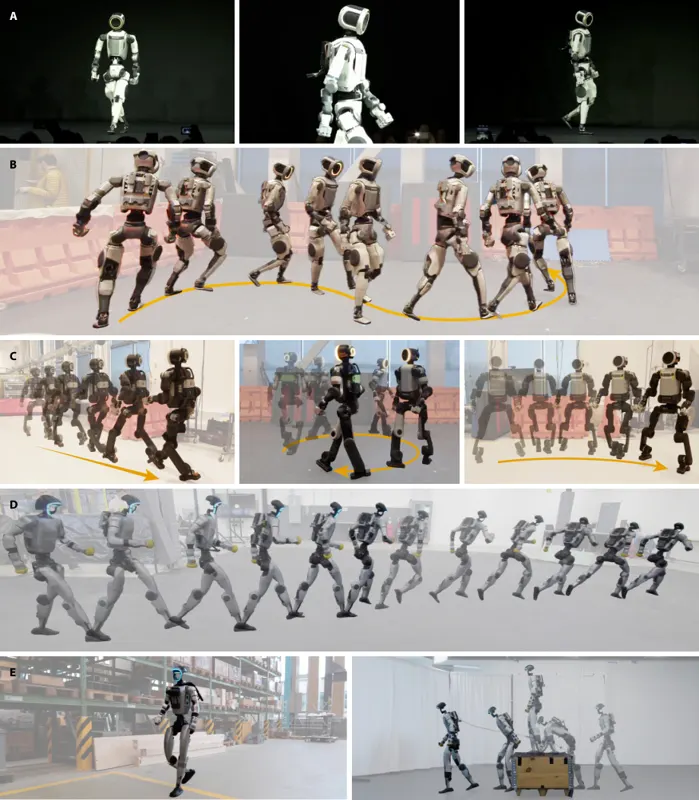
Despite recent advances in humanoid locomotion, controllers optimized for command tracking and robustness tend to produce mechanical gaits, whereas controllers tied to human motion data often fail to generalize to commands outside the data distribution. This work introduces a learning framework that balances these competing objectives to synthesize real-time steerable, robust, and biomimetic locomotion policies from human data. Using an in-house curated locomotion dataset covering diverse speeds and directions, we first learn a natural locomotion prior policy through a teacher-student distillation process. Specifically, we train a full-body reference-conditioned policy with Reinforcement Learning (RL), then distill it into a lightweight prior policy conditioned solely on proprioception and a planar torso-velocity steering command. Next, we fine-tune the prior policy with multi-task RL to expand command coverage and robustness beyond the data distribution, pairing a goal-conditioned task that tracks arbitrary commands with a reference-guided task that tracks the human data as an explicit style regularizer. We validate our framework on three humanoid robots: the Boston Dynamics Atlas R1, Atlas D1, and Unitree G1. Experimental results demonstrate robust performance across real-world scenarios, including direct user-controlled locomotion in indoor and outdoor environments, and integration as the locomotion layer within hierarchical control stacks. Benchmarks against Tabula Rasa RL policies trained without human data and ablation studies confirm that our framework yields a lightweight, deployable policy that reconstructs coordinated whole-body behavior from a steering command, retaining the human gait characteristics while remaining robust and fully steerable.

Humanoid LocomotionMotion Imitation
Mike Zhang, Dongho Kang, Kevin Bergamin · 615 views · Oct 7, 2026

As an Amazon Associate, we earn from qualifying purchases.