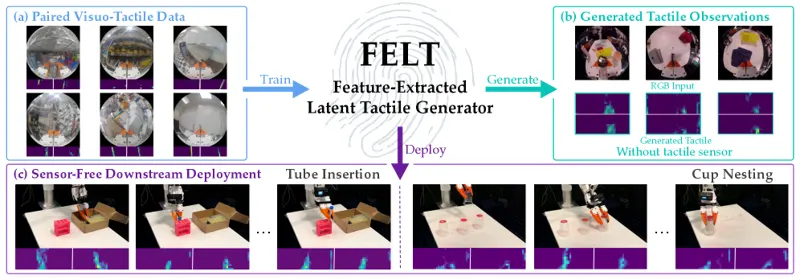
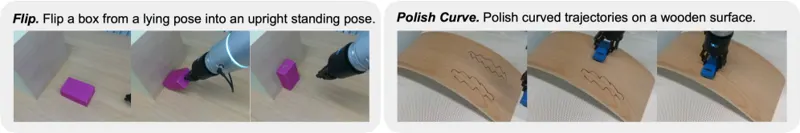
The sense of touch is central to manipulation, especially when vision is occluded or ambiguous. Although combining vision and touch improves manipulation, learning robust visuo-tactile policies requires substantial tactile data. Such data remains scarcer than visual data, because tactile sensors are fragile, specialized, and hard to standardize. To address this, we present Feature-Extracted Latent Tactile (FELT), a learning-based framework that synthesizes per-finger pressure tactile images from RGB observations, reducing the need for tactile-equipped data collection. FELT uses a large frozen visual encoder and a lightweight query decoder to predict tactile signals in a single feed-forward pass. To respect the physical topology of dual-finger tactile sensors, FELT decodes the left and right tactile sensor panels through separate branches, capturing the asymmetric contact patterns during interactions such as wiping, insertion, and in-hand rotation. At inference time, FELT only requires RGB data, allowing us to augment existing vision-only data with tactile observations, either as generated tactile images or as latent tactile features. Experiments on four contact-rich manipulation tasks demonstrate that both generated tactile images and latent tactile features improve policy success over vision-only baselines, with latent feature requiring no real tactile sensor during policy training or deployment. Supplementary material is available on our anonymous website: https://felt-tactile.github.io/.
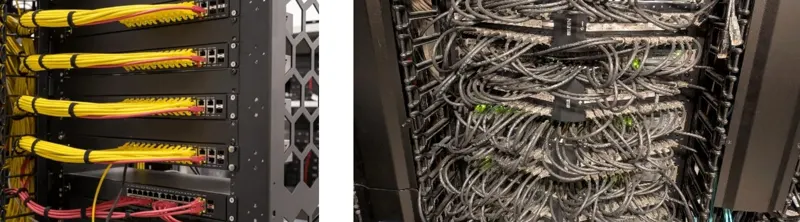
Dexterous manipulation remains a critical bottleneck in industrial automation; tasks such as cable routing, connector insertion, and precision assembly still rely heavily on manual labor despite decades of robotics research. This work presents a progression from classical, modular robotics pipelines toward an end-to-end multimodal imitation-learning framework for industrial dexterous manipulation. As a part of this work, we introduce three key contributions: a set of Industrial Dexterity Benchmark (IDB) boards aimed to mimic datacenter cable management, automotive cable harnesses, and gearbox assembly tasks; a scalable imitation learning framework (DAG-ROS); and a multimodal diffusion-based policy framework (AG-iDP3) that creates models fusing RGB images, point clouds, joint positions, and wrist-frame wrench data. Focusing on the datacenter cable manipulation board, we evaluate the performance of a task involving cleaning a single cable over variations of an end-to-end AI policy using 48 trials per configuration. The best performing configuration, a multimodal expansion Diffusion Policy (DP), includes a multi-view RGB image source passed through an R3M encoder and reaches a 78% grasp and insert combined task success rate. This performance marks a significant improvement over the 36% observed from the single-camera RGB DP baseline. Each of the tested configurations requires only approximately 100 teleoperated demonstrations per task phase. These results indicate that the correct learned policy can outperform classical vision and control robotic methods in robustness, generalization, and deployment efficiency, justifying a shift toward scalable robotic automation for high up-time industrial environments.
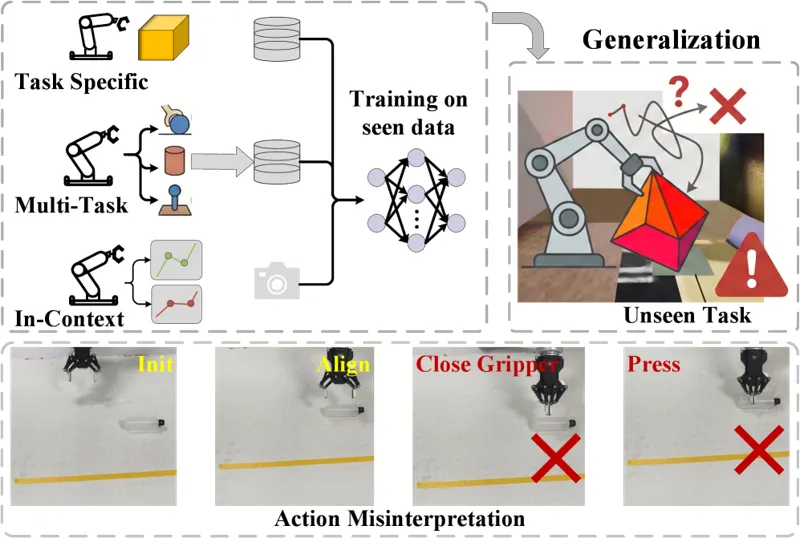
Imitation Learning aims to learn skills from extensive observations and demonstrations for robots, so it suffers from data scarcity and environment generalization. The existing methods predominantly focus on imitation from in-domain tasks and consequently struggle with generalization to unseen tasks. To bridge this generalization gap, we propose the Dynamics-Aware Meta-Imitation (DAMI) framework. By integrating meta-learning to construct a shared skill space, DAMI equips agents for rapid adaptation to novel tasks. We introduce the Visual-Motor Trajectory (VMT) module to capture complex spatio-temporal dynamics within the task latent space. Furthermore, we propose the Unpaired Unified Task (U2T) block to fuse unstructured multimodal observations. To coordinate these representations, we integrate a Task-Conditioned Feature Modulation (TCFM) mechanism customized for modulating low-level 3D features. By capturing intrinsic dynamics from a random complete reference demonstration, our framework learns the underlying task logic rather than memorizing static cues, ensuring effective generalization. Extensive experiments in both simulation and real-world settings demonstrate that our approach outperforms state-of-the-art baselines regarding direct inference on seen tasks and adaptation to unseen tasks via few-shot fine-tuning.
It has long been recognized that humans have the ability to switch between fast, reactive decision-making and slower, deliberative planning. In this paper, we study the question of how to learn this ability, known as meta-reasoning, in artificial agents. We model reactive decision-making as a policy that directly maps state observations to actions. Such policies can be trained with reinforcement learning (RL) or imitation learning, but may generalize poorly outside of their training distribution. Alternatively, model-based decision-time planning is more likely to produce good actions across a broader set of states but requires additional computation time, which delays acting. In this work, we introduce an RL method for training a meta-reasoning policy that allocates computation by conditioning on a reactive-policy uncertainty score. This score enables it to predict when the reactive policy is likely to perform poorly and when planning is needed. We conduct an empirical study on motion planning and navigation environments, showing that this design enables the meta-reasoning policy to learn when the reactive policy provides a good-enough action versus when decision-time planning is needed. Additionally, we show that our design enables the meta-agent to shift toward fully reactive control as the reactive policy improves.
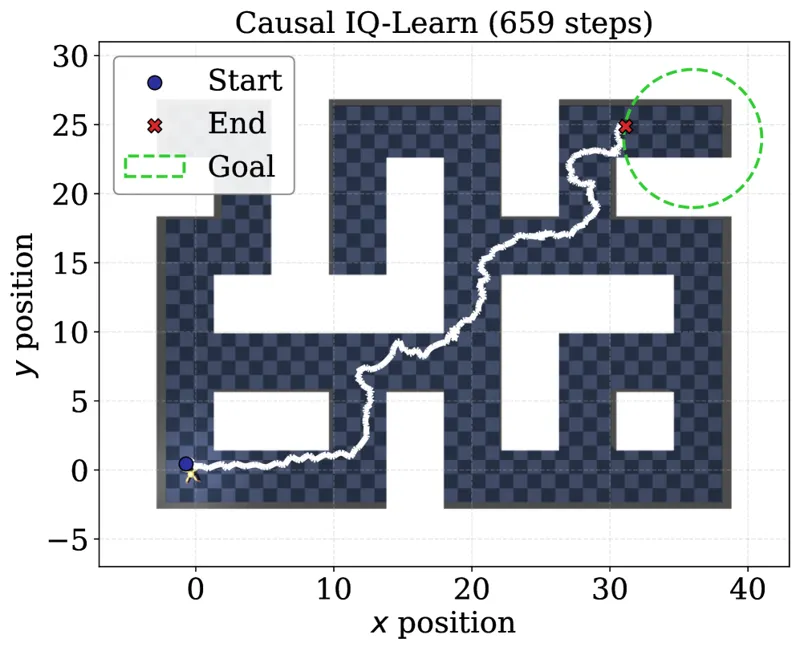
Imitation learning enables learning a policy in an unknown environment with a latent reward signal using expert demonstrations, but it struggles when the imitator's and expert's observations are mismatched and unobserved confounders are present in expert demonstrations. By identifying appropriate adjustment sets via the sequential π-backdoor criterion, causal imitation learning (CIL) provides a framework for approximating the expert's policy from confounded data. However, existing CIL methods, Causal Behavioral Cloning (Causal BC) and Causal Generative Adversarial Imitation Learning (Causal GAIL), are designed for short-horizon, low-dimensional settings. When applied to continuous control tasks with long horizons and high-dimensional state-action spaces, these methods exhibit poor performance: Causal BC suffers from compounding errors, Causal GAIL is unstable and sample-inefficient, and sequential π-backdoor adjustment becomes impractical. We introduce Causal Soft Q Imitation Learning (SQIL) and Causal Inverse soft-Q Learning (IQ-Learn), two off-policy causal imitation learning algorithms that combine the causal adjustment framework with state-of-the-art inverse reinforcement learning objectives. Both algorithms operate on causally-adjusted state representations produced by an efficient approximation of the sequential π-backdoor criterion, exploiting the causal structure of continuous control environments to reduce the full-horizon adjustment to a fixed-size sliding window. We evaluate all methods in a suite of confounded environments and find that Causal SQIL and Causal IQ-Learn substantially outperform prior CIL algorithms on long-horizon tasks, sometimes surpassing the expert, whereas all causally unaware imitation methods fail to learn meaningful behavior.
Diffusion policies have shown strong potential for robotic imitation learning, and recent extensions incorporate additional modalities to improve manipulation performance. However, these modalities often differ not only in information content but also in sensing rates and inference latencies. Existing multimodal diffusion policies typically rely on synchronous fusion or manually designed multi-frequency architectures, which either slow down high-frequency feedback or limit extensibility to new modality combinations. We propose LAG-Fusion, a latency-aware guidance fusion framework for asynchronous multimodal diffusion policy composition. LAG-Fusion allows modality-specific policies to operate at their native inference rates and contribute denoising guidance whenever available. To make asynchronous composition consistent, we derive a reference-frame rebasing rule for diffusion variables under relative action representations, enabling delayed guidance to be aligned before fusion. We instantiate LAG-Fusion in contact-rich manipulation by composing a low-frequency vision policy with a high-frequency force policy. Experiments under heterogeneous modality latencies show that LAG-Fusion improves policy responsiveness and task performance over synchronous fusion and specially designed force-aware baselines.
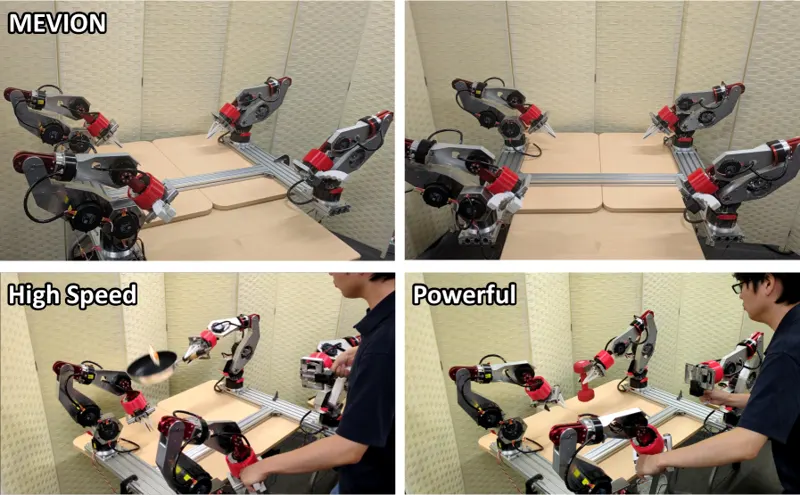
The global competition for developing robotic foundation models is intensifying. Among the data collection systems used for dual-arm robots, ALOHA is representative of being low-cost and open-source, and is widely adopted by researchers as a de facto standard. However, due to its limited ability to generate high forces and speeds, it is difficult to handle heavy objects or perform fast manipulations. To address this, we developed MEVION, a low-cost and open-source dual-arm robot data collection system capable of generating greater force and speed. All parts of this robot can be sourced through e-commerce, and by extensively utilizing sheet metal welding, its large body structure is constructed with a small number of components at low cost, while also simplifying assembly. MEVION is equipped with four 6-DoF arms with parallel grippers. Each arm weighs 7.0 kg and has a maximum torque of 60 Nm, and the entire system can be constructed for about USD 14,000. The elbow joint adopts a closed-link mechanism similar to those used in quadruped robots, which reduces the distal mass and enables higher force and speed output at the end-effector. We demonstrate that MEVION enables data collection for object manipulation tasks not previously possible and supports imitation learning-based motion generation. All hardware and software of this work are included in the Supplementary Materials or https://github.com/haraduka/mevion.
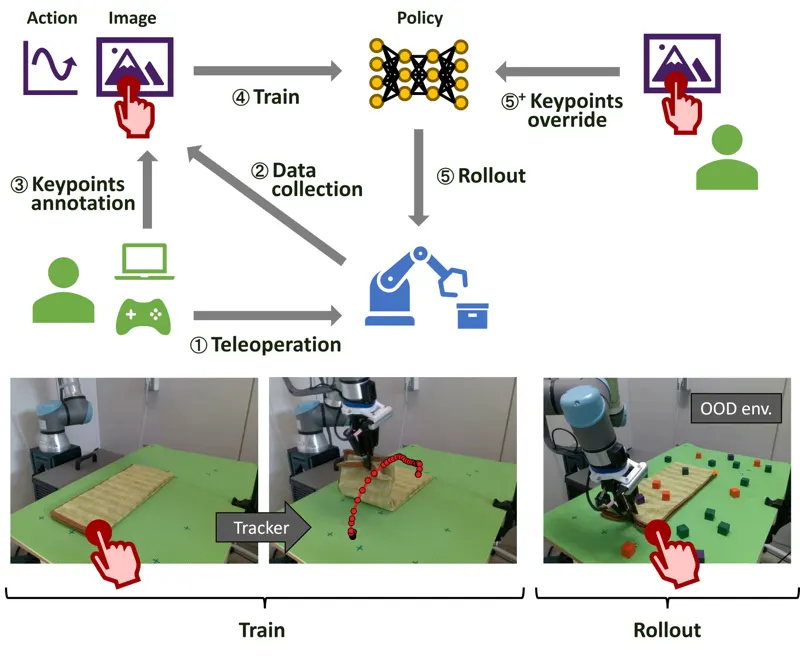
End-to-end visuomotor policies provide little opportunity for humans to understand or correct the policy's visual attention. We propose GuidedAttention, a visuomotor imitation learning framework that introduces interpretable and correctable visual attention as an explicit intermediate representation. Task-relevant attention keypoints are predicted from camera images and condition a diffusion-based action policy. Users can inspect and optionally correct selected keypoints once at rollout initialization, after which the corrected attention is automatically propagated throughout execution by a tracking module. Experiments in simulation and the real world demonstrate that GuidedAttention consistently improves robot manipulation performance, particularly under positional and appearance out-of-distribution (OOD) conditions.
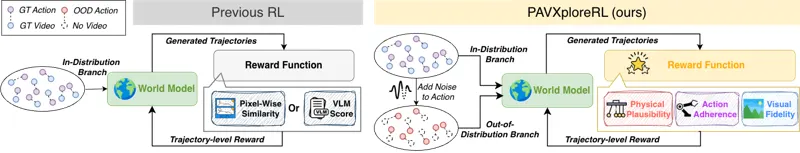
Action-conditioned world models are a key component of embodied AI, serving as scalable policy evaluators that reduce reliance on expensive real-world rollouts. To accurately capture diverse action-induced dynamics, such models should satisfy three key objectives-Physical Plausibility (P), Action Adherence (A), and Visual Fidelity (V), collectively referred to as PAV-while remaining robust to both in-distribution (ID) expert demonstrations and out-of-distribution (OOD) actions. However, existing methods primarily rely on ID action-video pairs and pixel-level reconstruction losses, which do not explicitly optimize PAV objectives and generalize poorly beyond expert data. To address this, we propose PAVXploreRL, a reinforcement learning framework built on a pretrained latent world model that explicitly optimizes PAV objectives through reward-driven training. To improve action generalization, our method jointly leverages ID trajectories and noise-driven OOD action exploration, without paired video supervision. Experiments show that PAVXploreRL consistently outperforms pretrained baselines, achieving a 5.6% average gain across benchmarks and producing higher-quality PAV properties. As a policy evaluator, it also yields more reliable performance estimates and reduces the overestimation bias of prior expert-only world models such as Ctrl-World. Code: https://github.com/Social-AI-Studio/PAVXploreRL
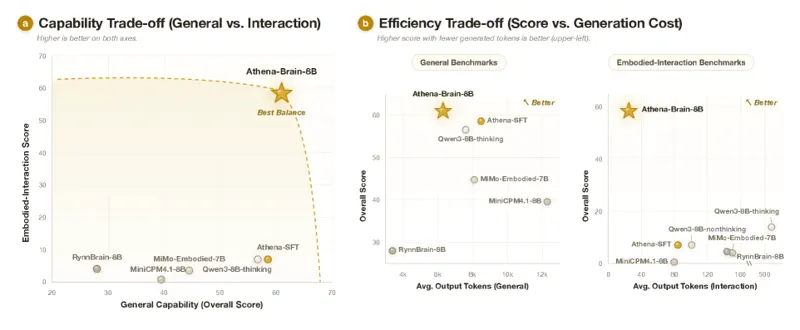
Large language models (LLMs) have demonstrated remarkable capabilities in language understanding, reasoning, and world knowledge. As embodied agents become increasingly capable, there is a growing demand for compact models that can serve as an on-device brain, preserving the broad general intelligence of LLMs while enabling effective high-level interaction with embodied environments. Existing approaches, however, often prioritize either general-purpose intelligence or specialized embodied capabilities, making it challenging to satisfy both requirements within a single model. We present Athena-Brain-8B, an 8B LLM designed to serve as an on-device brain for embodied intelligence for embodied intelligence. Through a multi-stage post-training pipeline consisting of General Supervised Fine-Tuning, General Reinforcement Learning, Embodied Expert training, and Model Merge, Athena-Brain-8B maintains strong general capabilities while acquiring strong high-level embodied interaction capabilities and generating concise responses for efficient embodied interaction. Experimental results demonstrate the effectiveness of Athena across both general and embodied evaluations. Compared with the corresponding Qwen3-8B thinking model, Athena-Brain-8B achieves comparable performance on general language and reasoning benchmarks while generating substantially shorter responses. On in-domain embodied benchmarks, Athena-Brain-8B consistently outperforms models of similar scale and surpasses several substantially larger frontier models evaluated zero-shot, demonstrating that compact language models can effectively integrate strong general intelligence with embodied capabilities.
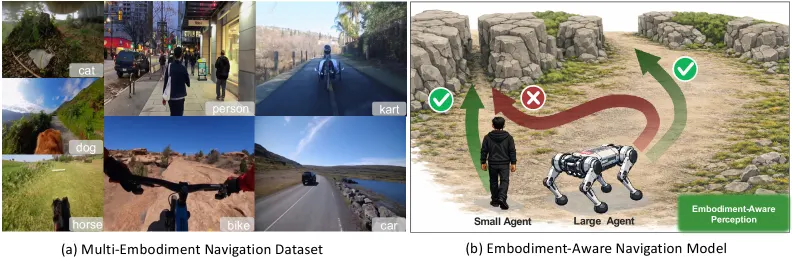
Cross-embodiment navigation is a key challenge in embodied intelligence. Due to differences in embodiment, the same visual observation may imply different actions for different agents, making prediction ambiguous when relying solely on vision. Existing studies mainly rely on reinforcement learning, which requires large-scale interaction and careful reward design, making it difficult to support scalable pretraining and real-world adaptation. In contrast, imitation-learning-based approaches remain limited. To address these challenges, we propose an imitation-learning-based embodiment-aware navigation framework with a modular multi-stage design. In pretraining, we construct a cross-embodiment navigation dataset from Internet videos and introduce embodiment geometry as conditional tokens to reduce action ambiguity under the same observation. In fine-tuning, we design a multimodal information injection mechanism based on a decoupled architecture. Specifically, we design a trajectory augmentation strategy to generate high-risk samples, which are used to train spatial perception and risk-aware correction separately, thereby explicitly incorporating embodiment geometry for safe navigation. Experimental results show that the proposed method effectively improves navigation performance across different embodiment settings, demonstrating the effectiveness of incorporating embodiment geometry into embodied navigation.
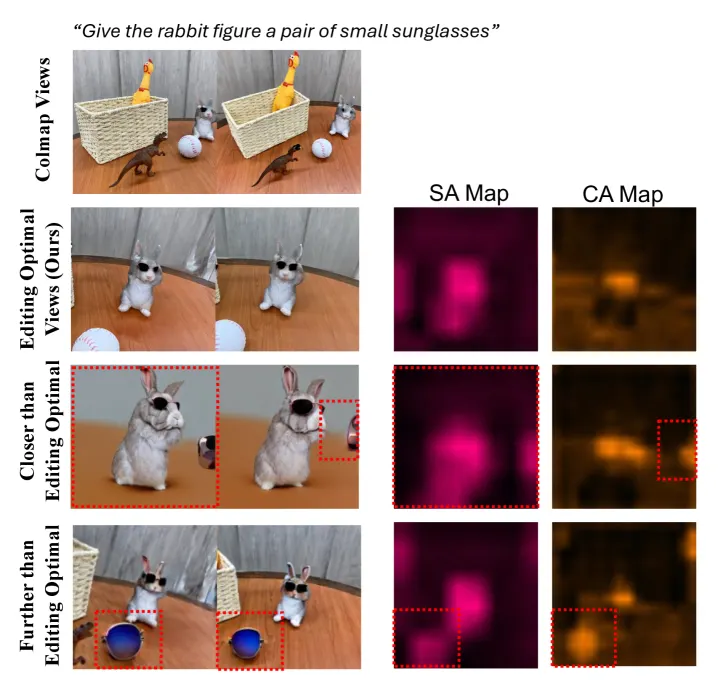
Text-driven 3D scene editing with 3D Gaussian Splatting (3DGS) typically applies a 2D diffusion editor to views rendered from fixed training cameras, limiting both the spatial coverage of edits and the user's freedom to target specific objects in complex scenes. We present LB-Edit, a framework that addresses two coupled problems: where to place editing cameras for localized edits, and how to make per-view edits agree with one another so that the 3D scene remains consistent after fine-tuning. First, Attention-Guided Editing Camera Placement (ACP) probes the diffusion model's self- and cross-attention at multiple candidate camera distances to find where attention is well-contained in the region of interest, then places a compact, geometrically diverse editing camera set at that attention-optimal distance. Second, Multi-view Attention Alignment (MAA) steers the editor toward the same edit across views along two axes: it aligns appearance by sharing self-attention features via token-level correspondence, and aligns spatial location by lifting cross-attention maps onto the 3D Gaussians as a shared 3D attention field, suppressing both appearance and spatial drift. Experiments on multi-object and single-object scenes show that our method achieves the highest user preference in instruction fidelity, multi-view consistency, and editing locality, using as few as 5 editing views and reducing latency by up to 7x over existing methods.