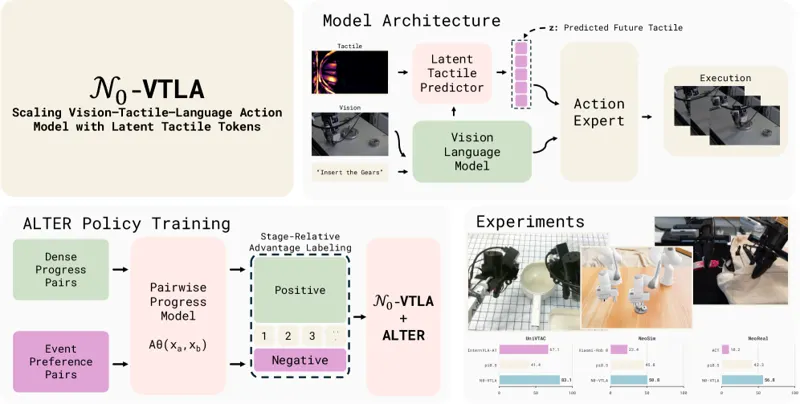
We present N₀-VTLA, a vision-tactile-language-action (VTLA) foundation model capable of (1) fine-grained contact-rich manipulation with tactile perception and tactile-feedback control, and (2) offline policy improvement from stored deployment data. Building on current vision-based backbones, we propose a training recipe for tactile integration consisting of visuo-tactile pre-training, staged tactile-pathway integration, and advantage-conditioned offline policy improvement. During pre-training, the policy learns broad contact priors from NeoData, our large-scale visuo-tactile robot dataset; to our knowledge, N₀-VTLA is the first VTLA model pretrained on tactile data at scale. During post-training, we augment the policy with a predictive tactile pathway that distills the contact patterns learned at scale into the fine motion adjustments required by downstream tactile-centric manipulation. For offline policy improvement, we introduce ALTER, an advantage-conditioned offline reinforcement learning method that converts relative progress and trajectory-event comparisons into binary advantage labels for policy training on a fixed deployment corpus, further improving task-specific learning on contact-rich skills such as deformable object manipulation. Across contact-rich benchmarks, N₀-VTLA outperforms strong baselines by wide margins: it wins all nine real-robot NeoReal tasks and reaches 63.8% mean success on a twenty-task simulation suite, against 44.0% for the strongest baseline. N₀-VTLA policies trained with ALTER reach 75-95% success on three long-horizon real-robot tasks. These results lay a foundation for versatile tactile-driven manipulation policies.
Operating constrained dynamical systems requires controllers to efficiently solve complex tasks while enforcing recursive feasibility and safety constraints. To address these competing requirements, we present Feasible Action for Optimal Control (FAOC), a novel control framework integrating Reinforcement Learning (RL) and Optimal Control (OC). The key contribution is a computationally efficient, optimization-based mapping algorithm that transforms the RL agent's action from a static abstract set into a state-dependent feasible parameter set of the Optimal Control Problem (OCP), guaranteeing strict satisfaction of the dynamical system's constraints. Thus, FAOC effectively combines the predictable safety of OC with the flexibility of RL. In contrast to prior work, the abstract action space of the RL agent does not require expert or heuristic design, and the OCP formulation is not compromised by the inability of RL to guarantee feasibility. We apply our approach to real-time motion planning for robot table tennis, which encapsulates these challenges. Via simulated experiments, we show that FAOC outperforms state-of-the-art baselines in both sample efficiency and closed-loop performance.
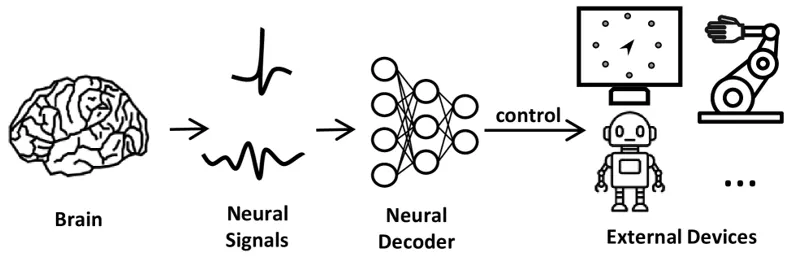
Brain-Machine Interfaces (BMIs) provide a direct communication pathway between the brain and external devices, enabling humans to control assistive and robotic technologies, with potential applications in rehabilitation, human motor augmentation, and human-centered robotics. However, due to neural drift, the performance of BMIs decreases over time, posing challenges for long-term viability, particularly for invasive BMIs (iBMIs). Existing solutions suffer from two main drawbacks: (i) difficulty in learning robust neural representations, and (ii) neglecting that neural drift varies across motor parameters (e.g., velocity, direction, and speed). To overcome these limitations, we propose Self-Supervised Consistency enhanced Disentangled Learning (SSCDL), a neural decoding generalization framework built on two key innovations. We first design a backbone model named Consistency enhanced Neural Decoder (CND), using a novel teacher-student consistency constraint with simulated neural signal perturbations to learn robust representations invariant to neural drift. Then, we employ three dedicated CNDs under the Complementary-Disentangled Generalization (CDG) mechanism, which disentangles motor signals into velocity, direction, and speed with inspiration from neural preference theory. This disentangled learning enables SSCDL to capture invariant neural representations from diverse neural preference perspectives, significantly enhancing cross-day generalization. Extensive experimental results show that SSCDL delivers state-of-the-art decoding performance, exhibiting high robustness and cross-day stability. These capabilities underscore its strong potential for long-term interaction in human-centric robotic and fine-grained assistive applications.
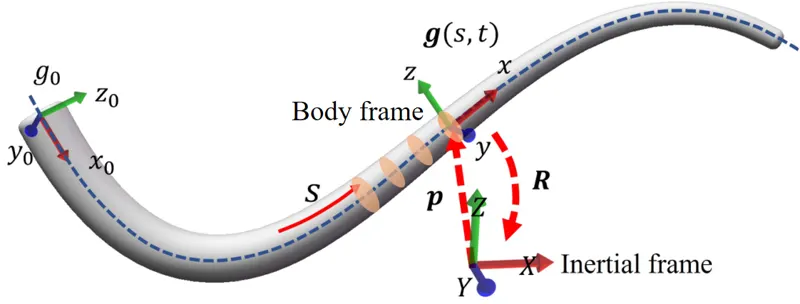
Precise control of soft manipulators remains challenging due to the difficulty of developing accurate yet computationally tractable models for model-based estimation and control. Reduced Cosserat-rod models provide a physics-based and control-oriented description of soft-robot dynamics, offering an explicit alternative to purely data-driven input-output representations. In this paper, we propose a moving-horizon estimation (MHE) and nonlinear model predictive control (NMPC) framework for cable-driven soft manipulators based on reduced Cosserat dynamics. A smooth cable-length-driven modeling formulation is developed by approximating the complementarity relationship between cable tension and cable slackness, enabling cable-length control without direct tension sensing. Based on this formulation, an MHE method is introduced to estimate the reduced state and reconstruct the manipulator configuration from end-effector pose measurements and cable-length information. An NMPC controller is then formulated to achieve task-space control under cable-length and cable-rate constraints. The proposed framework is validated through numerical simulations and experiments. Simulation results demonstrate the effectiveness of the estimator and controller for pose and strain-related regulation on a multi-cable soft manipulator. Experimental results on a four-cable prototype further show that the proposed MHE-NMPC scheme can be implemented in real time and enables accurate end-effector position tracking through cable-length control.
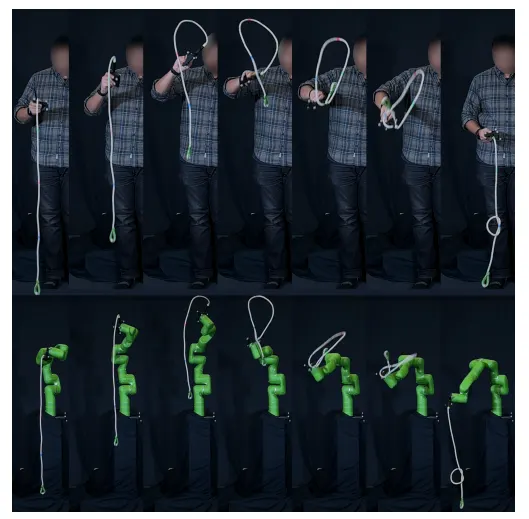
Bridging the sim-to-real gap is a central problem in robotics, and the prevailing approach is to build increasingly accurate simulators. Here, we propose another approach based on renormalization: using effective, resolution-dependent parameters to absorb details omitted by the simulator and reproduce real behavior. These parameters may differ from measured physical values because they compensate for what the simulator leaves out. We demonstrate this mechanism analytically for proportional–derivative (PD) control at finite simulation frequency, where proportional feedback changes the effective derivative gain and derivative feedback changes the effective inertia. We then interpret dynamic rope manipulation and underwater swimming through the same perspective. Finally, we present a practical procedure for choosing observables, identifying omitted physics, and determining effective parameters. Renormalization offers robotics a complementary path across the sim-to-real gap: effective parameters, real behavior.
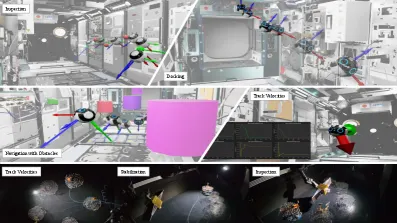
Autonomous free-flying robots in orbital environments require controllers that are both versatile and resource-efficient, yet maintaining a separate, task-specific policy for each mission profile is architecturally brittle and limits operational flexibility as requirements evolve. We introduce HYPER-GNC, a multi-task reinforcement learning framework in which a hypernetwork maps physics-informed task embeddings to the weights of a shared actor-critic policy, enabling a single compact controller to master four distinct GNC tasks: velocity tracking, docking, inspection, and navigation with obstacle avoidance. The continuous embedding space allows the controller to generalize to novel mission configurations at deployment time without any retraining. Extensive experiments demonstrate that HYPER-GNC achieves sample efficiency comparable to single-task specialists while maintaining stability under significant inertial perturbations and external body wrenches. We further validate the framework on a physical satellite emulator, successfully bridging the simulation-to-reality gap across all mission profiles. Code, trained models, and deployment scripts are made publicly available to support reproducibility.
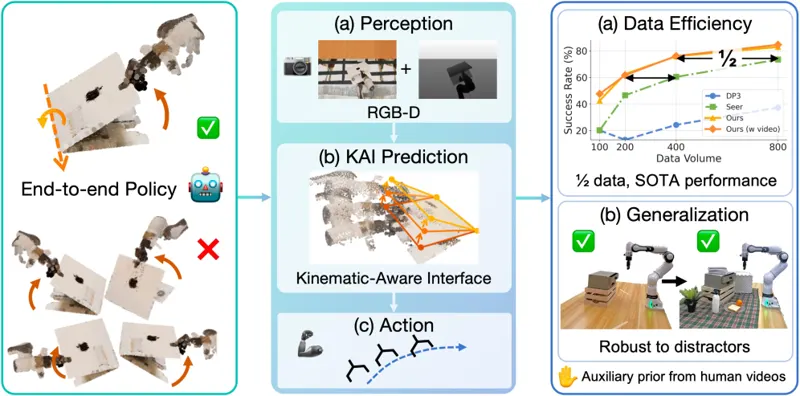
Articulated object manipulation requires an understanding of kinematic structure that is difficult and costly to learn from robot demonstrations alone. We introduce the Kinematic-Aware Articulation Interface (KAI), a structured intermediate representation that captures the kinematic structure of articulated objects. By embedding interpretable geometric and kinematic priors into policy learning, KAI provides a strong inductive bias aligned with the underlying structure of articulated motion. This design effectively improves sample efficiency, with gains particularly pronounced in low-data regimes: across six simulation tasks, our method achieves an average success rate of 82.9%, matching or surpassing baseline performance while using only half the demonstration data. Our method also exhibits robust generalization to unseen backgrounds and visual distractors, transferring from a single clean training environment to cluttered real-world scenes. KAI's action-agnostic design further enables co-training with human interaction videos to enhance real-world robustness: under diverse visual distractions, our method with video co-training achieves over 70% average success rate.
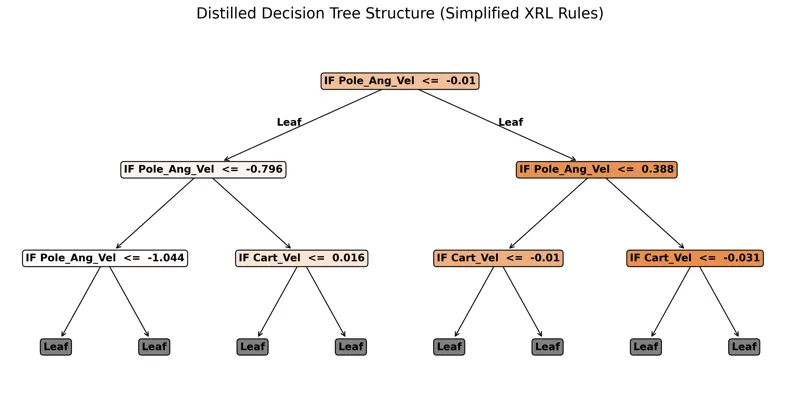
In safety-critical sectors such as robotics and automotive engineering, the deployment of Deep Reinforcement Learning (DRL) is often hindered by the black-box nature of deep neural networks. This lack of transparency poses significant challenges for regulatory compliance and human-agent trust. This paper presents an experimental study aimed at making high-performance continuous control DRL systems interpretable. A policy distillation framework is implemented using the classic Inverted Pendulum benchmark. A high-performance Twin Delayed DDPG (TD3) agent serves as an opaque, continuous teacher model, whose policy is distilled into an interpretable student surrogate based on a shallow Decision Tree. By leveraging a custom physics-aware feature and "Noisy Oracle Rollouts" for dataset generation, the distillation process achieves performance equivalent to the expert teacher. Furthermore, comparative control theory analysis reveals a fundamental trade-off: transitioning from continuous to discrete rule-based control induces high-frequency Bang-Bang actuation and a stable bimodal limit cycle. Simulation results indicate that Bounded-Input Bounded-Output (BIBO) stability is maintained while providing both global and local interpretability for safe autonomous systems.
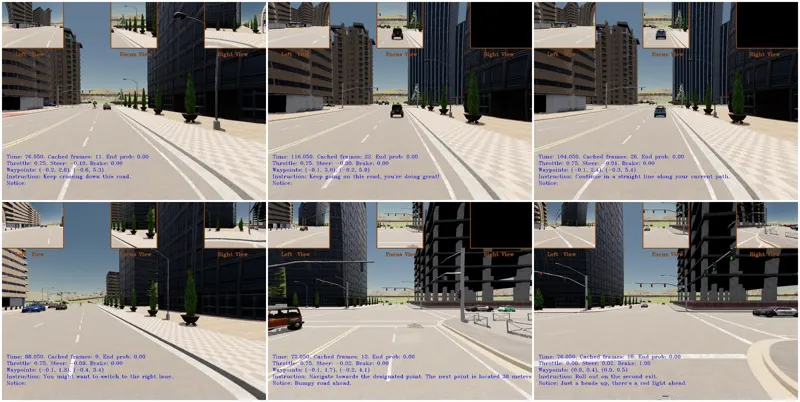
Large language models bring instruction following and scene reasoning to end-to-end driving, but their inference latency collides with the control rate a vehicle requires. Existing closed-loop agents hide this gap by invoking the model on alternate simulation ticks and replaying the previous command in between, so half of all control outputs ignore the newest observations. We present a fast-slow architecture that removes this compromise. A frozen 7B vision-language backbone acts as the slow system, digesting navigation instructions and visual history at low frequency while exposing its per-layer key-value cache as a standing representation of the scene. A lightweight action expert acts as the fast system, attending to this cache and to the current camera frame at every simulation tick to regress waypoints in a single forward pass. Since the cache lags behind the world at deployment, we train the expert under randomized staleness, aligning training with asynchronous execution. On LangAuto-Short routes in CARLA, our system produces fresh control at every 50 ms simulation tick and lifts route completion from 37.0 to 94.0 over the frame-skipping baseline. A frame-skip ablation with the same expert separates the two factors at work: the expert raises the driving score on its own, while per-tick freshness raises completion from 82.1 to 94.0 and cuts red-light violations by a third. Trained on a single town, the expert transfers zero-shot to two unseen towns, holding 84-94% route completion where the baseline reaches 31-41%. It reduces open-loop waypoint error by nearly a factor of four compared to the backbone's own action head, at a per-tick model cost of 32 ms that is independent of history length on a single consumer GPU.
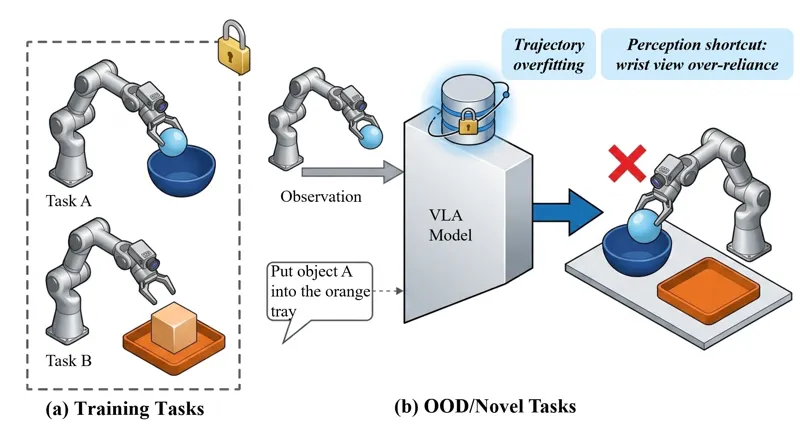
Vision-Language-Action (VLA) models excel at end-to-end robotic manipulation but struggle with out-of-distribution (OOD) generalization when familiar sub-tasks are recombined in unseen configurations. We identify two mutually reinforcing failure modes: trajectory overfitting, where models overfit to holistic trajectory patterns rather than compositional sub-skill semantics; and perceptual shortcut, where action tokens over-rely on wrist-view textures at the expense of global spatial grounding. To address both, we introduce AC-VLA, a plug-and-play Action Compositional learning framework comprising two architecture-agnostic components: (i) a compositional learning module that uses an LLM-driven instruction decomposer and a proprioceptive trajectory aligner to generate dense sub-task supervision, followed by mixed training on complete demonstrations and decomposed data to endow the model with compositional generalization; and (ii) a state-conditioned asymmetric masking strategy that suppresses wrist-view inputs during closed-gripper phases, enforcing global semantic grounding. All components are architectural modification-free and directly integrable into any VLA backbone. Instantiated on π_0.5 and evaluated on LIBERO and LIBERO-OOD benchmarks, AC-VLA achieves a ~28% absolute improvement on compositional OOD tasks while maintaining near-perfect in-distribution performance.