GTA-2: Modular VLM Framework for Zero-Shot Robot Manipulation That Beats pi0.5 Without Demonstrations
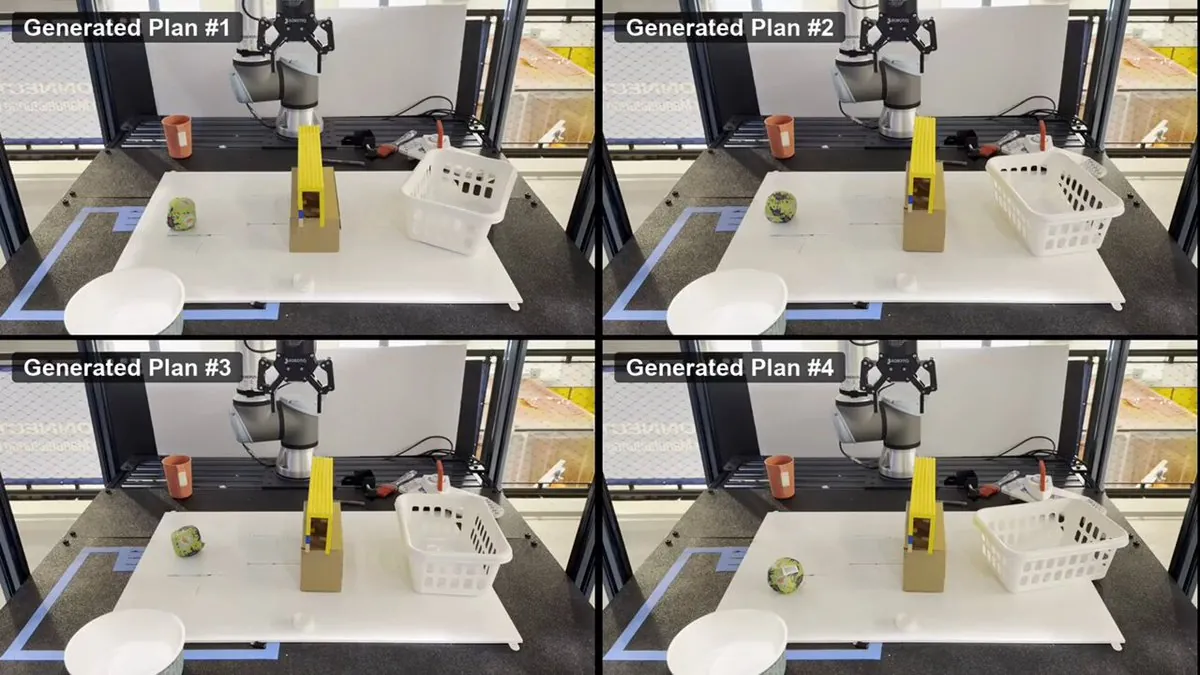
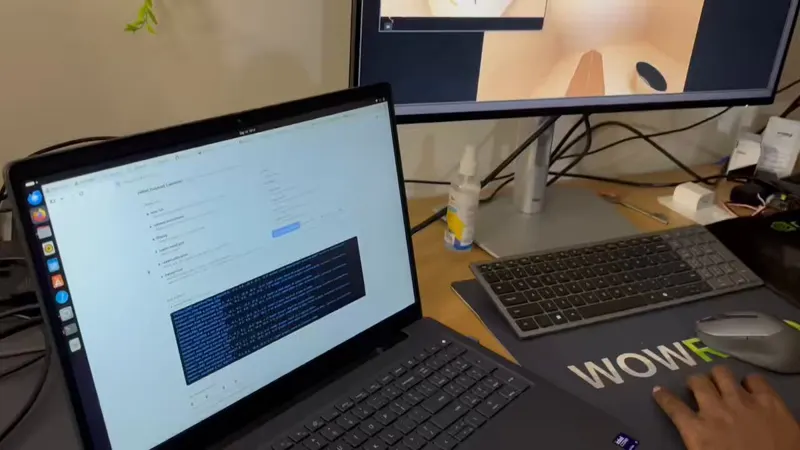
Leo Kharon posted a 100-second walkthrough of GTA-2 (Grounded Task Axes, Version 2), a modular vision-language-model framework plus benchmark for zero-shot robot manipulation that generates new manipulation behaviors from a natural-language instruction with no task-specific demonstrations, policy training or fine-tuning. Four specialized VLM agents run in sequence: decompose the task into ordered subtasks, generate an abstract skill from object-centric task-axis components, assign numerical parameters, and ground keypoints and axes in the image. The design deliberately separates reasoning about what the task means from the geometry and control that execute it: a manipulation is represented as semantic subtasks plus task-relevant keypoints and axes, controller compositions and scene-dependent parameters, so a failure can be corrected at one stage without retraining. The capture walks the five-stage interface (Task Decomposer, Skill Generator, Parameter Setter, Keypoint Module, Robot Script); the decomposed subtasks read as move above the ball, close the gripper, lift and carry it over the white basket, then release, and parameters such as a 30 cm lift height are generated before the robot script runs. Real-arm footage shows four generated plans executed on a tabletop scene with a yellow object and a white basket. The headline claim: GTA-2 beats pi0.5 with zero robot demonstrations.