TEMPO Gives a VLA a Short Memory for Dynamic Manipulation
Loading video
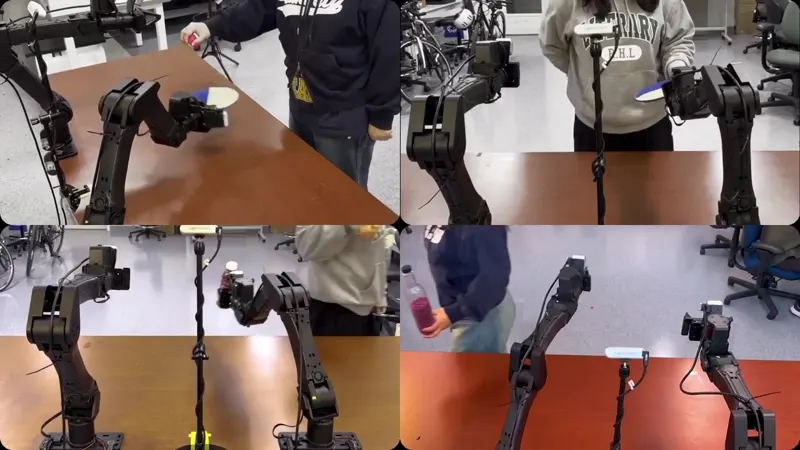
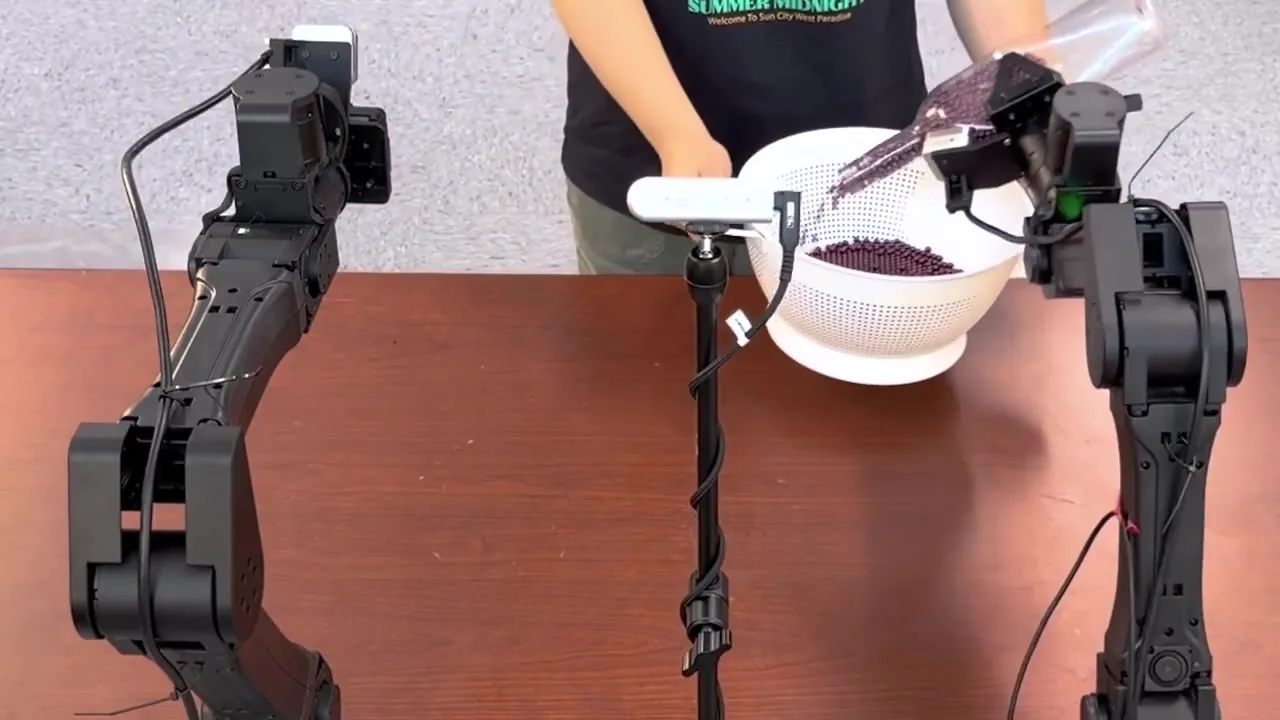
Loading videoA VLA looking at a single frame cannot tell which way a moving bottle is heading. TEMPO gives the policy a short memory: a frozen video foundation model summarizes recent scene motion and a compact proprioceptive history disambiguates visually similar moments, lifting dynamic bottle handover from 44% to 74% success.
VLADynamic ManipulationTemporal ContextMotion PerceptionVideo Foundation ModelI2RT YAM UltraVision-language-action (VLA)
Category: arm
Author: @heetezition
Date: 2026-09-17T00:00:00
Duration: 72.8s
Reference: https://arxiv.org/abs/2609.16864