TEMPO: Adding Temporal Context to a Pretrained VLA for Dynamic Manipulation
Loading video
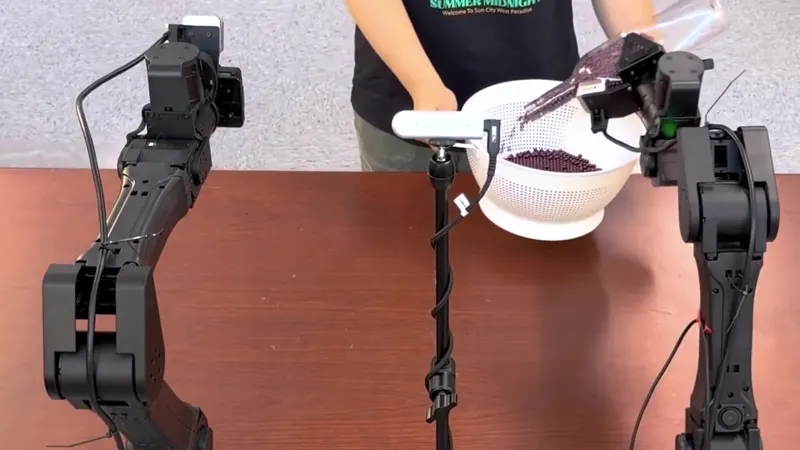
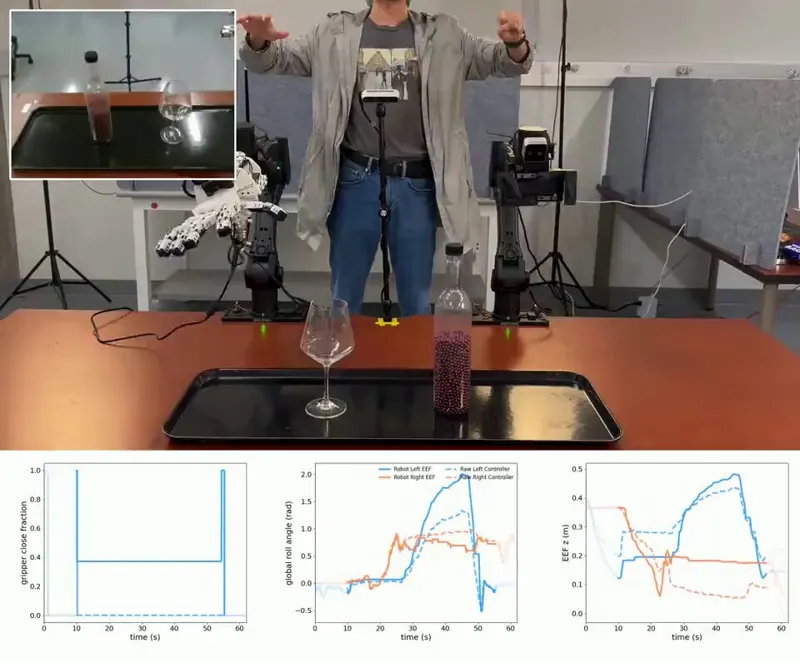
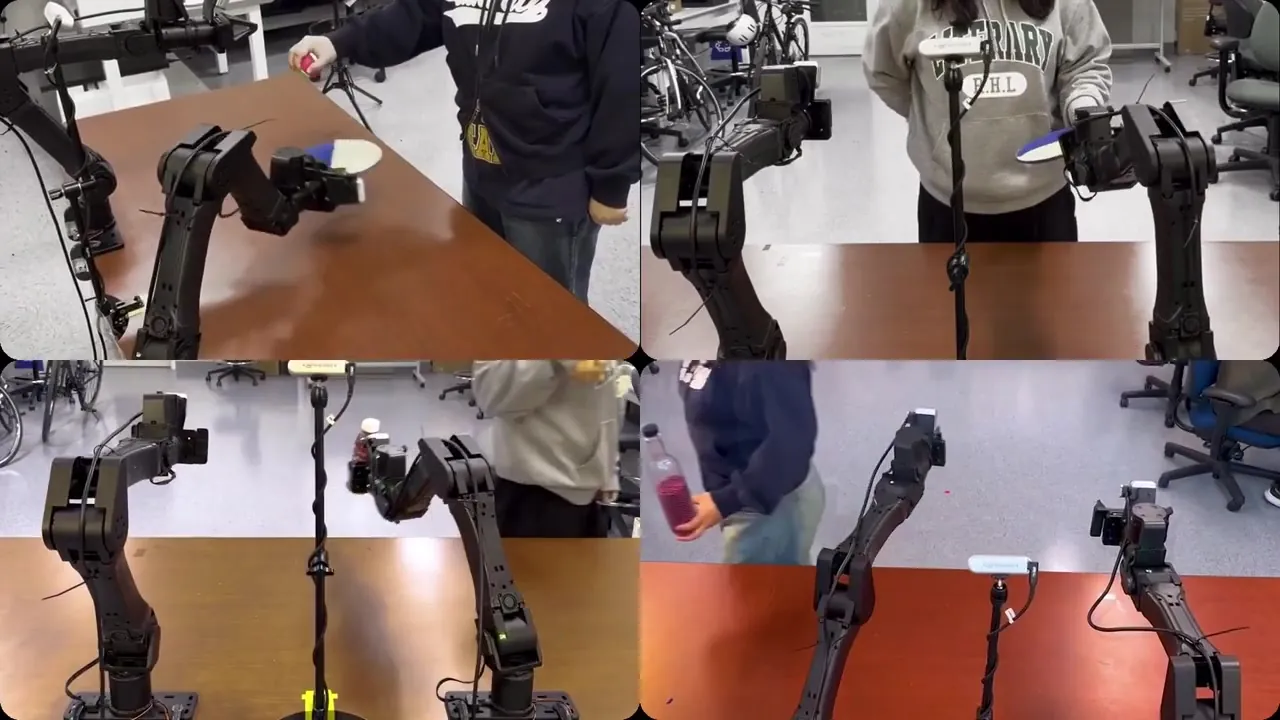
Loading videoA VLA sees a single frame, so it cannot anticipate where a moving object is heading. TEMPO adds two temporal inputs to a pretrained VLA without touching the backbone: a motion summary from a frozen video foundation model, plus a compact proprioceptive history. On a bimanual workstation with two 7-DoF I2RT YAM Ultra arms and three cameras, Bottle Handover success rises from 44% to 74% and Flick Catch reaches 66%.
VLADynamic ManipulationTemporal ContextBimanual ManipulationMotion PerceptionUC IrvineI2RT YAM UltraVision-language-action (VLA)Dual-arm manipulation
Category: arm
Author: @techniahqrobot
Date: 2026-09-17T00:00:00
Duration: 23.666s
Reference: https://arxiv.org/abs/2609.16864