Real-Time EXPO-FT: Reliable VLA Fine-Tuning
Loading video
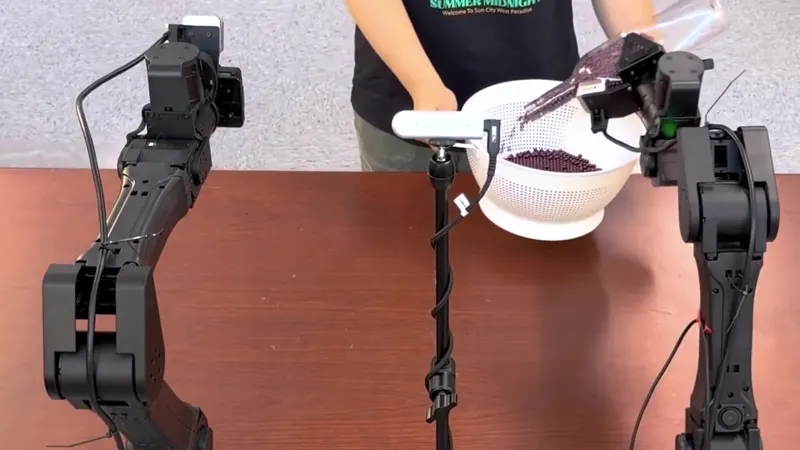
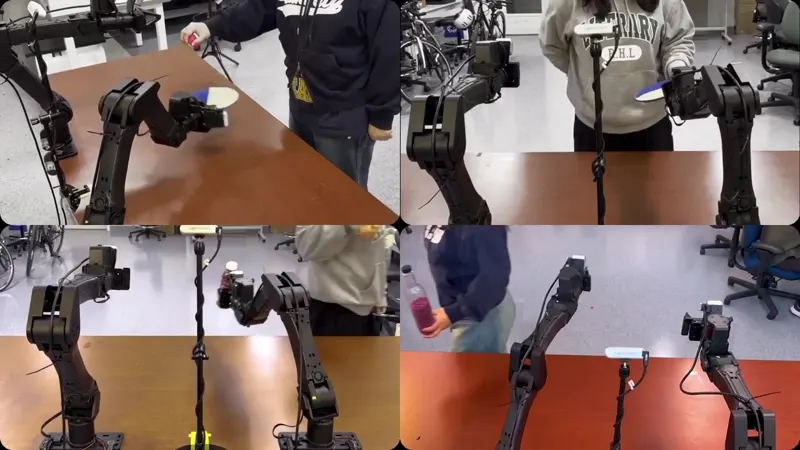
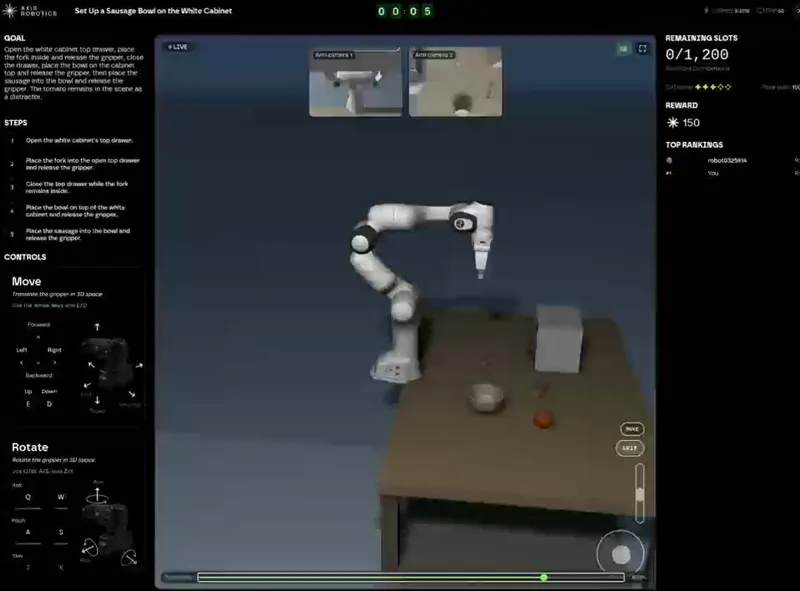
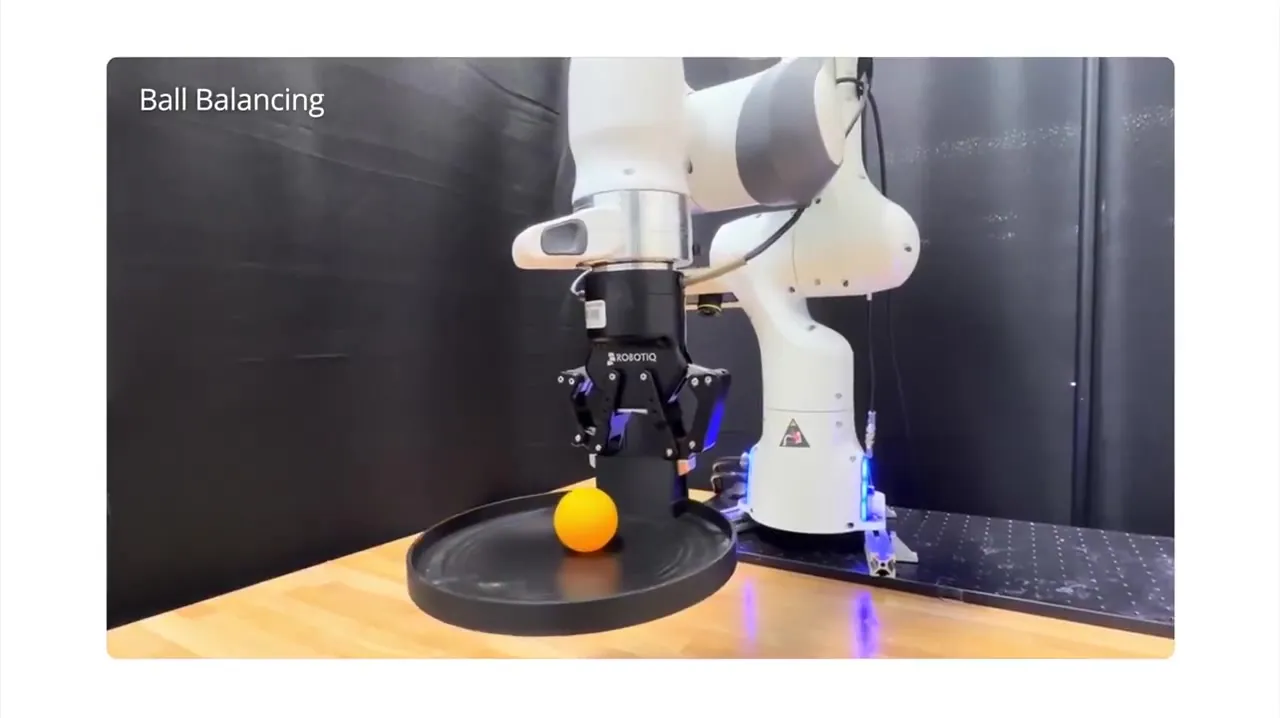
Loading videoA lightweight edit policy corrects VLA action candidates using the latest observation, while value-based selection trains the policy; four dynamic real-robot tasks improve from 42% to 97% within 10 minutes of online data.
VLARobotic ManipulationReinforcement LearningReal-time controlStanford UniversityVision-language-action (VLA)Robot Manipulation
Category: arm
Author: @robotsdigest
Date: 2026-09-24T00:00:00
Duration: 59.875s
Reference: https://arxiv.org/abs/2609.18207