RoboPrompt: Intuitive Robot Policy Steering with Sparse Human Input
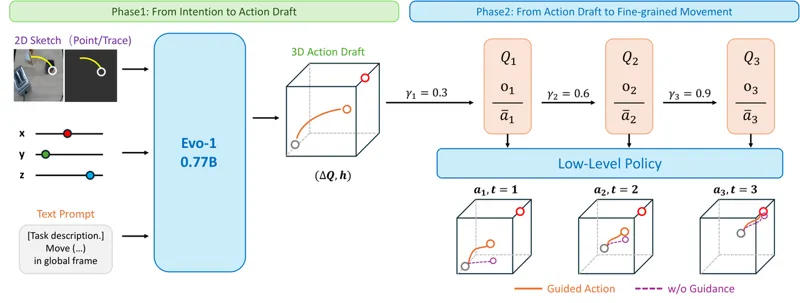
End-to-end robot policies trained through imitation learning remain constrained by limited data diversity, making reliable zero-shot deployment in real-world settings challenging. Shared-autonomy methods enable human correction through teleoperation, but specialized hardware and operator training hinder deployment at scale. Other approaches incorporate human guidance as additional policy inputs, often requiring architectural changes and dedicated training for steerability, which limits their applicability across policies. We present RoboPrompt, a general-purpose, lightweight robot policy steering system that enables users to guide policy behavior through intuitive, sparse inputs, including drawn traces, target points, and coarse directional instructions. RoboPrompt decouples human-intention translation from the underlying policy: a reusable module converts human guidance into action drafts, which are refined through the diffusion or flow-matching dynamics of the base policy. By controlling action generation in noise space, RoboPrompt balances human intent with the policy prior without modifying the base policy architecture or fine-tuning it for steerability. Experiments demonstrate effective steering across Diffusion Policy, π_0.5, and FastWAM. We further use steered rollouts for online policy improvement through DAgger. After 2-3 rounds of iteration, average success rates increase by 15.5% for π_0.5 across three tasks and by 21.3% across three policies(Diffusion Policy, π_0.5, FastWAM) on the Insert Bread task, while average human intervention counts decrease by 44.0% (2.86 to 1.60) and 81.9% (2.60 to 0.47), respectively.
Yanwen Zou, Chenyang Shi, Guoxuan Xu · 278 views · Oct 7, 2026
ManipulationImitation LearningDiffusion policiesOct 7, 2026
 1:34