Skip to content
← Tags

#Vision-language navigation (19)

StageVLN: Spatial and Trajectory Auxiliary Guidance for Efficient Vision-Language Navigation

StageVLN: Spatial and Trajectory Auxiliary Guidance for Efficient Vision-Language Navigation

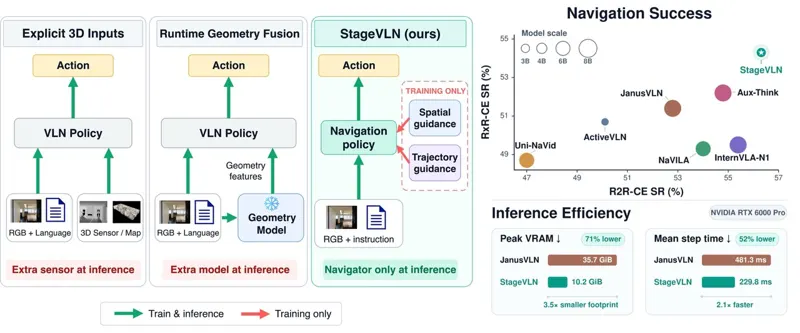
Vision-and-Language Navigation (VLN) policies increasingly benefit from strong semantic priors provided by large vision-language models (VLMs). However, standard action supervision does not explicitly encourage intermediate representations to preserve scene geometry, relative orientation, or global episode progress. Incorporating depth estimators, explicit maps, point clouds, or geometry foundation models at inference can provide such structure but introduces additional computation, memory overhead, and architectural dependence during deployment. We introduce StageVLN, a training framework that shapes navigation representations through privileged spatial and trajectory guidance while preserving the original inference pathway. A frozen geometry foundation model provides multi-level spatial guidance to hierarchical navigator states, while relative-heading and expert-route progress objectives provide complementary trajectory-state supervision. All auxiliary components are used only during training and removed at deployment. On R2R-CE validation-unseen, StageVLN achieves 56.3% SR and 51.4% SPL with a 4B-parameter backbone, without an additional geometry encoder at inference. On RxR-CE, it achieves 54.3% SR without additional navigation training data or a geometry encoder at inference.

Anh Dao, Quan-Dung Pham, Le Danh Vinh · 98 views · Oct 5, 2026
Vision-language navigationEmbodied AI
Oct 5, 2026
SimpleVLN: Towards Simple and Frontier Vision-Language Navigation

SimpleVLN: Towards Simple and Frontier Vision-Language Navigation

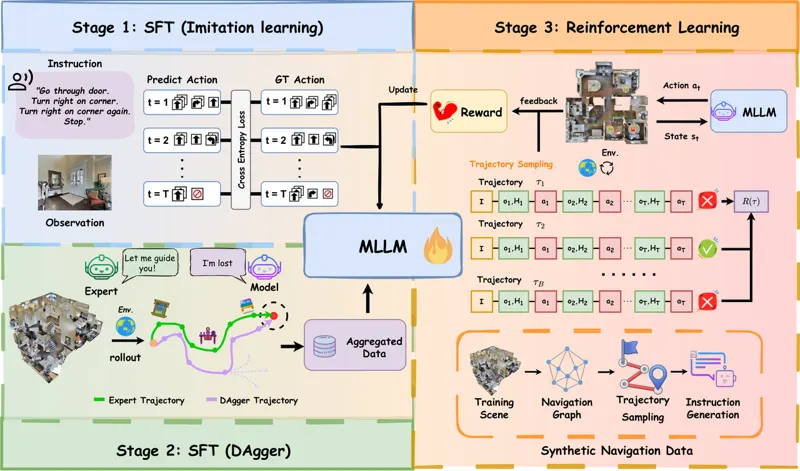
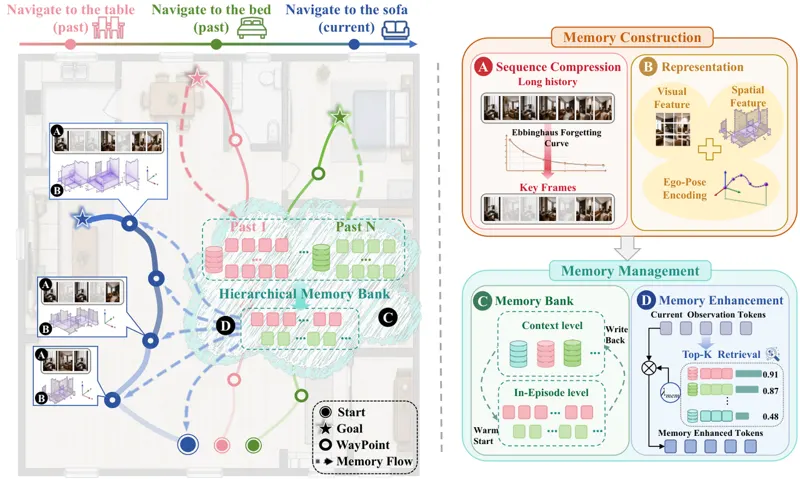
Vision-and-Language Navigation (VLN) requires embodied agents to ground language in visual observations and make long-horizon decisions. Existing methods often address these demands through task-specific architectures. As multimodal large language models (MLLMs) become increasingly capable, an important question remains: Have we truly unlocked the potential of native MLLMs for VLN before introducing task-specific architecture? We present SimpleVLN, an architecture-preserving framework developed through studies of navigation formulation, data construction, and optimization. At the formulation level, SimpleVLN combines single-turn decision inputs with fixed-budget global-local memory to efficiently use navigation history without unbounded context growth, while action chunks enable efficient output of multiple primitive actions per model invocation. For data construction, we combine expert demonstrations with policy-dependent DAgger experience and develop a scalable synthesis pipeline that generates large-scale tasks for reinforcement learning. At the optimization level, a progressive IL-DAgger-RL pipeline advances from action imitation to task-level outcome optimization. Comprehensive experiments validate the effectiveness of these three aspects. We instantiate SimpleVLN across multiple MLLM backbones and model sizes, demonstrating its generality. SimpleVLN achieves 76.7% and 80.1% success rates on the R2R-CE and RxR-CE splits, respectively, substantially outperforming existing methods. These results show that the navigation capabilities of native MLLMs can be effectively unlocked without task-specific architectural designs.

Lingyi Hong, Weiren Cai, Jiayu Chen · 163 views · Oct 16, 2026
Vision-language navigationEmbodied AI
Oct 16, 2026
ASENA: Self-evolving Agents for Embodied Navigation

ASENA: Self-evolving Agents for Embodied Navigation

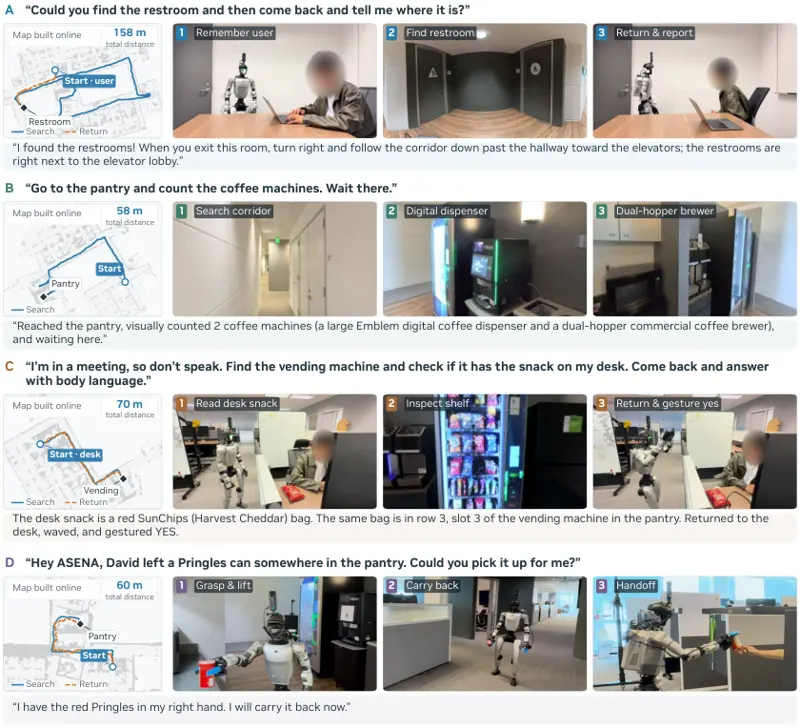
We present ASENA, an embodied agent system that enables general-purpose coding agents to program humanoid navigation, manipulation, and interaction. Through a unified robot harness, agents read sensor data, write and execute programs, inspect recorded outcomes, repair failures, and reuse notes and executable skills while keeping their model weights fixed. We also introduce ASENA-VLN, a 4B monocular navigation policy that serves as an optional tool within this programmable system. ASENA-VLN predicts body-frame trajectories for both extended routes and short-horizon behaviors. Its shared vision-language decoder is trained on route instructions, visual question answering, and a newly curated dataset of geometry-derived atomic navigation tasks. As a standalone policy, ASENA-VLN achieves state-of-the-art success rates of 68.7% on R2R and 70.2% on RxR. When integrated with a coding agent, learned navigation improves ASENA's success rate by 11 percentage points on both agentic benchmarks and reduces execution time. Persistent workspace evolution uses simulator feedback to improve success over ten passes through recurring 100-task subsets. Success increases from 72% to 98% on R2R and from 65% to 89% on RxR. On embodied question answering, ASENA achieves state-of-the-art accuracy with fewer interaction steps. On a Unitree G1, we demonstrate search, visual inspection, spatial reasoning, synthesized gestures, and mobile manipulation combining object pickup, carrying, and handoff without a pre-built map. These demonstrations illustrate how online programming extends robot behavior beyond route following and predefined skills.

An-Chieh Cheng, Isabella Liu, Edmund Bu · 299 views · Sep 30, 2026
Vision-language navigationEmbodied AI
Sep 30, 2026
LifelongCrossNav: Persistent 3D Semantic Memory for Cross-Floor Multi-Object Navigation

LifelongCrossNav: Persistent 3D Semantic Memory for Cross-Floor Multi-Object Navigation

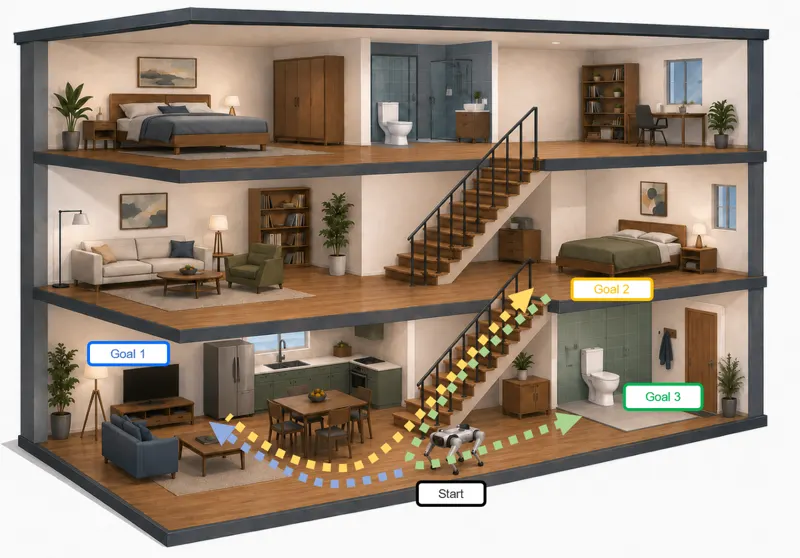
Object-goal navigation has made substantial progress in semantic perception and exploration, yet persistent memory for multi-object navigation and cross-floor navigation are still commonly addressed separately. We present LifelongCrossNav, a framework for sequential multi-object ObjectNav in unknown multi-floor indoor environments. Within each episode, the agent receives an ordered sequence of object-goal queries while continuously maintaining a shared sparse 3D semantic voxel memory. This memory incrementally accumulates geometric structure, traversability states, and vision-language features, allowing subsequent object-goal queries to retrieve previously acquired scene information without rebuilding the map. To support persistent search across floors, LifelongCrossNav combines support-aware 3D traversability mapping, stair-specific perception, and direction-aware stair traversal. A unified navigation policy coordinates same-floor frontier exploration, live and historical point-of-interest retrieval, stair navigation, and target-object search and approach. We further introduce HM3D-MFMON, a benchmark for sequential Multi-Floor Multi-Object Navigation built on HM3D scenes, including a dedicated subset in which completing the full sequence of object-goal subtasks requires at least one floor transition. Experimental results show that LifelongCrossNav consistently outperforms a representative planar persistent semantic-map baseline on HM3D-MFMON, demonstrating that persistent 3D semantic memory and cross-floor traversability modeling effectively support sequential multi-object navigation in multi-floor environments. Project page: https://flageval-baai.github.io/LifelongCrossNavPage.

Zehui Li, Zihao Sun, Jiawei Xu · 302 views · Aug 7, 2026
Object-Goal NavigationSemantic Memory
Aug 7, 2026
See-and-Reach: Precise Vision-Language Navigation for UAVs within the Field of View

See-and-Reach: Precise Vision-Language Navigation for UAVs within the Field of View

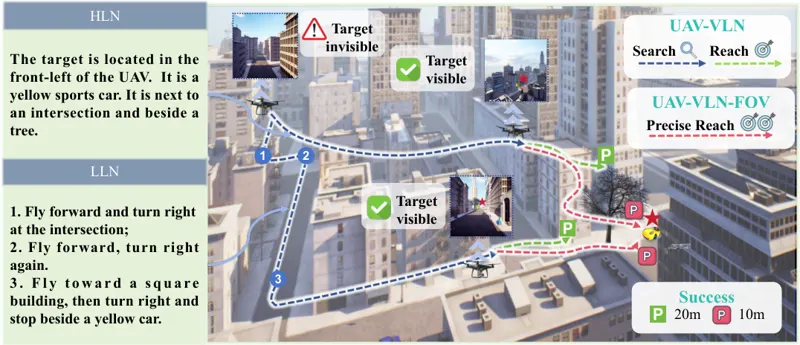
UAV Vision-Language Navigation (UAV-VLN) is typically formulated as a holistic search-and-reach problem, where long-range target discovery and final target approach are optimized and evaluated jointly. This formulation makes it difficult to assess a critical capability of aerial embodied agents, namely whether a UAV can accurately ground a visible target and translate vision-language evidence into precise 3D motion once the target enters its field of view. To address this limitation, we introduce UAV-VLN-FOV, a target-visible navigation task that isolates the see-and-reach stage and enables a more diagnostic evaluation of terminal reaching ability. We further propose 3DG-VLN, a vision-language waypoint prediction framework guided by dynamic 3D direction cues to enhance fine-grained visual grounding and spatial direction alignment for precise target reaching. Specifically, 3DG-VLN adaptively processes high-resolution front-view and downward-view observations to preserve fine-grained visual and geometric details for target grounding. It also updates the target-relative direction online during closed-loop navigation, allowing the agent to maintain spatial alignment with the target and reduce accumulated direction drift. To support this task, we construct a dedicated high-resolution benchmark which contains 2,717 trajectories with target-oriented high-level instructions, high-resolution front-view and downward-view egocentric observations, and continuous 3D waypoint annotations. Experiments show that 3DG-VLN outperforms competitive UAV-VLN baselines, achieving a 13.82% improvement in success rate. Real-world trials further demonstrate the potential of 3DG-VLN for practical see-and-reach navigation. The source code and benchmark are available at https://github.com/xuefanfu/3DG-VLN.

Fanfu Xue, En Yu, Yantian Shen · 225 views · Jun 18, 2026
Vision-language navigationUAV
Jun 18, 2026
From reactive to cognitive: brain-inspired spatial intelligence for embodied agents

From reactive to cognitive: brain-inspired spatial intelligence for embodied agents

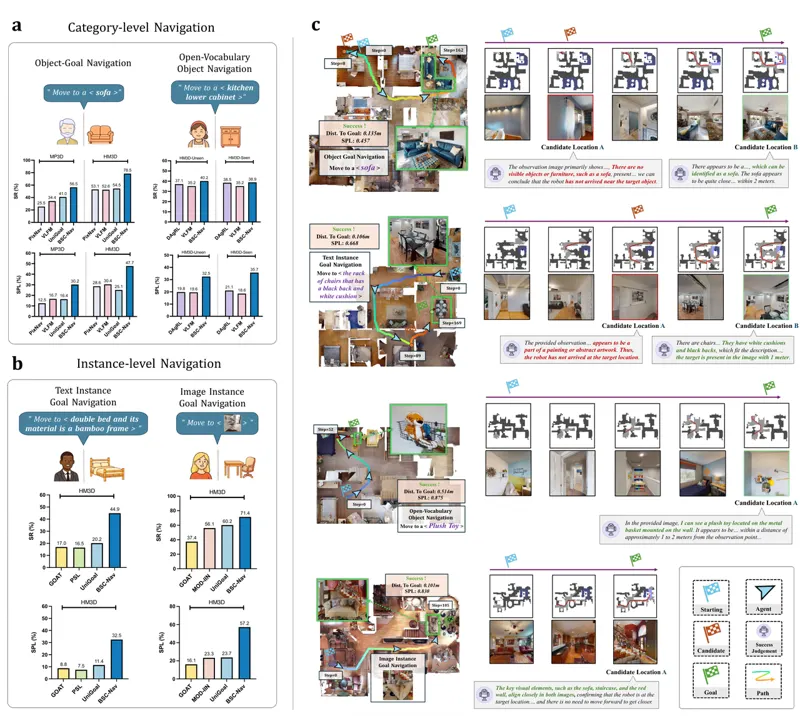
Tsinghua University and Beihang University present BSC-Nav (Brain-inspired Spatial Cognition for Navigation). The paper argues that existing embodied agents — whether end-to-end RL or "MLLM plus modular pipeline" — are fundamentally reactive and stateless: they process an observation and discard it, lacking any durable internal model of space, which yields fragmented knowledge, short-sighted planning and poor generalization. The authors borrow the answer from neuroscience, where spatial knowledge consolidates into three interconnected forms: landmarks, route knowledge, and survey knowledge. BSC-Nav instantiates these computationally in three modules. Landmark memory stores 4-tuples (world coordinates, open-vocabulary category, detection confidence, GPT-4o contextual description) with a spatial-overlap set plus confidence-weighted fusion for deduplication. The cognitive map extracts DINO-v2 patch features, projects them through inverse perspective projection and cascaded coordinate transforms into a voxel grid, and adopts a free-energy-principle-inspired surprise-driven update: a new feature is written when its mean distance to features in the n-hop neighborhood exceeds a threshold, replacing the lowest-surprise entry when the buffer is full, preserving cross-viewpoint diversity while bounding storage. Working memory retrieves hierarchically by instruction complexity — simple targets use text-only GPT-4 reasoning over landmark memory (even inferring unrecorded targets from co-located landmarks), while complex targets first have descriptions refined by GPT-4o, then "imagine" the appearance via Stable Diffusion 3.5, encoded by DINO-v2 and center-distance weighted pooled to query the cognitive map (imagine-then-localize), with similarity-weighted DBSCAN yielding candidate coordinates. Rather than greedily taking the highest confidence, candidates are ordered by H_i = lambda*p_i + (1-lambda)(1 - d_i/d_max). Across 62 MP3D/HM3D scenes and 8,195 episodes: OGN reaches 78.5% SR on HM3D (24.0 points above SOTA UniGoal), OVON zero-shot beats supervised DAgRL, IIN reaches 71.4%; SPL gains are even more consistent (IIN 57.2% vs 23.7%). On A-EQA it achieves the highest LLM-Match of 54.6, still trailing humans by 27.5. Real-world deployment on a custom platform (AgileX Ranger-mini-3.0 chassis, Franka Research 3 arm, RealSense D435i) ran 75 episodes in a ~200 m² two-floor space, with IIN reaching 100% SR on 4 of 5 targets and reliable localization to semantically plausible regions even on failure, plus long-horizon navigation-plus-manipulation demos such as "make breakfast" over three open-vocabulary objects. The paper proposes an embodied Turing test for spatial cognition probing three dimensions: real-time construction of reusable spatial representations, abstraction from sparse partial observations, and translation of high-level goals into actionable spatial plans.

Ruan, Shouwei, Wang, Liyuan, Kang, Caixin · 961 views · Aug 24, 2025
BSC-NavVision-language navigation
Aug 24, 2025
Navi-Agent: Unlocalized Monocular Navigation Agent

Navi-Agent: Unlocalized Monocular Navigation Agent

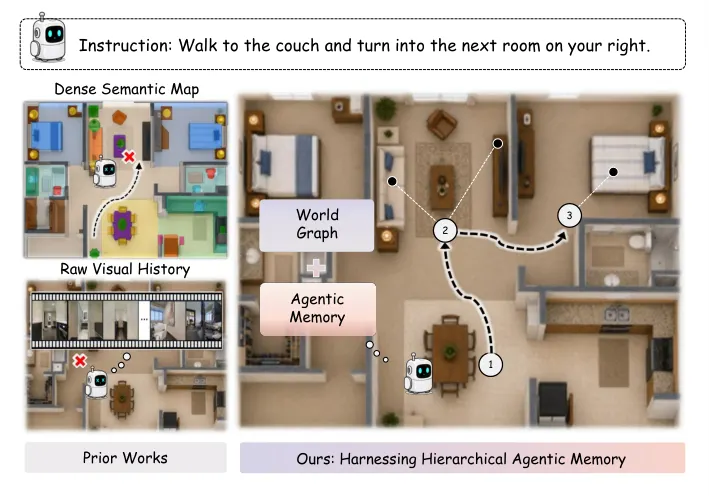
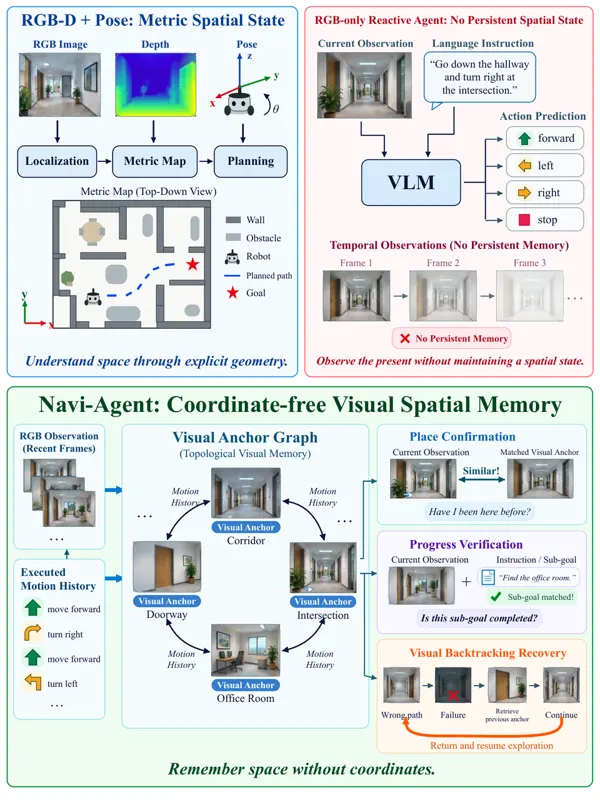
Vision-Language Navigation in Continuous Environments (VLN-CE) requires an embodied agent to execute long-horizon instructions in unknown environments. Existing zero-shot VLN-CE systems typically maintain spatial states through geometric localization or coordinate-based representations. Recent geometry-constrained navigation removes depth and globally consistent coordinates, but maintaining persistent spatial awareness for place confirmation, progress verification, and recovery remains challenging. We present Navi-Agent, a zero-shot VLN-CE agent that constructs a coordinate-free spatial state from visual observations and executed motion histories. Navi-Agent organizes this state as a navigation topology, where nodes represent visual places and edges represent motion transitions. This representation enables observation-based approximate self-localization, task progress verification, and visual revisitation-based recovery. Navi-Agent performs closed-loop navigation by decomposing instructions into sub-goals, executing local visual navigation, and verifying visited places through the constructed spatial state. Experiments on zero-shot VLN-CE benchmark and real-world robot platforms show that Navi-Agent achieves state-of-the-art performance among geometry-constrained methods while remaining competitive with approaches relying on geometric localization.

Xie, Wenyuan, Hong, Mengyang, Wang, Yongzhong · 730 views · Sep 17, 2026
VLNVision-language navigation
Sep 17, 2026
TANGO: Humanoid Navigation in Cluttered Environments with a Whole-Body Vision-Language-Action Model

TANGO: Humanoid Navigation in Cluttered Environments with a Whole-Body Vision-Language-Action Model

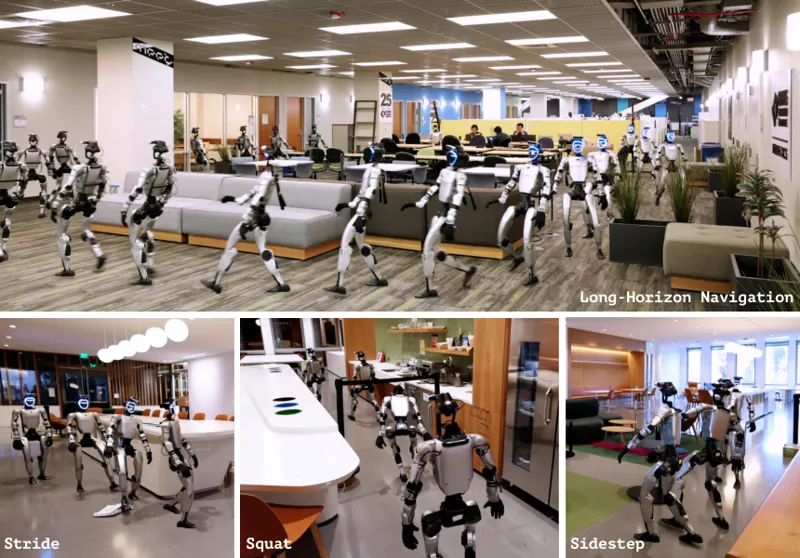
We study the problem of navigating cluttered indoor environments with a humanoid robot. Unlike conventional methods that model navigation as a 2D path planning problem, humanoid traversal in cluttered environments requires continuous geometry-aware whole-body adaptation, including coordinated arm placement, torso adjustment, and gait modulation for collision-free movement through complex 3D spaces. We introduce TANGO, the first whole-body vision-language navigation framework for language-conditioned humanoid traversal in cluttered environments. Given a natural-language instruction and egocentric RGB observations, TANGO directly predicts 29-DoF joint-space actions for downstream whole-body control. We train TANGO entirely in simulation by synthesizing diverse collision-free traversal behaviors via global path planning, kinematic whole-body motion generation, obstacle-aware motion editing, and RL-based tracking. This pipeline provides dynamically feasible action supervision for learning language-conditioned whole-body policies. In extensive simulation experiments, TANGO demonstrates state-of-the-art performance in vision-language navigation, while outperforming strong modular baselines in navigating challenging scenes requiring obstacle negotiation. Lastly, we deploy TANGO zero-shot on a Unitree G1 humanoid robot, and observe robust language-guided traversal in cluttered real-world scenes without training on any real-world navigation data.

Anqi Li, Yuxin Chen, Zhaobo Li · 1k views · Sep 8, 2026
HumanoidVLA
Sep 8, 2026
Token-Wise Latent Streaming from Slow Reasoners to Fast Planners for Dynamic Vision Language Navigation

Token-Wise Latent Streaming from Slow Reasoners to Fast Planners for Dynamic Vision Language Navigation

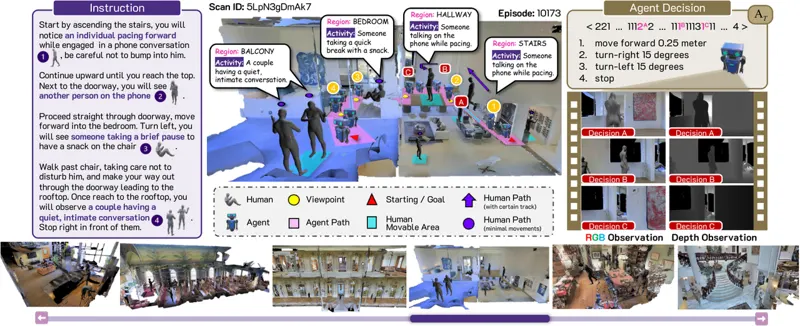
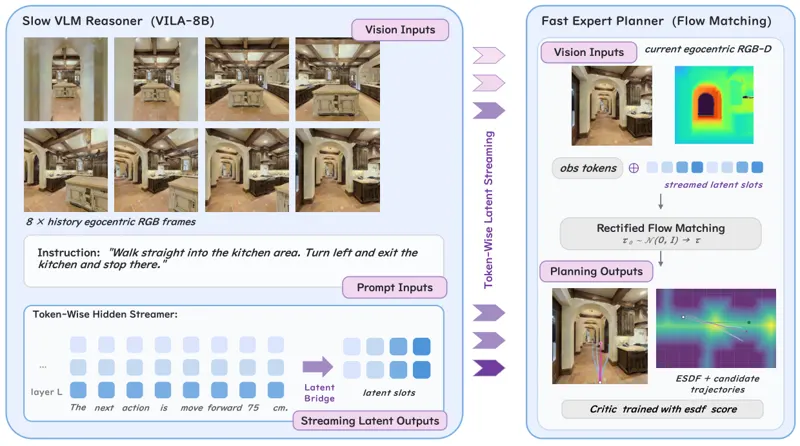
Vision-Language Navigation in dynamic, human-centric environments exposes a fundamental tension: linguistic reasoning is slow and deliberative, whereas safe, socially compliant planning should be instant and reactive. The resulting observation staleness is safety-critical: a maneuver chosen during inference can already be unsafe by the time it executes. We observe that, long before a VLM finishes its inference, its intermediate hidden states already encode action-relevant intent. We propose SPARK-VLN, a dual-system framework for dynamic social VLN that streams the slow VLM reasoner's knowledge to a fast flow-matching expert planner throughout token generation, providing fresh and evolving guidance during inference. This design is realized by three modules: a Token-Wise Hidden Streamer that extracts intermediate hidden states along the token generation process, a Sequence-to-Slot Latent Bridge that projects them into fixed-size latent slots, and an Evolving Latent Conditioner that infuses them into the expert planner. We also introduce a human-centric benchmark suite for dynamic social vision-language navigation that keeps pedestrians and the robot active throughout inference and reports navigation success, social compliance, human collisions, and explicit staleness statistics. Across these settings, SPARK-VLN mproves navigation success and social compliance while sustaining inference efficiency. Webpage: https://hutslib.github.io/SPARK-VLN/.

Tianshuai Hu, Yangyi Zhong, Zeying Gong · 692 views · Jul 18, 2026
Vision-language navigationSocial Navigation
Jul 18, 2026

As an Amazon Associate, we earn from qualifying purchases.