The ultimate guide to multi-harness RL: train models inside Claude Code and Codex — Hugging Face's four-harness experiment with a 2.6B model
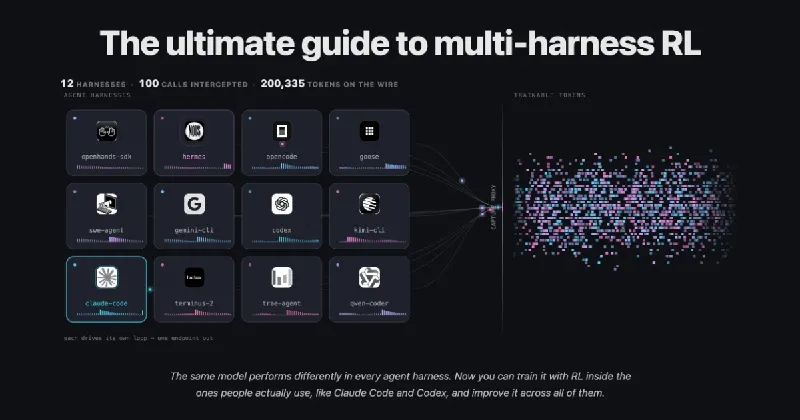
The same model behaves like two different models depending on the agent harness around it: GLM-5.2 scores 23% in one harness and 52% in another on SWE-bench Pro; in a controlled experiment swapping the harness moved scores 13 points while swapping the model moved only 2.5–5. A Hugging Face team (Adithya S Kolavi, Joel Niklaus, Lewis Tunstall, Leandro von Werra and colleagues, with Liquid AI) publishes an open fix: run agentic RL inside the real harnesses — Claude Code, Codex, OpenCode, Mini-SWE-Agent — with zero harness code changes. The stack: OpenEnv as the shared interface, a capture proxy that mints a session id per rollout and records exact token ids, per-token behavior logprobs and loss masks at the model endpoint (full-distribution sampling, top_p=1.0), Harbor for 40+ harness adapters and 26 sandbox backends, and TRL's Async GRPO consuming the masked training sequences. The numbers: LFM2.5-2.6B trained across four harnesses rises from 42.2% to 54.2% average pass@1 with gains under all four, and uses 31% fewer tool calls on tasks both it and the base model solved, while the OpenCode-only arm's gains stay mostly at home. The article also reports the SFT comparison (RL 54.6% vs SFT 47.5%), the full attribution of the earlier Qwen rise-and-decline (output-budget exhaustion, working without submitting, and a reward term that collapsed held-out accuracy from 0.740 to 0.178), and engineering boundaries like the proxy's concurrency ceiling.