BLOG
Official Jetson AI Lab tutorial: fine-tune models directly on Jetson with Unsloth and JetPack 7.2 using memory-efficient QLoRA, export to GGUF, and run locally with llama.cpp. Two hands-on examples: Qwen3.5-4B vision-language model on Jetson Orin Nano (LaTeX OCR fine-tuning), and NVIDIA Nemotron 3.5 Lightning 30B-A3B on Jetson AGX Thor (3 training steps in 44.8s, 66.1 tokens/sec with Q4_K_M quantization). No cloud required.
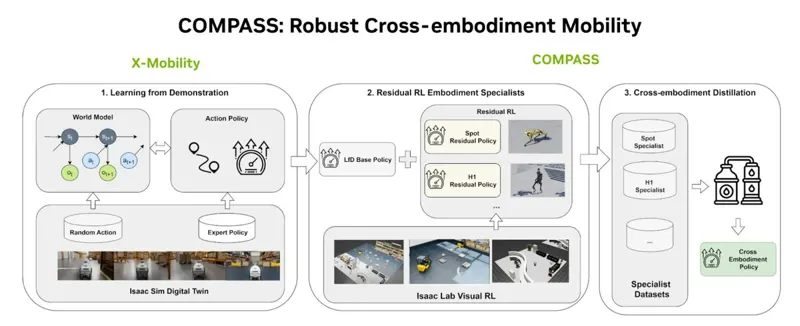
NVIDIA COMPASS framework enables cross-embodiment navigation via residual RL and skill synthesis. A coding agent automates environment validation, scene preparation, smoke testing, residual specialist training, and checkpoint evaluation with human approval gates. Uses Spot quadruped as reference across built-in warehouse, SAGE-10K, and NuRec captured environments.
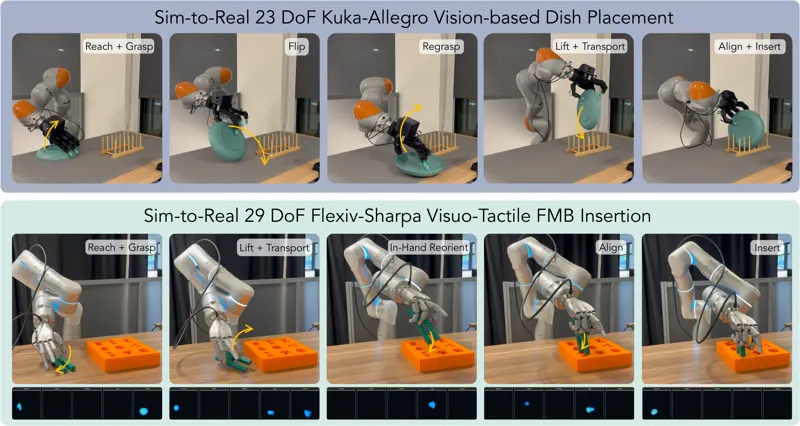
ADEPT pre-trains one dexterous policy on 16 primitives, post-trains specialists without forgetting, and deploys zero-shot on Kuka-Allegro and Flexiv-Sharpa, 2-14x faster than gripper pipelines.