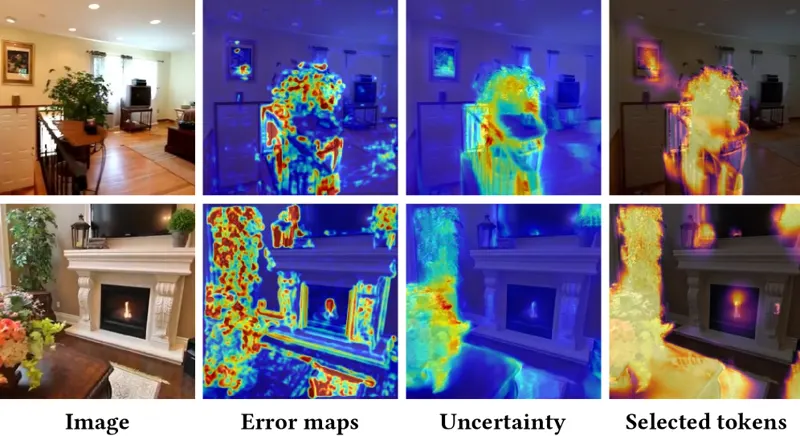
3D Gaussian Splatting (3DGS) achieves high-quality novel-view synthesis by optimizing freely placed primitives in 3D and adaptively densifying them in under-reconstructed regions. However, this scene-adaptive capacity allocation is largely lost in existing feed-forward 3DGS methods, which commonly regress Gaussians at input pixels and lift them along camera rays. Such pixel-aligned formulations make the number and placement of primitives depend on image resolution and input viewpoints rather than scene complexity, resulting in dense and often redundant Gaussian sets. We present ATSplat, a feed-forward 3DGS framework that restores the adaptive allocation capability of 3DGS optimization through Adaptive 3D Tokens. ATSplat first lifts coarse patch-level depth and camera cues into sparse 3D anchor tokens, forming a compact scaffold of the scene. Each token is then regressed into local Gaussians with learnable 3D offsets, decoupling primitive placement from input image grids. An Adaptive Token Expansion module predicts a token-level uncertainty score, supervised by rendering error maps, and selectively expands high-uncertainty tokens through learnable expansion layers. This sparse-to-adaptive formulation enables ATSplat to concentrate primitives in challenging regions while maintaining a compact representation. Experiments on two representative datasets, RealEstate10K and DL3DV, show that ATSplat achieves state-of-the-art rendering quality while reducing the number of Gaussians by more than 5.7× compared with dense feed-forward 3DGS methods. From 12 input images at 512 × 960 resolution, ATSplat completes reconstruction in less than a second using a single commercial GPU, and renders high-quality novel views at 1136 FPS (512 × 960) with only 311K Gaussians.
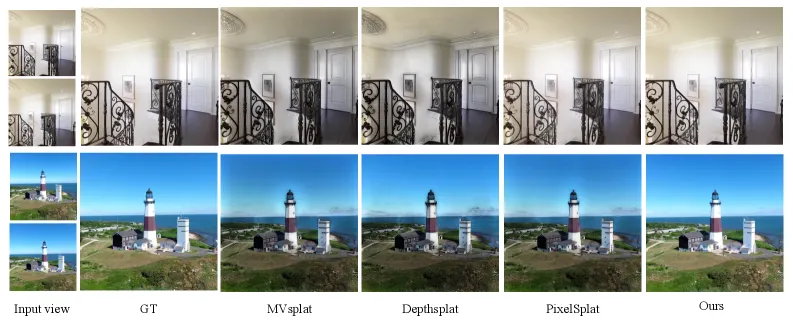
Pixel-aligned Gaussian splatting enables efficient and generalizable novel-view synthesis. However, high-resolution rendering faces a critical trade-off where increasing input resolution improves detail at the expense of quadratically rising network computational cost. Conversely, maintaining low-resolution inputs stabilizes this cost but results in insufficient Gaussian density and artifacts. To address this, we propose SubSplat, which introduces Sub-pixel Gaussian Reparameterizer(SPGR) to subdivide primary Gaussians into fine-grained primitives, restoring structural density directly from low-resolution features. We further enhance the reparameterization quality through feature aggregation, which effectively captures high-frequency details across multiple views. Experiments on RealEstate10K and ACID demonstrate that SubSplat achieves high-fidelity rendering with superior efficiency. Our results validate that the proposed framework successfully resolves the trade-off between reparameterization fidelity and network computational cost inherent in pixel-aligned Gaussian Splatting.
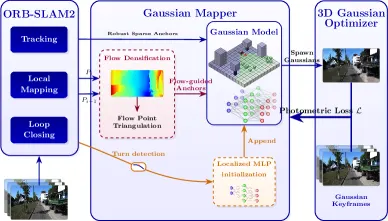
Existing Gaussian-splatting-based monocular Simultaneous Localization and Mapping (SLAM) systems are either tailored to short sequences, are not real-time, or suffer from prohibitive GPU memory requirements, limiting their applicability in realistic, long-horizon scenarios. To address this, we present GLAM-SLAM, a real-time, decoupled Gaussian-splatting SLAM system designed for large-scale outdoor scenes. We ensure lightweight tracking using a robust, feature-based SLAM frontend, while for mapping, we adopt a structured, sparse anchor grid representation that ensures scalable operation and maintains scene coherence across long-term sequences. To satisfy the dense initialization requirements of 3D Gaussian Splatting (3DGS), we introduce a geometry-based flow-densification anchoring strategy using epipolar constraints. Furthermore, by treating mapping as a multi-scene problem, we propose a scene-partitioning strategy that introduces a strong spatial inductive bias via MLP initializations to generate localized Gaussians. We evaluate our system on the challenging, long-sequence KITTI Odometry, Oxford RobotCar, and M'alaga datasets. Extensive ablations and comparisons demonstrate a 15% improvement in reconstruction quality over the second-best performer, while maintaining real-time performance and the ability to scale to longer sequences. Code is publicly available for the benefit of the community.
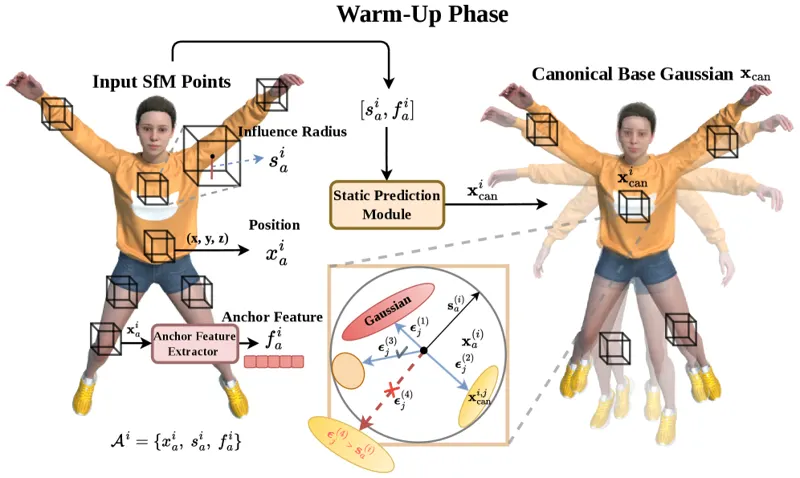
Dynamic scene reconstruction with 3D Gaussian Splatting requires a balance between fine-grained motion modeling, structural stability, and compact representation. Existing per-primitive methods provide flexible local deformation but often suffer from redundant primitive growth, while anchor-based methods improve spatial regularity at the cost of suppressing locally varying motion. To address these issues, we present GrainGS, a dynamic Gaussian framework that combines a hierarchical anchor scaffold with per-Gaussian deformation. A static warm-up stage first establishes a time-invariant canonical representation from observations across all timestamps. During joint training, a stop-gradient operation blocks the deformation-mediated gradient pathway to the canonical positions while preserving their direct refinement through the reconstruction objective. Each Gaussian then predicts independent temporal offsets for position, rotation, and scale, enabling detailed local motion within a structurally constrained scaffold. A canonical-residual appearance decomposition further models frame-dependent photometric changes without forcing them into geometric deformation. Experiments on synthetic monocular and real-world multiview benchmarks show that GrainGS achieves high reconstruction quality, real-time novel view synthesis, and compact storage. Under the synthetic benchmark setting, it reaches an average peak signal-to-noise ratio of 36.98 decibels, renders at 435.6 frames per second, and requires 4.67 megabytes of storage.
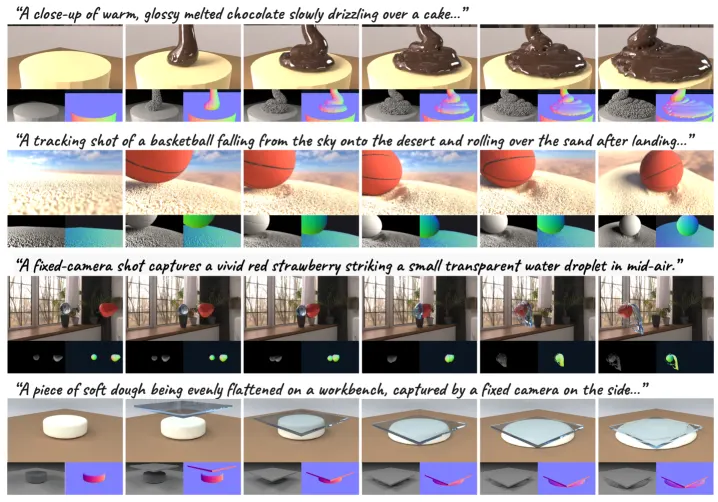
Creating dynamic and physically realistic 4D worlds from natural language descriptions is both fascinating and challenging. Traditional computer graphics methods rely on manual creation, requiring extensive human effort to fine-tune materials, motions, and visual fidelity. Recent advances in generative foundation models have sparked interest in learning to generate such 4D worlds from large-scale data; however, existing methods still struggle to ensure physical plausibility and controllability. In this work, we take a different path by leveraging foundation models to construct an agentic system that emulates how humans traditionally create 4D worlds, yet automates the entire process. We present GS-Agent, an end-to-end multi-agent framework that integrates physics engines in the loop to generate realistic, dynamic, and controllable 4D physical worlds from natural language. Inspired by how humans build 4D worlds, GS-Agent decomposes the task into entity management, covering 3D asset curation, material tuning, placement, and motion control, and rendering configuration, including camera and lighting manipulation. Multiple agents with distinct expertise interact with the physics engine via code, seek multimodal feedback, and collaborate to iteratively construct 4D worlds that align with the given descriptions. Experimental results show that GS-Agent effectively converts natural language into diverse and physically plausible 4D worlds exhibiting rich interactions among liquids, deformable objects, and rigid bodies, while achieving cinematic camera and lighting control. We envision GS-Agent as a foundation for a new paradigm in 4D world generation, empowering creative content creation and physical AI. Project page at https://umass-embodied-agi.github.io/gs-agent/
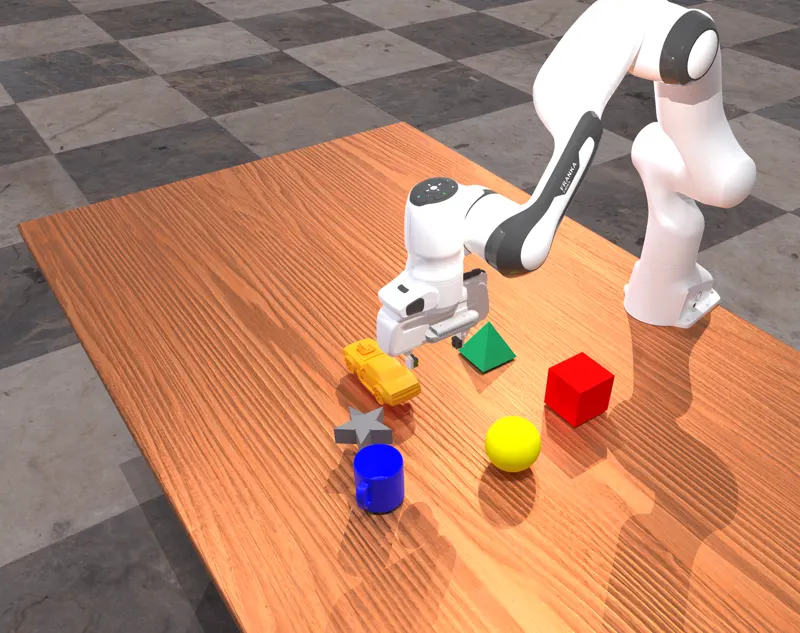
Compositional generalization is essential for robot to follow diverse instructions. However, pretrained policies are known to take shortcuts, deferring to salient cues rather than grounding language. We introduce a diagnostic framework that localizes this failure to individual instruction factors, e.g., reusable semantic components such as color, verb, object, size, and spatial attribute. Our framework formalizes instruction factor bias, the tendency of fine-tuned policies to over-rely on dominant factors as shortcuts, and quantifies it through two metrics: Factor Dominance Rate (FDR), capturing pairwise bias between factors, and Factor Dominance Hierarchy (FDH), aggregating these into a global ranking. Evaluation on six foundation policies reveals broadly consistent ordering, i.e., color ≥ object ≥ spatial ≥ verb ≥ size, with color dominant, and verb and size most under-grounded. We further show the diagnosis is actionable: a bias-aware data collection strategy that reallocates a fixed budget toward under-grounded factors outperforms baselines in simulation and on a real robot using half the demonstrations, thereby enabling more sample-efficient and generalizable policy learning.
The gap between simulation and reality remains a fundamental challenge in deploying simulation-trained robotic policies in the real world. Real-to-sim methods narrow this gap from the real side, learning transition dynamics from real data to build a more realistic digital world. Learned dynamics models are their dominant instance. Such methods, however, face a partial observability problem: the same observation may branch to different transitions due to unobservable factors. Existing methods assume these factors can be recovered from observation history. However, this may fail whenever observation history is uninformative, such as a sudden contact event with no prior warning. To address this limitation, we propose World Translation, which exploits a complementary strength of simulators and learned dynamics. Simulators are deterministic but physically imperfect, while learned models are accurate but underdetermined under partial observability. Rather than predicting transitions forward from history, we extract the unobservable dynamics information backward from an observed transition, then translate this feature across simulation and reality as an unpaired domain-translation problem that preserves dynamics content while transferring domain style. Experiments across humanoid, quadruped, and manipulator platforms show that our method achieves more accurate dynamics modeling than baselines, with the largest gains when unobservable factors cannot be recovered from observation history. Real-robot deployment on Go2 quadruped confirms improved policy transfer.
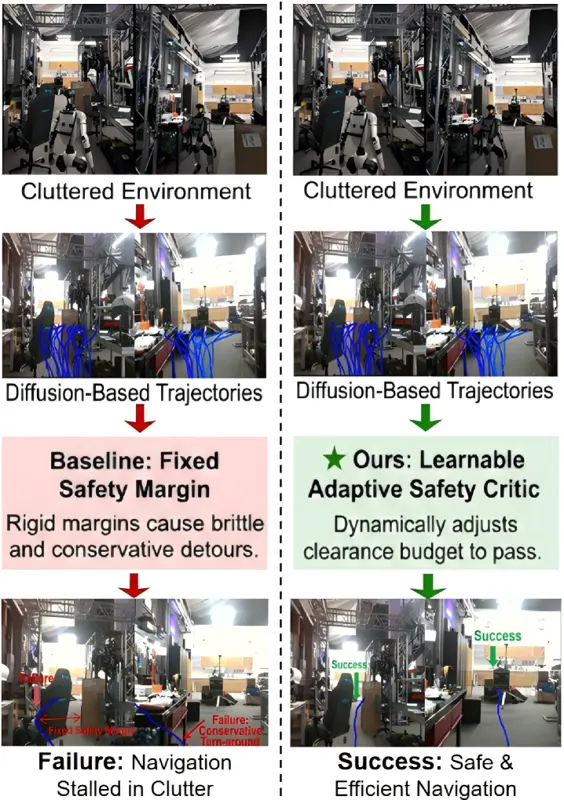
Robots in cluttered indoor spaces often fail not because they cannot generate collision-free paths, but because a fixed safety margin is mis-calibrated: conservative margins cause detours and timeouts, while permissive margins lead to near-boundary shortcuts under perception bias. Diffusion-based planners propose diverse trajectory candidates from egocentric RGB-D, yet reliable selection remains the bottleneck. We propose a context-conditioned safety critic that learns an adaptive clearance preference for ranking diffusion proposals, decomposed into three complementary terms: (i) a safety term with a clearance-budget penalty and a control-barrier-function residual for waypoint- and transition-wise safety, (ii) an efficiency term combining a smoothness penalty with a safety-gated detour-ratio penalty that avoids detours without incentivizing risky shortcuts, and (iii) a distance-constraint matching term that anchors the learned budget to realized ESDF clearances to prevent margin collapse. We train the critic with privileged ESDF geometry in simulation and distill it into a perception-only selector via a two-stage teacher-student procedure. On PointGoal navigation in HM3D and MP3D, including cross-dataset transfer, our method achieves the highest success rate (SR) and success weighted by path length (SPL) among strong diffusion, optimization, and RL baselines. Trained purely in simulation, it transfers to a Unitree G1 humanoid and navigates cluttered indoor scenes without task-specific tuning.
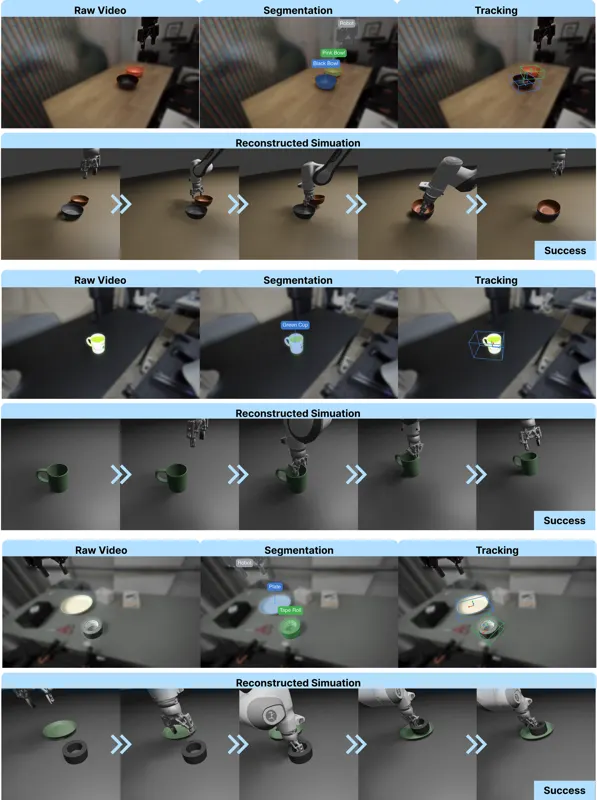
Real-to-sim conversion for robotic interaction with objects remains labor-intensive because it requires more than visual reconstruction: a streamlined real2sim process must recover scene geometries and object states, infer physical parameters, and assemble actors, objects, cameras, poses, and trajectories into a runnable physical simulation. Today this process still depends on manual tuning of visual foundation models, mesh cleanup, coordinate-frame alignment, and brittle workflow glue across visual perception tools and simulators. We introduce Agentic Real2Sim, a framework for generalized physical world modeling with vision-language agents, converting a real-world recording of object-robot interaction into a simulatable episodic twin which preserves observations, geometries, robot interactions, and object states. We evaluate Agentic Real2Sim on rigid-object manipulation, deformable-object interaction, and humanoid motion scenes, spanning domains that are usually handled by separate Real2Sim pipelines, marking a first step toward scalable conversion. The framework's agentic decisions can be driven by an open-weight VLM backend at a small fraction of the cost of frontier models, while attaining comparable conversion success rate. We aim to use the resulting real-world-aligned twins for downstream robotics tasks, specifically policy learning and evaluation. The project site is available at https://agentic-real2sim.github.io/.
Humanoid general motion tracking requires policies that can follow diverse whole-body references while maintaining balance. Building such policies involves many practical design choices, and their individual effects are often hard to assess. We address this issue with an empirical study of common modeling and training factors used in recent humanoid motion-imitation pipelines. To make the study controlled and reproducible, we developed YAHMP, an open-source modular framework for training, evaluating, and deploying whole-body motion tracking policies on the Unitree G1. Within YAHMP, we define a nominal configuration and compare variants that differ in motion-command representation, observation history, action representation, actuation profile, hand-force randomization during training, and training approach. We evaluate the resulting policies on a test set of retargeted human motions and compare the nominal policy with TWIST2 as an external baseline trained on the same motion set. The results distinguish choices with clear tracking effects from choices that mainly change actuation effort, training complexity, or physical interaction capability. Finally, we deploy YAHMP policies zero-shot on the real Unitree G1, demonstrating diverse whole-body motion tracking, balance under external perturbations, and forceful interaction.
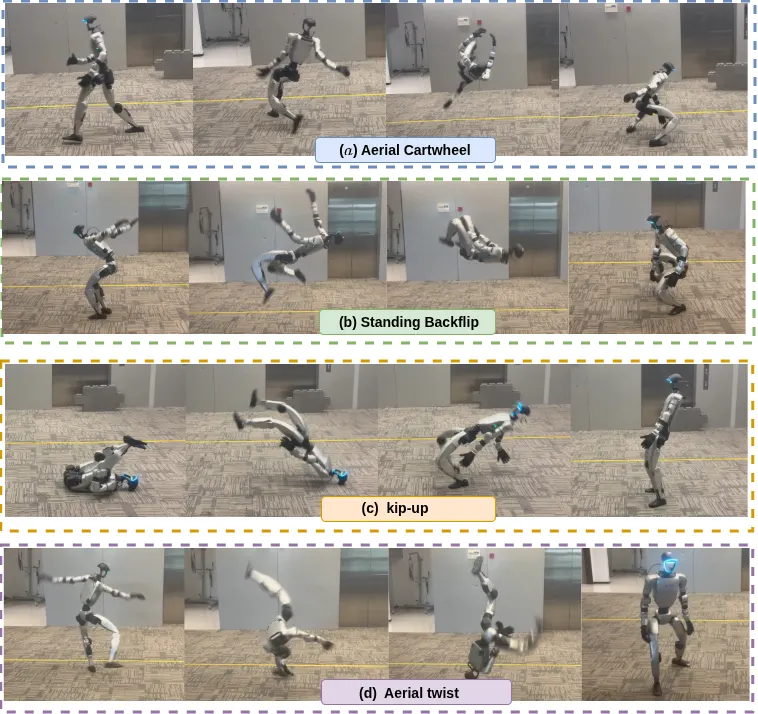
Humans can progressively acquire highly dynamic motor skills while preserving reliable everyday motor abilities. In contrast, existing humanoid controllers face a trade-off between generalist and specialist capabilities: generalist motion tracking policies struggle to reliably execute rare highly dynamic motions, whereas specialist training can degrade previously acquired behaviors. We introduce Extreme-RGMT, a two-stage continual learning framework for robust generalist humanoid control. The method first learns a generalist motion-tracking base policy from diverse multi-source motion data, then employs an asymmetric skill acquisition and capability consolidation mechanism to constrain policy drift on mastered motions while emphasizing difficult dynamic segments. To address the scarcity of highly dynamic motions, their high failure rates, and the resulting shortage of informative samples, Extreme-RGMT combines difficulty-aware sampling with advantage-prioritized trajectory resampling to emphasize critical segments. Experiments show that Extreme-RGMT achieves state-of-the-art generalist whole-body motion-tracking performance, including substantially improved completion of challenging highly dynamic motions. The resulting controller directly executes diverse unseen highly dynamic motions under fixed references and online inertial motion-capture inputs, advancing generalist whole-body motion-tracking controllers toward highly dynamic motor capabilities at the human-expert level.
Offline goal-conditioned reinforcement learning (RL) holds the promise of learning general-purpose policies from static datasets. However, scaling these methods to long-horizon tasks remains a challenge due to the curse of horizon, where value estimation errors can compound through long chains of bootstrapped Bellman backups. Existing hierarchical approaches mitigate this by decomposing tasks into subgoals, yet they often rely on low-level controllers that suffer from myopic execution and biased value estimates. In this work, we propose Hierarchical Implicit Q-Chunking (HiQC), an offline goal-conditioned RL algorithm that combines high-level latent planning with low-level action chunking. By conditioning the low-level critic on temporally extended action sequences, HiQC enables unbiased k-step value backups, compressing the horizon at both the planning and execution levels. We theoretically demonstrate that this dual decomposition results in a tighter bound on value error under a bounded per-backup error model compared to standard hierarchy or flat chunking alone. Empirically, HiQC achieves the highest aggregate performance among the compared methods on the OGBench suite, with its largest gains on long-horizon navigation tasks such as humanoid-giant.