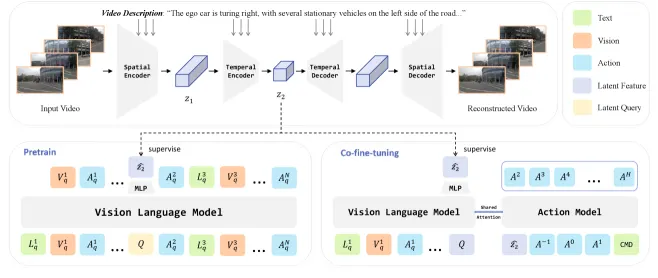
Vision-Language-Action (VLA) models augmented with world modeling represent a promising paradigm for end-to-end autonomous driving. While pixel-level future prediction enables fine-grained spatiotemporal reasoning, it compromises robustness in noisy driving scenarios. Conversely, latent-based world models alleviate this sensitivity but often incur limited interpretability and representational degradation due to absent pixel-level grounding. To reconcile this trade-off, we propose HyWorldVLA, a hybrid world-VLA framework that unifies pixel-level supervision and latent representation learning. In the pre-training stage, HyWorldVLA predicts video latents encoded by a pre-trained video VAE, while simultaneously reconstructing video frames to provide precise pixel-level grounding. During the subsequent co-fine-tuning phase, the model exclusively predicts latent features, which are fed into an action expert to generate trajectories. Extensive experiments on NAVSIM v1 and v2 benchmarks demonstrate that HyWorldVLA significantly outperforms both pixel-based and latent-based world model baselines. Notably, we present the first comprehensive qualitative and quantitative analysis of world model noise robustness in autonomous driving, establishing a new benchmark for evaluating future architectures.
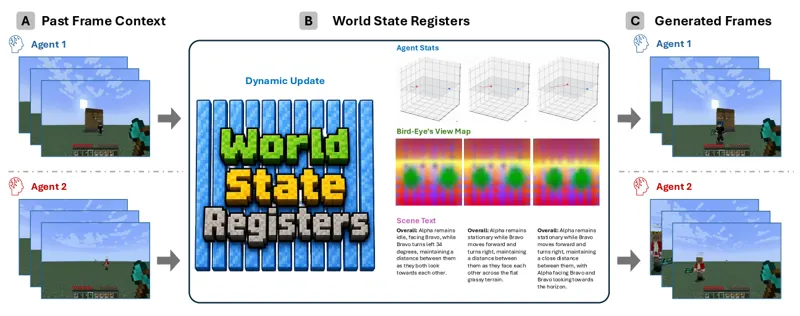
Multi-agent interactive world models should not only generate consistent observations, but also maintain world states that persist across agents and evolve across views. Existing autoregressive video diffusion pipelines carry forward observation history as conditioning context, which makes shared state difficult to maintain in multi-agent and multi-view settings. We present WorldWeaver (W^2), a streaming multi-agent video diffusion model that augments rollout with cross-agent world state registers: learnable tokens that store shared world information, track individual agent status, and are dynamically updated after each generated chunk. We ground these registers with supervision signals spanning individual agent status, global state views including bird's-eye views, and scene text. We further improve the architecture with a Mixture-of-Transformers design that uses separate weights for world state modeling and visual frame modeling. Extensive experiments in two-agent Minecraft video generation show that explicit world-state modeling improves logical consistency and generation quality.
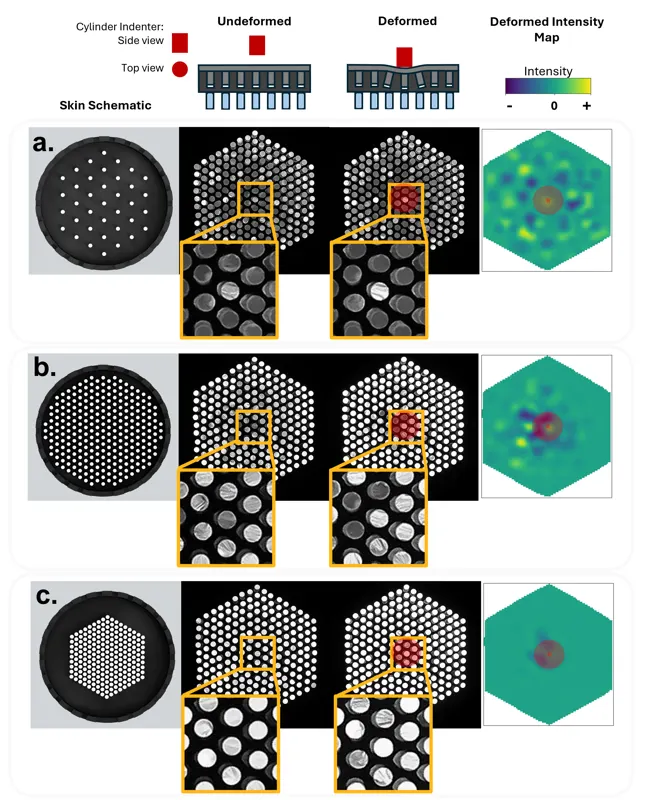
Robotic systems increasingly demand tactile sensing that approaches the adaptability and resolution of human skin to enable dexterous manipulation and safe interaction. OptiTac is a biomimetic tactile sensor that emulates the mechanoreceptor-to-nerve architecture of human touch by pairing each mechanical pin on a soft skin with an optical fiber acting as an artificial nerve. This design demonstrates an architectural principle for routing tactile information away from the sensing surface while preserving high spatial resolution, establishing a practical route toward distributed tactile sensing in future robotic systems. By treating tactile signals as images, simple analytical methods, rather than opaque deep-learning models, are used to infer contact location, size, and shape, providing interpretable and scalable tactile intelligence. This work demonstrates how evolutionary principles from biology can guide the development of artificial nerve systems for robots, offering a pathway toward human-like tactile perception in next-generation robotic platforms. More broadly, OptiTac establishes an artificial nerve-inspired sensing framework for interpretable robotic touch and a scalable route toward future distributed tactile systems.
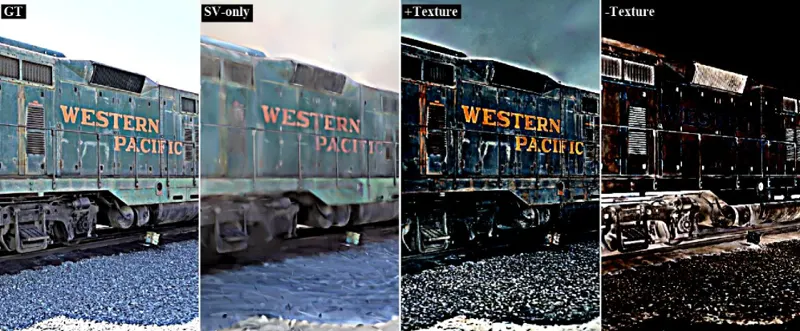
Recent extensions of 3D Gaussian Splatting (3DGS) capture fine color details using hash-grid-based appearance parameterization but incur high computational cost during fragment rendering. We introduce a decoupled radiance representation that models low-frequency geometry and view dependent appearance features with 2D surfels while representing high-frequency textures via a view-independent spatial hash grid that is baked into a compact texture atlas. By including sparsity-enhancing optimizations that penalize semi-transparency and per-primitive falloff, our method aggressively prunes insignificant surfels and achieves significantly faster and sparser reconstructions than prior work. Exploiting geometric sparsity and efficient GPU texture mapping, our approach achieves up to a fivefold speedup over 3DGS while preserving state-of-the-art visual fidelity, enabling real-time 4K rendering at 60 FPS on consumer hardware.
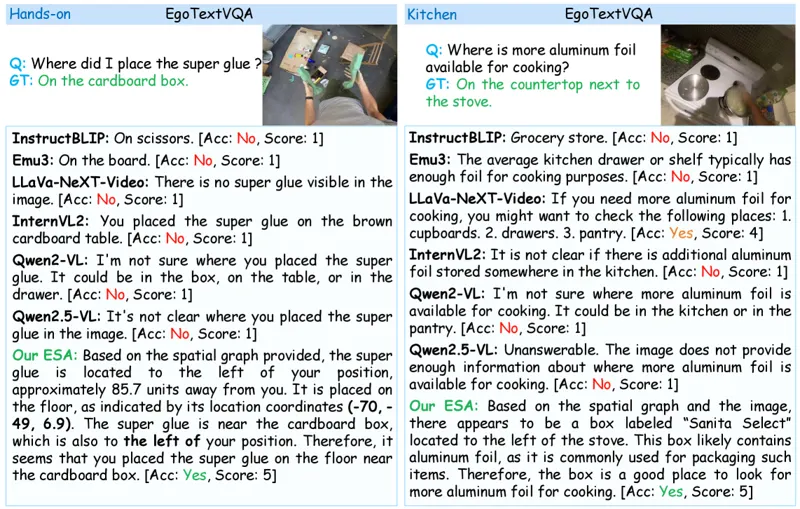
Egocentric Visual Question Answering (VQA) has attracted widespread attention as an important task for enabling Multimodal Large Language Models (MLLMs) to interact with the real world. However, existing MLLMs struggle to perform effective spatial reasoning in complex egocentric scenes due to their limited spatial perception capabilities. To this end, we introduce Ego Scene Augmentation (ESA), an egocentric spatial perception framework, which actively enhances the spatial perception capabilities from the egocentric perspective, powered by the proposed Ego-element Graph. Our core insight is leveraging the Ego-element Graph as an intermediary representation to augment the egocentric spatial perception of MLLMs via visual foundational models. Specifically, we 1) construct the Ego-element Graph, which encapsulates and integrates egocentric spatial features enabled by visual foundational models; 2) enhance the spatial perception capabilities of MLLMs via the Ego-element Graph for ego-perspective scenes. Our proposed ESA framework presents significant performance improvement on the EgoTextVQA benchmark. We achieve an 8.14% gain on the indoor setting and an 8.72% gain on the outdoor setting. Furthermore, our ESA shows the most impressive performance improvement in the shopping subset of the indoor setting. The project code is publicly available.
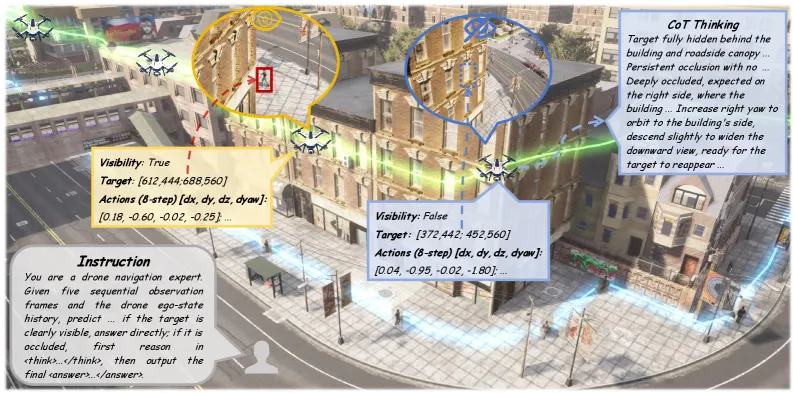
Dynamic target tracking is essential for Unmanned Aerial Vehicles (UAVs) operating in complex urban environments, where both the target and the camera viewpoint change continuously. Existing Vision-Language-Action (VLA) policies can track visible targets effectively, but their performance often degrades when buildings, vegetation, or roadside objects block the line of sight. During sustained occlusion, a policy may lose the target state, execute actions toward an incorrect region, and amplify this error through subsequent observations until re-acquisition becomes impossible. To this end, we present CosFly-VLA, a spatially aware VLA model that jointly grounds the target, estimates its visibility, and generates continuous flight actions through a structured prediction interface. To train this policy, we use a large-scale recipe over diverse data sources. Spatially Grounded Continued Pretraining (CPT) on a 500k mixed pool injects UAV-view depth, distance, and 3-D spatial reasoning. A three-stage Curriculum-based Supervised Fine-Tuning (SFT) process then specializes the tracker through multi-head warm-up followed by two-stage curriculum learning over natural and hard / long-occlusion data. Chain-of-Thought (CoT) training subsequently teaches recovery-oriented reasoning traces before structured answers. Finally, a closed-loop Reinforcement Learning (RL) stage optimizes tracking behavior with a multi-component reward covering stand-off tracking, grounding quality, collision avoidance, and task success. Relative to OpenVLA, CosFly-VLA-0.8B reduces open-loop Average Displacement Error (ADE) by 34.1% on seen-test and 35.3% on unseen-test. Closed-loop optimization improves Success Rate (SR) by 29.8% and 2.5%, respectively. These results demonstrate progress from visible-frame imitation toward spatially grounded action-closed-loop control, evaluated under a shared oracle state history.
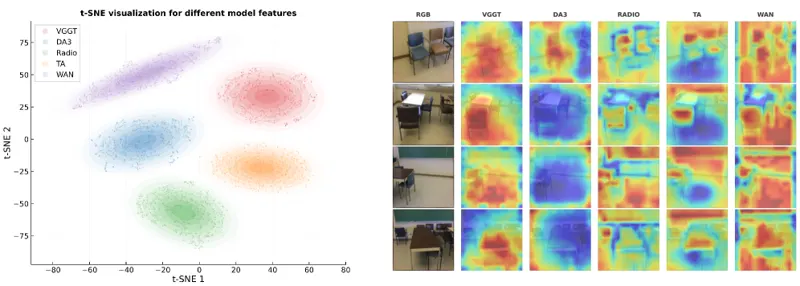
Multimodal Large Language Models (MLLMs) have demonstrated substantial promise in spatial understanding. Existing works typically incorporate prior knowledge extracted from a pre-trained foundation model to further enhance the spatial awareness of MLLMs. In this paper, we first reveal that when integrating diverse foundation models into MLLMs, different models provide complementary spatial priors that benefit different tasks. Motivated by this, we propose ViPS, a novel multi-model prior framework designed to fully unleash the potential of incorporating multiple Visual Priors from diverse models into MLLMs for Spatial understanding. Specifically, ViPS introduces an Efficient Prior Proxy to generate multiple foundational priors with minimal inference overhead, and a Dynamic Prior Fusion mechanism to achieve harmonious and context-aware prior fusion and injection from the prior proxies. Extensive experiments demonstrate that ViPS successfully harmonizes diverse visual priors, establishing new state-of-the-art performance across multiple complex spatial reasoning and 3D spatial understanding benchmarks. Project page: https://visual-ai.github.io/vips
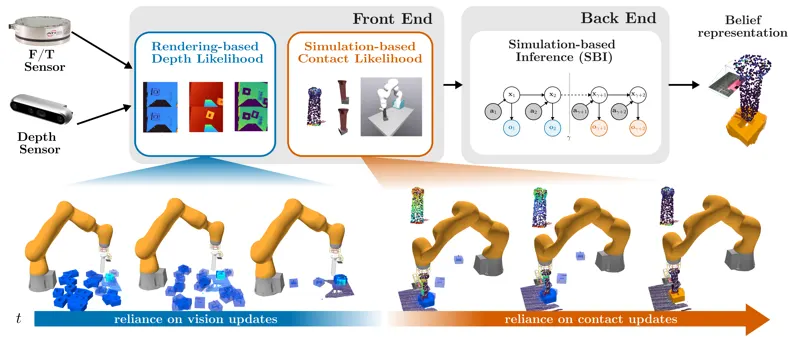
Contact-rich manipulation requires pose estimates that are often more accurate than what depth-only sensing provides. Existing methods, relying on vision and contact, employ costly offline training procedures that need to be retrained for new environments and geometries. We propose BayesContact, a Simulation-Based Inference framework for visuo-tactile pose estimation in peg-in-hole insertion. BayesContact maintains a particle belief over object pose and fuses depth observations with force/torque-derived contact evidence. We employ simulation based forward models to approximate these observation likelihoods. For each pose hypothesis, a renderer predicts depth measurements and a physics simulator predicts contact outcomes under guarded probing actions; both are scored against real observations to update the belief. The resulting multimodal belief also enables information-gain-based probing for active disambiguation. Across simulated geometries and real-robot experiments, BayesContact improves pose observability and insertion success over vision-only inference by 30%
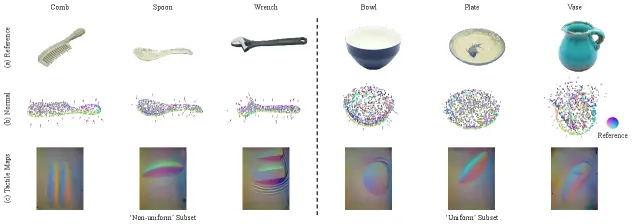
Vision and touch are complementary modalities essential for robotic perception and manipulation. While vision provides global object context, touch offers precise local information at contact points. Integrating these modalities for contact localization, i.e., predicting the location of touch on an object's surface, poses significant challenges due to the need for accurate spatial alignment between tactile data and visual geometry. To address this challenge, we propose VTLoc, a novel visual-tactile framework that localizes contact points from tactile readings using a 3D point cloud as visual input. VTLoc introduces two key components: a geometric multi-modal alignment module, which reconstructs a pseudo-point cloud from fused visual-tactile features and aligns it with the visual point cloud to enforce spatial consistencies across modalities; and an iterative localizing updater, which iteratively refines the predicted contact location using fused visual-tactile features. Evaluated on a new benchmark of 100 real-world objects, VTLoc improves single-touch contact localization by reducing local-to-global correspondence ambiguity.
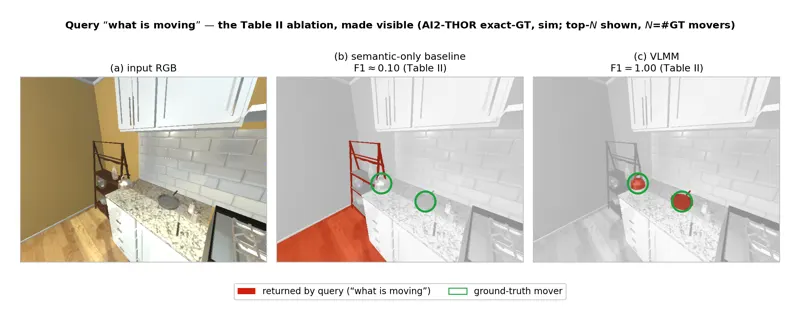
Open-vocabulary 3D maps let robots answer language queries about what and where, but they assume a static world and cannot answer queries about how scene elements behave. We introduce Vision-Language-Motion Maps (VLMM), an open-vocabulary, natural-language-queryable 3D map in which each element carries a fused motion attribute: a VLM/LLM semantic movability prior combined with geometrically observed cross-frame motion, together with a per-element uncertainty. Queries reduce to attribute filters that distinguish what has been seen to move, what could move but has not, and what stays still. On a controlled simulator benchmark with exact ground truth (AI2-THOR, three scene types) we show through ablation that the schema fields are non-substitutable: a semantic-only baseline fails motion queries even with strong features, and neither motion field substitutes for the other (the prior cannot answer "what is moving," observed motion cannot answer "what could move"). On real dynamic RGB-D (TUM and Bonn, six sequences) we show the uncertainty channel-our key difference from prior fused-motion work-consistently improves moving-vs-static average precision and reduces false motion flags, and is robust to estimated (noisy) poses. The raw confidence is not calibrated, but post-hoc isotonic calibration reaches an expected calibration error of 0.10. VLMM is a representation contribution: the closest prior maps each lack at least one of the four properties-open-vocabulary, language-queryable, fused prior-and-observed motion, and per-element uncertainty-that our combination provides.
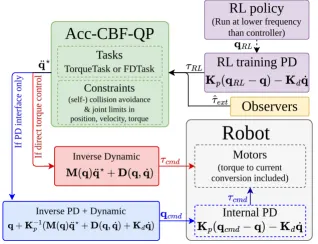
Reinforcement Learning (RL) has demonstrated remarkable capabilities for solving complex robotic control problems, but its lack of safety guarantees severely limits deployment on hardware. In particular, as legged robots and manipulators often operate near safety-critical boundaries, out-of-distribution states can lead to failure upon deployment. To address this, we introduce Acc-CBF-QP, an acceleration-based Quadratic Program (QP) safety filter using Control Barrier Functions (CBFs) that constrains any RL policy onto a safe set at runtime without modifying training. The method applies to unconstrained and Safe-RL policies, and enforces joint position, velocity, torque, and collision constraints within a unified optimization framework. A key contribution is the formulation of RL+QP tasks that regulate deviation from the RL command when constraints would otherwise be violated. We introduce a TorqueTask, minimizing torque deviation, and a Forward Dynamics Task, minimizing induced acceleration deviation, thus providing principled control over safety-performance trade-offs. Experiments on a 7-DoF Kinova Gen3 manipulator and a 19-DoF Unitree H1 humanoid, both in simulation and on hardware, highlight substantial reductions in constraint violations. On the real H1 hardware, a Safe-RL policy alone yielded 10.04 violations/s, which were reduced by 92% to 0.80 violations/s when augmented with Acc-CBF-QP. On the Kinova Gen3, Acc-CBF-QP fully eliminated violations. Nominal task performance of the RL objective is preserved in violation-free regimes. Under aggressive velocity commands on H1, Acc-CBF-QP improves execution by preventing constraint-induced shutdowns, yielding longer survival times. The full pipeline is open-source.
Humanoid control requires natural whole-body coordination, precise real-time responses to control signals, and robust generalization across diverse environmental contexts, making it a cornerstone for generalist embodied agents. Behavior Foundation Models (BFMs) have recently emerged as a promising solution to address these challenges by leveraging large-scale behavioral data to achieve superior expressiveness, versatility and generalization. However, despite growing interest in scaling BFMs to further improve their capabilities, it remains unclear how key factors, including the learning paradigm, behavioral data and model architecture should be coordinated to enable effective scaling. In this work, we revisit the scaling recipe for BFMs and demonstrate that substantial performance gains can be achieved through the coordination of three core components: 1) the learning paradigm of motion tracking that reformulates diverse humanoid control problems as the reproduction of integrated whole-body behaviors in the global frame; 2) the strategic synergy between on-policy rollout quantity and reference motion diversity; and 3) the expressive and scalable model architecture termed Humanoid Transformer that facilitates the natural emergence of structured behavioral representations. Through extensive experiments in both simulation and real-world deployment, we demonstrate that our approach yields significant improvements in control fidelity and task generalization, reducing Mean Per-Keypoint Position Error (MPKPE) on the test set by over 10% in local mode and 82% in global mode compared with existing humanoid controllers. These results establish BFM as a principled and effective foundation for scalable and general-purpose humanoid control.