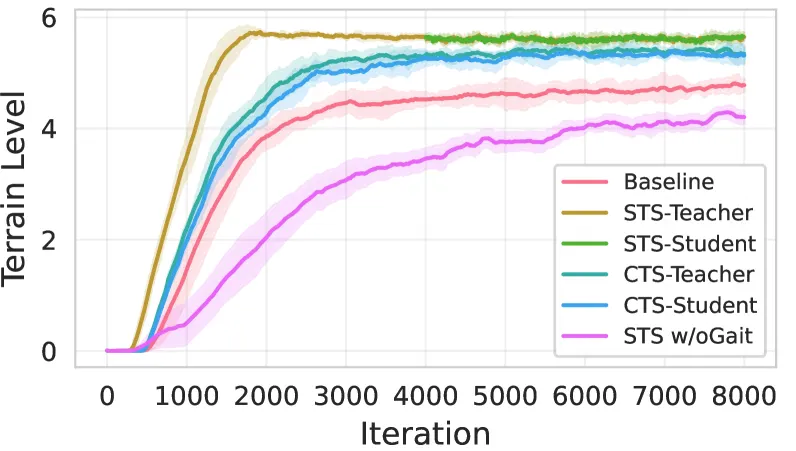
For full-size humanoid robots, even with recent advances in reinforcement learning-based control, achieving reliable locomotion on complex terrains, such as long staircases, remains challenging. In such settings, limited perception, ambiguous terrain cues, and insufficient adaptation of gait timing can cause even a single misplaced or mistimed step to result in rapid loss of balance. We introduce a perceptive locomotion framework that merges terrain sensing, gait regulation, and whole-body control into a single reinforcement learning policy. A downward-facing depth camera mounted under the base observes the support region around the feet, and a compact U-Net reconstructs a dense egocentric height map from each frame in real time, operating at the same frequency as the control loop. The perceptual height map, together with proprioceptive observations, is processed by a unified policy that produces joint commands and a global stepping-phase signal, allowing gait timing and whole-body posture to be adapted jointly to the commanded motion and local terrain geometry. We further adopt a single-stage successive teacher-student training scheme for efficient policy learning and knowledge transfer. Experiments conducted on a 31-DoF, 1.65 m humanoid robot demonstrate robust locomotion in both simulation and real-world settings, including forward and backward stair ascent and descent, as well as crossing a 46 cm gap. Project Page:https://ga-phl.github.io/
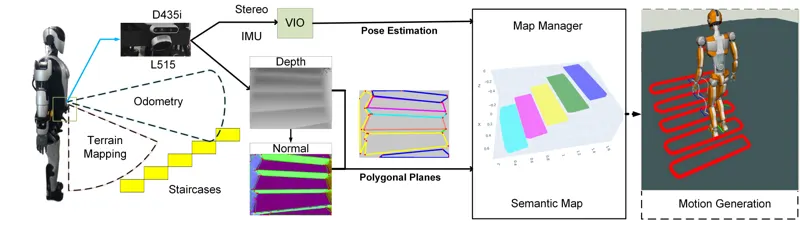
We present a novel algorithm for real-time planar semantic mapping tailored for humanoid robots navigating complex terrains such as staircases. Our method is adaptable to any odometry input and leverages GPU-accelerated processes for planar extraction, enabling the rapid generation of globally consistent semantic maps. We utilize an anisotropic diffusion filter on depth images to effectively minimize noise from gradient jumps while preserving essential edge details, enhancing normal vector images' accuracy and smoothness. Both the anisotropic diffusion and the RANSAC-based plane extraction processes are optimized for parallel processing on GPUs, significantly enhancing computational efficiency. Our approach achieves real-time performance, processing single frames at rates exceeding $30 Hz$, which facilitates detailed plane extraction and map management swiftly and efficiently. Extensive testing underscores the algorithm's capabilities in real-time scenarios and demonstrates its practical application in humanoid robot gait planning, significantly improving its ability to navigate dynamic environments.
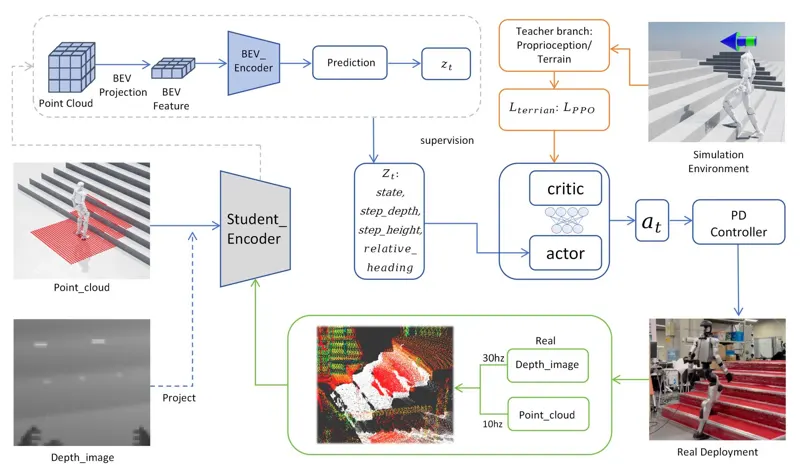
Robust humanoid stair climbing remains challenging due to geometric discontinuities, sensitivity to step height variations, and perception uncertainty in real-world environments. Existing learning-based locomotion policies often rely on implicit terrain representations or blind proprioceptive feedback, limiting their ability to generalize across varying stair geometries and to anticipate required gait adjustments. This paper proposes an explicit stair geometry conditioning framework for robust humanoid stair climbing. Instead of encoding terrain as high-dimensional latent features, we extract a compact set of interpretable geometric parameters, including step height, step depth, and current yaw angle relative to the robot heading. These explicit stair parameters directly condition a Proximal Policy Optimization (PPO)-based locomotion policy, enabling proactive modulation of swing-foot clearance and stride characteristics according to stair structure. Simulation experiments demonstrate improved generalization across unseen stair heights beyond the training distribution. Real-world experiments on the Unitree G1 humanoid validate reliable indoor and outdoor stair traversal. In challenging outdoor scenarios, the robot successfully ascends 33 consecutive steps without failure, demonstrating robustness and practical deployability.
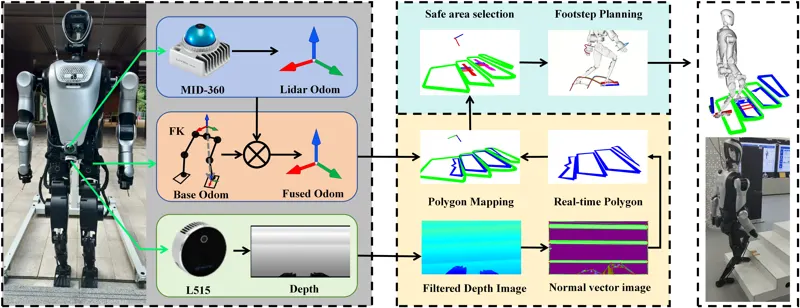
Recently, biped robot walking technology has been significantly developed, mainly in the context of a bland walking scheme. To emulate human walking, robots need to step on the positions they see in unknown spaces accurately. In this paper, we present PolyMap, a perception-based locomotion planning framework for humanoid robots to climb stairs. Our core idea is to build a real-time polygonal staircase plane semantic map, followed by a footstep planar using these polygonal plane segments. These plane segmentation and visual odometry are done by multi-sensor fusion(LiDAR, RGB-D camera and IMUs). The proposed framework is deployed on a NVIDIA Orin, which performs 20-30 Hz whole-body motion planning output. Both indoor and outdoor real-scene experiments indicate that our method is efficient and robust for humanoid robot stair climbing.
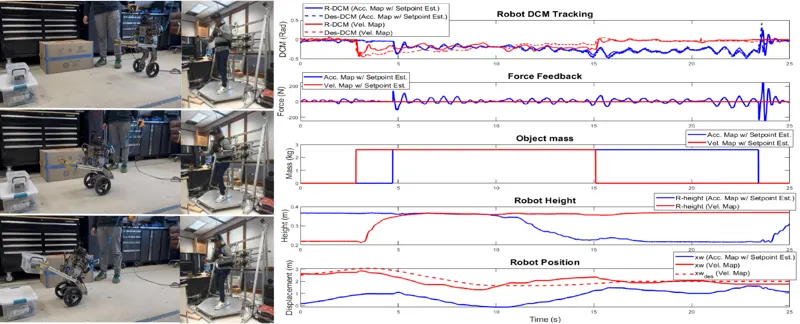
Humanoid robots can support human workers in physically demanding environments by performing tasks that require whole-body coordination, such as lifting and transporting heavy objects.These tasks, which we refer to as Dynamic Mobile Manipulation (DMM), require the simultaneous control of locomotion, manipulation, and posture under dynamic interaction forces. This paper presents a teleoperation framework for DMM on a height-adjustable wheeled humanoid robot for carrying heavy payloads. A Human-Machine Interface (HMI) enables whole-body motion retargeting from the human pilot to the robot by capturing the motion of the human and applying haptic feedback. The pilot uses body motion to regulate robot posture and locomotion, while arm movements guide manipulation.Real time haptic feedback delivers end effector wrenches and balance related cues, closing the loop between human perception and robot environment interaction. We evaluate the different telelocomotion mappings that offer varying levels of balance assistance, allowing the pilot to either manually or automatically regulate the robot's lean in response to payload-induced disturbances. The system is validated in experiments involving dynamic lifting of barbells and boxes up to 2.5 kg (21% of robot mass), demonstrating coordinated whole-body control, height variation, and disturbance handling under pilot guidance. Video demo can be found at: https://youtu.be/jF270_bG1h8?feature=shared
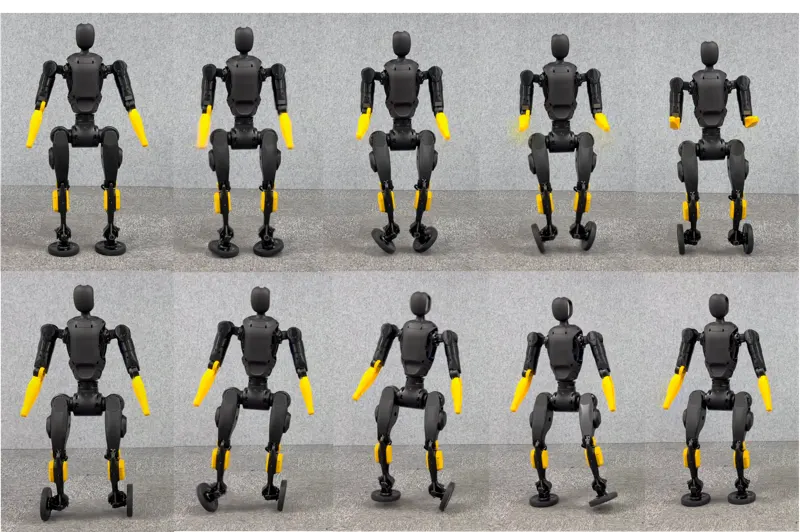
Wheel-legged robots combine the efficiency of wheeled locomotion with the versatility of legged systems, enabling rapid traversal over both continuous and discrete terrains. However, conventional designs typically employ fixed wheels as feet and limited degrees of freedom (DoFs) at the hips, resulting in reduced stability and mobility during legged locomotion compared to humanoids with flat feet. In addition, most existing platforms lack a full upper body with arms, which limits their ability to perform dexterous manipulation tasks. In this letter, we present X2-N, a high-DoF transformable robot with dual-mode locomotion and manipulation. X2-N can operate in both humanoid and wheel-legged forms and transform seamlessly between them through joint reconfiguration. We further propose a reinforcement learning (RL)-based whole-body control framework tailored to this morphology, enabling unified control across hybrid locomotion, transformation, and manipulation. We validate X2-N in a range of challenging locomotion and manipulation tasks, including dynamic skating-like motion, stair climbing and package delivery. Results demonstrate high locomotion efficiency, strong terrain adaptability, and stable loco-manipulation performance of X2-N, highlighting its potential for real-world deployment.
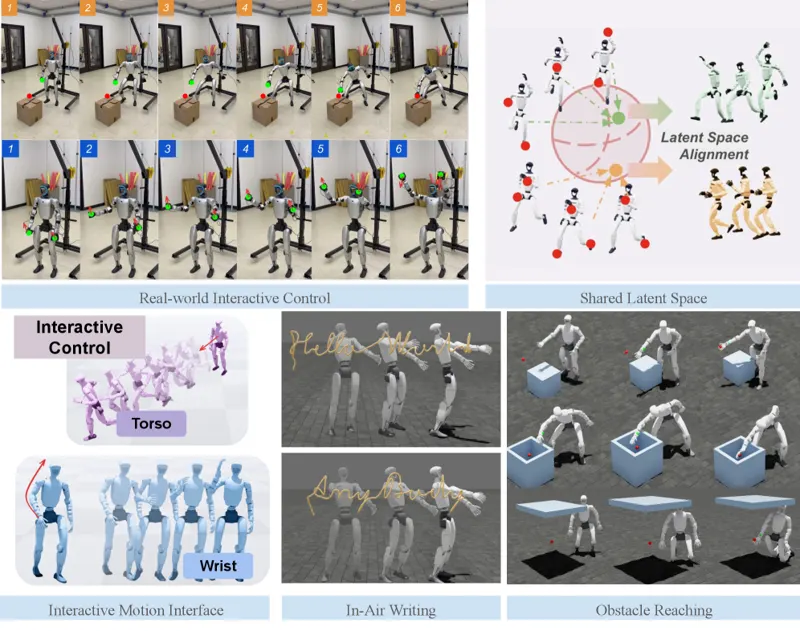
We present AnyBody, a unified whole-body humanoid controller driven by an arbitrary subset of body keypoints chosen at deploy time. Prior physics-based trackers either rely on expensive full-body motion capture and error-prone trajectory retargeting, which bottleneck scalable data collection and policy learning, or decompose upper- and lower-body control into separate hierarchical representations, sacrificing the coordinated whole-body motions that loco-manipulation requires. We close this gap by learning a single latent motion representation that any keypoint subset can address. To achieve this, we first train a privileged teacher tracker on a large unstructured motion corpus and distill it online into a deterministic encoder-decoder student whose latent space is a unit sphere. We then train a transformer keypoint encoder that admits any subset of body keypoints through masked self-attention, aligning it to the privileged latent. Additionally, we treat the frozen decoder as a motor prior and specialize downstream tasks with a lightweight residual corrector in the latent space. We demonstrate the effectiveness of AnyBody by tracking large-scale human motions from arbitrary keypoint subsets, free-form control, flexibly teleoperating, and learning downstream behaviors including locomotion, in-air writing, and obstacle-reach.
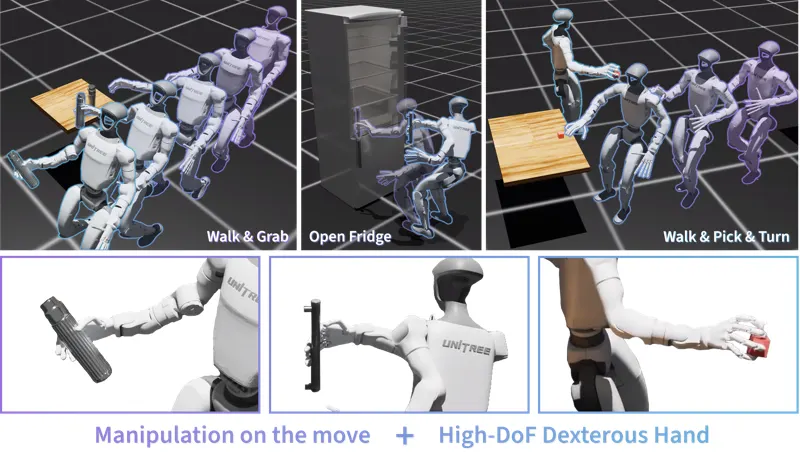
Humanoid loco-manipulation is often simplified into a stop-and-go process: walking to an object, stopping to manipulate it, and then resuming locomotion. It also commonly relies on low degree-of-freedom (DoF) end effectors that behave like an open-close grasp primitive. We introduce CoorDex, a learning pipeline that converts high-dimensional body and dexterous hand control into coordinated latent residual control, enabling high-DoF dexterous loco-manipulation on the move. Starting from simulated whole-body and hand demonstrations, CoorDex trains privileged motion tracking teachers for the humanoid body and dexterous hand, distills them into proprioception-conditioned latent priors, and uses the frozen priors as the action space for downstream residual reinforcement learning. A coordinated latent residual policy composes these priors through shared task context and separate body-hand residual heads, preserving natural whole-body motion while improving finger-level contact reliability. CoorDex enables a Unitree G1 humanoid with a 20-DoF WUJI hand to execute dexterous manipulation while in motion, including non-stop bottle grasping and carrying, fridge door opening on the move, and cube pick-and-turn. Ablations on the walk-grasp-carry task show that joint-space PPO, joint-space hand control, and monolithic latent prediction all fail under the same reward budget, while the latent-prior interface and coordinated residual structure make high-dimensional contact-rich loco-manipulation trainable. Project Page: https://skevinci.github.io/coordex/
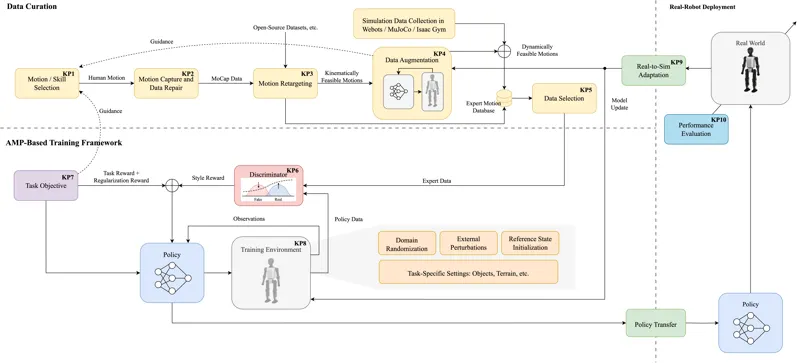
Humanoid robot motion learning requires not only task-oriented control policies but also physically feasible and natural behaviors that can be transferred to real robots. However, robot-feasible motion data are often scarce: raw human demonstrations may be incompatible with the robot morphology, open-source clips vary in quality, and simulation-collected robot trajectories still require feasibility checking. To address these challenges, we propose a data-centric training and deployment pipeline that integrates motion data curation, real-to-sim model adaptation, AMP-based reinforcement learning, and sim-to-real deployment. We validate the framework on the Booster T1 robot and further provide preliminary cross-platform validation on Booster K1.
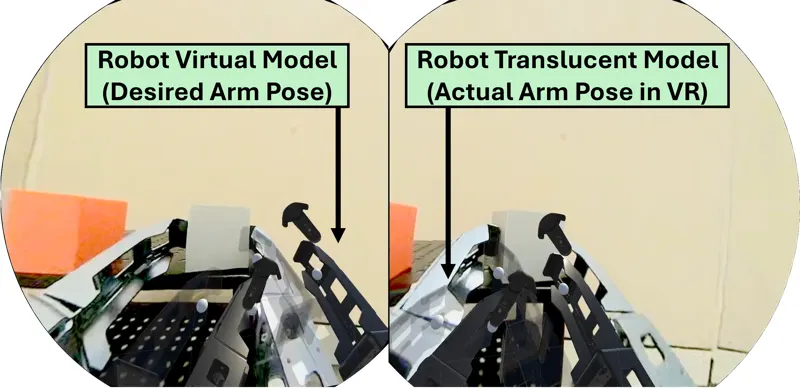
Full-sized humanoid robot capabilities have grown exponentially in recent years, aiming towards general-purpose deployment in human environments. A popular control method used by manufacturers utilizes Virtual Reality for upper-body teleoperation and Reinforcement Learning for lower-body balance and locomotion control. As a result, a single remote operator can see, manipulate, and navigate about a real, distant physical environment. This powerful control stack is often relegated to expensive full-sized robots, many of which are inaccessible to the research community. Miniature humanoids are more prevalent, but employ less biomimicry in their design (e.g. fewer sensors, Degrees of Freedom, etc) and lack similar developments. This paper describes a compliant full-body telepresence control stack developed from the ground up for miniature humanoids. Framework experimentation on ROBOTIS OP3 hardware showcases walking at speeds up to 0.45 m/s independent of arm motions. Tele-loco-manipulation is demonstrated via a cube relocation experiment with an expert human operator. On average, the teleoperated system moved 2 different 40 g cubes within 10 mins, walking a total distance of 5 m. Overall, the developed system shows potential for miniature humanoid tele-loco-manipulation.
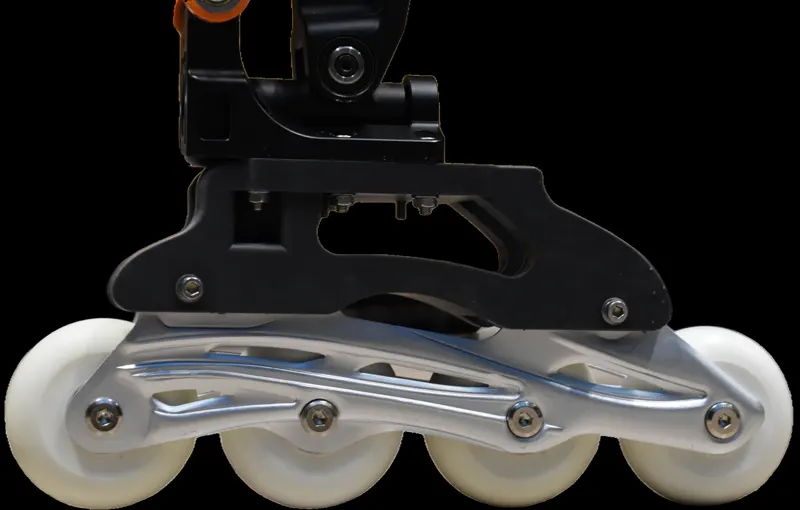
As humanoid robots become increasingly dynamic, coupling them with reinforcement learning offers a promising approach to solving the complex, underactuated mechanics of passive inline skating. Equipping a humanoid robot with passive inline skating wheels presents an opportunity to combine the versatile agility of humanoids with the high-speed, energy-efficient locomotion strategies utilized by human skaters. In this paper, we train and deploy a reinforcement learning control policy that enables novel locomotion strategies for a humanoid robot modified to equip consumer inline skates instead of conventional feet. Unlike previous work limited to quadrupedal robots or actively driven wheels, our system allows for precise 6-DoF control of the skates to execute dynamic, edge-driven propulsion strategies. Our skating strategies emerge entirely from our reward structure, without reliance on human motion data, imitation learning, or kinematic priors. We overcome the inherent instability of passive wheels and simulation contact artifacts by utilizing different geometric wheel models (spherical and ellipsoidal) during training and validation, along with a custom success-based command curriculum and a specialized rolling reward. Consequently, our policy demonstrates up to a 50% reduction in Cost of Transport (CoT) compared to standard walking gaits. The resulting policy successfully transfers zero-shot to the physical Booster T1 hardware. Real-world deployments demonstrate dynamic balance, the ability to reject active physical perturbations, and agile locomotion strategies capable of turning at speed. A video of our results can be found at https://www.youtube.com/watch?v=-_APcOS7uFo.
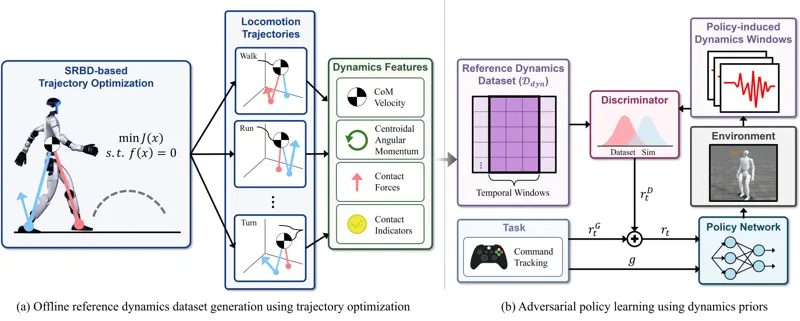
In this paper, we propose Adversarial Dynamics Priors (ADP) for perturbation-resilient humanoid locomotion control. Existing motion prior-based methods induce natural motion styles by imitating kinematic motion features, but they do not directly regularize dynamics features, such as CoM motion, centroidal momentum, contact forces, and contact states. To address this limitation, we replace kinematic motion-style feature with selected dynamics features extracted from locomotion trajectories as the target of adversarial regularization. To this end, we use trajectory optimization to construct a reference dataset and train a discriminator to evaluate whether policy-induced temporal windows are consistent with the resulting reference distribution. Without explicit motion tracking, ADP encourages policy rollouts to remain close to the reference support, even after perturbations. Experimental results show that, compared with AMP, the strongest baseline in our evaluation, ADP improves the 80%-success impulse threshold (J_80) by 16.7%, while reducing direction-averaged recovery time and velocity tracking error by 47.9% and 35.4%, respectively.