QF3: Fast Off-Policy RL for Flow Policies with Filtered Q-Gradients
Loading video
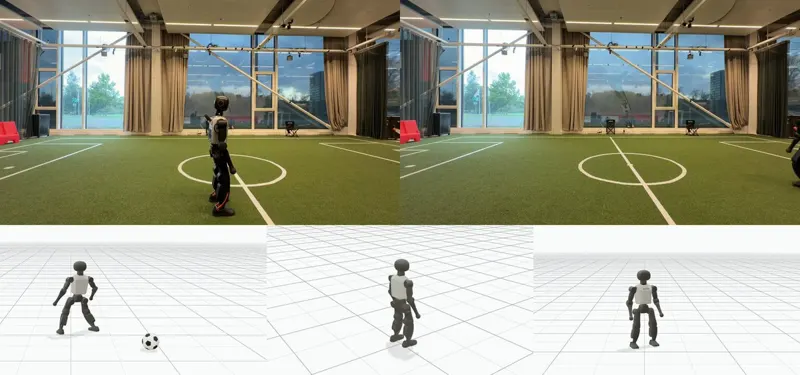
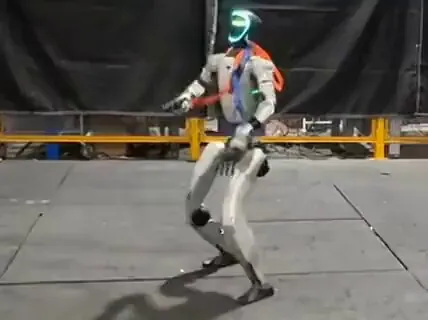
Loading videoQF3 (Fast Flow RL with Filtered Q-Gradients) is an online off-policy algorithm that trains a flow policy with flow matching plus the critic action gradient, backpropagated through a one-step prediction of the flow output. To keep updates where the critic and that prediction are reliable, the gradient is applied only to action dimensions that stay near the replay action. The authors report it as the first off-policy flow RL method to train humanoid locomotion policies from scratch and transfer them zero-shot to hardware.
QF3Flow MatchingOff-Policy RLFlow PolicyHumanoid LocomotionReinforcement LearningZero-Shot TransferMotion Tracking
Category: reinforcement-learning
Author: @robotsdigest
Date: 2026-10-11T00:00:00
Duration: 6.033s
Reference: https://arxiv.org/abs/2610.08789