Skip to content
← Tags

#Zero-Shot (20)

Navi-Agent: Unlocalized Monocular Navigation Agent

Navi-Agent: Unlocalized Monocular Navigation Agent

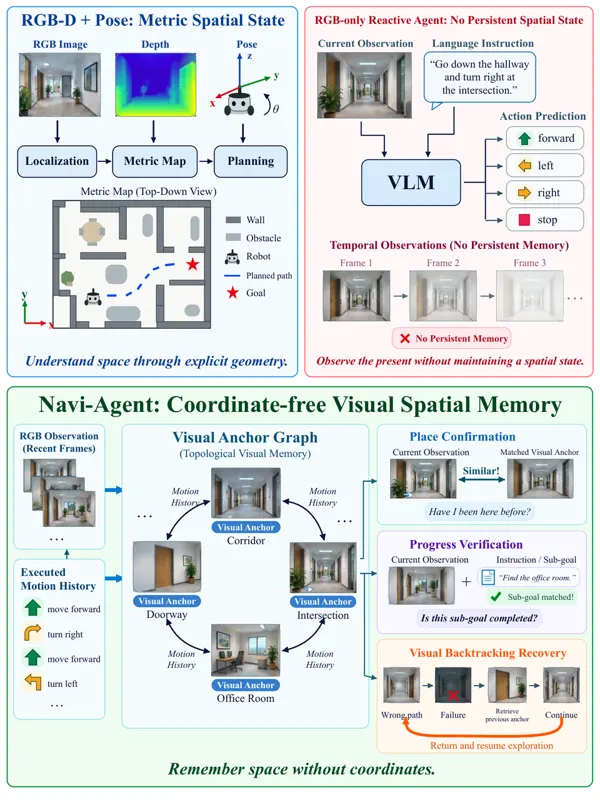
Vision-Language Navigation in Continuous Environments (VLN-CE) requires an embodied agent to execute long-horizon instructions in unknown environments. Existing zero-shot VLN-CE systems typically maintain spatial states through geometric localization or coordinate-based representations. Recent geometry-constrained navigation removes depth and globally consistent coordinates, but maintaining persistent spatial awareness for place confirmation, progress verification, and recovery remains challenging. We present Navi-Agent, a zero-shot VLN-CE agent that constructs a coordinate-free spatial state from visual observations and executed motion histories. Navi-Agent organizes this state as a navigation topology, where nodes represent visual places and edges represent motion transitions. This representation enables observation-based approximate self-localization, task progress verification, and visual revisitation-based recovery. Navi-Agent performs closed-loop navigation by decomposing instructions into sub-goals, executing local visual navigation, and verifying visited places through the constructed spatial state. Experiments on zero-shot VLN-CE benchmark and real-world robot platforms show that Navi-Agent achieves state-of-the-art performance among geometry-constrained methods while remaining competitive with approaches relying on geometric localization.

Xie, Wenyuan, Hong, Mengyang, Wang, Yongzhong · 636 views · Sep 17, 2026
VLNVision-language navigationVisual navigationSep 17, 2026
Show-Harness: Just a VLM Agent Can Play Robots

Show-Harness: Just a VLM Agent Can Play Robots

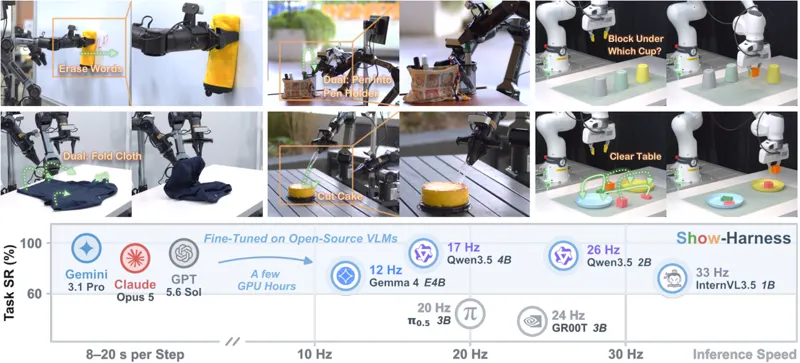
Foundation vision-language models (VLMs) exhibit broad intelligence about the world, yet translating this intelligence into robot control remains challenging. We present Show-Harness, an Embodied Harness that enables VLMs to "play" robots through a compact semantic interface linking intent to action. Show-Harness exposes discrete semantic action units that VLMs can naturally reason over, while embodiment-specific interpreters deterministically ground them into local robot actions, keeping the VLM directly responsible for fine-grained physical decisions. Through the same interface, Show-Harness demonstrates the feasibility of (1) directly unlocking closed-source frontier VLMs for zero-shot robot control, and (2) adapting small-scale open-source VLMs for low-cost deployment with just a few GPU-hours of fine-tuning. We further develop GUMI (GUI Manipulation Interface), which extends the same semantic action space to GUI-based demonstration collection, allowing humans and agents to "play" robots across embodiments without specialized teleoperation hardware. Extensive experiments show that Show-Harness-equipped VLM agents generalize robustly across tasks, embodiments, and environments, outperforming representative agentic and VLA paradigms. These results suggest that the right interface can unlock substantial embodied capability from foundation VLMs, without requiring additional model capacity or costly embodiment-specific pretraining.

Yanzhe Chen, Zechen Bai, Zhijun Cao · 1k views · Sep 9, 2026
Vision-language modelsAgentic HarnessSemantic Action InterfaceSep 9, 2026
ZEST: Zero-shot Embodied Skill Transfer for Athletic Robot Control

ZEST: Zero-shot Embodied Skill Transfer for Athletic Robot Control

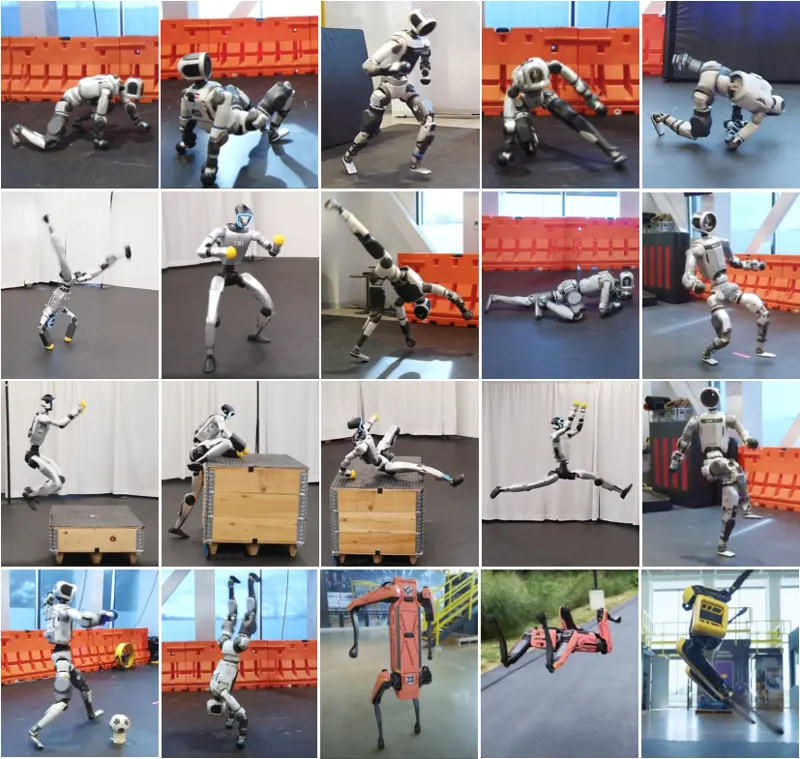
Achieving robust, human-like whole-body control on humanoid robots for agile, contact-rich behaviors remains a central challenge, demanding heavy per-skill engineering and a brittle process of tuning controllers. We introduce ZEST (Zero-shot Embodied Skill Transfer), a streamlined motion-imitation framework that trains policies via reinforcement learning from diverse sources – high-fidelity motion capture, noisy monocular video, and non-physics-constrained animation – and deploys them to hardware zero-shot. ZEST generalizes across behaviors and platforms while avoiding contact labels, reference or observation windows, state estimators, and extensive reward shaping. Its training pipeline combines adaptive sampling, which focuses training on difficult motion segments, and an automatic curriculum using a model-based assistive wrench, together enabling dynamic, long-horizon maneuvers. We further provide a procedure for selecting joint-level gains from approximate analytical armature values for closed-chain actuators, along with a refined model of actuators. Trained entirely in simulation with moderate domain randomization, ZEST demonstrates remarkable generality. On Boston Dynamics' Atlas humanoid, ZEST learns dynamic, multi-contact skills (e.g., army crawl, breakdancing) from motion capture. It transfers expressive dance and scene-interaction skills, such as box-climbing, directly from videos to Atlas and the Unitree G1. Furthermore, it extends across morphologies to the Spot quadruped, enabling acrobatics, such as a continuous backflip, through animation. Together, these results demonstrate robust zero-shot deployment across heterogeneous data sources and embodiments, establishing ZEST as a scalable interface between biological movements and their robotic counterparts.

Jean Pierre Sleiman, He Li, Alphonsus Adu-Bredu · 759 views · Jan 30, 2026
ZESTSim-to-RealAtlasJan 30, 2026
Actuator Reality Shaping for Zero-Shot Sim-to-Real Robot Learning

Actuator Reality Shaping for Zero-Shot Sim-to-Real Robot Learning

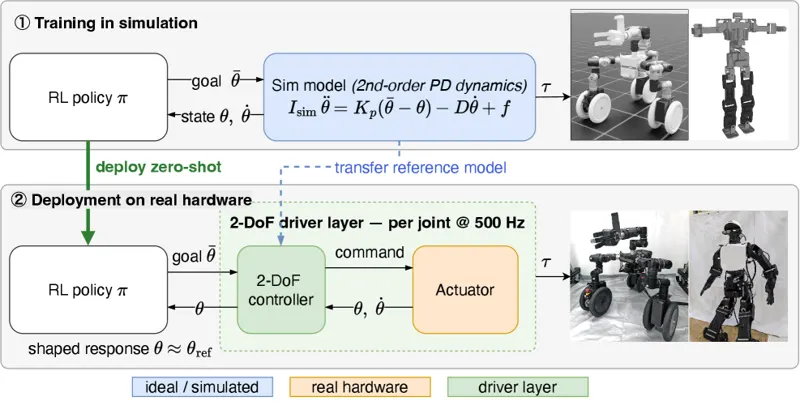
Sim-to-real transfer in robot learning is often limited by discrepancies between the ideal actuator dynamics assumed during policy training and the nonlinear, hardware-dependent behavior of physical motors. While conventional approaches attempt to bridge this gap by increasing simulator fidelity through system identification, domain randomization, or learned actuator models, we introduce an alternative paradigm: actuator reality shaping. Instead of modifying the simulator to match the real world, our method shapes the closed-loop behavior of physical actuators to match the idealized second-order reference dynamics used in simulation. By equipping each joint with a two-degree-of-freedom feedforward–feedback controller, we decouple reference-response shaping from robust stabilization, thereby providing a standardized actuator interface for reinforcement learning policies. As a result, policies trained only with the prescribed reference model can be deployed zero-shot on real hardware without task-level fine-tuning or learned actuator models. We validate the approach on a single-joint high-gear-ratio servo under external loads and a 7-DOF robotic arm reaching task, where actuator reality shaping substantially reduces sim-to-real tracking error and improves zero-shot task performance compared with standard servo-control and representative real-to-sim-to-real baselines. We further demonstrate zero-shot transfer on a wheeled-legged robot driving over a slope and a humanoid robot walking, suggesting that actuator reality shaping can serve as a reusable interface for robot learning across diverse hardware platforms. Project page: https://syamamori.github.io/ActuatorRealityShaping.github.io/

Satoshi Yamamori, Koji Ishihara, Kenjiro Minamikawa · 381 views · Jul 2, 2026
Sim-to-RealZero-ShotActuatorsJul 2, 2026

As an Amazon Associate, we earn from qualifying purchases.