Skip to content
← Tags

#3D Gaussian Splatting (50)

LEGS: Fine-Tuning Teleop-Free VLAs for Humanoid Loco-manipulation in an Embodied Gaussian Splatting World

LEGS: Fine-Tuning Teleop-Free VLAs for Humanoid Loco-manipulation in an Embodied Gaussian Splatting World

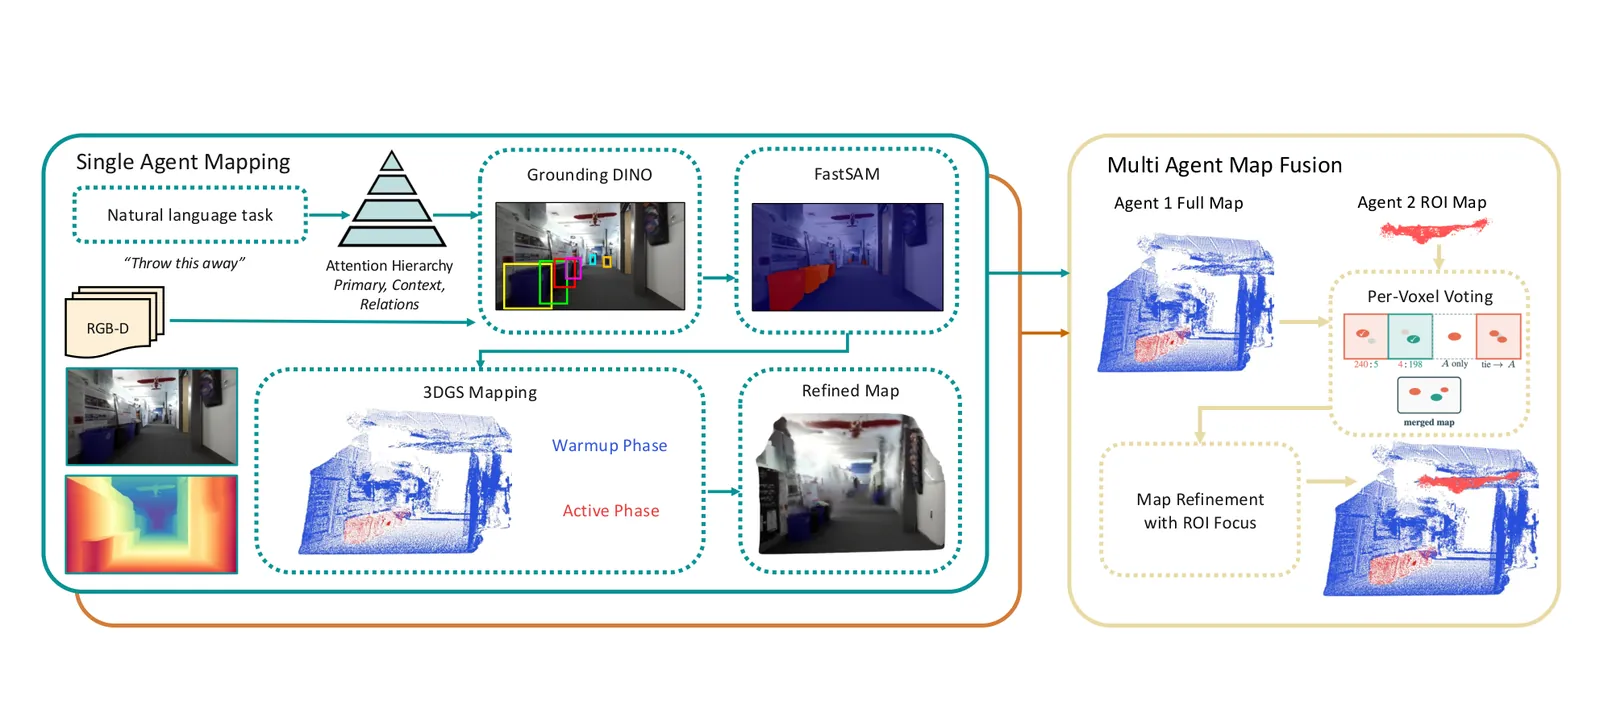
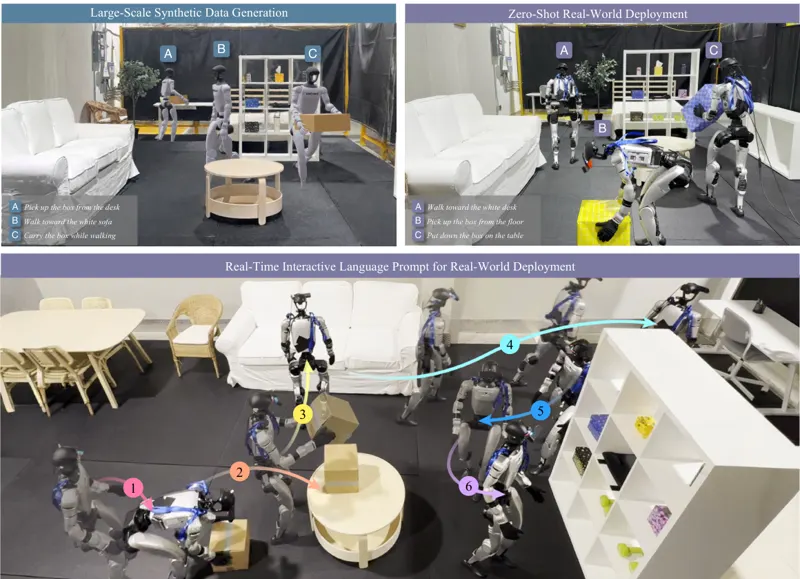
Training vision-language-action (VLA) policies for humanoid loco-manipulation is constrained by the high cost and complexity of collecting human teleoperation demonstrations. VLA policies fine-tuned in simulators have, until now, failed to transfer effectively in humanoid loco-manipulation tasks. We present LEGS (Loco-manipulation via Embodied Gaussian Splatting), a hybrid simulator that composites a mesh foreground (robot, objects, props) over a photorealistic 3D Gaussian Splatting (3DGS) background reconstructed from a handheld scene capture. LEGS uses a procedural motion-primitive generator to synthesize labeled demonstrations at scale without human teleoperation, and a deterministic two-stage color calibration to align the rendered 3DGS image to the robot's deployment camera. On a Unitree G1 humanoid robot, across three pick-and-place tasks of increasing whole-body difficulty and three VLA backbones (psi_0, pi_0.5, GR00T N1.6), a policy trained purely on LEGS data matches or exceeds one trained on human teleoperation demos on every experiment. It also outperforms a mesh-only simulation baseline that ablates the effect of the 3DGS background, showing that photorealistic rendering is a key enabler for synthetic data transfer. Humanoid motion is recorded independently of scene appearance in LEGS, allowing the same auto-generated demonstrations to be re-rendered under new backgrounds and object meshes–covering a new scene at more than 15x lower cost than teleoperation–to augment training data for robustness to scene variations. Under combined object-and-scene appearance shift, the policy trained on re-rendered LEGS-AUG data maintains task success while the baseline trained on teleoperation data fails entirely. Our project page is located at https://legsvla.github.io/.

Kim, Hojune, Chen, Timothy, Sun, Jiankai · 867 views · May 31, 2026
HumanoidVLA3D Gaussian SplattingMay 31, 2026
WilLaGS: Latent-Conditional 3D Appearance Fields for Robust Gaussian Splatting In-the-Wild

WilLaGS: Latent-Conditional 3D Appearance Fields for Robust Gaussian Splatting In-the-Wild

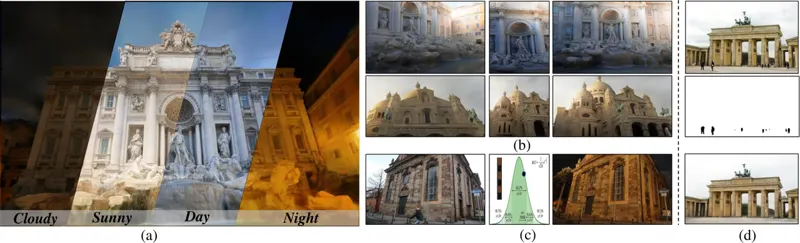
3D Gaussian Splatting (3DGS) delivers real-time and high-fidelity rendering but remains challenged by unconstrained in-the-wild scenes, where drastic appearance variations and transient objects violate multi-view consistency. Existing methods are fundamentally limited by independent and discrete embeddings that struggle to capture continuous environmental changes or model spatially-varying local illumination. To address these limitations, we propose WilLaGS, a unified framework for robust 3D scene reconstruction and generative appearance synthesis under unconstrained settings. Specifically, we introduce a generative appearance model where a β-VAE learns a structured and continuous manifold of global appearance. Conditioned on the latent code, we construct a 3D neural appearance field that generates dynamic Tri-Plane features to encode spatially-varying local illumination effects. Furthermore, to suppress transient artifacts, we present a self-supervised perceptual masking mechanism that leverages a Teacher-Student (EMA) architecture to derive a stable scene consensus, robustly identifying inconsistent regions via perceptual discrepancies. Extensive experiments on multiple datasets demonstrate that WilLaGS achieves state-of-the-art performance in reconstruction quality and novel view appearance synthesis, while maintaining real-time rendering efficiency.

Yuhao Bai, Qianqiu Tan, Lilong Chen · 693 views · Aug 28, 2026
3D Gaussian SplattingGaussian Splattingβ-VAEAug 28, 2026
DL-SLAM: Enabling High-Fidelity Gaussian Splatting SLAM in Dynamic Environments based on Dual-Level Probability

DL-SLAM: Enabling High-Fidelity Gaussian Splatting SLAM in Dynamic Environments based on Dual-Level Probability

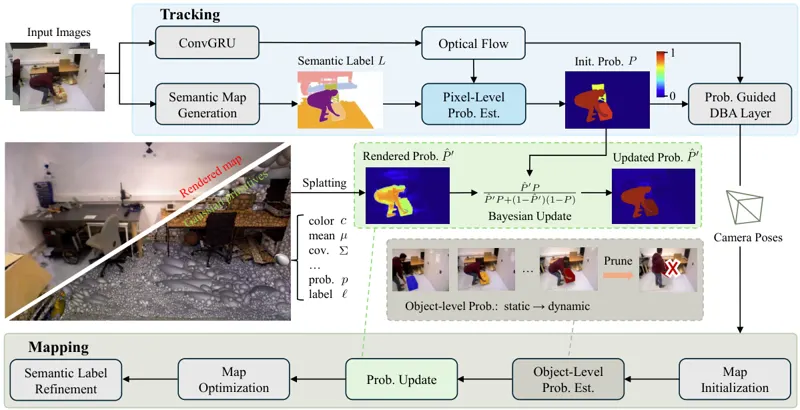
Recent advances in 3D Gaussian Splatting (3DGS) have enabled significant progress in dense dynamic Simultaneous Localization And Mapping (SLAM). Prevailing methods typically discard predefined dynamic objects, ignoring that transiently static objects offer valuable geometric constraints for pose estimation. A recent work attempts to leverage this potential by employing per-pixel uncertainty maps to quantify the magnitude of motion. While this approach enables transiently static objects to enhance pose estimation, it erroneously integrates these objects into the static map, resulting in persistent artifacts. Moreover, its reliance on purely geometric information leads to ambiguous object boundaries in the uncertainty maps. To overcome these limitations, we present DL-SLAM, a monocular Gaussian Splatting SLAM system built upon a novel dual-level probabilistic framework. Our method computes dynamic probability maps by combining semantic and geometric information. These pixel-level probabilities are lifted to 3D and aggregated to derive an object-level dynamic probability for each instance. Object-level probability enables the categorical pruning of dynamic Gaussians, resulting in an artifact-free static map. The static map, in turn, provides a geometrically consistent guidance to refine the pixel-wise probabilities, enhancing their reliability. Experimental results demonstrate that DL-SLAM outperforms existing approaches, improving tracking accuracy by up to 13% while generating high-fidelity semantic maps.

Ziheng Xu, Qingfeng Li, Xuefeng Liu · 623 views · Jul 2, 2026
Dynamic EnvironmentSLAM3D Gaussian SplattingJul 2, 2026
StreamSplat: Streaming Feed-Forward 3D Gaussian Splatting

StreamSplat: Streaming Feed-Forward 3D Gaussian Splatting

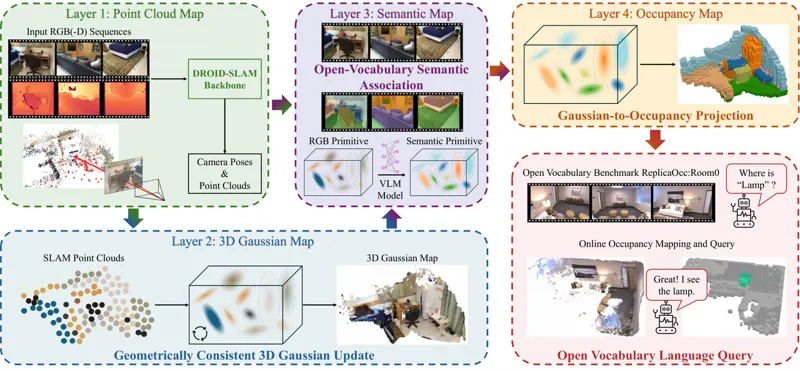
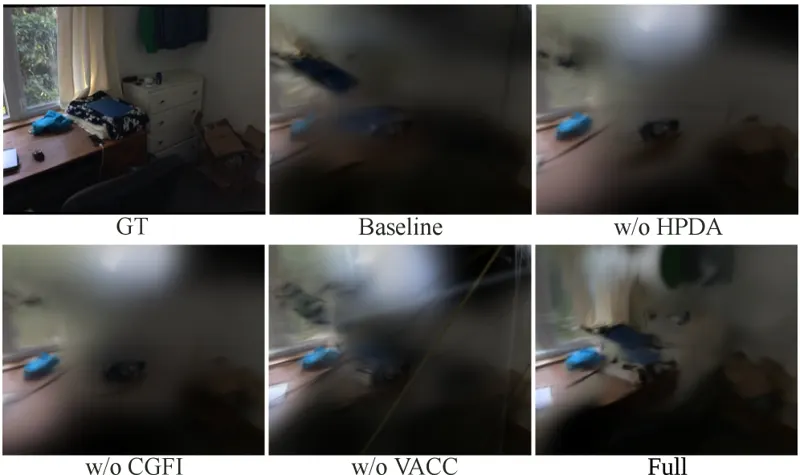
Feed-forward 3D Gaussian Splatting enables efficient novel-view synthesis without per-scene optimization, but most existing methods assume a fixed set of context views and process them jointly. This limits their applicability to online scenarios where calibrated views arrive sequentially and the scene must be updated causally. We present StreamSplat, a streaming feed-forward 3DGS framework that incrementally maintains a persistent geometry-grounded scene state and decodes it into renderable 3D Gaussians after each input chunk. StreamSplat centers on a Voxel-Aligned Causal Cache (VACC), which stores historical 3D tokens in a memory-bounded voxel structure so that memory grows with explored scene geometry rather than stream length. To better reuse history during causal prediction, we introduce History-Projected Depth Anchoring (HPDA) to project cached geometry as depth guidance for current cost-volume estimation, and Cache-Guided Feature Injection (CGFI) to inject cached latent evidence into Gaussian-token regression. Experiments on DL3DV, RealEstate10K, and ScanNet show that StreamSplat remains competitive with state-of-the-art feed-forward 3DGS methods under sparse causal inputs, despite not using future views or full-scene context. More importantly, it scales to long input streams with 256, 512, and 1024 views where fixed-view baselines run out of memory, yielding sustained improvements in novel-view synthesis quality as more observations arrive. The code will be made publicly available upon acceptance.

Changhao Song, Yuxuan Wang, Qibiao Li · 416 views · Aug 3, 2026
3D Gaussian Splatting3D reconstructionStreaming InferenceAug 3, 2026

As an Amazon Associate, we earn from qualifying purchases.