Claude Opus 5.5: the long-running agentic tier at $4/$20 with 1M context and adaptive thinking
The fixed version Anthropic positions for long-running agentic coding and knowledge work (claude-opus-5-5, retirement no earlier than 2027-09-22): 1M-token context, 128K-token single output, adaptive thinking defaulting to medium, at $4/$20 per million tokens, the cheapest of the three top rows tracked here. On the Artificial Analysis intelligence index (2026-09-22) the top three rows are all its thinking tiers (max 57.62, xhigh 55.99, high 53.58), while the default medium tier sits #8 at 51.24, with sibling Fable 5.1 (53.35) and GPT-6 Astra (52.67) in between. Two discounts: those rows carry the with fallback qualifier while Astra reads (max), so the protocols differ, and the 53.94% at #8 on Terminal-Bench belongs to the previous-generation Opus 5. Closed, API only; adaptive thinking is a black box, so budget on p90 rather than the mean; 1M context is not 1M of effective attention, so whole-repo input still needs retrieval. Use it for most workloads and move to Fable 5.1 only when the highest tier is not enough: 2.5x the price for 4.3 index points. Graded A (confirmed); not independently benchmarked.
57.62Artificial Analysis Intelligence IndexConfirmed · 2026-09
Claude Opus 5.5: the long-running agentic tier at $4/$20 with 1M context and adaptive thinkingClaude Code: the agentic coding tool that lives in the terminal, and the reference harness for Anthropic models
Claude Code is the agentic coding tool from Anthropic, and its own definition is deliberately modest: it lives in your terminal, understands your codebase, and executes routine tasks, explains complex code and handles git workflows through natural language. The official docs name three surfaces - terminal, IDE, and tagging @claude on GitHub. anthropics/claude-code stood at 148,438 stars / 24,902 forks on 2026-09-28, among the highest in this class; stated plainly, the repository has no LICENSE file (the GitHub API returns null), so it is publicly readable but not openly licensed - a material difference from the Apache-2.0 core of Codex CLI that must not be blurred during evaluation. Installation moved from npm to native installers (claude.ai/install.sh, install.ps1, brew cask, winget) and npm install -g @anthropic-ai/claude-code is officially deprecated, usually a way to escape the Node version matrix and global-permission support burden. The plugins/ directory is not a shell: it ships 13 officially maintained capability packs - code-review, pr-review-toolkit, commit-commands, feature-dev, frontend-design, security-guidance, agent-sdk-dev, plugin-dev, hookify, the explanatory and learning output styles, the opus 4.5 migration and ralph-wiggum - each a bundle of custom commands plus agents, turning personal prompts into installable team assets. It is also the reference harness for Anthropic models in third-party benchmarks (the Cursor footnote routes Anthropic model scores through Claude Code). Boundaries: no open license, closed models with unavoidable data egress, a terminal-first form factor that costs non-CLI users a learning curve, and a ceiling that depends on how well any third-party model adapts to the Anthropic protocol and tool calling when swapped in. The card metric is the verifiable fact (stars). Confidence: confirmed.
148,438GitHub stars (repo has no LICENSE)Confirmed · 2026-09
Claude Code: the agentic coding tool that lives in the terminal, and the reference harness for Anthropic modelsCodex: an Apache-2.0 core, one agent in four form factors, and the reference harness for OpenAI models
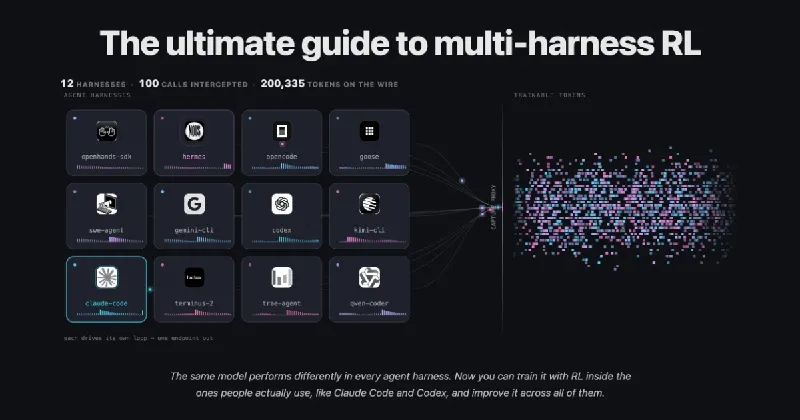
Codex is the coding agent from OpenAI, and in 2026 it is not one product but four entry points onto one core: the CLI in your terminal, an IDE extension (officially for VS Code, Cursor and Windsurf), a desktop app launched with a single codex app command, and Codex Web running tasks remotely at chatgpt.com/codex. The openai/codex repository is Apache-2.0 and stood at 126,918 stars / 19,819 forks when fetched on 2026-09-28 - one of the few frontier-vendor coding harnesses whose harness is itself open source, so context assembly, tool ordering and approval gating can all be read. Safety is a first-class citizen: docs/ carries sandbox.md, execpolicy.md, exec.md, agents_md.md, skills.md and slash_commands.md, where execpolicy turns which commands may run unattended into an auditable, versionable, org-distributable policy instead of model goodwill, exec lets Codex run in CI, scripts and batch jobs rather than only waiting in a terminal, and AGENTS.md has become a de facto cross-tool standard. Four install channels (install.sh, install.ps1, npm, brew) and two billing models: usage included in ChatGPT plans versus per-token API keys, a cost question to settle before choosing. Codex is also the reference harness for OpenAI models - the Cursor Terminal-Bench 2.0 footnote states that OpenAI model scores use the Simple Codex harness, and the vendor-published Terminal-Bench 4.0 reading of 58.18% is already carried on the GPT-6 Astra card because it measures the model rather than the shell, so this entry does not claim it. Boundaries: models are closed and data egress cannot be avoided; developers.openai.com returns 403 to automated fetching, so the fact layer rests on the repository README/docs and the GitHub API. The card metric keeps only the verifiable fact layer (license plus stars). Confidence C (vendor-claim).
Apache-2.0 · 126,918★Harness core licence + GitHub starsVendor Claim · 2026-09
Codex: an Apache-2.0 core, one agent in four form factors, and the reference harness for OpenAI modelsClaude Fable 5.1: the long-horizon agentic tier that tops the ladder on a different ruler
The fixed version Anthropic positions for demanding reasoning and long-horizon agentic work (claude-fable-5-1, retirement no earlier than 2027-09-01): default thinking effort high at $10/$50 per million tokens, 2.5x sibling Opus 5.5, and default-high is itself a default cost behaviour. Its standing only holds once you switch rulers: #1 on net_improvement in the Arena Agent board (13.71, confirmed_success 19.83, praise 31.83) ahead of GPT-6 Astra (11.54/17.70/32.79), while Opus 5.5 misses the top eight; #2 on Terminal-Bench 4.0 at 57.88% (n=330), 0.3 points behind Astra at 58.18% but with pass@5 of 0.7879 against 0.7121, lower single-shot and more robust over five attempts; #4 on the intelligence index at 53.35 (max), below Opus 5.5. The picture is consistent: not first on composite intelligence, first on pushing a real task forward. A separate praise column means the board carries a human or judge component and is not an objective benchmark. Choose by whether the workload is hard from reasoning or from long-horizon consistency. Closed, API only. Graded A (confirmed); no long-task comparison on a standard harness.
13.71Arena Agent net improvementConfirmed · 2026-09
Claude Fable 5.1: the long-horizon agentic tier that tops the ladder on a different rulerGPT-6 Astra: first on terminal engineering tasks, third tier on composite intelligence
The OpenAI flagship tier, officially positioned for hardest end-to-end work (gpt-6-astra): 1.05M-token context, 128K-token single output, knowledge cutoff 2026-04-30, with Functions, Web search, File search and Computer use built in, so search, retrieval and interface control ship with the model instead of an outer agent framework. Reasoning effort runs low to max in five steps while price stays fixed at $10/$50, so the cost lever is token consumption; siblings Sol ($2/$10) and Luna ($0.1/$0.5) make a 100x spread, so load splitting can stay inside one vendor. Readings (2026-09-22): #1 on Terminal-Bench 4.0 at 58.18% (n_trials=330, pass@5 0.7121), the protocol closest to a coding agent's daily life; #2 on Arena Agent with net_improvement 11.54 and confirmed_success 17.70, both below leader Fable 5.1, but the field's highest praise at 32.79; #6 and #7 on the intelligence index (max 52.67). The cutoff is nearly five months older than this page, so version numbers and API changes must go through Web search; computer-use reliability appears on no board; closed, API only. Graded A (confirmed); not independently benchmarked.
58.18%Terminal-Bench accuracyConfirmed · 2026-09
GPT-6 Astra: first on terminal engineering tasks, third tier on composite intelligenceKimi Code: a model lab that builds its own harness, then opens it to every other shell over two protocols
Kimi Code is the developer coding service from Moonshot AI at kimi.com/code, and it sits in an unusual spot in this cohort: most harnesses are shell vendors plugging into models, while Kimi Code is a model lab building its own shell and then opening the API over two protocols at once - OpenAI-compatible at api.kimi.com/coding/v1 (China) and api.kimi.ai/coding/v1 (overseas), Anthropic-compatible at api.kimi.com/coding/ and api.kimi.ai/coding/ - with dedicated integration guides for Claude Code, OpenCode, Codex and Hermes Agent, which amounts to opening its own models to every other shell. Three clients run in parallel: Desktop (released 2026-09-17 for macOS Apple Silicon/Intel and Windows, moving the CLI agent core into a GUI), the CLI (the kimi command, widest feature surface, install.sh verifies checksums; Windows relies on Git Bash from Git for Windows with KIMI_SHELL_PATH for non-standard bash.exe) and a VS Code extension. The model surface is three models across four model IDs - k3, k3-256k, kimi-for-coding, kimi-for-coding-highspeed - and the docs insist on the model ID rather than a version name (writing K3 or K2.8 Preview fails outright), since a misspelled HighSpeed ID falls back silently instead of erroring. K2.7 Code HighSpeed runs about 180 tokens/s (up to 260 on short context) at 5-6x speed for 3x quota, and it only accelerates model output, so rounds dominated by tool calls feel little faster. K2.7 Code was released and open-sourced on 2026-06-12 with official deltas over K2.6 of Program-Bench +10.4%, MCP Mark Verified +11.4%, SWE Marathon +76.2% and 30% fewer reasoning tokens. Boundaries: all readings come from the vendor or vendor-relayed external benchmarks and were not independently reproduced; the K3 technical report is not public alongside the weights; quota is tightly bound to membership tiers (the 1M tier costs about twice the 256K tier, HighSpeed three times); older models retire fast (kimi-k2 on 2026-05-25, kimi-latest on 2026-01-28, kimi-k2.5 and moonshot-v1 on 2026-08-31). Confidence C (vendor-claim).
4 model IDs · 1M contextBuilt-in model lineup (K3 / K2.8 Preview / K2.7 Code HighSpeed)Vendor Claim · 2026-09
Kimi Code: a model lab that builds its own harness, then opens it to every other shell over two protocolsTrae: ByteDance two-form-factor coding line - TraeCode (IDE + SOLO) and TraeWork, plus a stalled MIT-open shell
Trae is the AI coding line from ByteDance, and the official docs split it into two clearly different things. TraeCode is a development tool with AI deeply integrated, in two modes: IDE mode keeps the editor, terminal, debugger, extensions and source control for scenarios that need fine-grained control over code changes and execution, while SOLO mode hands the lead to AI - describe the requirement in natural language, by voice or by uploading local files, and it decomposes the task itself and runs code generation, testing, preview, change summary and deployment, with a task panel, an AI conversation panel and a tool panel (built-in editor, doc viewer, browser) from left to right. TraeWork is the AI-native workspace grown out of the SOLO mode of TraeCode, on web, desktop and mobile, in Work / Code / Design modes, aimed at product managers, data analysts, operations and designers rather than developers only. The long-task ceilings are stated concretely: Max mode extends the context window to 1M, allows up to 200 tool-call rounds per task and reads up to 750 lines per file read to cut down on chunking. bytedance/trae-agent is MIT-licensed but has not been updated for about eight months and cannot stand for the current engineering of Trae. Boundaries: no third-party benchmark readings are published (no SWE-bench or Terminal-Bench self-evidence), so every capability claim comes from feature docs and vendor descriptions; clients are closed source; 1M / 200 rounds / 750 lines are ceilings rather than typical experience and the vendor itself says they raise cost substantially; model availability is doubly limited by region (Seed, MiniMax and GLM unavailable to US users) and by plan tier, so teams across regions do not share one model set; concurrent cloud tasks are a hard tier difference and Free excludes SOLO, so evaluation cannot look at monthly price alone. Confidence C (vendor-claim).
1M · 200 roundsMax mode limits (context / tool rounds per task)Vendor Claim · 2026-09
Trae: ByteDance two-form-factor coding line - TraeCode (IDE + SOLO) and TraeWork, plus a stalled MIT-open shellJev: TypeSafe's first System One Model types decisions and prices them two orders of magnitude lower
TypeSafe's first System One Model: outputs are type-safe structured values under three question primitives (Noul/Choice/Score) rather than strings, trained with RLCD for calibrated decision probabilities. The official 13-question parallel experiment makes one synthesized call ~12.2x cheaper and ~10.0x faster than 13 separate calls; four-workflow mean accuracy 67.8% at /tmp/run_ingest2.sh.0004 and 0.4s per instance - opus 5 / sol tier accuracy at almost two orders of magnitude less cost; input $0.042/M tokens, output free. Ships an OpenJev local reproduction path and an eight-item caveats list.
67.8%Mean accuracy across four workflows (vendor eval)Vendor Claim · 2026-09
Jev: TypeSafe's first System One Model types decisions and prices them two orders of magnitude lower