Claude Opus 5.5: the long-running agentic tier at $4/$20 with 1M context and adaptive thinking
The fixed version Anthropic positions for long-running agentic coding and knowledge work (claude-opus-5-5, retirement no earlier than 2027-09-22): 1M-token context, 128K-token single output, adaptive thinking defaulting to medium, at $4/$20 per million tokens, the cheapest of the three top rows tracked here. On the Artificial Analysis intelligence index (2026-09-22) the top three rows are all its thinking tiers (max 57.62, xhigh 55.99, high 53.58), while the default medium tier sits #8 at 51.24, with sibling Fable 5.1 (53.35) and GPT-6 Astra (52.67) in between. Two discounts: those rows carry the with fallback qualifier while Astra reads (max), so the protocols differ, and the 53.94% at #8 on Terminal-Bench belongs to the previous-generation Opus 5. Closed, API only; adaptive thinking is a black box, so budget on p90 rather than the mean; 1M context is not 1M of effective attention, so whole-repo input still needs retrieval. Use it for most workloads and move to Fable 5.1 only when the highest tier is not enough: 2.5x the price for 4.3 index points. Graded A (confirmed); not independently benchmarked.
57.62Artificial Analysis Intelligence IndexConfirmed · 2026-09
Claude Opus 5.5: the long-running agentic tier at $4/$20 with 1M context and adaptive thinkingClaude Code: the agentic coding tool that lives in the terminal, and the reference harness for Anthropic models
Claude Code is the agentic coding tool from Anthropic, and its own definition is deliberately modest: it lives in your terminal, understands your codebase, and executes routine tasks, explains complex code and handles git workflows through natural language. The official docs name three surfaces - terminal, IDE, and tagging @claude on GitHub. anthropics/claude-code stood at 148,438 stars / 24,902 forks on 2026-09-28, among the highest in this class; stated plainly, the repository has no LICENSE file (the GitHub API returns null), so it is publicly readable but not openly licensed - a material difference from the Apache-2.0 core of Codex CLI that must not be blurred during evaluation. Installation moved from npm to native installers (claude.ai/install.sh, install.ps1, brew cask, winget) and npm install -g @anthropic-ai/claude-code is officially deprecated, usually a way to escape the Node version matrix and global-permission support burden. The plugins/ directory is not a shell: it ships 13 officially maintained capability packs - code-review, pr-review-toolkit, commit-commands, feature-dev, frontend-design, security-guidance, agent-sdk-dev, plugin-dev, hookify, the explanatory and learning output styles, the opus 4.5 migration and ralph-wiggum - each a bundle of custom commands plus agents, turning personal prompts into installable team assets. It is also the reference harness for Anthropic models in third-party benchmarks (the Cursor footnote routes Anthropic model scores through Claude Code). Boundaries: no open license, closed models with unavoidable data egress, a terminal-first form factor that costs non-CLI users a learning curve, and a ceiling that depends on how well any third-party model adapts to the Anthropic protocol and tool calling when swapped in. The card metric is the verifiable fact (stars). Confidence: confirmed.
148,438GitHub stars (repo has no LICENSE)Confirmed · 2026-09
Claude Code: the agentic coding tool that lives in the terminal, and the reference harness for Anthropic modelsCodex: an Apache-2.0 core, one agent in four form factors, and the reference harness for OpenAI models
Codex is the coding agent from OpenAI, and in 2026 it is not one product but four entry points onto one core: the CLI in your terminal, an IDE extension (officially for VS Code, Cursor and Windsurf), a desktop app launched with a single codex app command, and Codex Web running tasks remotely at chatgpt.com/codex. The openai/codex repository is Apache-2.0 and stood at 126,918 stars / 19,819 forks when fetched on 2026-09-28 - one of the few frontier-vendor coding harnesses whose harness is itself open source, so context assembly, tool ordering and approval gating can all be read. Safety is a first-class citizen: docs/ carries sandbox.md, execpolicy.md, exec.md, agents_md.md, skills.md and slash_commands.md, where execpolicy turns which commands may run unattended into an auditable, versionable, org-distributable policy instead of model goodwill, exec lets Codex run in CI, scripts and batch jobs rather than only waiting in a terminal, and AGENTS.md has become a de facto cross-tool standard. Four install channels (install.sh, install.ps1, npm, brew) and two billing models: usage included in ChatGPT plans versus per-token API keys, a cost question to settle before choosing. Codex is also the reference harness for OpenAI models - the Cursor Terminal-Bench 2.0 footnote states that OpenAI model scores use the Simple Codex harness, and the vendor-published Terminal-Bench 4.0 reading of 58.18% is already carried on the GPT-6 Astra card because it measures the model rather than the shell, so this entry does not claim it. Boundaries: models are closed and data egress cannot be avoided; developers.openai.com returns 403 to automated fetching, so the fact layer rests on the repository README/docs and the GitHub API. The card metric keeps only the verifiable fact layer (license plus stars). Confidence C (vendor-claim).
Apache-2.0 · 126,918★Harness core licence + GitHub starsVendor Claim · 2026-09
Codex: an Apache-2.0 core, one agent in four form factors, and the reference harness for OpenAI modelsKimi Code: a model lab that builds its own harness, then opens it to every other shell over two protocols
Kimi Code is the developer coding service from Moonshot AI at kimi.com/code, and it sits in an unusual spot in this cohort: most harnesses are shell vendors plugging into models, while Kimi Code is a model lab building its own shell and then opening the API over two protocols at once - OpenAI-compatible at api.kimi.com/coding/v1 (China) and api.kimi.ai/coding/v1 (overseas), Anthropic-compatible at api.kimi.com/coding/ and api.kimi.ai/coding/ - with dedicated integration guides for Claude Code, OpenCode, Codex and Hermes Agent, which amounts to opening its own models to every other shell. Three clients run in parallel: Desktop (released 2026-09-17 for macOS Apple Silicon/Intel and Windows, moving the CLI agent core into a GUI), the CLI (the kimi command, widest feature surface, install.sh verifies checksums; Windows relies on Git Bash from Git for Windows with KIMI_SHELL_PATH for non-standard bash.exe) and a VS Code extension. The model surface is three models across four model IDs - k3, k3-256k, kimi-for-coding, kimi-for-coding-highspeed - and the docs insist on the model ID rather than a version name (writing K3 or K2.8 Preview fails outright), since a misspelled HighSpeed ID falls back silently instead of erroring. K2.7 Code HighSpeed runs about 180 tokens/s (up to 260 on short context) at 5-6x speed for 3x quota, and it only accelerates model output, so rounds dominated by tool calls feel little faster. K2.7 Code was released and open-sourced on 2026-06-12 with official deltas over K2.6 of Program-Bench +10.4%, MCP Mark Verified +11.4%, SWE Marathon +76.2% and 30% fewer reasoning tokens. Boundaries: all readings come from the vendor or vendor-relayed external benchmarks and were not independently reproduced; the K3 technical report is not public alongside the weights; quota is tightly bound to membership tiers (the 1M tier costs about twice the 256K tier, HighSpeed three times); older models retire fast (kimi-k2 on 2026-05-25, kimi-latest on 2026-01-28, kimi-k2.5 and moonshot-v1 on 2026-08-31). Confidence C (vendor-claim).
4 model IDs · 1M contextBuilt-in model lineup (K3 / K2.8 Preview / K2.7 Code HighSpeed)Vendor Claim · 2026-09
Kimi Code: a model lab that builds its own harness, then opens it to every other shell over two protocolsTrae: ByteDance two-form-factor coding line - TraeCode (IDE + SOLO) and TraeWork, plus a stalled MIT-open shell
Trae is the AI coding line from ByteDance, and the official docs split it into two clearly different things. TraeCode is a development tool with AI deeply integrated, in two modes: IDE mode keeps the editor, terminal, debugger, extensions and source control for scenarios that need fine-grained control over code changes and execution, while SOLO mode hands the lead to AI - describe the requirement in natural language, by voice or by uploading local files, and it decomposes the task itself and runs code generation, testing, preview, change summary and deployment, with a task panel, an AI conversation panel and a tool panel (built-in editor, doc viewer, browser) from left to right. TraeWork is the AI-native workspace grown out of the SOLO mode of TraeCode, on web, desktop and mobile, in Work / Code / Design modes, aimed at product managers, data analysts, operations and designers rather than developers only. The long-task ceilings are stated concretely: Max mode extends the context window to 1M, allows up to 200 tool-call rounds per task and reads up to 750 lines per file read to cut down on chunking. bytedance/trae-agent is MIT-licensed but has not been updated for about eight months and cannot stand for the current engineering of Trae. Boundaries: no third-party benchmark readings are published (no SWE-bench or Terminal-Bench self-evidence), so every capability claim comes from feature docs and vendor descriptions; clients are closed source; 1M / 200 rounds / 750 lines are ceilings rather than typical experience and the vendor itself says they raise cost substantially; model availability is doubly limited by region (Seed, MiniMax and GLM unavailable to US users) and by plan tier, so teams across regions do not share one model set; concurrent cloud tasks are a hard tier difference and Free excludes SOLO, so evaluation cannot look at monthly price alone. Confidence C (vendor-claim).
1M · 200 roundsMax mode limits (context / tool rounds per task)Vendor Claim · 2026-09
Trae: ByteDance two-form-factor coding line - TraeCode (IDE + SOLO) and TraeWork, plus a stalled MIT-open shellZCode: the official GLM-5.3 harness, defined as an ADE rather than an editor
ZCode is the official harness Z.ai built for GLM-5.3, and it defines itself as neither an AI editor nor a CLI but an ADE (Agentic Development Environment): it turns the 1M context window and long-horizon capability of GLM-5.3 into a stable desktop experience covering planning, coding, review and iteration, keeping goal, files, terminal output, browser context, execution mode and Git state inside one task so continuity survives from plan through implementation to verification, with model capability, tool calling and the execution chain tuned over multiple rounds against GLM-5.3. The most distinctive design is /goal mode: after a goal is set, every round ends with an automatic check of whether the goal is met, and the agent continues into the next round on its own until completion is confirmed (the documented example is a research task running twenty-plus rounds, with a right-hand panel showing what each round did). One session holds one goal at a time; /goal shows it, /goal sets it (replacing any existing goal), /goal replace swaps it explicitly, /goal pause suspends it, and the docs are honest about the fit - work that is easy to state in one sentence but takes many rounds to finish. The card metric keeps the verifiable price fact layer: GLM-5.3 API at $1.4 input / $4.4 output per million tokens. Boundaries: the client is not open source and the deep tuning only covers the GLM-5.3 family; a stable 1M context is a vendor claim and mid-context recall is an industry-wide weakness, so stuffing a whole repo is no substitute for retrieval; idle-time tasks are being rolled out to subscribers rather than always available; the free quota is a 5-day window, not a lasting benefit. Confidence C (vendor-claim).
$1.4 / $4.4GLM-5.3 API price (input / output, per million tokens)Vendor Claim · 2026-09
ZCode: the official GLM-5.3 harness, defined as an ADE rather than an editorCursor: one of the few vendors holding all three layers - in-house coding model, own harness, cloud-parallel execution
Cursor began as a VS Code fork from Anysphere and by 2026 is one of very few vendors holding three layers at once: an in-house agentic coding model (Composer), its own harness, and cloud-parallel execution - layers that feed each other, since the real long tasks running through the product every day become RL environments and the resulting Composer is tuned against the tool surface of Cursor itself. The Agent is officially decomposed into instructions (system prompt plus rules), tools (file editing, codebase search, terminal execution) and model, with instructions and tools tuned per frontier model and no cap on tool calls. Composer 2 (2026-03-19) reports CursorBench 61.3, Terminal-Bench 2.0 61.7 and SWE-bench Multilingual 73.7 at $0.50 input / $2.50 output per million tokens, with the same-intelligence fast tier as the product default. Composer 2.5 (2026-05-18) stops adding benchmark tables and targets long-horizon persistence, instruction following and collaboration feel via targeted RL with text feedback (hint-augmented policy as teacher, original-context policy as student, an on-policy distillation KL term) plus 25x the synthetic tasks of Composer 2, including dynamic feature-removal problems. Eval footnotes disclose harness differences: Anthropic models on Claude Code, OpenAI models on Simple Codex, Cursor scores on the Harbor framework averaged over 5 runs per pairing. Boundaries: Composer is closed source and is not the same thing as the open-weight base, CursorBench is in-house, and the forked IDE lags the upstream extension ecosystem. Confidence C (vendor-claim).
61.7Terminal-Bench 2.0 (Composer 2, Harbor / mean of 5 runs)Vendor Claim · 2026-03
Cursor: one of the few vendors holding all three layers - in-house coding model, own harness, cloud-parallel executionQoder: Alibaba agentic platform for real work - nine product lines on one knowledge engine
Qoder is the agentic coding platform from Alibaba, positioned officially as an agentic platform for real work: not an editor but an end-to-end loop - understand the task and context, plan, call tools, verify results, iterate toward the deliverable - resting on three stated principles (context engineering, agent autonomy, goal-directed loops), with nine product lines sharing one knowledge engine (desktop Qoder and Qoder IDE coexisting rather than replacing each other, Editor and Quest forms, a JetBrains plugin, Qoder CLI, cloud agents and more); session history and memory are stored separately but can be imported from the IDE. Repo Wiki is generated locally by multiple agents, never uploads the codebase, is off by default and supports Auto Update, Auto Export and Citation back to source locations. Quest has four drives - Agent, Experts, Goal and Spec (convertible to scheduled tasks): Spec runs requirement clarification (multiple choice, with Recommend / Continue / Skip), a structured Spec covering requirements, design, task breakdown and acceptance criteria, human review, execution, then Review/Commit/Push, while Goal takes only the desired outcome and evaluates progress at the end of every round, continuing automatically until met. Two scaled cases: building Qoder with Qoder (10 people, 3 weeks, 500,000 lines of agent code merged into a 4-million-line legacy system, 99% agent-generated, still in production at v1.4.0 with zero incidents; the method is a cognitive base plus Ultra Spec plus Experts cross-review plus a verifier agent filtering hallucinated issues, with humans only deciding SLO definitions and irreversible operations, and each person driving 20-plus Experts tasks a day); and AutoSDK for AMap in-car systems across 20-plus repositories and over a million lines, where the strict first-pass rate went from 37.3% to 61.5% (problem framing cites KoCo-Bench / arXiv:2601.13240v3: general coding reaches 90% Pass@1 while domain code generation reaches only 8.9%). Boundaries: the client and knowledge engine are closed; every scaled number comes from official cases and vendor self-reporting, and self-evidence from a product about itself carries methodological self-interest, none of it independently reproduced; Experts cost per unit is clearly above a single agent (median about 75 versus about 50 Credits) and Credits reset each cycle rather than accumulating. Confidence C (vendor-claim).
500,000 lines · 99% agent-written10 people, 3 weeks, merged into a 4M-line legacy system (vendor case)Vendor Claim · 2026
Qoder: Alibaba agentic platform for real work - nine product lines on one knowledge engineGPT-6 Astra: first on terminal engineering tasks, third tier on composite intelligence
The OpenAI flagship tier, officially positioned for hardest end-to-end work (gpt-6-astra): 1.05M-token context, 128K-token single output, knowledge cutoff 2026-04-30, with Functions, Web search, File search and Computer use built in, so search, retrieval and interface control ship with the model instead of an outer agent framework. Reasoning effort runs low to max in five steps while price stays fixed at $10/$50, so the cost lever is token consumption; siblings Sol ($2/$10) and Luna ($0.1/$0.5) make a 100x spread, so load splitting can stay inside one vendor. Readings (2026-09-22): #1 on Terminal-Bench 4.0 at 58.18% (n_trials=330, pass@5 0.7121), the protocol closest to a coding agent's daily life; #2 on Arena Agent with net_improvement 11.54 and confirmed_success 17.70, both below leader Fable 5.1, but the field's highest praise at 32.79; #6 and #7 on the intelligence index (max 52.67). The cutoff is nearly five months older than this page, so version numbers and API changes must go through Web search; computer-use reliability appears on no board; closed, API only. Graded A (confirmed); not independently benchmarked.
58.18%Terminal-Bench accuracyConfirmed · 2026-09
GPT-6 Astra: first on terminal engineering tasks, third tier on composite intelligenceMiMo-V2.6: Live RL as an auditable ledger of 30 steps, 750k trajectories, and dollars
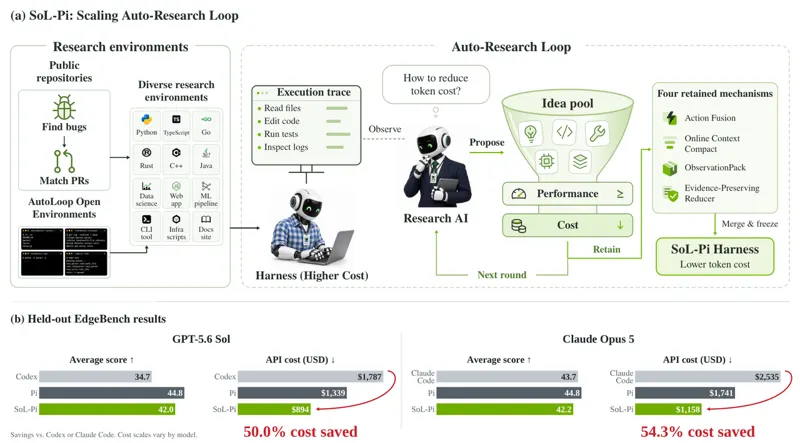
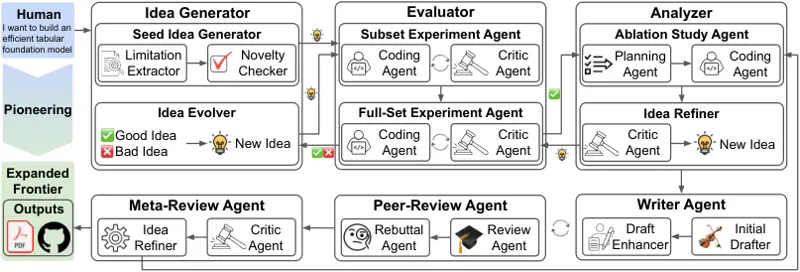
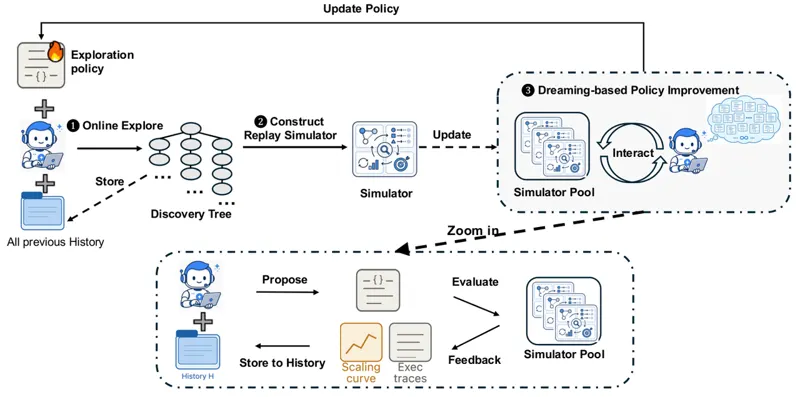
Xiaomi's open-source MiMo-V2.6 Pro/Flash: 30 steps of Live RL, roughly 750k trajectories, public cost of $850k/$2.62M, and 7k+ RL environments released in the same batch; tops the open-weights camp on the Artificial Analysis intelligence index at 46 with +17/+14 points out-of-sample on DeepSWE v1.1; four demo lines (Vibe World, CUA, research, content creation) all open. Self-improvement becomes an auditable ledger - steps, trajectories, and dollars on the table for third-party recomputation.
46Artificial Analysis Intelligence Index (top open-weight)Confirmed · 2026-09
MiMo-V2.6: Live RL as an auditable ledger of 30 steps, 750k trajectories, and dollarsGLM-5.3: the open-weights coding flagship bought with post-training alone
Z.ai post-trained the very same base as GLM-5.2 and nothing else, producing the 744B-A40B GLM-5.3: 50 percent over 5.2 on the in-house Z.ai Code Bench, open-weights first on Terminal Bench 3.0 at 28.3 and Agents' Last Exam at 28.5, while AutomationBench 48.2 and GDPVal-AA v2 1769 beat every closed-source comparison on the official chart; CyberGym vulnerability discovery is SOTA and the exploitation-chain gains emerged without dedicated training. The companion 320B-A18B Flash starts from a new base and is the first GLM to mix sparse with linear attention, attacking long-context serving cost. Weights ship in FP8 and BF16, deployable on SGLang, vLLM, KTransformers and the Ascend stack.
28.3Terminal Bench 3.0 (top open-weight, vendor chart)Vendor Claim · 2026-08
ProductZ.ai (Zhipu AI)SiteRepo GLM-5.3: the open-weights coding flagship bought with post-training aloneBase44: the vibe-coding platform with backend, auth, payments and hosting all built in
Base44 (Wix) takes a different road from v0 and Lovable: rather than leading with "code an engineering team can take over", it builds backend, storage, auth, payments, hosting and analytics into the platform so that "describe it, then go live and take payment" is the default path. Output covers apps, websites and 24/7 AI agents; the design side has a multi-page collaboration board, in-app video generation and whole-app design control, and after publishing there are built-in SEO/GEO dashboards, social content generation and app analytics, with Superagents as the execution layer running alongside what you built. Pricing starts free, paid from $16/mo billed annually, metered in credits. Boundaries are explicit: under a no-code positioning code portability is not written up as a commitment, built-in means bound-in, the security wording is generic rather than a verifiable certification, and there is no public generation-quality benchmark (the only quantified material is the vendor-selected Gift My Book case).
auth + payments + hostingBuilt-in backendVendor Claim · 2026-09
Base44: the vibe-coding platform with backend, auth, payments and hosting all built inopencode: the open-source coding agent split into client and server
anomalyco/opencode (formerly sst/opencode, 210k stars, MIT) splits the coding agent into a client layer and a server layer: the server exposes OpenAPI 3.1 plus an SDK generated from the spec, and the TUI is just one remote frontend of it, so a single session can be driven from a terminal, an IDE, GitHub Actions and ACP clients such as Zed. More than 75 providers plug in through the AI SDK and Models.dev, OpenCode Zen offers a curated gateway of models tested before listing, the 35+ built-in LSPs ship disabled with docs stating they are not always a net win, skills resolve from .opencode, .claude and .agents roots, and permissions are a three-state allow/ask/deny. It is the most engineering-first branch of open-source coding agents: interface before UI.
211kGitHub stars
opencode: the open-source coding agent split into client and serverUI UX Pro Max: a 132k-star AI coding skill that generates complete design systems from 192 industry reasoning rules
An open-source AI skill that injects design intelligence into coding agents: one request generates a complete design system (style + colors + typography + anti-patterns) from 192 industry reasoning rules, 79 searchable UI styles, 192 color palettes, 74 font pairings, 25 chart types and 22 tech stacks (React, Next.js, Astro, SwiftUI, Flutter, Three.js and more). The v2.0 flagship Design System Generator runs five parallel searches (product type, style, palette, landing pattern, typography) through a BM25-ranked reasoning engine to output pattern, style, colors, typography, effects, anti-patterns and a pre-delivery checklist (4.5:1 contrast, no emoji icons, cursor-pointer, prefers-reduced-motion, four responsive breakpoints). MIT licensed, one-line npm CLI install, works with Claude Code and other coding agents.
132kGitHub stars
UI UX Pro Max: a 132k-star AI coding skill that generates complete design systems from 192 industry reasoning rulesCaveman: The Token-Cutting Skill, Proxy and Middleware for Coding Agents
A MIT rule file makes agents talk like cavemen (code and errors never shortened), a local Go proxy compresses what agents read before each call with byte-exact originals recoverable, and middleware brings the same to your own app. JetBrains' 86-task A/B: -8.5% output tokens, quality flat; the repo's pinned 54-run suite: -33.2% input tokens, 18/18 checks passed.
108kGitHub stars
Caveman: The Token-Cutting Skill, Proxy and Middleware for Coding AgentsUnderstand Anything: Turn a Codebase Into an Interactive Knowledge Graph
Turns codebases, documentation, and wikis into an interactive knowledge graph by combining deterministic Tree-sitter structure with LLM-generated summaries, layers, tours, and incremental analysis.
90kGitHub stars
Understand Anything: Turn a Codebase Into an Interactive Knowledge GraphArchify: Verifiable Interactive Diagrams from Coding Agents
An agent skill that turns plain language or Mermaid into self-contained interactive HTML diagrams. Five typed-JSON types, one finalize command chaining validation, delivery, provenance and a real-browser gate; interactions reuse only authored topology, and source evidence is pinned to a commit and line ranges.
75kGitHub stars
Archify: Verifiable Interactive Diagrams from Coding AgentsGitNexus: The Zero-Server Code Intelligence Engine
Indexes any codebase into a knowledge graph — dependencies, call chains, clusters and execution flows precomputed — then serves it to coding agents through 17 smart MCP tools so Cursor, Claude Code and Codex never miss code.
47kGitHub stars
GitNexus: The Zero-Server Code Intelligence EngineAlibaba open-sources Open Code Review: battle-tested hybrid code review CLI
Originating from Alibaba's internal official AI review assistant (tens of thousands of devs, millions of defects over two years): hybrid deterministic pipelines + LLM Agent, line-level comments, built-in NPE/thread-safety/XSS/SQL-injection rulesets, plugins for Claude Code/Codex/Cursor and more, CI/CD integration, and a public benchmark of 200 real PRs with 1,505 annotated issues. OpenAI/Anthropic compatible.
43kGitHub stars
Alibaba open-sources Open Code Review: battle-tested hybrid code review CLIherdr: The Always-On Terminal Runtime for Coding Agents
A single Rust binary that runs coding agents as always-on background terminals: panes report working, blocked or idle, agents drive each other through a CLI and socket API, and sessions survive restarts.
36kGitHub stars
herdr: The Always-On Terminal Runtime for Coding Agents