Skip to content
WORLD MODELS · TIMELINE

World Models: 36 Years from Internal Models to WAMs

1990–2026 · Five lineages · 33 milestones

Early explorationLatent-space eraVideo generation · Physical AI · VLAWAM unification1990200020102018202020222023202420252026Model-based RL · Latent DynamicsVideo-generation World ModelsJEPA Predictive EmbeddingsVLA · World Action ModelsEmbodied / Physical World ModelsWorld Models1990 · SchmidhuberPILCO2011 · Deisenroth & RasmussenWorld Models2018 · Ha & SchmidhuberPlaNet2018 · DeepMindMuZero2019 · DeepMindDreamer2019 · Hafner et al.DreamerV22020 · Hafner et al.TD-MPC2022 · Hansen et al.DreamerV32023 · Hafner et al.I-JEPA2023 · Meta AIGAIA-12023 · WayveUniSim2023 · GoogleSora2024 · OpenAIGenie2024 · DeepMindV-JEPA2024 · Meta AI1X World Model2024 · 1X TechnologiesGenie 22024 · DeepMindCosmos2025 · NVIDIAV-JEPA 22025 · Meta AIGenie 32025 · DeepMindRT-22023 · Google DeepMindOpenVLA2024 · Stanford et al.π02024 · Physical IntelligenceGR00T N12025 · NVIDIAHelix2025 · Figure AIWAMs Survey2026 · Fudan University · Shanghai Innovation Institute · NUSACT2023 · StanfordRDT / H-RDT2024 · Tsinghuaπ0.52025 · Physical IntelligenceOpenVLA-OFT2025 · Stanford · BerkeleyGR00T N1.72026 · NVIDIAXiaomi-Robotics-02026 · XiaomiGigaWorld-Policy-02026 · GigaWorld Team
The x-axis is non-linear (1990–2017 compressed). Hover a node for details.← swipe to explore the full timeline →
WAM PHYLOGENY · 2023–2026

Branching Evolution: From VLA to World Action Models

61 site-collected papers · four lineages · taxonomy per arXiv:2605.12090

Vertical axis is paper date (non-linear; the dense 2026 band is expanded). WAM unifies VLA's p(a|o,l) and world models' p(o′|o,a) into the joint distribution p(o′,a|o,l), splitting into cascaded (imagine, then act) and joint (one model generates both) families; the bottom band is the RoboDojo arena snapshot (Aug 2026, 34 models). Hover for details; click a node to open the paper.
PAPERJul 20, 2026

Patch Policy: Efficient Embodied Control via Dense Visual Representations

Pretrained dense visual features from Vision Transformers (ViTs) are powerful yet have been underutilized in robot learning. Modern robot policies either compress each observation into a single global token, or rely on visual backbones trained from scratch, sacrificing both fine-grained spatial detail and the benefits of large-scale visual pre-training. While there exist policies that do operate on dense patch features like large vision-language-action models (VLAs), they tend to be heavy and slow, inheriting the full cost of a billion-parameter vision-language model (VLM) backbone. We close this gap with Patch Policy, a minimal architectural extension that enables transformer-based policies to consume dense pre-trained patch tokens directly without the computational overhead of a full VLM. At its core is a block-causal attention mask that preserves the temporal causality of standard policies while letting the model attend over many patch tokens per observation, alongside other state information. Patch Policy is lightweight, fast, and highly effective. Across four simulated and three real-world environment suites, our method achieves a 40% relative improvement over policies using state-of-the-art global-pooled representations. Furthermore, it surpasses fine-tuned OpenVLA-OFT by 18% while using roughly 0.7% of the parameters. We believe Patch Policy provides a pipeline for the robotics community to readily leverage continuing progress in visual representation learning, without sacrificing the training efficiency or inference speed required for high-frequency, reactive control. Videos can be viewed at https://patch-policy.github.io

Gaoyue Zhou, Zichen Jeff Cui, Ada Langford

Patch PolicyDense Visual RepresentationDINOv2WebSSL
PAPERJul 20, 2026

World Translation: Minimizing Sim-to-Real Gap with Backward Dynamics Extraction and Unpaired Domain Translation

The gap between simulation and reality remains a fundamental challenge in deploying simulation-trained robotic policies in the real world. Real-to-sim methods narrow this gap from the real side, learning transition dynamics from real data to build a more realistic digital world. Learned dynamics models are their dominant instance. Such methods, however, face a partial observability problem: the same observation may branch to different transitions due to unobservable factors. Existing methods assume these factors can be recovered from observation history. However, this may fail whenever observation history is uninformative, such as a sudden contact event with no prior warning. To address this limitation, we propose World Translation, which exploits a complementary strength of simulators and learned dynamics. Simulators are deterministic but physically imperfect, while learned models are accurate but underdetermined under partial observability. Rather than predicting transitions forward from history, we extract the unobservable dynamics information backward from an observed transition, then translate this feature across simulation and reality as an unpaired domain-translation problem that preserves dynamics content while transferring domain style. Experiments across humanoid, quadruped, and manipulator platforms show that our method achieves more accurate dynamics modeling than baselines, with the largest gains when unobservable factors cannot be recovered from observation history. Real-robot deployment on Go2 quadruped confirms improved policy transfer.

Xinchen Yao, Leixin Chang, Hua Chen

Sim-to-RealDomain AdaptationWorld ModelsInverse Dynamics
PAPERJul 20, 2026

Closing the Loop in Humanoid VLA: Persistent 3D Object Tokens for Verifiable Loco-Manipulation

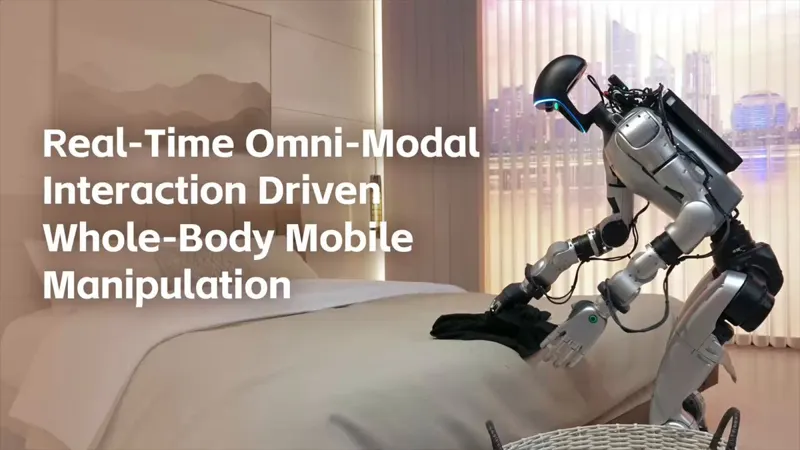
Vision-language-action policies are a promising foundation for general robot control, but long-horizon humanoid loco-manipulation requires the robot to treat task objects as persistent physical entities across movement, contact, occlusion, and recovery. We study this problem as object-state divergence: the object state used to condition a whole-body action can differ from the state used to decide whether the action achieved the intended physical relation. We propose Persistent Object Tokenization (POT), which maintains role-indexed 3D object records from RGB-D observations and converts them into object tokens for a whole-body action expert. Instantiated as POT-VLA, the same object records condition action generation and support geometric predicate checks, yielding a closed-loop execution system in which object state is both actionable and verifiable. On a Unitree G1, POT-VLA improves a matched direct GR00T-N1.7 baseline from 39/80 to 71/80 successes over eight real-world task families. In an external Being-0-aligned reference, POT-VLA achieves 44/50 successes on aligned service tasks, compared with the 37/50 success reported by the Being-0 paper. The largest gains occur on tasks requiring maintained 3D relations, suggesting that persistent object-centered state is a useful abstraction for verifiable humanoid VLA execution.

Peng Ren, Haoyang Ge, Jiang Zhao

VLARGB-DUnitree G1NVIDIA GR00T
PAPERJul 20, 2026

Reasoning as a Double-Edged Sword: Architecture and Cross-Stage Robustness in Vision-Language-Action Models

Does adding a reasoning step make a Vision-Language-Action (VLA) model more robust to perturbation? Intuitively, a policy that reasons before acting should absorb a perturbed input better than one that maps observations directly to actions. We test this premise head-on across three models that span the reasoning spectrum (no reasoning, a text chain-of-thought, and a latent iterative loop), perturbing each at the vision, reasoning, and action stages on LIBERO and SimplerEnv. Two questions organize the study: does the reasoning design shift robustness, and can the reasoning be read back at runtime as a safety signal? We find that the latent-iterative model is by far the least robust: under both stochastic noise and white-box perturbation its task success collapses, while the other two hold. This fragility is structural rather than cumulative: varying the reasoning depth at inference barely moves it. Reasoning outputs can in principle be monitored, but the monitors fail under fair tests. A plan–action consistency probe that looks near-perfect under naive evaluation falls to chance under adaptive attack. Under matched-FPR calibration, fusing it with an action-anomaly probe never lifts defended success above undefended. Scoped to these output-level behavioral probes under white-box vision-stage attack, this ceiling is a precondition that any viable defense must first satisfy.

Tuan Duong Trinh, Naveed Akhtar, Basim Azam

VLAVision-language-action (VLA)

As an Amazon Associate, we earn from qualifying purchases.